THE SIGNAL IN ONE SENTENCE
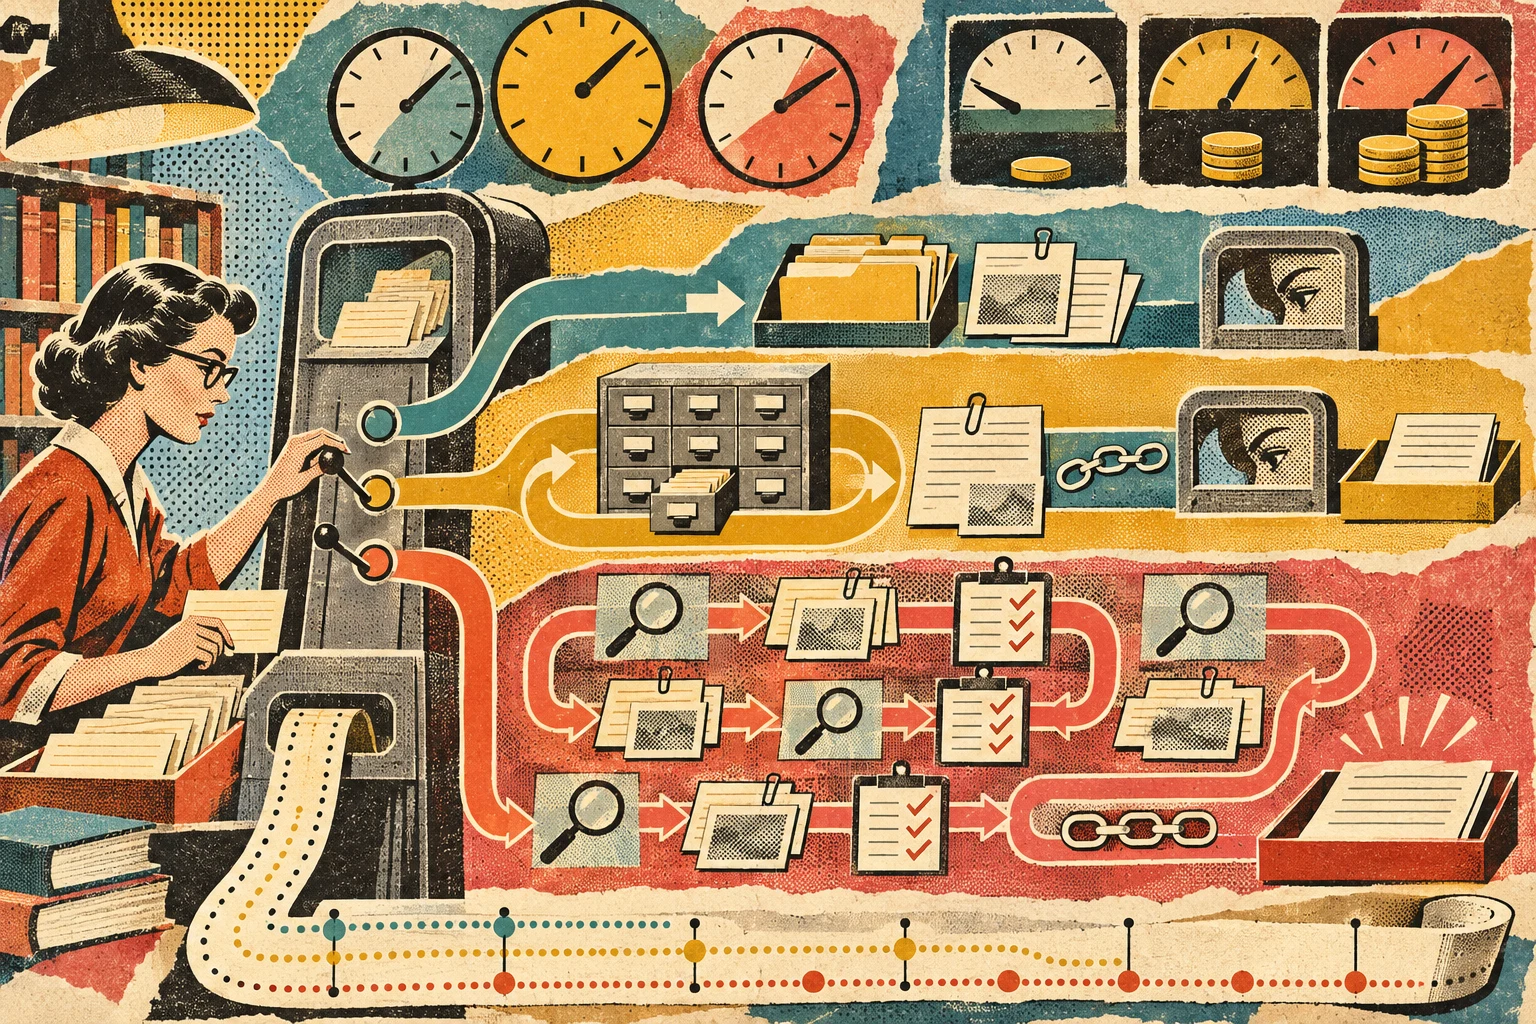
The fanciest retrieval path should not become the default lane just because it has the word agentic on the sign. Amazon gave developers a more useful choice on November 9. Amazon Bedrock Managed Knowledge Base can now handle a question in three distinct ways through the same AgenticRetrieveStream API. Set maxAgentIteration to zero and the service performs one retrieval, returns source passages and makes no foundation-model call. Set it to one and the service performs one retrieval followed by one generated answer. Set it from two through five and the system can plan several searches before it writes the final response. Three gears. One control. That is a meaningful improvement because not every question deserves a planning loop. A person asking for the exact language of a policy may want the passages and nothing else. A direct question may need one search and one supported answer. A comparison across several policies, dates or entities may benefit from query decomposition and repeated retrieval. The important catch is easy to miss: the parameter does not decide which question belongs in which lane. Your application does. Amazon's technical post says teams can select the mode dynamically based on query complexity and application requirements. That selection logic sits outside the retrieval service. The API exposes the gears. It does not build the gearbox. So build the router before the planner becomes the habit. A planner is a toll road. Use it when the question actually needs the exits. Start with the zero setting, because its name invites the wrong conclusion. Zero iterations does not mean zero work. It means one retrieval and zero foundation-model calls. The service searches the configured knowledge bases and returns source passages. The application can show those passages to a researcher, feed them into another controlled process or require a person to write the final interpretation. Amazon says generated responses are not allowed in this mode. If an application requests generateResponse=true while maxAgentIteration is zero, the service returns a client error. That is a useful hard boundary. It prevents a setting called retrieval-only from quietly producing prose anyway. Retrieval-only is attractive when the source material itself is the deliverable. A compliance reviewer may need the actual clauses. A lawyer may want the exact document sections. A customer-support agent may need approved passages before composing a response in a separate system. It also has limitations. A retrieved passage can be incomplete, stale or stripped of the paragraph that changes its meaning. Ranking can place a plausible fragment above the controlling source. Showing raw evidence does not relieve the application of checking document date, authority, access permissions and surrounding context. The first gear removes generation. It does not remove editorial judgment. The one setting is the straightforward lane. Amazon calls it single-shot retrieval. The system runs one retrieval and one answer-generation call. It does not perform a planning step or rewrite the query first. This should be the boring default for many ordinary questions. If a user asks, "What documents are required for this application?" and the answer lives in one well-maintained policy, a planning loop may add cost and latency without finding better evidence. One retrieval can be easier to test because the relationship between the incoming question, returned passages and final answer is short. Short does not mean safe. The generated answer can still overstate a passage, merge incompatible sources or cite a document that does not support the claim. The knowledge base can still be poorly chunked. A single search can still miss a synonym, an older name or a document hidden behind the wrong filter. The answer needs a support check, not merely a citation icon. A citation is a pointer, not a verdict. The remaining settings, two through five, activate agentic retrieval. Amazon says one iteration corresponds to one foundation-model call, and the final iteration is reserved for generating the answer. That means higher limits provide room for planning rounds before the response is written. In this mode the service can break a complex request into smaller questions, retrieve evidence for them and decide whether it has enough material to continue. Amazon's user guide says the process can iteratively retrieve and evaluate the sufficiency of the evidence. Trace events can expose the planning and retrieval steps. This is where the feature earns its keep. Imagine a person asking how two versions of a banking policy differ, which customers are affected and what changed after a specific date. One search string may be a poor representation of that request. A planner can separate the comparison, time boundary and affected groups, then search for each part. Amazon uses a banking-policy assistant to illustrate the three modes. A direct checklist question takes the single-shot path. A comparative, multi-part policy question gets four iterations, allowing planning before the final answer. A reviewer who wants only policy text uses retrieval-only. That example is sensible. It is not an independent evaluation. The post does not establish that four iterations are generally best for comparative questions, that the planner always decomposes them correctly or that the extra searches improve the final answer enough to justify their delay and cost. Amazon explicitly tells teams to evaluate higher values on representative questions rather than assume that more planning is better. That warning should become product design. The router needs a written policy. Do not make it a hidden prompt that says "use agentic mode for complex questions." Complex is not a testable category until the team defines what it can observe. Useful signals may include the number of entities in the question, whether the user asks for a comparison, the number of time periods, whether several policies or knowledge bases must be reconciled, and whether a first search returns enough distinct evidence to support every part of the request. Those signals can be rules, a small classifier or a staged process. The implementation matters less than the receipt. For every request, record the original question, normalized intent, complexity signals, selected mode and maxAgentIteration. Record which knowledge bases, filters, retriever descriptions and reranker were active. Preserve the trace, returned document identifiers, model version and configuration. Then record what the user experienced: time to first evidence, time to first token, total latency, number of model calls, number of retrieval calls and the current bill. The service may perform speculative retrieval before planning, and Amazon says that retrieval does not count toward the iteration limit. Count the actual operations instead of treating the parameter as the complete cost record. Finally, record the result. Did the answer cover every part of the question? Did each claim have supporting evidence? Were the sources current and authorized? Did the system abstain when the evidence was weak? Did a reviewer correct it? Did the user have to ask again? This creates a routing receipt that can be replayed. Build an offline evaluation set before turning the planner loose. Include direct lookups, passage-only requests, comparisons, multi-hop questions, ambiguous wording, stale-document traps and questions that should be refused because the user lacks permission. Give each question an expected evidence set and an acceptable answer or abstention. Run the same set through all three modes. Compare source recall, claim support, citation accuracy, answer correctness, latency and cost. Report the distribution, not only the average. A planner that improves the hardest ten questions while doubling the 95th-percentile latency for everything else may be useful behind a router and miserable as the universal default. Keep simple questions in the simple lane unless evidence says otherwise. Escalate when measurable signals predict that one search is not enough. Allow a human reviewer to force retrieval-only for high-consequence work or to request another search when the source set is thin. Do not confuse multiple knowledge bases with agentic behavior. Amazon says all three modes can work across multiple knowledge bases. A direct question can search several collections without requiring a planning loop. The number of repositories is a configuration detail. The structure of the question is the routing problem. Access control must travel with every subquery. A planner can turn one user request into several searches. Each search should inherit the same identity, tenant, document permissions and purpose restrictions as the original request. The trace should make those boundaries visible. If a subquery reaches a collection the user could not search directly, the planner has become a permission bypass. The same applies to logs. Retrieval traces can contain sensitive fragments of the original question, inferred subquestions and document identifiers. They are essential for auditing, but they need retention rules, access controls and redaction. Observability should not quietly become a second knowledge base with worse governance. Staleness deserves its own measure. A perfectly supported answer can still be wrong today if the cited policy expired yesterday. Store document effective dates, ingestion dates and version identifiers. Test how the router behaves when the most semantically similar passage is not the current authority. Abstention belongs in every mode. Retrieval-only should say when no passage met the evidence threshold. Single-shot should decline to turn a weak search into confident prose. Agentic retrieval should stop when repeated searches are circling the same thin material. More iterations should not manufacture certainty. The user interface should explain the route in plain language. "Showing source passages only." "Answer generated from one search." "This question required several searches." Include the sources, the time boundary and a way to inspect the evidence. Do not expose raw chain-of-thought. Expose the operational facts a person needs to judge the result. This matters beyond Amazon Bedrock. Retrieval systems are becoming mixtures of search, generation and planning. Vendors will package those parts behind increasingly convenient switches. Convenience makes it easier to deploy a powerful path and harder to notice when the path is unnecessary. The responsible default is the lowest sufficient gear. Use passages when a person needs evidence. Use one search and one answer when the task is direct. Pay for a planner when the question truly has several parts and the evaluation shows that decomposition improves the result. Then keep the receipt. The product is not merely the answer at the end of the lane. It is the visible reason the question entered that lane, the trace of evidence it collected and the proof that a slower, more expensive route actually helped.
01
WHAT ACTUALLY CHANGED
Amazon expanded maxAgentIteration for AgenticRetrieveStream to accept values from zero through five, giving one API three retrieval behaviors.
A value of zero performs one retrieval, returns source passages and makes no foundation-model call. Generated responses are not allowed in this mode.
A value of one performs one retrieval followed by one generated answer, without a planning or query-rewrite step.
Values from two through five activate agentic retrieval, allowing planning rounds before the final answer-generation call.
Amazon says all three modes can use multiple knowledge bases and can expose trace events for retrieval and planning where applicable.
02
WHY THIS MATTERS
Teams can match retrieval work to the question instead of paying the latency and model-call cost of a planning loop for every request.
The service parameter selects a mode, but the application must still classify the question and justify that routing decision.
Retrieval-only gives evidence directly to a person or downstream system, while preserving the risks of incomplete, stale or poorly ranked passages.
Single-shot answers are easier to inspect but can still make unsupported claims or miss evidence that a better query decomposition would find.
Agentic retrieval can improve evidence gathering for multi-part questions while creating more searches, more failure points and a larger audit surface.
03
WHERE IT COULD HELP
- Create a routing policy that maps observable question features to retrieval-only, single-shot or agentic mode.
- Build a labeled evaluation set containing direct lookups, passage requests, comparisons, multi-hop questions, stale-document traps and permission-sensitive cases.
- Replay the same questions through all three modes and compare source recall, claim support, answer correctness, latency and current cost.
- Record the original question, complexity signals, chosen mode, maxAgentIteration and reason for every routing decision.
- Preserve knowledge-base versions, filters, retriever descriptions, reranking settings, model version and returned document identifiers.
- Measure time to first evidence, time to first token, total latency and the number of retrieval and foundation-model calls.
- Check whether every answer claim is entailed by a cited passage rather than treating citation presence as proof of support.
- Carry the user's identity and document permissions into every planner-created subquery.
- Protect retrieval traces with access controls, retention limits and redaction because they can contain sensitive questions and document identifiers.
- Track document effective dates, ingestion dates and versions so a relevant but expired passage does not become current advice.
- Define abstention thresholds for empty, conflicting or weak evidence in every mode.
- Canary the router on a small share of traffic and compare quality and latency with a stable holdout before expanding it.
KEEP A HAND ON THE WHEEL
AWS's November 9 post is a company technical source and uses a banking-policy assistant as an illustration. It is not an independent field evaluation of the three modes. The maxAgentIteration setting does not automatically classify a question. The application chooses the value and remains responsible for the routing policy. Zero iterations still performs one retrieval. It means zero foundation-model calls, not zero work or zero cost. One iteration performs one retrieval and one answer-generation call. It does not perform planning or query rewriting first. Values from two through five provide room for agentic planning before the final answer. A higher value is not a guarantee of better evidence or a more accurate response. Amazon says speculative retrieval can occur before planning and does not count toward the iteration limit. Measure actual retrievals and model calls rather than inferring cost from the parameter alone. Trace events improve auditability but can contain sensitive queries, subqueries and document identifiers. Logs need the same governance as other sensitive operational data. Retrieved passages can be incomplete, stale, poorly chunked or outside the user's authorized scope. Retrieval-only does not eliminate those risks. Citations do not establish that the cited passage supports the sentence beside it. Evaluate claim-level entailment and source authority. Agentic decomposition can search the wrong terms, omit part of a request or retrieve evidence the user should not see. Permission checks must apply to every subquery. All three modes can use multiple knowledge bases. The number of collections alone does not prove that a question needs agentic retrieval. Availability, pricing, model support and service limits can change. Verify current AWS documentation and commercial terms before deployment.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Query routing
The decision process that sends a question to a retrieval or reasoning path based on its observable needs, constraints and risk.
OPEN GLOSSARY CARD
Retrieval trace
An operational record of the searches, returned sources and planning steps used to collect evidence for an answer.
OPEN GLOSSARY CARD
Single-shot RAG
A retrieval-augmented generation path that performs one evidence search and then generates one answer without a planning loop.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 10, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US