THE SIGNAL IN ONE SENTENCE
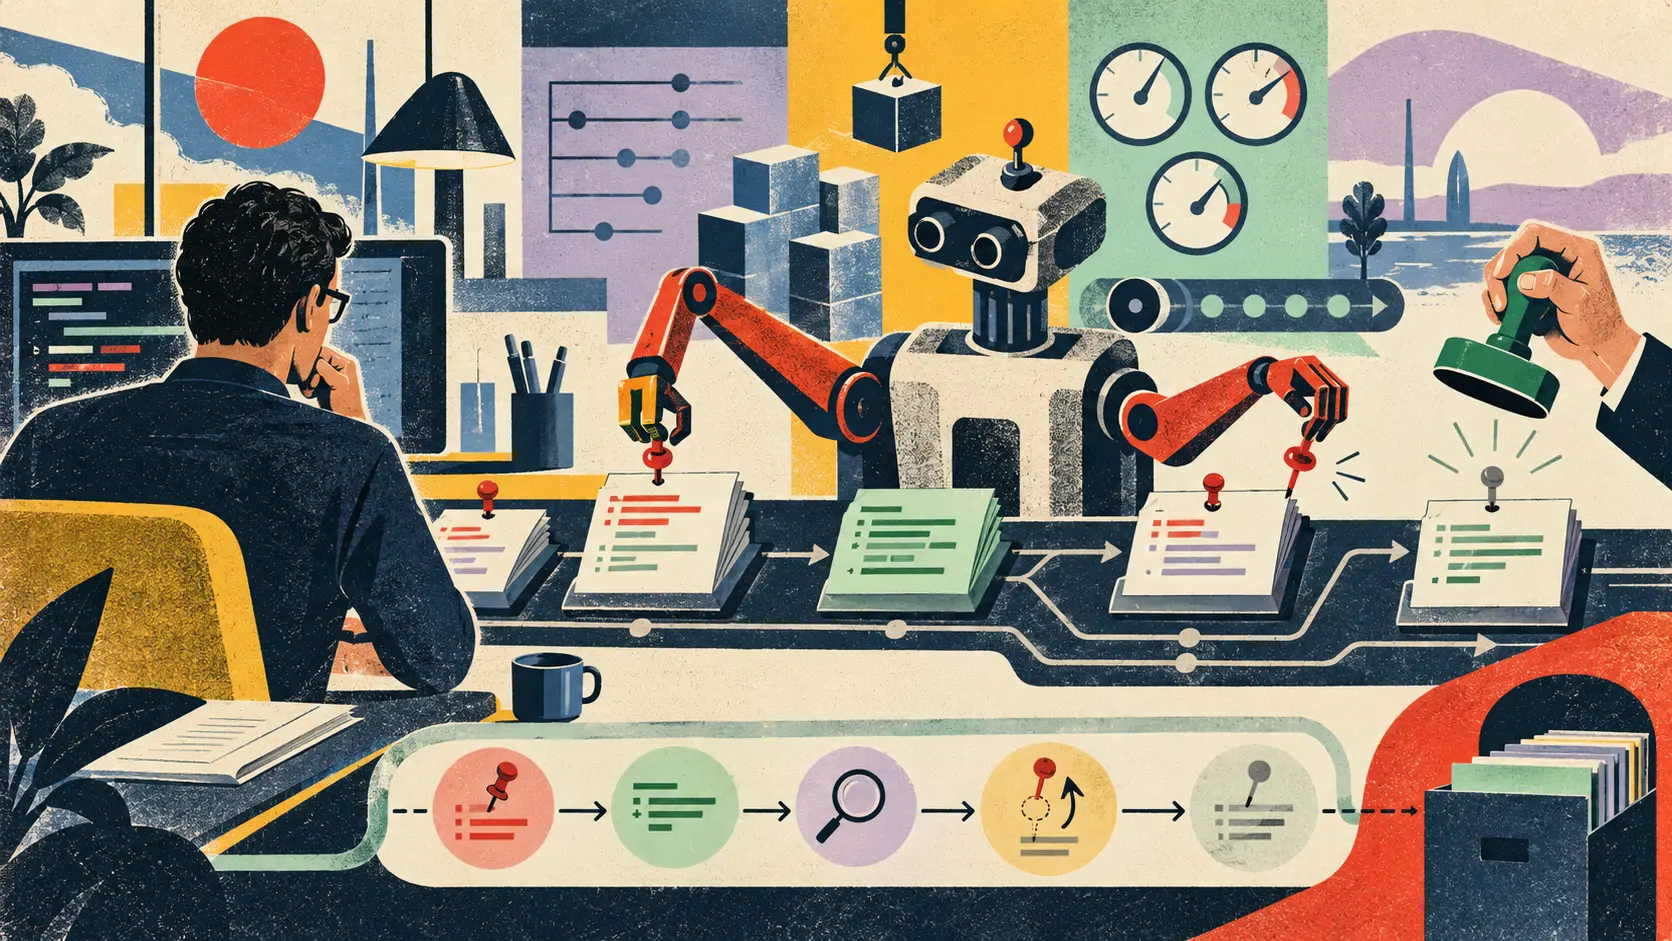
GitHub Copilot code review can now close one of its own review threads after a developer pushes a commit that it believes addresses the underlying feedback. Unfixed comments are supposed to remain open. GitHub also gave the reviewer more shell tools for running builds, tests, and targeted scripts, and moved its Lite review level from one agent to an ensemble. The convenient part is obvious: developers see fewer stale objections. The trust question is less obvious: the same automated reviewer now raises a concern, interprets the fix, and clears the record.
01
WHAT ACTUALLY CHANGED
GitHub announced the update on September 11. When a developer pushes a commit that addresses a Copilot code review comment, Copilot can resolve the thread during its rereview. GitHub says feedback that remains outstanding stays open. The action is narrower than approving or merging the pull request, but it changes the visible state of the review without requiring a person to click resolve.
Copilot now writes a more specific commit-message suggestion when a developer applies an autofix from one of its review comments. Previously the action used a standard message. A useful generated message should describe what changed and why, but it is still editable metadata. It does not prove that the suggested change matches the code, that the code fixes the issue, or that the developer understood the tradeoff.
The review agent also received the full set of shell tools available through the Copilot SDK, operating behind GitHub's Copilot agent firewall. GitHub says the reviewer can run build commands, execute tests and targeted scripts, and retrieve information from available tools and APIs. That is a meaningful upgrade from reading files alone because many defects appear only when code is compiled, exercised, or checked against the repository's own machinery.
The Lite effort level now uses several agents that contribute different perspectives before Copilot combines their findings into one review. GitHub reports that its experiment increased the average number of addressed comments per review by 47 percent for high-severity findings, 31 percent for medium-severity findings, and 11 percent for low-severity findings, while reducing review cost by about 8 percent. Those are GitHub-reported experiment results, not an independent benchmark.
The changelog does not publish the experiment's sample size, repository mix, duration, statistical uncertainty, baseline prompts, false-positive rate, false-negative rate, or complete cost method. It says developers left more positive feedback after shell tools were added and that Copilot surfaced more high-severity findings and fewer minor style complaints. That is encouraging product evidence. It is not enough to calculate how often the reviewer correctly closes a comment or misses a dangerous defect.
02
WHY THIS MATTERS
Open review threads are a shared memory. They tell the author, reviewer, future maintainer, and auditor that a concern still needs attention. Automatic cleanup can keep that memory useful by removing stale warnings. It can also erase a visible disagreement too early if the model mistakes a nearby code change for a complete fix. The cost of a false closure is not another notification. It is a problem that now looks finished.
Rereview is a second reasoning task, not a clerical action. The reviewer must reconstruct the original concern, identify the relevant new diff, decide whether the risk is removed, and check for side effects. A null check may stop one crash while introducing an incorrect default. A permission change may close one exposure while opening another. Matching the comment's wording is easier than preserving the intent behind it.
Shell access makes code review more evidence-based. A reviewer that can run the actual test suite, reproduce an error, inspect generated output, or call a repository tool has more than a language model's impression of the code. The result is only as useful as the environment. Missing dependencies, skipped integration tests, untrusted scripts, weak fixtures, flaky tests, and network limits can all produce a reassuring green result that covers less than it appears to cover.
An ensemble can broaden the search without creating independent accountability. If several agents share the same model family, context, tools, or blind spot, agreement may be correlated rather than corroborating. Combining findings can also hide which agent raised an objection and why it was discarded. The strongest implementation preserves the dissent trail instead of compressing several reviews into one polished answer with no visible seams.
Team metrics can turn convenience into pressure. If managers count fewer open comments, faster review completion, or more addressed findings as success, developers may be rewarded when the interface goes quiet rather than when the software becomes safer. Better measures include escaped defects, reopened threads, revert rate, test coverage gained, security findings, human overrides, and the time it takes to explain a change to someone who did not write it.
03
WHERE IT COULD HELP
- Let Copilot auto-resolve low-risk review threads while requiring human closure for security, permissions, payments, data loss, migrations, and public API changes
- Record the original comment, fixing commit, rereview explanation, tests run, tool output, and resolution event in an audit trail that remains searchable
- Require the reviewer to state the failure mode it checked, the evidence that changed, and any residual risk before closing a thread
- Run repository builds, tests, linters, type checks, security scanners, and targeted reproduction scripts inside a constrained environment before accepting a fix
- Track false closures, reopened comments, human overrides, escaped defects, reversions, and severity by repository instead of celebrating fewer visible threads
KEEP A HAND ON THE WHEEL
GitHub announced the features as current product improvements, but the changelog does not provide a complete plan-by-plan availability table, public reliability study, automatic-resolution accuracy rate, false-positive rate, false-negative rate, sample size, repository distribution, experiment duration, uncertainty range, or independent reproduction. Its 47, 31, and 11 percent figures describe changes in the average number of addressed comments per review at three severity levels during GitHub's ensemble experiment. They do not directly measure defects found, defects prevented, complete-task correctness, or production incidents. The roughly 8 percent cost reduction is also company-reported. A resolved thread means Copilot judged later code to have addressed its own feedback. It does not prove correctness, security, compliance, test completeness, or human approval. Shell tools improve the evidence available to the reviewer, but scripts can be incomplete, flaky, unsafe, or misleading. Teams should preserve resolution history and keep branch protections, required checks, specialist review, and accountable human approval for consequential code.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 13, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 13, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US