THE SIGNAL IN ONE SENTENCE
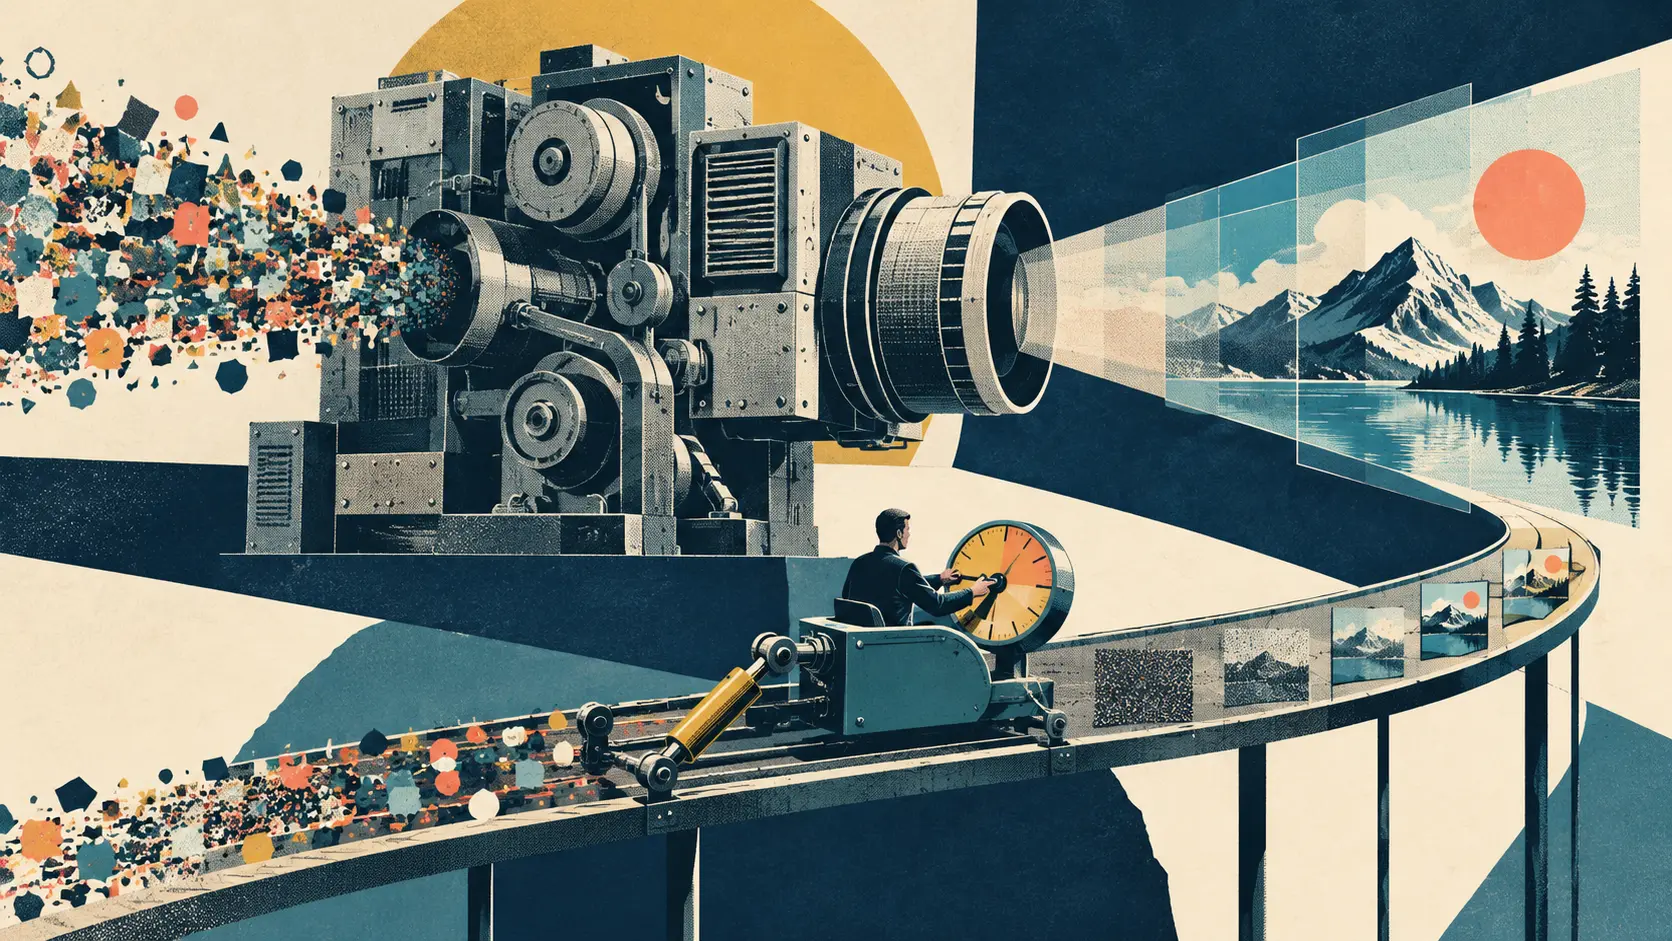
Google Research has a neat answer to a stubborn image-generation problem: leave the big model alone and attach a smaller steering mechanism beside it. The method is called Diffusion Controller. Its underlying paper was first submitted on March 7, 2026 and presented at ICML 2026 in Seoul. Google published a fresh explanation on September 29. The idea is not to rebuild a diffusion model every time someone wants a new style, preference or objective. The pretrained backbone stays frozen. A lightweight side network watches part of the reverse-diffusion process and adds a correction at each step, nudging the noisy latent path toward images that score better under a chosen reward. Google compares this with a steering damper. That metaphor is unusually helpful. A damper does not replace the engine, road or driver. It changes how the vehicle responds while it is moving. Here, the frozen diffusion model supplies the basic image-making ability. The controller supplies the correction. A guidance-strength setting determines how hard the correction pulls. That creates a practical dial between the original model and the optimized behavior. The researchers place the method inside a mathematical framework called a linearly solvable Markov decision process. In less ceremonial language, image generation becomes a sequence of decisions. At every denoising step, the system sees the current state, compares the path with a reward objective and chooses a small adjustment. The paper derives several ways to learn those adjustments. Supervised fine-tuning can learn from preferred examples. Reward-weighted learning gives more influence to samples with higher reward. Proximal policy optimization, or PPO, can update the controller through trial and feedback. The same controller idea can operate in two access regimes. In the white-box setting, the researchers can use more internal information from the model. In the gray-box setting, the controller has less access, but it still sees the intermediate reverse mean and adds a correction before the next sample. That last detail matters. Gray-box does not mean any customer can bolt this onto any commercial image API. The method still needs model execution and access to an intermediate quantity that many hosted products do not expose. It is a lighter integration boundary, not a magic adapter for a sealed service. The reported experiments use Stable Diffusion v1.4 as the frozen backbone. That model is historically important, widely studied and now several product generations old. The text encoder and variational autoencoder stay fixed. The researchers fine-tune the score or controller components under several learning methods and measure results primarily with HPS-v2, a learned human-preference score for text-to-image output. They also report CLIP, PickScore and CLIP-Aesthetics checks. In comparisons with the original pretrained model, the strongest white-box PPO variants exceed a 90 percent HPS-v2 win rate. The gray-box controller reports lower but still positive win rates, including 69.57 percent for PPO against the pretrained baseline. Under supervised fine-tuning and reward-weighted learning, the gray-box controller beats the reported LoRA comparison on HPS-v2. Under PPO, LoRA reaches 90.48 percent while the gray-box controller reaches 69.57 percent, and the white-box controller variants rise above 93 percent. Those distinctions are the story. A sentence saying the controller wins more than 90 percent of the time would be true only for particular white-box PPO comparisons against the original model. It would be false as a general description of every controller, training method and competitor. LoRA also uses more trainable parameters in the paper, 17 million compared with 12 million for the gray-box controller, but parameter count alone does not settle engineering cost. The controller introduces its own inference path, tuning choices and access requirements. HPS-v2 is useful because image quality is difficult to capture with pixel similarity. It is also a learned proxy. Optimizing a proxy can make a system better at whatever the proxy rewards without improving every property people care about. A higher HPS-v2 score does not prove factual visual content, anatomical correctness, cultural appropriateness, copyright safety, resistance to harmful requests or faithfulness to a brand guide. The paper reports that CLIP-Aesthetics sometimes moved slightly downward even when the primary preference score improved. That does not invalidate the method. It shows why one score cannot be the whole steering wheel. The evaluation procedure adds another caution. For each checkpoint, the researchers tried a small set of test-time guidance strengths and reported the best HPS-v2 win rate. Selecting the best dial setting is a normal way to study a method, but it gives a tuned result rather than the performance a user would automatically get from one fixed default. A production evaluation should freeze the selection rule on a validation set, then measure the chosen setting on untouched prompts. It should also show the full curve. If a small increase in guidance makes the score climb before image diversity collapses, the operator needs to see that cliff. Human evaluation helps, but here it remains modest. The paper says more than 50 paid contract raters compared PPO-generated images across 50 randomly generated HPS-v2 prompts. That is enough to check whether the learned metric and people point in a similar direction on a small sample. It is not enough to establish broad human preference across languages, cultures, subjects, disabilities, art traditions or risky content. Fifty prompts can miss entire continents of failure. The rating design also compares outputs inside the research setup rather than measuring whether creators complete real work faster or prefer the controller after weeks of use. The strongest product idea is separation of capability from control. A model owner could keep one expensive backbone frozen and train smaller controllers for different house styles, product categories, personalization rules or domain constraints. A design tool could let a creator slide between the base model and a preferred look instead of swapping checkpoints. A research system could attach different controllers to the same base so experiments remain easier to compare. An organization could version the controller independently, roll it back and inspect which reward changed. That is cleaner than quietly changing the foundation model and calling the result an update. The same separation could support safety work, but that is a proposed application, not a demonstrated result in this paper. A controller trained to reduce prohibited content might help if the reward catches the right failures and the attacker cannot route around it. It might also learn superficial signals, miss rare harms or suppress legitimate material. Safety needs adversarial prompts, protected-class analysis, false-positive measurements, red-team results and evidence that the controller remains effective at every guidance setting. A preference experiment on ordinary images cannot carry that claim. Teams considering the method should build a controller receipt. Record the frozen backbone, controller version, training data, reward model, optimization method, guidance strength, seed and prompt. Keep the original output available for comparison. Evaluate both average preference and failure slices. Measure diversity so a strong reward does not squeeze every request into the same visual grammar. Include prompts where the reward model is likely to be weak, such as unfamiliar languages, specialized diagrams, hands, text, culturally specific clothing and scenes that require factual relationships. Check whether a controller trained for one objective damages another. A brand controller that makes every image look consistent may erase product details. A beauty controller may flatten age and body diversity. A safety controller may overblock educational material. A speed controller may reduce quality exactly where customers notice it. The best operating model is staged. First, run the controller offline against a fixed prompt set with a locked evaluation protocol. Second, conduct blinded human comparisons across relevant user groups. Third, run it in shadow mode so it produces an alternative without changing the delivered image. Fourth, expose the guidance dial to a small group of creators and observe whether they understand it. Fifth, expand only when rollback, monitoring and provenance work. The model should not silently choose maximum steering because one metric liked it. The plain signal is that Diffusion Controller offers a reusable way to add behavior without reopening the whole model. Its math connects supervised tuning, reward weighting and reinforcement learning inside one control view. Its compact side network and adjustable guidance strength are genuinely useful engineering ideas. The road test is also small: one old Stable Diffusion backbone, author-run experiments, a learned preference metric, selected guidance settings and a human study with 50 prompts. Google has shown a promising steering mechanism. It has not shown that the mechanism belongs on every vehicle, every road or every safety system. Keep the backbone frozen if that helps. Keep the claims moving only as fast as the evidence.
01
WHAT ACTUALLY CHANGED
Google Research published a September 29 explanation of Diffusion Controller.
The underlying paper was first submitted March 7, 2026 and presented at ICML 2026 in Seoul.
The method frames reverse diffusion as a continuous-control problem.
A pretrained diffusion backbone can remain frozen while a lightweight side network adds corrections during denoising.
A guidance-strength setting controls how strongly the correction influences generation at test time.
The paper derives supervised fine-tuning, reward-weighted learning and PPO training methods in one framework.
The experiments use Stable Diffusion v1.4 as the frozen backbone.
The text encoder and variational autoencoder remain fixed in the reported setup.
The primary automatic measure is HPS-v2, with CLIP, PickScore and CLIP-Aesthetics used as additional checks.
The gray-box controller has 12 million trainable parameters in the reported table, compared with 17 million for LoRA.
Gray-box DiffCon reports HPS-v2 win rates of 66.67 percent for supervised fine-tuning, 68.15 percent for reward-weighted learning and 69.57 percent for PPO against the pretrained model.
Reported LoRA win rates are 57.66 percent, 61.09 percent and 90.48 percent under the same three training categories.
White-box controller variants exceed 93 percent under PPO against the pretrained baseline.
The team evaluated several guidance strengths and reported the best HPS-v2 win rate for each checkpoint.
More than 50 paid contract raters compared PPO outputs on 50 randomly generated HPS-v2 prompts.
02
WHY THIS MATTERS
A small controller can specialize a model without retraining or replacing the full image backbone.
Keeping the backbone frozen can reduce training scope and make controller changes easier to version and roll back.
An inference-time guidance dial gives creators a visible tradeoff between base behavior and the optimized objective.
One control framework spanning several training methods can make experiments easier to compare.
Gray-box control still needs intermediate model access, so it is not automatically compatible with sealed commercial APIs.
Stable Diffusion v1.4 makes the result reproducible but limits evidence about current proprietary and open models.
HPS-v2 is a learned preference proxy, not a complete measure of image quality, factuality or safety.
Optimizing one reward can improve that score while narrowing diversity or damaging another visual property.
Best-of-several guidance selection can make a method look stronger than a fixed default used without tuning.
White-box PPO results above 90 percent do not describe the gray-box controller or every training regime.
A 50-prompt human comparison is a useful check but too small for broad cultural, linguistic or safety conclusions.
Separate controllers could support personalization, house styles and domain constraints with one shared backbone.
Safety control remains a proposed use until adversarial evaluations and false-positive measurements are published.
A controller can be audited independently only if the reward, data, guidance setting and backbone version are preserved.
The method is promising engineering evidence, not proof of production value or universal preference.
03
WHERE IT COULD HELP
- Train a controller for a narrow visual objective before considering a change to the full backbone.
- Version the backbone and controller separately so either component can be rolled back.
- Expose guidance strength as a creator setting instead of silently maximizing it.
- Freeze guidance selection on a validation set before measuring an untouched test set.
- Publish the complete guidance curve rather than only the best point.
- Compare HPS-v2 with blinded human ratings and task-specific quality measures.
- Measure diversity, prompt faithfulness, anatomy, text rendering and factual relationships separately.
- Test prompts across languages, cultures, styles and user groups relevant to the product.
- Run a brand or house-style controller in shadow mode before it changes delivered work.
- Keep the base output available so reviewers can see what the controller changed.
- Record prompt, seed, backbone, controller, reward, training method and guidance strength for every evaluation.
- Stress-test reward hacking with prompts that are weakly represented in the preference model.
- Measure whether one controller damages objectives it was not trained to optimize.
- Require dedicated adversarial safety testing before using a controller as a content safeguard.
- Check serving latency and memory rather than inferring deployment cost from parameter count.
- Pilot with creators and measure completed work, revisions and rejection, not only pairwise preference.
- Use controller-specific monitoring so a failed update can be isolated without replacing the backbone.
KEEP A HAND ON THE WHEEL
The paper was first submitted March 7, 2026, and Google published its explanatory post September 29. The experiments are author-run and use Stable Diffusion v1.4, not a current commercial image system. HPS-v2 is the primary automatic metric and also supplies the prompts used for the limited human comparison. The team tested several guidance strengths and reported the best HPS-v2 win rate for each checkpoint. Results above 90 percent apply to white-box PPO comparisons against the pretrained baseline, while the gray-box PPO result is 69.57 percent and LoRA reports 90.48 percent in that column. Gray-box control still requires access to an intermediate reverse mean and model execution. More than 50 paid contract raters evaluated 50 prompts, which is not broad evidence about creators, cultures or safety. Watch for independent replication, modern backbones, locked test-time settings, complete preference curves, serving cost, diverse human evaluation, reward-hacking tests, controller interaction studies and a dedicated safety benchmark.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 30, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 30, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US