THE SIGNAL IN ONE SENTENCE
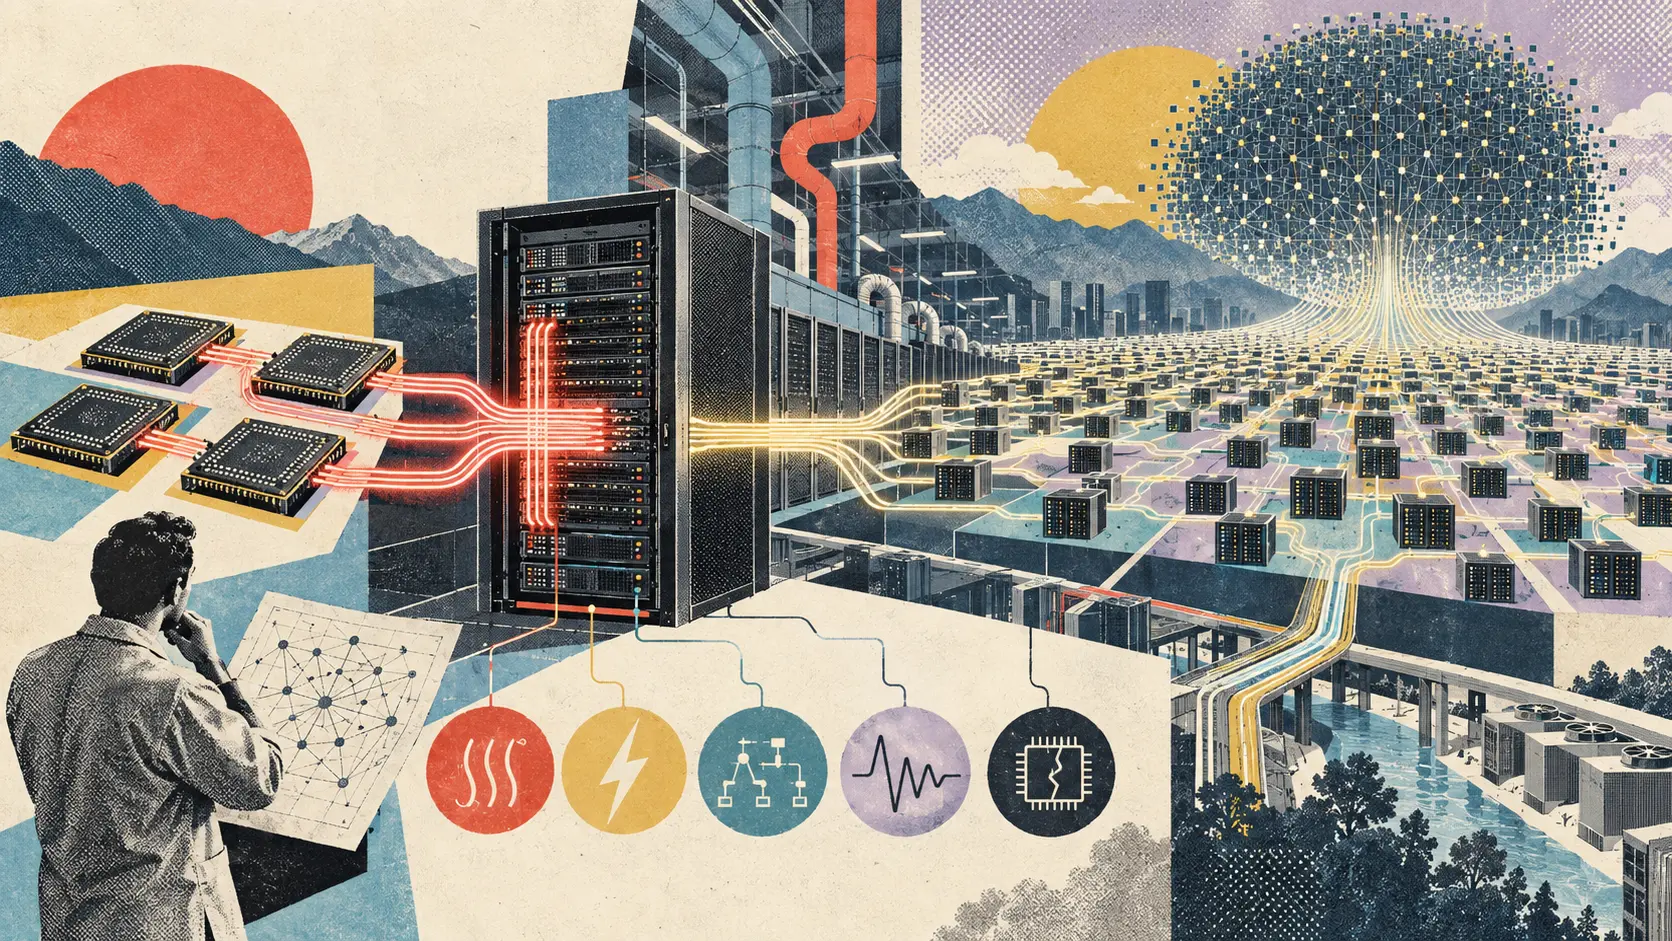
Huawei says it is accelerating two Ascend AI processors planned for 2027 and building a Peerium architecture intended eventually to connect as many as one million processors into one system. The first important word is intended. Huawei has not shown a completed million-processor machine or published an independent full-system training test. The second important idea is that the interconnect is becoming the product. When access to the strongest individual accelerators and the equipment needed to manufacture them is constrained, one answer is to make many available processors cooperate more efficiently. That can create useful capacity, but the arithmetic gets rude fast. More chips bring more communication, synchronization, power, cooling, software work, component failures, and idle time. The plain signal is that a million-chip headline matters only if the whole machine finishes real jobs reliably, efficiently, and at a price someone can defend. Peak chip specifications are the opening scene. Wall-clock training time, useful utilization, energy, recovery, delivery, and software portability are the plot.
01
WHAT ACTUALLY CHANGED
At Huawei Connect in Shanghai on September 17, Huawei presented a faster processor roadmap. Reuters reports that the Ascend 960DT is now planned for the first quarter of 2027, three quarters earlier than Huawei had previously planned, while the Ascend 960PR is scheduled for the third quarter, one quarter earlier. Huawei also outlined yearly generations called Ascend 970 in 2028 and Ascend 980 in 2029. These are schedules announced by the company, not delivered products.
Huawei rotating chairman Eric Xu said the company cannot make enough AI computing equipment to satisfy demand in China and is therefore limiting overseas sales. That shortage sits inside a larger push for domestic computing capacity after United States restrictions reduced Chinese access to advanced accelerators and chipmaking equipment. A roadmap can answer strategic pressure, but it cannot by itself solve fabrication yield, memory supply, packaging, networking, power, or delivery.
The new Peerium architecture is designed eventually to connect as many as one million processors so they can operate as one system. Huawei calls the communication layer UnifiedBus. Reuters reports that an Atlas 960 SuperPoD could connect up to 4,096 processors, while many of those systems could be linked into clusters containing hundreds of thousands of processors. Peerium is an architectural plan. Huawei has not publicly demonstrated an operating one-million-processor installation.
Huawei says clusters of roughly 100,000 chips are becoming standard for some of the largest model-training jobs and that communication between machines can consume more than 40 percent of training time in conventional server systems. Those figures help explain the bet on a tighter fabric. They are company claims, not an independently published benchmark with a disclosed workload, comparison system, precision, software version, network topology, or power envelope.
Huawei also says more than 1,000 systems using its Ascend 910C are deployed, Ascend 950 systems are in commercial use, more than 5,200 developers are active monthly, and more than 40 AI models have been trained directly on the platform. These numbers describe an ecosystem forming around the hardware. They do not establish parity with Nvidia's CUDA software stack, the reliability of Peerium at full scale, or the economics of the planned systems.
02
WHY THIS MATTERS
At large enough scale, the network is the computer. A training job constantly moves parameters, gradients, activations, checkpoints, and data among processors. If that traffic waits on the fabric, a warehouse full of expensive chips can spend a surprising amount of time doing nothing useful. Faster interconnects and fewer boundaries between compute, memory, storage, and networking can improve the share of the machine that is actually working.
Scale-out has a synchronization tax. Adding twice as many processors rarely finishes a job in half the time because every additional participant creates coordination work. Latency, bandwidth limits, workload imbalance, software overhead, and stragglers can flatten the gain. The serious metric is strong scaling: how much faster one fixed job completes as processors are added, not how impressive the processor count looks in a diagram.
A million components turn ordinary reliability into statistics. Even a small failure probability becomes routine when enough chips, cables, switches, power supplies, cooling loops, and software services are involved. The machine needs fault isolation, redundant paths, rapid checkpointing, job restart, repair procedures, spare capacity, and a published account of how much productive time disappears into recovery.
Power and cooling can erase paper performance. A processor may be less capable than a rival but still be useful if a complete system delivers dependable work per watt and per dollar. Conversely, a cluster can win a peak-throughput comparison while losing on energy, water, land, grid upgrades, maintenance, or the cost of moving data. Huawei has not published a full power profile or total cost for a one-million-processor configuration.
Software determines whether theoretical capacity becomes usable capacity. Compilers, kernels, communication libraries, monitoring, debuggers, model frameworks, schedulers, and developer habits all sit between a chip and a finished model. Nvidia's CUDA advantage is not a decorative moat. Huawei needs a stack that lets teams move real workloads, diagnose failures, reproduce results, and train staff without turning every model into a custom infrastructure project.
03
WHERE IT COULD HELP
- Publish the exact bill of materials for every claimed system scale, including accelerator count, memory, switches, links, storage, processor precision, rack count, physical footprint, software release, and which components are installed rather than planned
- Run independent end-to-end training tests that report model, dataset, tokens, time to target quality, utilization, communication share, energy, failed runs, restarts, precision, comparison rules, and the complete wall-clock result instead of only peak operations
- Stress the failure budget by removing processors, links, switches, storage nodes, cooling capacity, and software services during long jobs, then measuring detection, isolation, checkpoint loss, recovery time, degraded throughput, and final-result integrity
- Account for the site as carefully as the chips, publishing peak and average electricity demand, grid connection, cooling design, water use, heat rejection, backup power, embodied construction, maintenance labor, and who pays for each upgrade
- Test software portability with representative models and teams, measuring code changes, unsupported operations, compiler failures, numerical differences, debugging time, operator training, migration cost, and performance after the first polished demonstration is over
KEEP A HAND ON THE WHEEL
The verified event is a Huawei product and architecture announcement reported on September 17, not a public demonstration of a working one-million-processor machine. Huawei's processor dates, accelerated schedule, shortage, demand, performance, communication share, deployment count, developer count, model count, system scale, and efficiency are company statements. Reuters says Huawei did not provide supporting data for several performance claims. Associated Press independently confirms the Atlas 960 SuperPoD announcement and later 970 and 980 roadmap, but does not supply a full technical validation. Huawei's official conference page confirms the Shanghai event and its AI-infrastructure focus, not every product specification. No independent production benchmark establishes full-scale training speed, utilization, reliability, power, cooling, footprint, cost, manufacturing yield, delivery volume, software parity, customer outcome, or one-million-chip operation. The 2027 to 2029 roadmap can change. One thousand deployed systems do not mean one million processors have been linked. Watch for a disclosed reference design, installed customer configuration, complete system power, independently observed wall-clock training, fault-recovery trials, strong-scaling curves, software migration records, shipment evidence, and total cost per completed training job.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Scale-out computing
Increasing computing capacity by connecting more separate processors, servers, or nodes so they can work on a larger task together.
OPEN GLOSSARY CARD
Interconnect
The links, switches, protocols, and software that move data among processors, memory, storage, and machines.
OPEN GLOSSARY CARD
Supernode
A tightly connected group of processors and memory presented as one larger computing unit before several such units are joined into a cluster.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 17, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 17, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US