THE SIGNAL IN ONE SENTENCE
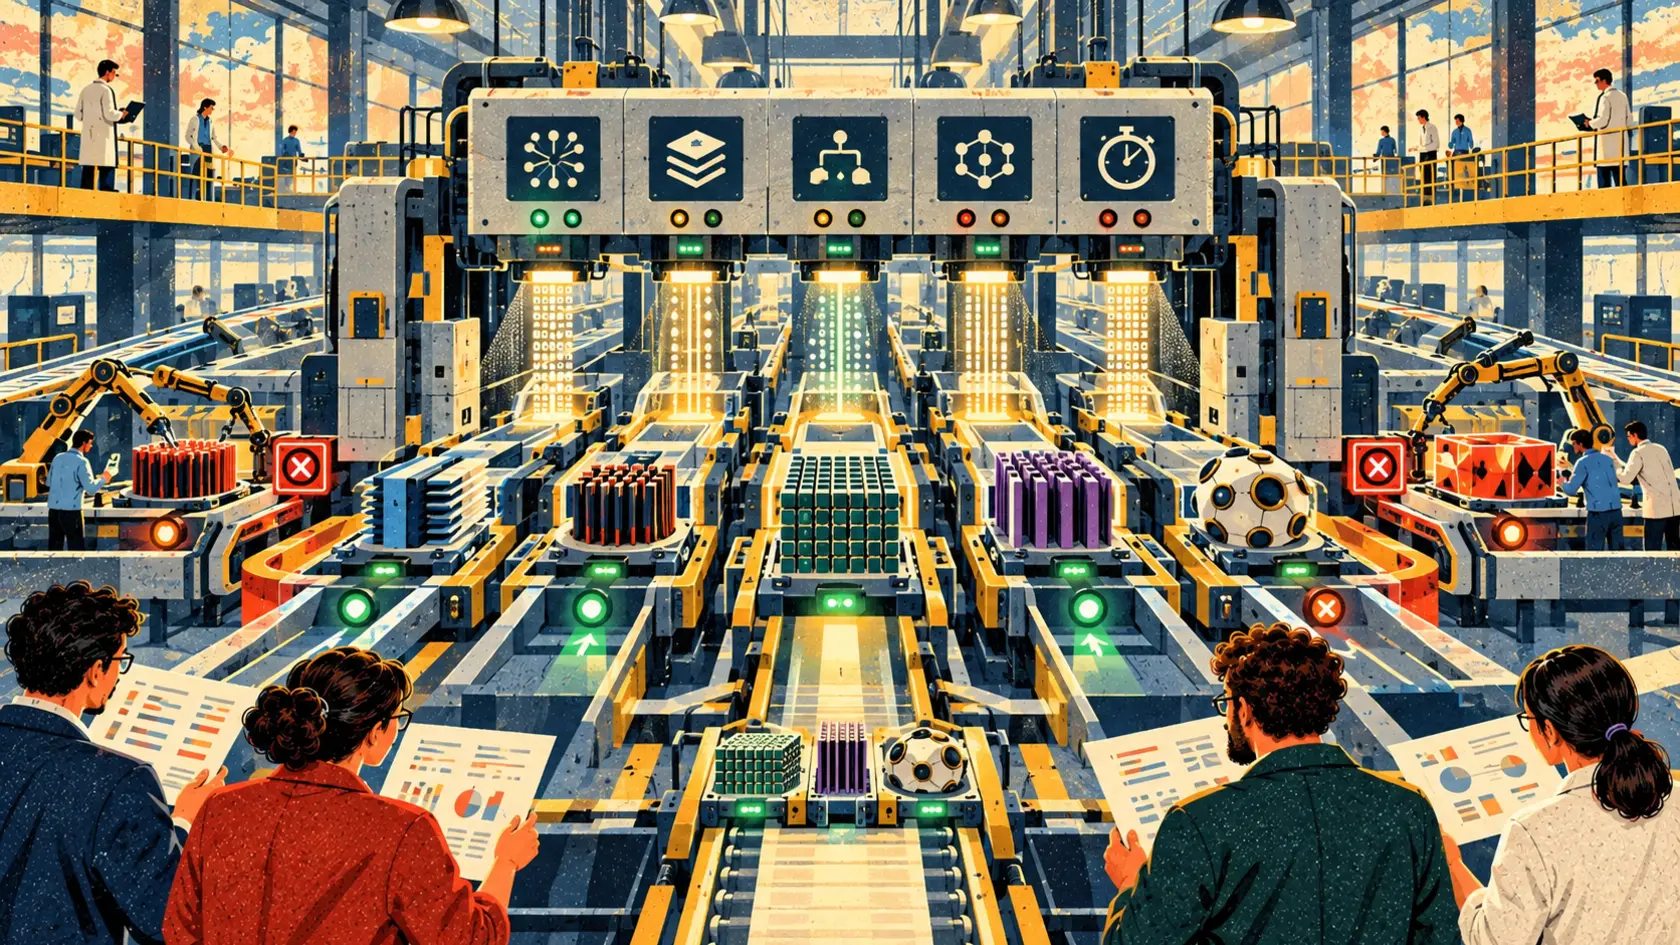
Every new AI chip arrives with a graph that bends sharply upward and a sentence about changing computing forever. Then somebody tries to run an ordinary training job. An operator is missing. A profiler cannot see the device. Distributed workers disagree about whether a collective finished. A framework upgrade breaks a private patch. The benchmark demo was real, but the software stack around it is still held together by three engineers and a calendar invitation. PyTorch's Accelerator Integration Working Group is trying to make that awkward middle more visible and less bespoke. In an October 5 progress report, the group described a collection of projects for connecting new hardware to PyTorch through shared interfaces, reusable tests, reference implementations and cross-repository continuous integration. The work is not one giant certification button. It is closer to building a common entrance exam, a practice laboratory and a public admissions office for accelerators that want to operate inside a framework used across research and industry. The need is obvious. PyTorch sits between model developers and a widening collection of compute platforms. NVIDIA CUDA remains enormously important, but the ecosystem also includes AMD ROCm, Intel XPU, Apple MPS, Qualcomm AI Engine and many devices connected through PyTorch's PrivateUse1 mechanism. Each new backend has to support a broad surface: device registration, operator dispatch, tensors, streams, events, automatic differentiation, compilation, profiling, distributed execution and enough testing to survive the next upstream release. Historically, hardware teams often maintained custom patches or studied production backends to infer the unwritten contract. That can get a device running. It also creates a private compatibility tax that returns whenever PyTorch changes. The working group is moving that contract into shared infrastructure. One part is the Cross-Repository CI Relay, or CRCR. When a pull request or commit lands in the PyTorch repository, the relay can dispatch tests to registered downstream projects in parallel. Those projects run their own workflows and report status back to a common dashboard. This closes a nasty timing gap. Without the relay, a PyTorch maintainer may merge a clean-looking change without knowing it breaks an out-of-tree accelerator. The hardware vendor discovers the problem after the fact, then races to patch its integration or ask upstream maintainers to revisit completed work. CRCR moves the warning earlier. The system uses a four-level allowlist. A downstream project can begin with dispatch notifications, progress toward dashboard reporting, then provide non-blocking and eventually blocking checks on upstream pull requests. PyTorch says callbacks use GitHub identity tokens, allowlist checks, rate limits, state-machine validation and a separation between trusted and self-reported data. A compromised downstream repository should be able to damage only its displayed status, not PyTorch's build machines or merge decisions. That detail matters because a shared test network also creates a shared attack surface. The second big project is less glamorous and probably more consequential: removing assumptions about specific hardware from PyTorch's tests. PyTorch says its suite contains more than 600,000 test cases covering operators, automatic differentiation, profiling, distributed training and other behavior. Many tests were written with hardcoded device names, CUDA-only decorators or device-specific memory and profiling calls. For a new backend, that meant the official test might contain the right behavior but still be impossible to reuse without patches. The working group is classifying tests as accelerator-unrelated, accelerator-agnostic or accelerator-specific. It is replacing hardcoded references with parameterized device calls and adding metadata so a runner can select the correct slice. The October update says contributors migrated more than 276 test files during the first half of 2026. It also says 1,191 unclassified files were placed on an allowlist at launch and are being reduced over time. Those numbers show progress and unfinished work at once. A common test suite is valuable only when it checks meaningful behavior across backends. A vendor should not receive compatibility credit merely because unsupported cases were skipped. The skip mechanism needs to reveal which features are absent, which tests are irrelevant and which failures remain unresolved. The difference between a declared limitation and an invisible gap is the difference between a useful integration report and marketing fog. PyTorch is also building reference backends so accelerator teams do not have to reverse-engineer production code. OpenReg is an in-tree, CPU-backed implementation of the PrivateUse1 integration path. It demonstrates device registration, operator dispatch, streams, events and runtime behavior without pretending to be a fast production backend. That last part is the point. CUDA and other mature backends contain years of performance tuning, hardware-specific scheduling and operational complexity. They are essential systems and terrible beginner examples. OpenReg isolates the integration mechanics so a new team can see the contract before adding its own device runtime and optimizations. The same teaching strategy now reaches profiling, compilation and distributed training. For profiling, an OpenReg reference shows how an out-of-tree backend can register an activity profiler, manage sessions and connect device events to CPU activity. It is a stub, not a production profiler. For distributed work, the group is building OCCL, a minimal collective-communications backend that demonstrates process-group registration, collective dispatch and completion semantics. OCCL is not trying to outrun hardware-specific libraries. It shows where the wires connect. For compilation, OpenReg examples document how a backend registers with Dynamo and Inductor, captures graphs and reaches fused-kernel generation without changing upstream PyTorch code. These references reduce ambiguity. They do not reduce the engineering job to a checklist. A real accelerator still has to implement correct kernels, preserve numerical behavior, handle memory pressure, expose useful traces, survive failures across several machines and deliver enough performance to justify its existence. A reference implementation tells the team where the doors are. It does not carry the furniture. The most public-facing change is PyTorch's Additional Platforms page. The page is meant to become the official, foundation-governed home for compute platforms beyond the primary install paths. Vendors apply through a public issue and supply evidence for the admission requirements, including documentation, continuous-integration dashboards and security information. This is healthier than an unfiltered logo wall. But listing is not certification of universal production readiness. A platform can integrate correctly and still have limited geographic availability, immature tools, poor performance on one workload, expensive networking, weak support or a supply chain that exists mainly in a presentation. Users need a compatibility card that stays specific. Which PyTorch versions are supported? Which operating systems, data types and operators work? Does automatic differentiation pass? Can distributed training recover from a worker failure? Does the compiler generate correct output across dynamic shapes? Are results numerically comparable with a known implementation? Which tests are skipped, and why? Then comes performance. Measure representative models rather than a vendor's favorite kernel. Report time to target quality, end-to-end throughput, tail latency, power, memory, interconnect cost, compilation time, failed runs and engineering hours. Include a mature baseline and publish the software versions. Performance without correctness is a fast wrong answer. Correctness without operational detail is a laboratory specimen. This shared entrance exam also matters beyond hardware companies. Model developers gain earlier warning when an upstream change breaks another platform. Framework maintainers get a structured view of downstream effects. Researchers can compare devices through common behavior instead of translating every experiment into a vendor-specific dialect. Smaller accelerator teams gain a documented route into the ecosystem rather than negotiating it from scratch. There is still a governance problem to solve. Once downstream checks can block upstream changes, PyTorch will need clear rules for reliability, maintenance and appeals. A flaky vendor test should not freeze the framework. A popular vendor should not receive an easier path than a small project with strong evidence. Self-reported results need visible trust labels. Admission and removal decisions should be documented. The working group's staged allowlist is a sensible start because it lets a project earn influence as its reporting becomes reliable. The plain signal is not that PyTorch has made every AI chip interchangeable. It has begun turning the hidden work of compatibility into public infrastructure. That can make the hardware market more competitive because new platforms have a clearer path into the software developers already use. It can also make weak integrations easier to spot because missing tests, unsupported features and downstream failures have somewhere to appear. The common entrance exam will not tell us which chip wins. It should tell us which ones are ready to sit for the harder tests.
01
WHAT ACTUALLY CHANGED
PyTorch published an October 5 update on first-half 2026 accelerator-integration work
The Cross-Repository CI Relay can dispatch upstream changes to registered downstream repositories and collect their results in one dashboard
Contributors migrated more than 276 test files toward device-agnostic execution across a suite containing more than 600,000 cases
OpenReg, OCCL and related examples provide reference paths for device, profiler, compiler and distributed integration
The Additional Platforms page adds a foundation-governed admission process requiring public evidence from accelerator vendors
02
WHY THIS MATTERS
Shared tests can catch downstream hardware breakage before an upstream PyTorch change is merged
Reference implementations reduce the need for new accelerator teams to reverse-engineer mature production backends
Public admission evidence can make platform support more inspectable than a vendor logo or one benchmark chart
A common integration path can reduce ecosystem fragmentation without claiming that hardware platforms are interchangeable
03
WHERE IT COULD HELP
- Run device-agnostic operator, autograd, profiling, compiler and distributed tests before accepting an accelerator backend
- Publish supported PyTorch versions, data types, operators, skipped tests, security policy and CI history in one compatibility card
- Use cross-repository checks to catch an upstream change before it breaks downstream hardware releases
- Benchmark representative end-to-end workloads with correctness, cost, power, latency, memory and failure recovery reported together
- Stage a backend from notification-only testing toward trusted blocking checks as its reliability and maintenance record improve
KEEP A HAND ON THE WHEEL
Watch the unclassified-test allowlist, downstream projects admitted to each CI tier, skip rationales, flaky-check handling, public Additional Platforms decisions, independent numerical-parity testing, compiler and distributed coverage, workload-level benchmarks, security disclosures and evidence that listed platforms remain maintained across future PyTorch releases.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Interoperability
The ability of different systems, devices, and data formats to work together without custom rebuilding at every connection.
OPEN GLOSSARY CARD
Inference
The moment a trained model uses what it learned to produce an answer.
OPEN GLOSSARY CARD
Benchmark
A fixed test used to compare how systems perform on the same tasks.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 6, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US