THE SIGNAL IN ONE SENTENCE
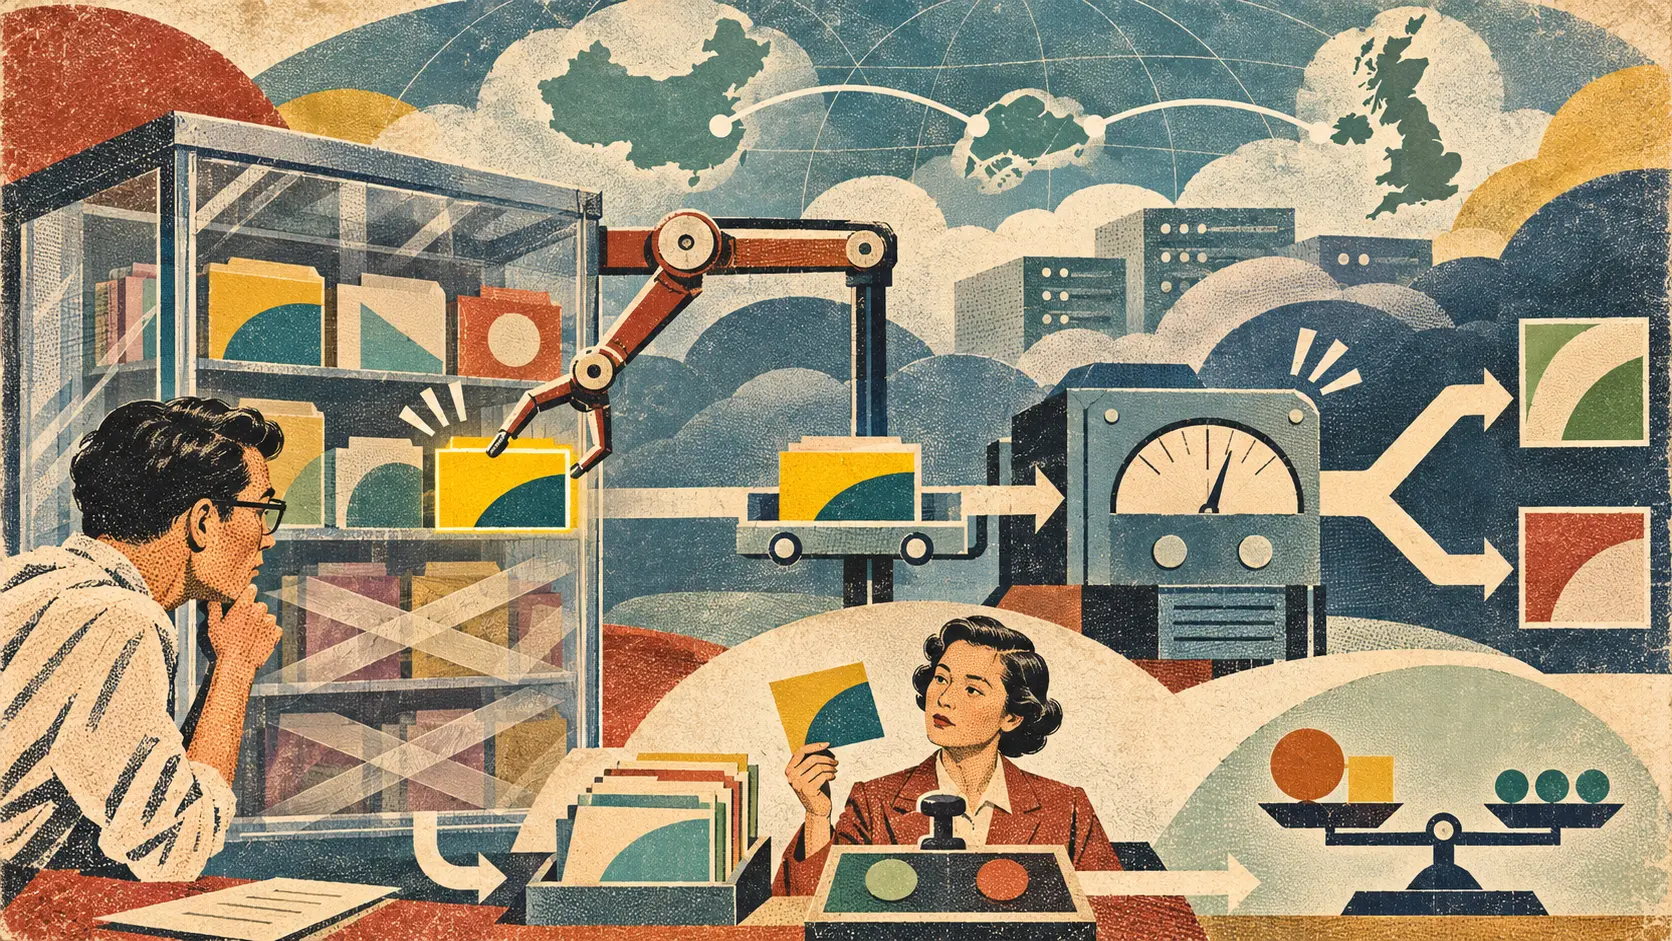
A memory system can fetch the correct fact and still make the wrong decision. That sentence sounds obvious until you look at how agent memory is usually demonstrated. The agent remembers a favorite restaurant. It recalls a project deadline. It finds a preference from three conversations ago. Everyone nods. The demo ends before the difficult part, which is whether the agent actually uses the current fact when it acts. Qwen Memory Agent did not end there. The open-source project was built by Ryan Duffy, an independent UK-based engineer, for an Alibaba Cloud hackathon. It uses Qwen Plus and Alibaba Cloud's text-embedding-v3 model, with the application deployed on an Alibaba Cloud ECS instance in Singapore. This is not an Alibaba product release. It is not an independent benchmark of Qwen. It is a small, inspectable engineering project with creator-reported results. That limitation is exactly why its most useful number is 0.60. The builder created a synthetic fixture with six personas and 24 queries. Across retrieval budgets from eight to 64 tokens, the system reported context recall of 1.000 and a staleness score of 0.000. In that controlled test, it retrieved the expected memory and avoided returning a superseded fact. Then the project ran ten multi-session scenarios that asked a harder question: did the agent produce the right outcome, store the right state and consult memory before deciding? The reported task success was 0.60. The component results were 0.80 for outcome, 0.90 for stored state and 0.70 for process. In plain English, the memory could be present and retrievable while the agent still skipped recall, attached an update to the wrong subject or failed to retire an older fact. That is a wonderfully inconvenient result. The project publishes examples of the failure modes. Some decision turns did not call recall before acting. A generic subject collision retired a dietary constraint that belonged elsewhere. A cross-subject update failed to supersede the fact it should have replaced. None of those failures are fixed by making the vector database slightly shinier. They sit at the joints between storage, identity, retrieval, tool use and decision-making. The project treats memory as structured state rather than a bag of chat fragments. Its remember, recall and forget tools support typed memories, provenance, semantic deletion, decay, supersession and budget-constrained retrieval. A live inspector exposes what is stored. Export and import make the state portable. A dreaming loop can propose consolidation, but a human must approve the change. That is a sensible architecture because memory errors are often history errors. Suppose a person tells an assistant, "I am vegetarian." Two weeks later they say, "I now eat fish." A naive memory system may keep both statements, retrieve whichever embedding ranks highest and let the model improvise a biography. A better system preserves both records and marks the relationship. The old statement should remain visible as superseded, not vanish as if it never existed. The new statement should record when it became valid, where it came from and which earlier record it replaced. Retrieval should prefer the current fact, while an inspector can still reconstruct the change. Deleting the old fact completely makes debugging harder. Returning it as current makes the agent wrong. Keeping it visible but inactive gives the system a history. Every persistent-memory agent needs that history. Call it a memory receipt. For each stored item, the receipt should include a stable memory ID, subject, type, content, source, creation time, validity period, model or human provenance, supersession links and deletion state. If a model inferred the memory rather than receiving it directly, label the inference and its confidence. When the agent retrieves memory, add the query, candidate set, selected records, similarity scores, filters, ranking reason and token budget. A tiny budget can force a useful fact out of context. A large budget can pull stale or irrelevant history back in. "The model had memory" is not an explanation unless we know what fit through the window. Then connect retrieval to the decision. The trace should show whether recall was called before a consequential action, which records entered the prompt, what instruction the agent derived from them and whether the final output followed the current fact. That last link is where ordinary recall metrics stop helping. A system can retrieve "meeting moved to Thursday" and still send the calendar invite for Wednesday. Retrieval succeeded. The task failed. If the evaluation scores only whether Thursday appeared in context, it grades the librarian and ignores the courier. Active-use evaluation should score the whole chain. Did the system store the update under the right subject? Did it supersede the right earlier record? Did the agent retrieve before deciding? Did the current fact enter the decision context? Did the final action respect it? Could an evaluator explain a failure from the trace? The Qwen Memory Agent evaluation separates outcome, stored state and process. That is a good start because one combined score can hide the actual defect. A failed outcome with correct storage suggests a reasoning or tool-use problem. Incorrect storage with a correct outcome may be luck. A skipped recall call means the system did not use its memory process even if the model guessed correctly. Production teams should go further. Test mutations, not only happy paths. Change a preference twice. Use two people with similar names. Correct a fact from another device. Ask the agent to forget one detail but retain the rest. Import a memory archive with older schema fields. Reduce the token budget. Add an adversarial note that tries to rewrite another person's state. Subject identity deserves special aggression. "My manager," "Sam," "the client" and an email address may refer to the same person, or to four different people. A memory system should not merge them merely because their text is similar. It needs explicit subject keys, scoped aliases and a review path for uncertain matches. The published repository notes a similarity threshold around supersession. Its validation pairs landed roughly between 0.879 and 0.908 for intended supersession examples, while distractors fell around 0.683 to 0.743. The default threshold is 0.9. Those ranges show why a single threshold is not a law of nature. One intended update can fall below it. A different domain, language or embedding model can shift the entire distribution. Thresholds need local validation, versioning and a record of what changed after an upgrade. Human approval matters most when the system rewrites its own history. Consolidation can reduce clutter by merging several memories into a summary. It can also erase nuance, flatten uncertainty or turn an old inference into a permanent fact. The proposed summary should show every source record, the text to be created, records to be retired and the reason for the change. A person should be able to approve, edit or reject it. Privacy cannot be bolted on after persistence. Users need to inspect, correct, export and delete their stored state. Deletion should cover the active store, indexes, derived summaries and queued consolidation jobs, with clear retention rules for backups and audit logs. Access controls should prevent one agent, tenant or tool from reading another's memory. Memory poisoning also needs a boundary. A web page, email or tool result should not become a trusted personal fact simply because the agent saw it. Store untrusted observations separately. Require provenance and confirmation before they can override user-supplied state. Treat instructions inside retrieved content as data, not authority. Finally, publish the misses. The Qwen Memory Agent project is small. Ten active-use scenarios cannot establish production reliability. Its perfect fixture result is not a universal claim, and its live 0.60 score was measured by the builder, not an independent evaluator. Still, the project contributes something many larger demos avoid: it places the clean retrieval result beside the messier task result and explains why they differ. That is useful engineering behavior. An agent should never get credit merely for remembering a fact it ignored. Keep the old fact visible. Keep the current fact explicit. Keep the recall trace attached to the decision. Keep the human approval at the point where history changes. Then score what the agent actually did. Memory is not the card in the cabinet. Memory is whether the right card changed the choice.
01
WHAT ACTUALLY CHANGED
Ryan Duffy published Qwen Memory Agent as an MIT-licensed open-source hackathon project on November 3, 2026.
The system uses Qwen Plus, Alibaba Cloud text-embedding-v3 and an application deployed on Alibaba Cloud ECS in Singapore.
Its memory layer supports typed records, provenance, supersession, semantic forgetting, decay, token-budgeted recall, export, import and a live inspector.
A human-approved consolidation loop can propose memory summaries without silently rewriting stored history.
A six-persona, 24-query synthetic fixture reported 1.000 context recall and 0.000 staleness across retrieval budgets from eight to 64 tokens.
A separate ten-scenario active-use evaluation reported 0.60 task success, with outcome at 0.80, stored state at 0.90 and process at 0.70.
The builder documented skipped recall calls, a generic-subject collision and a missed cross-subject supersession as observed failure modes.
02
WHY THIS MATTERS
A memory can be correctly stored and retrieved while the agent still ignores it during a consequential decision.
Separating outcome, stored state and process makes it easier to locate a failure than a single recall score.
Superseded facts need a visible history so users and operators can distinguish a correction from unexplained deletion.
Subject collisions can apply one person or project's update to another, creating privacy and reliability failures.
Token budgets, similarity thresholds and embedding versions can change which memories reach the model.
Human approval before consolidation protects against silent summaries that erase nuance or promote an inference into fact.
Publishing failed scenarios gives other builders more useful evidence than a demonstration containing only successful recall.
03
WHERE IT COULD HELP
- Give every memory a stable ID, subject key, type, source, validity period, provenance and supersession links.
- Preserve superseded records as visible inactive history instead of deleting them or returning them as current.
- Record the recall query, candidate set, ranking scores, filters, selected memories and token budget for each decision.
- Require a recall step before actions that depend on user preferences, deadlines, permissions or prior commitments.
- Score outcome, stored state and process separately, then investigate disagreements between those scores.
- Test repeated corrections, similar names, cross-device updates, partial forgetting, schema migration and constrained token budgets.
- Use explicit subject keys and reviewed aliases instead of merging identities from text similarity alone.
- Revalidate supersession thresholds whenever the domain, language, embedding model or memory schema changes.
- Show proposed consolidation beside every source record and require a person to approve, edit or reject it.
- Provide inspection, correction, export and deletion controls that cover indexes, summaries and queued jobs.
- Separate untrusted observations from confirmed user facts and prevent retrieved instructions from gaining authority.
- Publish active-use failures and the regression tests added after each material memory incident.
KEEP A HAND ON THE WHEEL
This is an independent hackathon project using Qwen and Alibaba Cloud services, not an Alibaba product release or independent benchmark. The synthetic fixture contains six personas and 24 queries, and the active-use evaluation contains ten scenarios. All reported results come from the builder. Watch for external reproduction, larger multilingual fixtures, adversarial identity tests, privacy and deletion audits, performance under longer histories, threshold sensitivity, model-version changes and evidence that human-approved consolidation remains practical at scale.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 3, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US