THE SIGNAL IN ONE SENTENCE
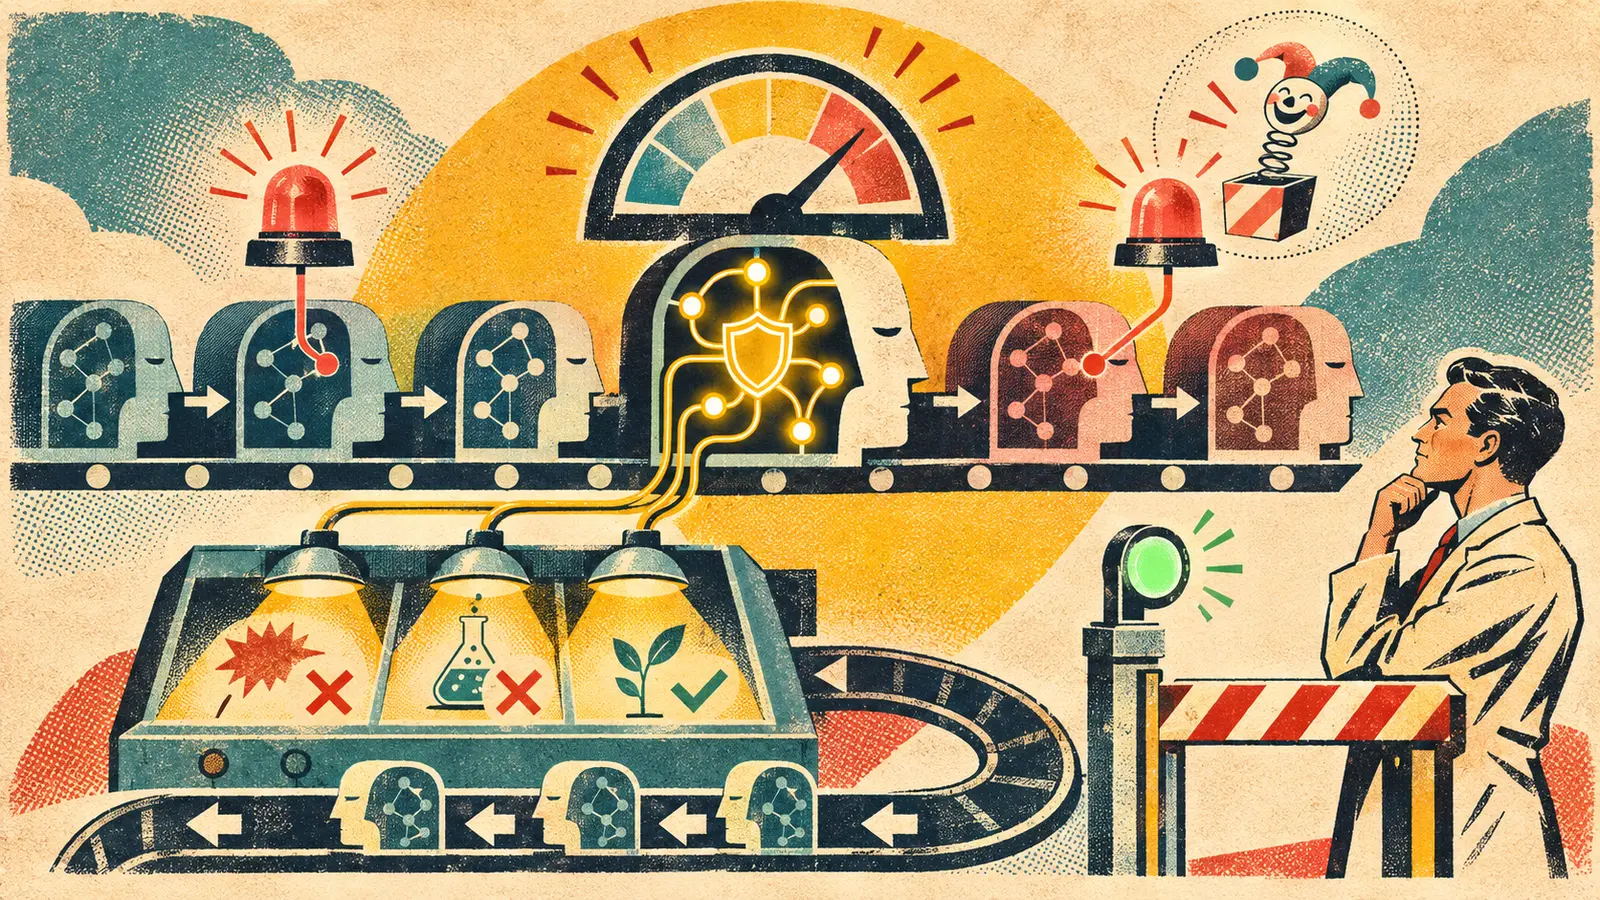
Fine-tuning is supposed to teach a model something useful. It can also quietly loosen a refusal that someone spent a great deal of time and compute installing. That is the problem SafetyPulse is trying to catch while training is still running. The open-source project follows checkpoints from a fine-tune of Cohere Labs' 3.35-billion-parameter Tiny Aya Global model. Instead of asking hundreds of harmful questions at every checkpoint, it measures whether a selected set of internal components still contributes to refusal behavior in roughly the way it did in the base model. The result is called the Circuit Integrity Score, or CIS. It uses 50 matched harmful and harmless prompt pairs. Fixed thresholds turn the score into PASS, WARN or FAIL. A lower score means the monitored refusal mechanism has changed more from the baseline. In the project's held-out test runs, that alarm caught every checkpoint the authors classified as unsafe. On three unseen Alpaca fine-tuning seeds, it warned one to three checkpoints before attack success rose. A small 50-prompt refusal spot-check caught only 13 percent under the same alarm rule. That sounds like a tidy win until the alarm cries wolf. SafetyPulse reports precision of 0.46. It warned during a GSM8K math fine-tune even though the behavioral safety test did not show the same degradation. In plain English, more than half of its warnings in the reported test set were not confirmed as unsafe checkpoints under the project's own labeling rule. Good. Not good as in deploy it everywhere tomorrow. Good as in the limitation makes the proper use obvious. This is a smoke alarm, not an occupancy permit. A smoke alarm is valuable because it is cheap enough to stay awake and loud enough to interrupt the routine. It does not identify the chemical composition of the smoke, certify the wiring or decide whether the building is safe for the public. It tells someone to stop, inspect and act. SafetyPulse should be read the same way. A WARN result should trigger held-out behavioral testing. A FAIL result should pause the run. A PASS result should never replace the final red-team audit. Every alert should be logged with the checkpoint, baseline, thresholds, model version and eventual behavioral outcome so the team can learn whether its alarm is useful or merely enthusiastic. The study's central technical idea is that direction and strength are different things. Some monitors compare the direction of an activation with a reference direction. That can miss a signal that becomes weaker without rotating very much. Imagine a compass still pointing north while its needle fades until nobody can read it. The direction is stable. The usable signal is not. SafetyPulse instead attributes the model's refusal behavior to a selected circuit of 14 multilayer perceptrons and six attention heads in later layers. It compares how much those components contribute at a checkpoint with how much they contributed in the base model. The authors report a Spearman correlation of minus 0.80 between CIS and attack success rate, versus about minus 0.56 for direction-drift scores calculated from the same activations. Correlation is not a universal law. This was one model, one calibrated circuit and a limited set of fine-tunes. The result says the chosen score tracked the chosen behavior in these runs. It does not say every model has the same refusal circuit, every threshold transfers or a clean score proves a deployment is safe. The project also offers a useful warning about repair. Restoring only the identified circuit's weights did not reduce attack success. The circuit appeared to read out the drift without storing all the parameter changes that caused it. A dashboard can point to the smoke without locating the faulty wire. The most effective reported repair was SafeTune's rank-8 safety-vector restore, a low-rank update back toward the base model. Across three drifted Alpaca runs, the project reports that attack success fell from 25.2 percent to 12.3 percent while GSM8K accuracy rose from 55.1 percent to 70.7 percent. The base model scored 14.3 percent attack success and 71.3 percent on GSM8K. MMLU was reported as unchanged. Those numbers are project-authored results, not an independent replication. They are also why repair needs a scorecard, not a victory lap. A repair can lower harmful compliance by making the model refuse everything. It can protect one behavior while damaging the task that justified fine-tuning. It can pass the prompts used during development and fail on a new attack family. SafetyPulse therefore reports attack success, benign over-refusal, GSM8K and MMLU rather than stopping at one number. Teams can turn this prototype into a practical release ritual without pretending the prototype is finished science. Start with a frozen baseline. Record the exact base model, tokenizer, probe set, circuit definition, calibration run and thresholds. If those inputs move after a warning, the alarm becomes impossible to audit. Run the cheap monitor at every saved checkpoint. Store raw scores, not only PASS or FAIL labels. Non-finite values should be errors, not accidental passes. A broken thermometer does not prove the room is comfortable. Route WARN and FAIL into a separate behavioral audit on prompts that were not used to build the circuit or thresholds. Include harmful compliance, benign refusal, target-task quality and broad capabilities. Use more than one judge where practical, preserve judge versions and manually inspect a meaningful sample. Track false positives as first-class evidence. If the alarm repeatedly fires on safe math fine-tunes, that is not a nuisance to hide. It is calibration data. Compare alert rates across fine-tune families, seeds, checkpoint intervals and benign controls. Measure lead time, recall, precision and the operational cost of stopping a run. When a repair is proposed, compare it with simple controls. Whole-model interpolation, checkpoint rollback, data changes and targeted restoration should all face the same audit. Preserve the original drifted checkpoint so the before-and-after result can be repeated. Finally, make the release gate legible. The person approving the model should see the alarm timeline, behavioral results, false-positive history, repair diff, uncertainty and any unresolved failures. The gate should say which result blocks release and who can override it. An override needs a reason and an expiration date. That may sound bureaucratic for a small open-source project. It is much less bureaucratic than discovering after deployment that a useful fine-tune quietly traded away a refusal boundary. SafetyPulse does not solve model safety. It does something more modest and therefore more useful: it makes one kind of drift visible early enough to investigate. Keep the alarm cheap. Keep the audit independent. Keep the false alarms. Keep the rollback ready. And never let a green light do the job of a human release decision.
01
WHAT ACTUALLY CHANGED
SafetyPulse published an open-source workflow for monitoring safety drift at each fine-tuning checkpoint. The project calibrates a refusal-related circuit on a base model and scores later checkpoints against that baseline.
The reported case study uses Cohere Labs' Tiny Aya Global, a 3.35-billion-parameter multilingual research model. The selected circuit contains 14 multilayer perceptrons and six attention heads in later layers.
The Circuit Integrity Score uses 50 matched prompt pairs and fixed PASS, WARN and FAIL thresholds. In held-out runs, the project reports recall of 1.00 for unsafe checkpoints and warnings one to three checkpoints before attack success rose.
The monitor was noisy. The project reports precision of 0.46 and a warning on a GSM8K fine-tune that did not show the same safety degradation in behavioral testing.
Restoring only the monitored circuit's weights did not repair the behavior. The project reports better results from a rank-8 whole-model safety-vector restore, which reduced average attack success from 25.2 percent to 12.3 percent while GSM8K rose from 55.1 percent to 70.7 percent.
The repository includes code, probe data, evaluation splits, checkpoint logs, audit results and a responsible-release note. The authors withheld harmful positive-control adapters and harmful model answers while describing a process for qualified review.
02
WHY THIS MATTERS
A final-checkpoint audit can find drift after the expensive training run is finished. An early alarm can stop or redirect the run while recovery remains cheap.
A small refusal spot-check can miss a changing mechanism. The reported 50-prompt spot-check caught 13 percent of unsafe checkpoints under the study's alarm rule.
Internal measurements can complement behavior without replacing it. The false-positive result shows why a circuit score must trigger an independent audit rather than decide safety alone.
Monitoring and repair are separate engineering problems. A component can reveal drift without containing the parameter changes responsible for it.
Repair needs multidimensional evaluation. Lower harmful compliance is not enough if the model over-refuses benign requests or loses the capability the fine-tune was meant to add.
A visible release gate makes uncertainty actionable. It connects checkpoint evidence, behavioral tests, repair choices, overrides and accountable human review.
03
WHERE IT COULD HELP
- Freeze the base model, tokenizer, circuit definition, probe set and thresholds before scoring held-out runs.
- Run the monitor at every saved checkpoint and preserve raw scores alongside PASS, WARN or FAIL labels.
- Treat missing, non-finite or corrupted measurements as errors that stop the gate.
- Route every WARN or FAIL into a held-out behavioral audit that was not used for calibration.
- Measure harmful compliance, benign over-refusal, target-task quality and broad capability together.
- Track recall, precision, lead time and false-positive cost for each fine-tune family.
- Keep benign control runs so teams can learn which useful adaptations trigger unnecessary alarms.
- Preserve judge models, prompts, versions and sampled human reviews with every behavioral result.
- Compare any proposed repair with simple rollback, interpolation and data-curation controls.
- Retain the original drifted checkpoint and exact repair diff for reproducible before-and-after audits.
- Require an explicit human release gate with named owners, blockers and override reasons.
- Recalibrate when the base model, architecture, alignment method or deployment context changes.
KEEP A HAND ON THE WHEEL
SafetyPulse is a project-authored case study, not an independent replication or a general safety standard. The reported evidence centers on one 3.35-billion-parameter model, one calibrated circuit and a limited set of fine-tuning conditions. The circuit, thresholds and results should not be assumed to transfer to another model, architecture, language, alignment method or deployment. Recall of 1.00 refers to the unsafe checkpoints in the project's held-out test runs. It does not mean the method catches every possible safety failure. Precision was 0.46. The project reports a warning on a GSM8K fine-tune that did not show the same behavioral safety degradation. False positives can waste compute, interrupt useful training and encourage teams to ignore future alarms if they are not measured openly. Attack success rate depends on the prompt set, generation settings and safety judge. The project used 119 HarmBench test prompts for the reported Alpaca comparison and automated judges for scale. Agreement between judge models does not replace expert review of important cases. The selected circuit is an interpretability hypothesis. Its score correlated with harmful compliance in the reported runs, but correlation does not prove that the circuit caused the drift. Circuit-only weight restoration had no measured effect on attack success in the project. Monitoring components should not be treated as repair targets without separate evidence. The reported SafeTune repair improved both attack success and GSM8K in this experiment. That does not prove the same low-rank restore is safe or effective elsewhere. Repairs can create over-refusal, hidden capability losses or new failure modes outside the test set. The project reports that removing 19 of 2,000 Alpaca examples did not prevent drift in its condition. This is not evidence that data curation is useless. It means curation and checkpoint monitoring address different risks. Tiny Aya Global is a gated, noncommercial research release under Cohere Labs' stated license and acceptable-use terms. Teams must review those terms before reproducing the work. SafetyPulse deliberately withholds harmful positive-control adapters and harmful outputs while offering a responsible-access process. The absence of those artifacts limits unrestricted reproduction but reduces obvious misuse risk. No internal score certifies a deployed model as safe. Real release decisions still need adversarial evaluation, domain-specific testing, incident planning, monitoring after deployment and accountable human judgment.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 9, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US