THE SIGNAL IN ONE SENTENCE
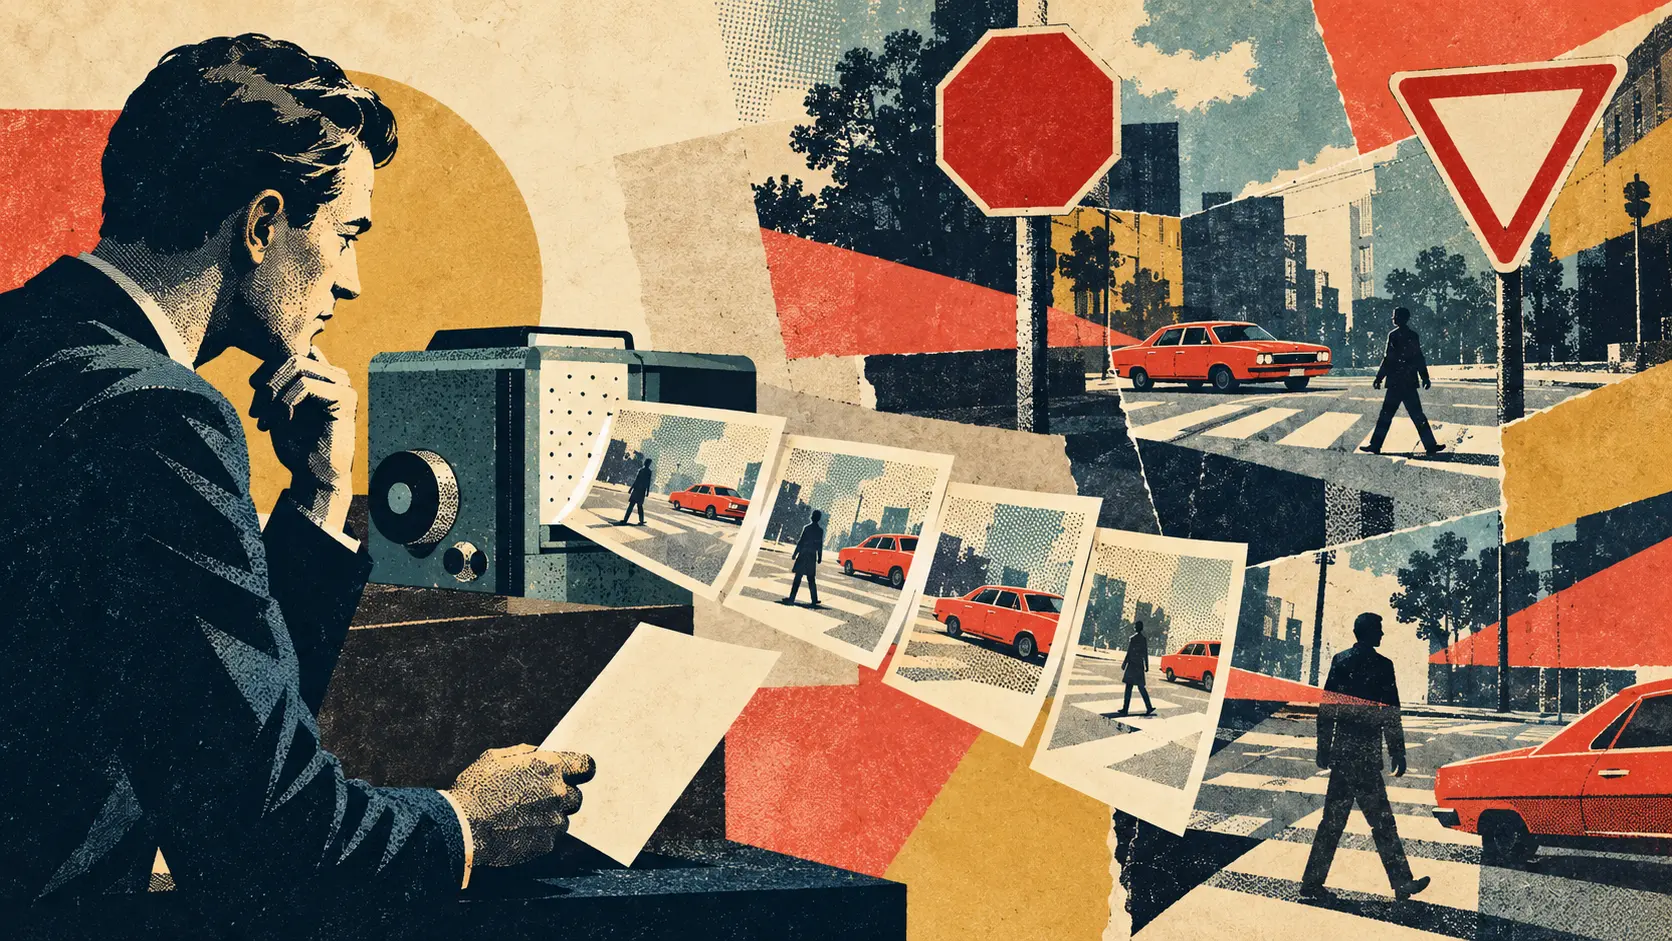
The usual safety plan for an imperfect AI summary is simple: let a person review it. A new study asks what happens when the reviewer's own memory is easier to edit than the document. Researchers at Georgetown University and the University of Washington showed adults a 25-second animated car-pedestrian accident. A day or two later, participants read a 21-sentence summary that accurately named the traffic sign or quietly swapped a stop sign for a yield sign, or the other way around. The people were then told to answer from their memory of the original video. Among the 328 participants included in the analysis, 83.6 percent who received a consistent summary recalled the sign correctly. Only 44.8 percent who received the misleading version did. Calling the exact same summary AI-written or human-written did not produce a significant difference. Reported trust in AI and frequency of chatbot use did not rescue memory either. A companion test of twenty summaries produced by ChatGPT-5.5 and Gemini 2.5 Flash-Lite found errors in every one, including omissions of 51.6 percent of the researchers' nineteen central details on average. That model test was tiny, and the memory experiment manipulated one detail in two simple animated clips. It does not establish an error rate for real police reports, medical records or workplace incident summaries. It does establish a mechanism those deployments cannot wave away. Once a generated account becomes the first clean narrative a witness, officer, clinician or investigator rereads, the human in the loop may absorb the mistake instead of catching it. The plain signal is that review order matters. Preserve the original evidence, record an independent human account before showing the generated summary, display uncertainty and source links next to every claim, and keep the person who verifies the record from becoming its first test subject.
01
WHAT ACTUALLY CHANGED
Mattea Sim, Yael Eiger and Tadayoshi Kohno posted the study to arXiv on September 23, 2026.
The paper combines a small analysis of generated video summaries with a controlled human-memory experiment.
For the model analysis, the researchers used two 25-second animated car-pedestrian accident videos that differed in whether the intersection had a stop sign or a yield sign.
They prompted ChatGPT-5.5 and Gemini 2.5 Flash-Lite five times per video, creating twenty summaries in total.
The prompt asked for a factual, neutral account of at least 300 words, instructed the model not to introduce facts or interpretations and told it to include everything important.
All twenty summaries contained errors. The count ranged from seven to twenty-one errors in summaries averaging 305 words.
Across the twenty summaries, 51.6 percent of nineteen preidentified central details were omitted on average.
Ninety-five percent of the summaries omitted the central event that the car collided with the pedestrian.
Sixty-five percent of the summaries inaccurately described at least one central detail, while ninety percent included at least one noncentral inaccuracy.
The separate human experiment recruited 360 U.S.-based adults through Prolific for its first part.
After attention checks and completion requirements, 328 participants remained in the analysis.
Participants watched one accident video, waited 24 to 48 hours and then read a 21-sentence summary generated with ChatGPT and lightly standardized by the researchers.
The experimental manipulation changed one critical fact: whether the summary named the same traffic sign shown in the video or the other sign.
Participants were also told that the summary came from either AI software or a professional human transcriber, even though the underlying text was the same.
Correct recall of the traffic sign was 83.6 percent after a consistent summary and 44.8 percent after a misleading summary.
The difference was statistically significant, with a chi-square value of 53.937 and a reported probability below .001.
The source label, AI or human, did not significantly change correct recall within either information condition.
Neither reported trust in AI nor frequency of chatbot use significantly moderated the effect in the researchers' models.
The authors released data and supplementary material through the Open Science Framework.
A shortened version is listed for the October 2026 AAAI/ACM Conference on AI, Ethics, and Society.
02
WHY THIS MATTERS
A human reviewer is not an independent checksum if the output being reviewed can alter what that person remembers.
Generated summaries are persuasive partly because they turn messy evidence into one coherent sequence, and coherence can make a wrong detail feel settled.
The most dangerous error may be a plausible substitution rather than an absurd hallucination that invites immediate correction.
Reviewing a summary before recording an independent recollection can contaminate the baseline that an organization later treats as human confirmation.
Police reports, witness interviews, clinical handoffs and workplace incident reviews all depend on chronology and small details whose legal or medical importance may not be obvious at first.
A traffic sign was the only manipulated fact here, but the same mechanism could matter for names, times, symptoms, doses, directions or who performed an action.
A source label is a weak safeguard when the study found similar susceptibility among people who believed the text came from AI and those who believed it came from a human.
General skepticism toward AI did not eliminate the observed effect, so a warning badge cannot carry the whole safety burden.
The model-analysis result shows that omission deserves as much attention as fabricated detail. A summary can be grammatically clean while erasing the event that matters most.
A reviewer cannot verify an omitted detail if the interface hides the source moment and presents only the compressed narrative.
The study does not show that every AI summary distorts memory, nor that the measured percentages will transfer to real cases.
Its contribution is causal and narrower: in this controlled setting, changing one generated detail changed later recall by a large margin.
That is enough to challenge product designs that use a person's final approval as the only quality control.
Good systems must protect human memory as part of the evidence chain, not treat it as an unlimited error-correction resource.
The work also suggests a documentation principle: the original media, the generated draft, every edit and the final human account should remain distinguishable rather than collapsing into one polished record.
For researchers, the small stimulus set makes replication with body-camera footage, medical encounters, meetings and longer delays the obvious next step.
03
WHERE IT COULD HELP
- Collect and timestamp a witness or operator's independent account before displaying any generated summary.
- Preserve original video, audio, sensor records and documents as the primary evidence rather than replacing them with a narrative.
- Link each summary sentence to the exact source segment, transcript span or record field that supports it.
- Mark unsupported inference, uncertain identity and missing context directly beside the claim instead of burying caveats at the end.
- Show reviewers the source evidence first, then the generated draft, so the model does not set the initial frame.
- Require a reviewer to flag contradictions and omissions, not merely click approve on fluent prose.
- Use a second reviewer who has not read the generated version when a detail could affect liberty, diagnosis, discipline or money.
- Separate factual extraction from narrative synthesis and test each layer independently.
- Maintain a visible edit history showing which words originated with the model and which were added or confirmed by people.
- Do not let the system silently overwrite a reviewer's earlier notes after the generated summary appears.
- Design accuracy tests around critical details and omissions, not only overall similarity to a reference summary.
- Measure whether review interfaces improve detection without degrading later recall of the source event.
- Test plausible substitutions such as dates, names, directions and quantities, not only conspicuous hallucinations.
- Train staff to treat a polished summary as a hypothesis that needs evidence, not as a memory aid that becomes the record.
- For high-stakes uses, retain the generated draft separately and require a signed human account with source citations.
- Audit downstream documents to learn whether an early summary error is copied into later reports, decisions and testimony.
- Give affected people a correction path that preserves the original record and explains where the mistaken claim traveled.
- Pause automated summarization when the source is incomplete, corrupted or too ambiguous to support sentence-level verification.
KEEP A HAND ON THE WHEEL
This is a preprint, and its conclusions are deliberately narrower than the headline risk. The model analysis used twenty outputs from two models, one prompt and two short animated videos. It was not designed to estimate a general hallucination rate. The human experiment tested 328 U.S.-based Prolific participants, one manipulated traffic-sign detail and a summary generated by ChatGPT, then lightly standardized so it could be used across both videos. The design gives the researchers experimental control, but it is not a live police, medical or workplace workflow. Participants knew they were in an online study, and the measured outcome was a two-choice recognition question after a 24 to 48 hour delay. The study did not compare multiple interface designs, test source-linked summaries, measure professional investigators or establish how long the effect persists. The reported 83.6 percent and 44.8 percent therefore describe these conditions, not an expected error rate for every deployment. The analysis also found that the AI or human label did not significantly change susceptibility, but absence of a difference here does not prove labels never matter. Watch for independent replications, more realistic footage, audio-only records, longer delays, varied errors, professional users and tests of concrete safeguards such as source-first review, blind independent accounts and sentence-level evidence links.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 26, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 26, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US