THE SIGNAL IN ONE SENTENCE
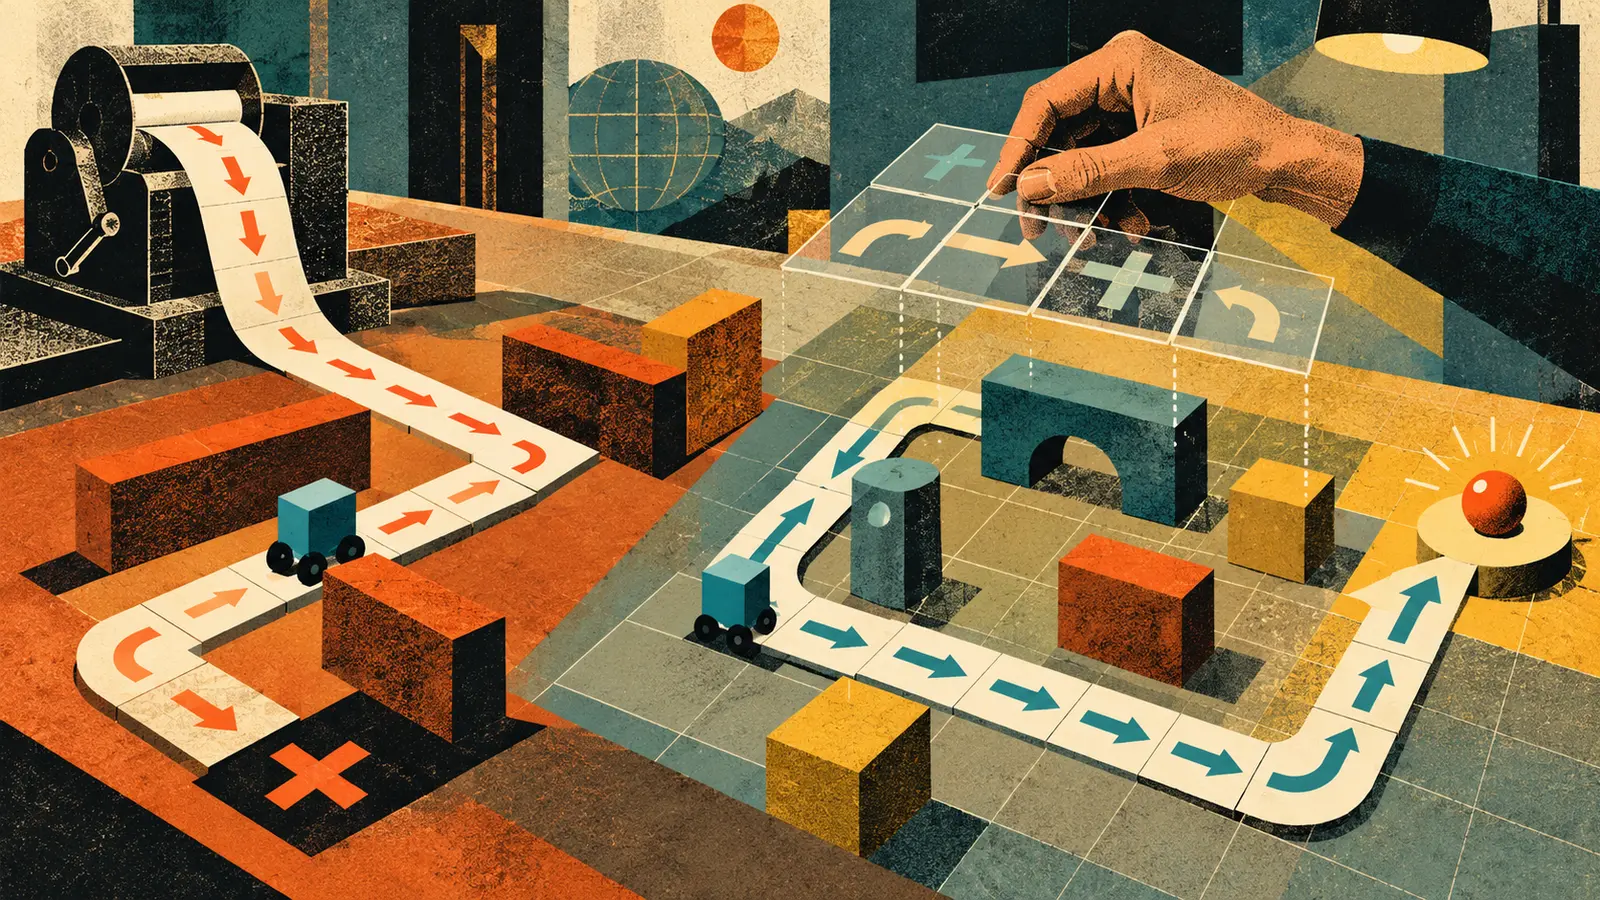
A world model is supposed to learn what happens next when an agent takes an action. That sounds different from learning what an expert usually does next. AnyGoal is a new benchmark built to find out whether current systems know the difference. The October 19 preprint comes from Heejeong Nam, Divyat Mahajan, Quentin Le Lidec, Randall Balestriero and David Klindt, with affiliations at Brown University, Cold Spring Harbor Laboratory, Mila, Université de Montréal and New York University. It asks a compact but difficult question. If a model has already seen the pieces, can it obey the same physical rules when those pieces are recombined around a new goal? The answer in the authors' controlled experiments is often no. The plain signal is this: test a world model by moving the finish line while keeping the rulebook still. AnyGoal starts with four familiar research environments. TwoRoom is a simple navigation problem. Push-T asks an agent to push a T-shaped block into a target pose. DMC Manipulator Insert-Peg uses a simulated arm and peg. OGBench Cube uses a robot manipulator and a cube. The benchmark adds eight goal-shifted variants. Some ask for free movement through familiar space. Others change the contact problem, such as avoiding a block instead of pushing it, extracting a peg instead of inserting it, or moving a cube along a different relationship. The important detail is what does not change. The environment dynamics remain the same. The benchmark is designed so the individual physical factors and actions are familiar from training. The new task changes which familiar states and actions occur together. The paper calls this the combinatorial gap. Imagine that a warehouse robot has learned to approach a pallet from the east, lift it and carry it to one marked bay. During training it has separately moved west, seen another bay and handled the same pallet. A new job asks it to approach from the west and place the pallet in that other bay. No ingredient is novel. The recipe is. That is where a model that learned transition rules should have an advantage over a model that learned the shape of successful demonstrations. The first can reason about the effect of a westward action from this state. The second may quietly expect the robot to behave the way the expert behaved in the training data. AnyGoal makes that shortcut testable. The authors apply three factor-wise support checks to every base and target pair. A range check asks whether target samples stay within the coordinate ranges seen in the reference data. A Mahalanobis-distance check tests whether at least 95 percent of target samples sit below the reference distribution's 0.99 quantile. A kernel-density check requires at least 95 percent of target samples to remain above a low reference-density threshold. All eight variants were designed to pass the combined factor-wise test. The researchers also estimate how poorly covered the full joint combinations are. In other words, AnyGoal does not simply throw a purple cube or a new action into the test and call the failure surprising. It tries to preserve familiar factors while changing their pairing. The benchmark includes 400 episodes for each goal-shifted variant. Its open-source library supports data collection, training, rollout evaluation and model-predictive-control planning through Python and a command-line interface. A researcher can load one base-trained checkpoint, evaluate it on the original task, then point the same checkpoint at a new goal. The study covers five end-to-end world models and three oracle-state predictor families. The end-to-end set includes LeWorldModel, Sensorimotor World Model, DINO-WM, DriftWorld and IRASim. The oracle-state predictors receive task-relevant physical variables directly instead of having to infer them from pixels. That second group matters because it helps separate two failure modes. An end-to-end model can fail before its dynamics predictor gets a fair chance. A familiar agent position and a familiar block pose may produce a visual arrangement that the encoder rarely saw together. If the representation bends or collapses that new combination, planning is already in trouble. Giving the predictor the true state removes that visual interpretation problem. If it still fails, the problem is closer to the learned dynamics and their use by the planner. The results do not reduce to one clean ranking. The paper explicitly warns that goal-shift performance depends on the environment, whether interaction is required, the prediction space, the metric, the model family and the planning method. Rollout error can worsen while planning remains useful, or look stable while control collapses. That is not statistical clutter. It is the point. In free-space variants, oracle-state predictors often preserved or improved model-predictive-control performance. The paper names TR-Route, Avoid-T, Avoid-Peg and Cube-Hop in this group. When exact contact mattered, however, the privileged predictors also degraded. Stack-T, Push-T Antigoal, Extract-Peg and Cube-Diagonal were harder even when task-relevant state factors were supplied directly. The authors interpret this as an interaction-dependent dynamics gap. Free motion often allows many routes to the goal. Contact-rich manipulation has fewer viable action sequences, because the timing, pose and interaction must be right together. The absolute planning table makes the contrast vivid. On the original Push-T task, four of the five end-to-end models reported success rates from 43.3 percent to 84.7 percent, while IRASim reported 5.3 percent under this setup. On Avoid-T, where the agent had to avoid the block using familiar two-dimensional navigation, those five models ranged from 0 to 6.7 percent. The oracle-state predictors reached 89.3 to 92.7 percent on Push-T and 99.3 to 100 percent on Avoid-T. That tells us the end-to-end Avoid-T collapse was not a universal impossibility. The visual representation and learned latent geometry were part of the problem for those systems. Contact-rich shifts expose a different warning. On Insert-Peg, oracle-state planning success ranged from 71.3 to 74 percent. On Extract-Peg, it fell to 16.66 to 25.33 percent. Privileged coordinates did not carry the interaction rule into the reversed goal. These numbers are author-run results from a new preprint. They are not independent replication, and they should not be compared as if every model used the same representation, objective or planning geometry. The authors say oracle state access does not guarantee better planning, because a planner may find one learned representation easier to optimize than a raw physical state vector. The benchmark also reveals why an action input is not proof of action-conditioned reasoning. Expert data couples states with the actions a successful policy chose in those states. A predictor can fit those trajectories by learning the behavior policy's usual next move and largely ignoring the action supplied at evaluation time. On the expert rollouts, that shortcut can have very low error. On a new goal that asks for a different familiar action in the same familiar region, it can fail immediately. The paper probes this with action interventions. It compares a model's prediction under the recorded action with predictions under alternative actions that remain inside the empirical action range. Weak sensitivity in a region where actions should change the next state is evidence that the model may be replaying the training behavior instead of modeling controlled dynamics. That idea travels well beyond benchmark robotics. A software agent may learn that refund requests usually end with one workflow, then fail when policy changes the goal but keeps the same screens and buttons. An energy controller may know every device state and every allowed control but fail when a new tariff changes which combination is useful. A game agent may recognize the map and all legal moves yet keep chasing the old objective. A warehouse planner may know every aisle and action but break when priority shifts from speed to cold-chain safety. Those are Plain Signal examples, not demonstrations in the AnyGoal paper. The operational lesson is the same: a familiar interface does not make a new objective in-distribution. Teams evaluating a world model should build a rule-transfer matrix before handing it authority. List the state variables the system observes. List the actions it can take. Name the transition rules that should remain stable. Then identify the goals represented in the training data and the combinations of state, action and interaction regime that those goals actually produced. Do not stop at marginal coverage. Seeing a westward action somewhere and a loaded pallet somewhere else does not establish that the model knows what a westward action does while loaded. Joint coverage matters. Create goal-shifted tests that reuse known factors. Change the destination, route, order, priority, constraint or success condition. Test free movement separately from contact, grasping, collision and handoff. Apply alternative valid actions at the same state and check whether predictions respond in the right direction. Then compare at least three layers. First, measure one-step and multi-step prediction against real transitions. Second, test whether the planner reaches the new goal in the actual environment, not only inside the model's imagination. Third, inspect whether the representation still separates the physical factors needed for control. The system should also know when the combination is under-covered. Track uncertainty or disagreement, but do not pretend a confidence score repairs a missing mechanism. Require the agent to stop when observation contradicts prediction. Keep hard safety constraints outside the world model. Put a human or an independently verified controller in charge of consequential exceptions. AnyGoal has important limits. It is a preprint built around controlled simulated environments. Four base tasks and eight variants do not measure every kind of world knowledge, planning or physical intelligence. Passing the benchmark would not prove that a robot understands a factory. Failing it does not prove that the same model will fail every physical deployment. The support checks are statistical tests over chosen factors and distributions, not a certificate that every relevant physical condition has been covered. The end-to-end models differ in architecture and prediction space, which complicates direct comparisons. Model-predictive control adds its own cost function and optimizer. A poor plan can reflect the model, the representation, the planner or their interaction. The authors' proposed theoretical direction is also deliberately modest. They describe sparse local mechanisms and regime-conditioned support as an illustrative sufficient condition, not a complete recipe. It does not solve mechanism discovery, interaction-regime discovery or genuinely new local physics. Still, AnyGoal improves the question. The usual test asks whether a model can continue a trajectory that looks like the ones it studied. The more revealing test asks whether the model can take the same world, the same actions and the same physical rules somewhere the expert did not choose to go. Move the finish line. Then watch whether the rules move with it.
01
WHAT ACTUALLY CHANGED
AnyGoal was released as a benchmark, paper and open-source Python library
The benchmark builds goal shifts from four widely used world-model environments
Eight variants test familiar physical factors and actions in underrepresented combinations
Each variant includes 400 released episodes plus tools for collecting more data
Three factor-wise checks test whether target factors remain within training support
Five end-to-end world models span JEPA-style and generative approaches
Three oracle-state predictor families separate representation from dynamics failure
Free-space transfer was often easier than contact-rich goal transfer
Rollout error and model-predictive-control success did not always move together
Action interventions test whether a model follows the supplied action or training behavior
02
WHY THIS MATTERS
Expert demonstrations cover chosen state-action pairings, not every valid recombination
Low training error can coexist with a predictor that largely ignores the queried action
A new goal can break a system even when every state and action is individually familiar
Visual encoders may fail on new combinations before dynamics prediction begins
Privileged state access does not automatically repair contact-rich dynamics
Free-space planning can tolerate errors that precise manipulation cannot
Stable rollout metrics do not guarantee that a planner will reach the goal
Joint state-action coverage matters more than a checklist of separately observed factors
Operational systems need a stop rule when observation contradicts predicted dynamics
A benchmark pass is evidence about a bounded test, not proof of physical understanding
03
WHERE IT COULD HELP
- Inventory state variables, actions, goals and interaction regimes before evaluation
- Map which state-action combinations actually appear in training trajectories
- Construct goal shifts that reuse known factors under new success conditions
- Test navigation separately from contact, grasping, collision and handoff
- Intervene with alternative valid actions at the same familiar state
- Measure one-step prediction, long-horizon rollout and real planning success
- Compare learned representations with task-relevant state variables when possible
- Track prediction disagreement in under-covered combinations
- Stop the controller when real observations contradict the model
- Keep hard safety constraints and consequential approval outside the world model
KEEP A HAND ON THE WHEEL
Watch for independent replication; evaluations on physical systems; more environments and interaction regimes; goal shifts that preserve marginal support while varying real operational constraints; tests that cross model, representation and planner under matched conditions; methods that force action sensitivity; data collection aimed at joint rather than marginal coverage; calibrated uncertainty in the combinatorial gap; failure analysis that separates encoder, dynamics and planner errors; and evidence that gains on AnyGoal transfer beyond the benchmark.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
World model
A model that predicts how an environment changes after an action so an agent can simulate possible futures and plan.
OPEN GLOSSARY CARD
Compositional generalization
The ability to combine familiar parts or factors correctly when their particular arrangement was rare or absent during training.
OPEN GLOSSARY CARD
Behavior-policy shortcut
A prediction strategy that copies what a training policy usually did in a state instead of learning the effect of the action supplied now.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 20, 2026.
PUBLICATION RECEIPT: This article reports the preprint authors' controlled benchmark results. The deployment checklist and examples outside the four benchmark environments are Plain Signal analysis. AnyGoal is a new preprint and does not establish reliability in physical deployments.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US