THE SIGNAL IN ONE SENTENCE
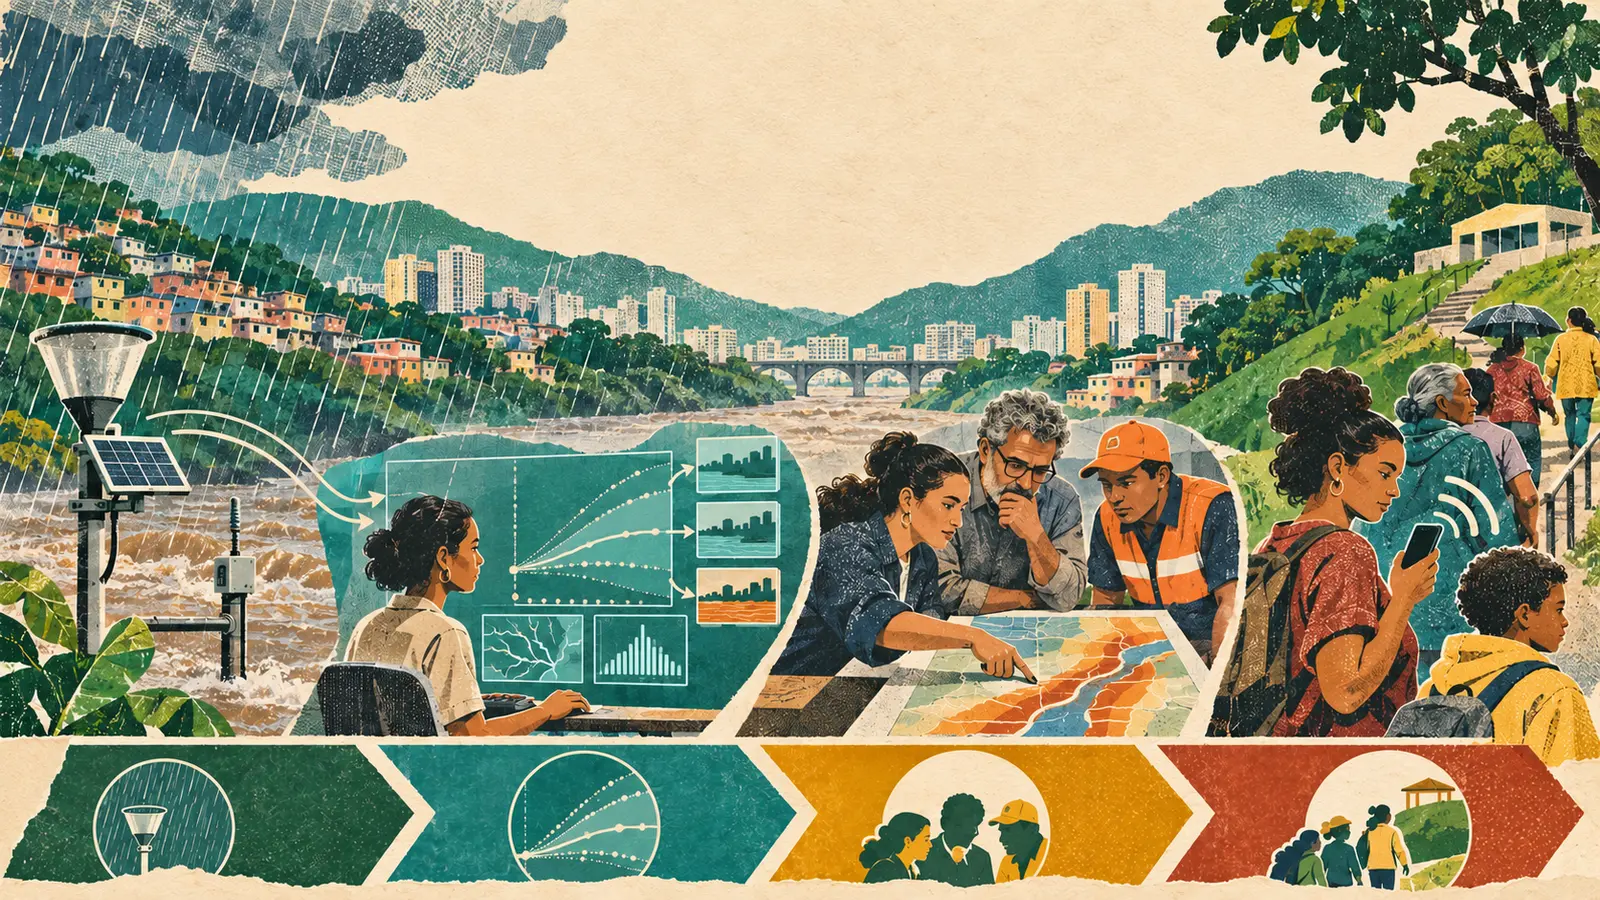
A flash flood does not care that your dashboard is impressive. It cares about gravity, rain, pavement, river channels and the people who may have only minutes to move. Brazil's Centro Nacional de Monitoramento e Alertas de Desastres Naturais, known as Cemaden, has built a platform called FloodcastingXAI to give those minutes a head start. The Ministry of Science, Technology and Innovation described the system on November 6 as a way to estimate rapid rises in urban river levels one to four hours ahead. The platform combines readings from rain gauges and river-level sensors already used in monitoring networks. New measurements arrive every 10 minutes. Machine-learning models look for patterns in the rain and the water, then estimate how the river may behave over the next several hours. The XAI part stands for explainable artificial intelligence. Instead of producing only a forecast, the system can show technical users which inputs, such as rainfall intensity or current river conditions, most influenced the result. That is useful. A hydrologist deciding whether a forecast makes sense should be able to inspect more than a red light. Cemaden reports that operational tests showed an approximately 40 percent performance improvement for forecasts one to four hours ahead. That result deserves attention and a footnote the size of a sandbag. The public material does not define the exact performance metric, comparison baseline, number of events, locations, false alarms or missed floods. Forty percent better at a named metric is evidence. Forty percent better at weather is not a scientific sentence. The ministry is also explicit that the system does not replace the professionals who monitor conditions and issue warnings. It adds another source of evidence for people who must make fast decisions. That distinction points to the real story. Flood forecasting is not one model call. It is a handoff chain. A sensor must work. Its timestamp must be current. The model must run. A hydrologist must understand the result. Civil Defense must decide whether and how to warn. A message must travel through channels people can receive. Residents need a safe destination, accessible transport and enough trust to act. Every handoff can consume the precious lead time the model created. So the practical signal is not simply that Brazil has an AI that can see a flood coming. It is that Brazil has a tool that may create a one-to-four-hour decision window, and that window should be measured all the way to the person standing near the water. Keep the warning handoff visible. Record when the reading arrived, what the model predicted, how uncertain it was, who reviewed it, what threshold triggered action, when the public message left, which channels carried it, whether it arrived and what happened next. The forecast is the beginning of the receipt. Safety is the part at the end.
01
WHAT ACTUALLY CHANGED
FloodcastingXAI joins high-frequency monitoring with short-range forecasting. Cemaden says the platform receives public readings from rain gauges and river-level sensors every 10 minutes. The models use those observations to estimate rapid water-level rises over horizons from one to four hours. That matters because a flash flood develops faster than many ordinary river floods. In a paved urban basin, heavy rain can move into channels quickly, leaving residents and emergency teams little time to interpret what they are seeing. Forecasting shifts part of the work from describing the current river to estimating the next one.
The platform exposes factors that influenced a forecast. Explainability does not make a model correct. It can, however, help a trained reviewer ask better questions. Did an extreme rain reading dominate the result? Was the river already elevated? Did a sensor change abruptly? Does the forecast match the physical behavior of this basin? Those clues are especially valuable when a public warning could cause an evacuation, close a road or send emergency crews toward danger. The explanation belongs beside the prediction, not in a research appendix that operators cannot reach during the storm.
Cemaden reports an approximately 40 percent gain in operational forecast performance for one-to-four-hour horizons. The number comes from the agency that developed and operates the platform. The reviewed public pages do not specify the metric, baseline model, event count, geographic split, confidence interval, false-alarm rate or missed-event rate. Those details are necessary before comparing the result with another flood-warning system or turning it into a general claim. The honest version is narrower: the agency reports a substantial improvement in its operational tests, and the evidence needed to interpret that improvement should be published.
The system sits inside the broader iFAST project, a collaborative flood-alert effort hosted by Cemaden. Official project material says iFAST brings together researchers from Brazilian and international institutions and has public research funding. Cemaden says FloodcastingXAI has been in operation since 2025 and was built without an additional external procurement for the platform itself. That institutional setting matters. A warning tool needs long-term sensor maintenance, technical staff, local coordination and public-service continuity. A clever model with no operating home is only a weather-themed demo.
02
WHY THIS MATTERS
For residents in flood-prone neighborhoods, lead time is only useful if it becomes action time. A warning delivered four hours early could help a family move medicine, documents and children. A warning delivered through an app they do not use may as well have been delivered to the moon. Sirens, mobile alerts, radio, television, community leaders, schools, health services and door-to-door support all reach different people. Measure the last mile. Did the message arrive in language people understood? Could a blind or Deaf resident use it? Was transport available for older adults and people with disabilities? Was the proposed shelter open, reachable and safe?
For hydrologists, explainability can turn a model from a mysterious score into one inspectable instrument among several. The reviewer still needs rainfall radar, sensor health, basin history, upstream conditions, weather forecasts and local reports. A model explanation may reveal why a prediction changed, but it does not certify that the cause is physically sensible. Human review is not ceremonial approval. It is the place where the model meets the river.
For Civil Defense, every alert balances two kinds of error. A missed event can cost lives. Too many false alarms can exhaust staff, disrupt communities and weaken trust. That does not mean an agency should avoid warning until certainty arrives. It means thresholds, uncertainty and consequences should be explicit. Publish how often the system warned, how often the event occurred, how much lead time remained at each handoff and what changed after an error. Trust grows from visible learning, not from pretending the weather always cooperates.
For other cities, the platform is a useful reminder that local hydrology matters. A model trained on one combination of basin shape, drainage, pavement, sensors and rainfall may not transfer cleanly to another. A city considering similar tools should validate them on its own storms and failure patterns. It should also budget for the unglamorous pieces: reliable gauges, communications, maintenance, staff coverage, evacuation routes and community drills.
For public AI, the project offers a better success test than model accuracy alone. Ask whether a warning reached more people sooner, whether evacuation support improved, whether dangerous roads closed in time and whether the system recovered after sensors or networks failed. If the model score rises while the alert stalls inside an agency, the river will not award partial credit.
03
WHERE IT COULD HELP
- Attach sensor freshness to every forecast. Show the last reading time, expected update interval, missing values, calibration status and whether the model is operating with degraded coverage.
- Publish the evaluation card behind the 40 percent figure. Name the metric, baseline, sites, storm periods, event definition, lead-time buckets, confidence intervals, false alarms and misses.
- Display forecast uncertainty and the influential inputs together. A reviewer should see the range of plausible water levels and which rain or river observations pushed the estimate.
- Predefine human review roles. Name who monitors the system, who can issue an alert, who can override it, who receives an escalation and what happens when the primary operator is unavailable.
- Track the lead-time budget. Record when sensors observed the change, when the forecast completed, when a person reviewed it, when Civil Defense decided, when each channel sent the message and when residents confirmed receipt.
- Use several warning channels. Combine sirens, cell broadcast or SMS, radio, television, local messaging networks, community organizations and accessible formats instead of betting safety on one app.
- Connect the warning to an action card. Include the affected area, expected timing, safe routes, closed routes, shelters, accessibility support, transport contacts and the next official update.
- Rehearse degraded modes. Test power loss, broken gauges, stale readings, disconnected networks, unavailable staff and contradictory forecasts. Operators need a documented fallback before the rain arrives.
- Run community drills and pay attention to who is missing. A technically perfect alert can still fail tenants without data plans, people working nights, informal settlements, tourists, children, older adults and residents who distrust official channels.
- Conduct an after-action review for forecasts, false alarms and misses. Preserve the evidence, explain what happened, correct thresholds or procedures and publish the improvement without exposing residents' private information.
KEEP A HAND ON THE WHEEL
The approximately 40 percent improvement is a government-reported operational result. The public source does not define the exact measurement, baseline, evaluation locations, sample size or uncertainty. Those omissions do not erase the result, but they limit what readers can infer from it. The reported forecast horizon runs from one to four hours. It should not be described as four hours of guaranteed warning for every storm or river. Actual lead time will depend on data quality, basin behavior, model confidence, operator review, alert thresholds and communications. Explainable AI can show which variables influenced a prediction. It cannot prove that the model learned the right physical relationship, that the sensors are correct or that the event will unfold inside the predicted range. Watch for independent hydrological evaluation, comparisons with established forecast methods and performance broken out by basin and storm type. Sensor networks are infrastructure. Gauges can fail, drift, lose power, disconnect or sit in places that do not represent the most vulnerable neighborhoods. Watch for maintenance records, coverage maps, degraded-mode indicators and procedures for contradictory readings. A forecast is not an alert, and an alert is not an evacuation. Civil Defense needs authority, staffing, channels, transport, shelters and local trust. Watch for measured end-to-end lead time, receipt rates, accessible communications, drill results and evidence that support reached people with the least room to improvise. Climate and urban development can change the patterns a model learned. New pavement, blocked drainage, river works, hillside loss and more intense rain may move the system outside its training experience. Watch for drift monitoring, scheduled retraining, version control and a clear process for retiring a model that no longer helps. Finally, keep misses and false alarms visible. A public-warning system will never be perfect. The responsible question is whether the agency learns quickly, explains corrections and improves the whole chain instead of polishing only the forecast score.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 7, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US