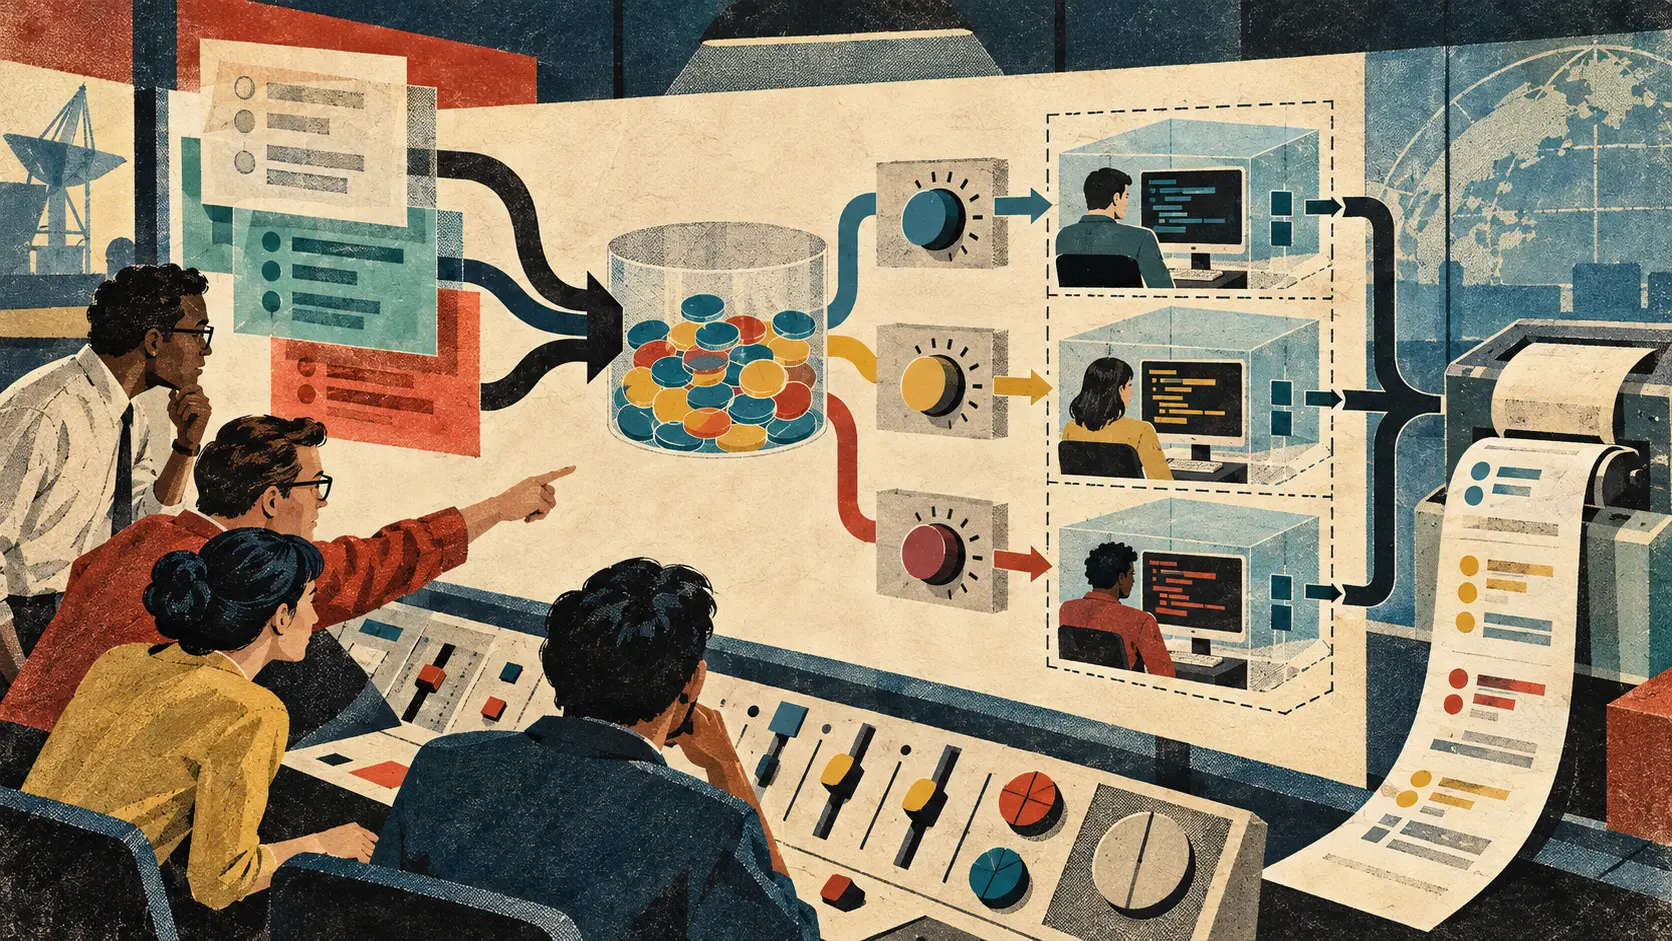
THE SIGNAL IN ONE SENTENCE
A policy file is a promise about what should happen. A session trace is evidence about what did happen. The awkward space between those two things is where expensive surprises breed. Anthropic released Claude Code 2.1.316 on October 31. The official release notes add several controls that can change how a coding-agent session spends money, selects effort, chooses models and passes through a managed gateway. One addition is a pooled group budget in the Claude apps gateway. Anthropic describes it as one monthly budget shared by a group's members, on top of each member's own limit. An administrator sets it with the pooled_budget field in the spend-limits admin API. Another addition is CLAUDE_CODE_SUBAGENT_EFFORT. It sets the effort level used by subagents when nothing else names one, instead of inheriting the parent session's effort. The release also adds a layered policy mode to the Claude apps gateway. In that mode, every policy matching a developer applies, with each policy merged over the ones listed below it. The previous first-match mental model is no longer enough for an administrator who turns this mode on. For organizations routing Claude Code through Amazon Bedrock, the gateway can now add guardrail input tagging. Anthropic says the option wraps prompts in the tags expected by Bedrock's prompt-attack filter, and one setting can include the system prompt. These are not one feature. They live at different layers. The pooled budget, layered policy mode and Bedrock tagging are gateway controls. The subagent effort default is a Claude Code environment setting. A team running Claude Code without that gateway does not automatically gain the gateway controls just because the version number matches. That boundary matters. A developer can truthfully say, "We are on 2.1.316," while the shared budget is absent, the gateway is bypassed, a different policy matched or the subagent effort came from another source. Version numbers tell you which controls may exist. They do not tell you which controls governed a particular run. The practical answer is a policy receipt. Create one at session start, update it when the effective configuration changes and close it when the session ends. Store it beside the session trace, not in a separate administrator's notebook that nobody can join back to the work. The receipt should begin with identity. Record the Claude Code version, session identifier, user or service identity, group memberships used for policy matching, project, repository, working directory, start time, end time and execution environment. Use stable internal identifiers where possible. A person's display name can change. A group label can be renamed. The receipt should preserve both the readable label and the identifier that the gateway actually evaluated. Next, record the route. Did the request go directly to Anthropic, through the Claude apps gateway, through Amazon Bedrock or through another supported provider? Save the gateway version, upstream name and region. If failover is possible, record the upstream that handled each request, not only the one preferred when the session started. Do not store secrets in the receipt. Record secret references, key fingerprints or vault object versions instead of raw API keys, tokens and credentials. An audit record that becomes a credential spill has taken the scenic route to failure. Then preserve the policy inputs. Anthropic's current settings documentation says Claude Code can read user, shared-project, project-local and managed settings. It also says managed settings can arrive through server-managed delivery, device policy, a system file or an embedding host. For every source that participated, record its type, location or management channel, version, retrieval time and content hash. If a policy is fetched remotely, record whether its signature or verification passed. The 2.1.316 release notes say server-managed settings for Team and Enterprise logins now apply without an approval prompt, while a stored copy that does not verify is refused. That is a useful safety behavior. It is also a reason to log the verification result. A receipt should distinguish: The administrator intended policy. The policy delivered to the machine. The policy Claude Code accepted. The effective settings applied to the session. Those can be four different things. Now capture the merge. For ordinary Claude Code settings, record the source that won for each consequential key. Anthropic's settings documentation explains that settings can come from multiple scopes and that managed settings override lower scopes for the keys they control. It also warns that lists and permission rules can combine differently from simple scalar values. For gateway layered policies, preserve the ordered list of every matching policy and the resolved result after each merge. Order is part of the evidence. If policy C overwrites a value from policy B, which overwrote policy A, saving only the final value makes the result hard to explain. Saving the ordered merge lets an administrator answer why the value exists and which edit would change it. The receipt does not need to duplicate every harmless appearance preference. Prioritize settings that affect cost, capability, data exposure, tool use, model selection, approvals, network access and retention. Budget comes next. Record whether a pooled group budget was configured, which group pool matched, the pool's billing period, starting available amount and the member's separate limit. Then record the amount charged during the session and the balance observed when it closed. If the gateway exposes only a later consolidated balance, say so. Do not manufacture penny-level precision from a dashboard snapshot. Also record the behavior at exhaustion. Did the request fail immediately? Was the person still allowed to use an individual limit? Did an administrator grant an exception? Did the session switch to another provider or model? A budget is not a security boundary. It is a spending control. Once exhausted, poorly designed fallback can quietly turn it into a routing suggestion. Effort deserves its own section. Record the parent session's effort, the CLAUDE_CODE_SUBAGENT_EFFORT value if present, the model assigned to each subagent and the effort that each subagent actually used. The wording in the release notes is specific: the new variable is a default when nothing else names an effort level. It is not proof that every subagent must use that value. That means the receipt should save both default and resolved values. This is useful for debugging. Two runs can receive the same prompt and use the same model, yet spend different time or tokens because the subagents ran at different effort levels. Without the resolved setting, the difference can look like mysterious model drift. It is also useful for cost review. A low-effort parent session can still launch several subagents with a higher default. A high-effort parent session can delegate routine searches at a lower level. Both choices may be sensible. Neither should be invisible. Model policy is another consequential field. The 2.1.316 release includes a fix for gateway checks across every model named in a request. Anthropic says a request naming a model blocked by availableModels, deniedModels or models now receives a 400 response that identifies the relevant field. Record the allowed model set, denied model set, requested model, resolved model and any fallback. If a provider or region lacks the requested model and Claude Code moves to an older model in the same family, record the change. The release notes include a fix for that provider behavior too. The receipt should never imply that an alias such as Sonnet or Opus proves one immutable model snapshot. Save the resolved identifier the upstream reports. Tool policy and sandbox boundaries belong beside the model. Record the permission mode, allow, ask and deny rules, working directories, additional directories, network allowlist, MCP servers, hooks and any bypass capability available at session start. Then record every exception granted during the run, including the actor, reason, scope and expiry. Anthropic's release notes include fixes for restricted sessions reading outside working directories under some allow rules, PowerShell hooks not blocking in certain forms and a managed auto-mode allow list regaining built-in exceptions. Those fixes are a reminder that policy engines are software. They can have bugs. The policy receipt does not prove the sandbox enforced every rule perfectly. It proves which rules and version were supposed to enforce the boundary, which is the starting point for testing and incident review. For Bedrock guardrails, record the guardrail identifier, version, gateway upstream, input-tagging mode and whether the system prompt was included. Do not copy protected prompt contents into a broadly accessible receipt. Record hashes and trace references where the content is sensitive. If guardrail tracing is enabled, link the filter result without copying matched attack text into an analytics system that was never designed to hold it. Guardrails are filters, not magic absolution. Input tagging can help the filter see the intended boundaries. It does not prove that every prompt attack was detected, that a tool call was safe or that output handling was correct. Close the receipt with outcomes. Record session status, code changes, commands, tool calls, budget consumption, policy denials, approval events, errors, model changes, guardrail events and the final human review. Hash or sign the closed record. Link it to the commit, pull request, build, deployment or incident ticket produced by the session. That turns the receipt into a useful operational object. A security team can reconstruct whether an agent had permission to read the file involved in an incident. A finance team can explain why one group exhausted a shared pool and which sessions consumed it. A platform team can compare a failed run with a successful one and see that the subagent effort or upstream model changed. A regulated organization can show which managed policy version governed a code change. A release engineer can test a new gateway policy against historical receipts before turning it on for everyone. There are limits. Anthropic's release notes are publisher-reported. They describe behavior the company says it shipped, not an independent audit of every deployment. Several controls covered here belong to the Claude apps gateway, not every Claude Code installation. Organizations using third-party clouds, local policy files or custom gateways need to verify their own route. Policy merging must be tested with the organization's real groups and exceptions. Budget exhaustion must be tested before month-end. Guardrail tagging must be tested with the configured Bedrock guardrail. Upgrade and rollback behavior need rehearsal. A receipt can also become too large to use. Keep a compact resolved summary in the main record and link to detailed traces under appropriate access controls. Redact secrets and sensitive prompt content. Set retention by risk and legal need, not by the storage team's enthusiasm. Finally, test the receipt itself. Start a session with two matching gateway policies, a pooled budget, a subagent effort default, one denied model and one tool rule. Launch a subagent. Trigger an allowed action and a denied action. Approach the budget limit in a safe test account. Close the session. Then give the receipt to someone who did not configure the system. Can that person tell which policies matched, in what order, which values won, what each subagent used, what the gateway denied and how much of the pool remained? If not, the organization has settings. It does not yet have evidence.
01
WHAT ACTUALLY CHANGED
Anthropic released Claude Code 2.1.316 on October 31, 2026.
The Claude apps gateway can now apply one monthly pooled budget shared by a group on top of each member's own limit.
CLAUDE_CODE_SUBAGENT_EFFORT can set the default effort used by subagents when no other source names one.
Gateway administrators can enable layered policy mode so every matching developer policy applies in an ordered merge.
Bedrock upstreams in the gateway can add guardrail input tags, including an option that also tags the system prompt.
The release also fixes model-policy checks, restricted-session file access, hook blocking and managed auto-mode behavior.
02
WHY THIS MATTERS
A version number shows which controls may exist, not which settings actually governed a particular session.
Pooled budgets can change access and fallback behavior for an entire group, making per-session cost attribution important.
Subagent effort can change latency, cost and behavior even when the parent prompt and model appear unchanged.
Layered policies make merge order part of the evidence administrators need to explain an effective setting.
Gateway, provider, local settings and project policy operate at different layers and should not be collapsed into one vague claim of compliance.
Security and incident reviews need the resolved policy, model, tools and exceptions that applied when code was changed.
03
WHERE IT COULD HELP
- Generate a signed policy receipt at session start and close it with the final outcome, cost and review decision.
- Store the ordered list of matching gateway policies and the resolved value after each consequential merge.
- Record pooled-budget identity, billing period, starting balance, session consumption and exhaustion behavior.
- Capture parent and subagent model and effort defaults beside the values each agent actually used.
- Record model allow and deny lists, permission rules, sandbox boundaries, network access and every temporary exception.
- Link Bedrock guardrail configuration and filter traces without copying secrets or sensitive prompt contents into the receipt.
- Use historical receipts to test policy changes, reproduce incidents and compare apparently identical agent runs.
KEEP A HAND ON THE WHEEL
Watch for Anthropic documentation covering the pooled-budget admin API and gateway layered-policy merge details, clearer telemetry for resolved subagent effort, and administrator guidance for exporting effective policy state. Test group matching, merge order, model denial, budget exhaustion, upstream failover and rollback in the exact environment your team operates. A policy receipt records what the system reports; it does not replace independent tests of sandbox, permission or guardrail enforcement.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 1, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US