THE SIGNAL IN ONE SENTENCE
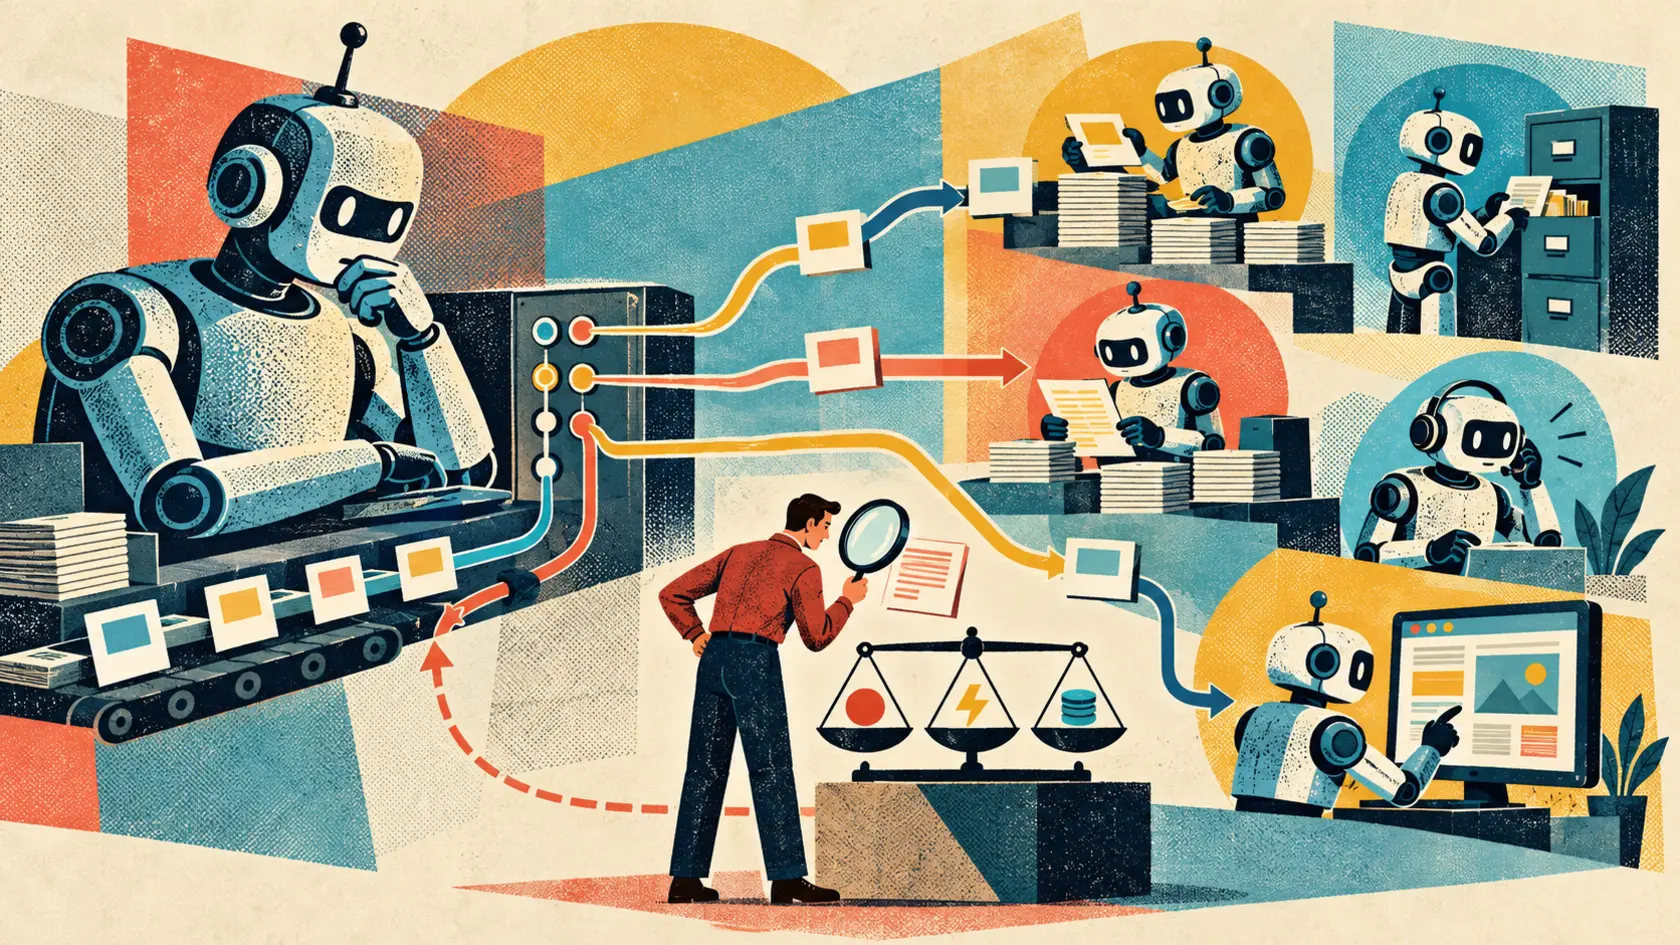
The most important model in an AI system may not be the one that gets the keynote slide. It may be the one that quietly performs ten thousand boring jobs before lunch. Anthropic released Claude Haiku 5.5 on October 7 as its cheapest, fastest and most capable small model so far. The company designed it for high-volume, cost-sensitive work: summaries, context compaction, database questions, classification, live support, browser use and tightly scoped subagent tasks. It is available through Anthropic and the major cloud platforms under the model identifier claude-haiku-5-5. The headline number is cost. Anthropic says Haiku 5.5 costs about 75 percent less to run on average than Haiku 4.5. For prompts up to 100,000 tokens, the listed API price is 10 cents per million input tokens and 50 cents per million output tokens. Above 100,000 tokens, those prices rise to 50 cents and $2.50. Cache reads and writes have the same fivefold step at that boundary. That pricing table is more interesting than a generic claim that AI got cheaper. It gives product teams a reason to split one large model job into a small system of specialized jobs. A stronger model can plan the work, decide what needs judgment and check the final result. A faster small model can extract fields, classify requests, summarize documents, compact context, run routine lookups or handle a well-defined tool call. If those tasks pass a quality gate, the small model can do them repeatedly without turning every workflow into an expensive encounter with the largest model available. This is the workhorse pattern. The analogy should not be stretched too far. A model is not a dependable employee simply because its token price is low. It can misunderstand an instruction, call the wrong tool, omit an exception, invent a field or turn a cheap attempt into three retries and a human cleanup job. A low unit price only becomes a low operating cost when the whole task succeeds. Anthropic's launch results make the opportunity look substantial. The company reports that Haiku 5.5 scored 72.4 percent on the offline subset of OSWorld 2.1, compared with 15.7 percent for Haiku 4.5. On Terminal-Bench 4.0, it reports 39.2 percent versus zero for Haiku 4.5. On its knowledge-work comparisons, Haiku 5.5 also moved much closer to larger models than its predecessor did. Those numbers are vendor-reported launch evidence. They are not a purchase order. The same page shows why. Sonnet 5.5 remains far ahead on the more complex Terminal-Bench task at 70.6 percent. Anthropic explicitly positions Haiku for narrower work such as summarization, compaction and subagents, not as a universal replacement for larger models. Its customer examples come from early testing by launch partners on their own selected workloads. They are useful clues, not guarantees for somebody else's documents, users or failure costs. The practical decision is therefore not Which model is best? It is Which model is good enough for this particular task, under this particular consequence? Start by cutting the workflow into units small enough to evaluate. Summarize a support transcript is a task. Handle customer support is a fog bank. Extract the invoice number, supplier, date, currency and total into a fixed schema is a task. Process accounts payable is several departments wearing one trench coat. Each unit needs a pass condition. For extraction, measure whether every required field is correct and whether the model marks missing information instead of guessing. For classification, report precision and recall by class, especially for the rare cases that trigger expensive or harmful actions. For summaries, test factual coverage, unsupported statements and whether a reviewer can trace every important claim to the source. For a tool-using subagent, verify the final state in the external system rather than counting a plausible sequence of clicks. Then calculate cost per accepted result. Token price belongs in that calculation, but it does not get to sit there alone. Include cache hits and misses, prompts crossing the 100,000-token boundary, tool charges, retries, failed runs, escalation to a stronger model, human review and the engineering time required to keep the workflow stable. A model that costs half as much per call but needs twice as many corrections has not discovered economics. It has discovered invoicing. Latency deserves the same treatment. Anthropic calls Haiku 5.5 its fastest model at the standard speeds used for each model, though its Opus models can run faster in a separate Fast Mode. Launch partner Asana reported more than a 30 percent reduction in task completion latency and as much as 2.5 times faster inference per agent turn in its evaluation. Box reported roughly half the latency of Haiku 4.5 on its tests. Measure that on the job users actually experience. Record time to first useful response, time to verified completion, median latency and the ugly tail. A support assistant that feels fast nine times and freezes on the tenth can still create a queue. An agent that responds quickly but waits on a database, browser or reviewer may not change total task time at all. Haiku 5.5 also brings adjustable effort to the Haiku class for the first time. That turns a model name into the beginning of a configuration, not the end of one. A higher effort setting may improve difficult cases while consuming more tokens or time. Teams should save the effort level beside the prompt, model snapshot, tools and evaluation result. Otherwise two reports about Haiku 5.5 may describe meaningfully different systems. Prompt length is another quiet fork in the road. Anthropic says roughly 90 percent of requests to the previous Haiku model used prompts at or below 100,000 tokens. That population supports the company's average savings estimate. A long-document product may sit in the other ten percent. If a workflow regularly crosses the price boundary, teams should test retrieval, chunking and compaction instead of assuming the launch average applies. They should also check whether shortening the prompt removes the very evidence needed to answer correctly. Prompt caching can help when stable instructions or documents repeat. It can also produce a beautiful spreadsheet based on an imaginary hit rate. Forecast with measured cache behavior from production traffic, including invalidation after document, policy or tool changes. A cache is an optimization, not a business model. The safest routing system uses three doors. Door one sends a bounded, low-consequence task to the small model. Door two escalates uncertain, unusual or high-stakes cases to a stronger model. Door three sends consequential decisions and unresolved disagreement to a person with the authority and evidence to judge them. The router needs tests of its own. If it cannot recognize hard cases, it will confidently direct them toward the cheapest lane. Build a gold set containing ordinary examples, rare exceptions, messy inputs, adversarial instructions, missing data and cases where the correct answer is to stop. Run the small and large models on the same hidden set. Compare accuracy, calibration, refusals, tool completion, cost and latency. Then test the rule that decides who gets which task. A cautious launch begins in shadow mode. Let Haiku make the decision while the existing system still controls the outcome. Compare the recommendation with the real result. Next, canary the route on a small share of low-risk traffic with automatic fallback. Expand only when quality, total cost and incident rates remain inside the agreed envelope. Keep the receipt. For every routed job, save the task type, model and effort setting, prompt or policy version, relevant input references, tool calls, validation result, fallback reason and final outcome. Do not log sensitive content merely because observability sounds responsible. Store the minimum evidence required, apply retention limits and keep access narrow. Safety documentation matters too, but it answers a different question from application quality. Anthropic says Haiku 5.5 improved across almost all of its alignment evaluations relative to Haiku 4.5 and showed less willingness to cooperate with misuse. Its cyber safeguards are more restrictive than Haiku 4.5's but less restrictive than those on some recent larger Claude models, permitting more defensive work while still blocking penetration testing and related techniques. The company says its biology safeguards match those used for Sonnet 5, Sonnet 5.5 and Opus 5. Those controls do not certify a financial summary, customer escalation, browser action or database answer. Misuse safeguards, factual reliability and workflow authorization are neighboring problems, not substitutes for one another. A model can decline a dangerous cyber request and still put the wrong total in a weekly report. For users, the immediate change may feel pleasantly unremarkable. A support reply arrives faster. A long conversation keeps more of its useful context. A product can afford to classify and summarize information that previously went untouched. The small model disappears into the machinery. That is precisely why teams need to measure it. Cheap models make it possible to add intelligence to far more steps. They also make it easy to multiply a small error across far more steps. The winning architecture will not route everything to Haiku, or everything to the largest model. It will know what is routine, what is uncertain, what is consequential and when the economics stop working. Small models are becoming the workhorses. Give them a harness, a scoreboard and a gate back to human judgment.
01
WHAT ACTUALLY CHANGED
Anthropic released Claude Haiku 5.5 on October 7 for high-volume, cost-sensitive tasks, including summarization, classification, compaction, database queries and subagent work
The company says Haiku 5.5 costs about 75 percent less to run on average than Haiku 4.5 and is its fastest model at each model's standard speed
Prompts up to 100,000 tokens are priced at 10 cents per million input tokens and 50 cents per million output tokens, with fivefold higher rates above that threshold
Haiku 5.5 is the first Haiku-class model with adjustable effort, allowing teams to trade cost and speed against intelligence
The model is available through Anthropic, Amazon Web Services, Google Cloud and Microsoft Azure as claude-haiku-5-5
Anthropic also cut Sonnet 5.5 cache-read pricing from 20 cents to 10 cents per million tokens and estimates that change lowers most agentic-work costs by about 20 percent
02
WHY THIS MATTERS
A capable low-cost model can make classification, extraction, compaction, search and routine tool use economical at volumes where a frontier model would be difficult to justify
Teams can separate planning and judgment from repetitive execution, using a larger model as coordinator and a smaller model for bounded subagent tasks
Token price can hide retries, tool failures, long-prompt rates, human review and escalation, so cost per accepted result is the useful production metric
Adjustable effort means the model name alone no longer identifies the system being evaluated or deployed
Routing creates its own safety problem because a weak router can send the hardest or highest-consequence cases toward the cheapest lane
03
WHERE IT COULD HELP
- Classify support, operations or document queues with per-class precision, recall and escalation thresholds
- Extract structured fields from invoices, forms and records while validating schemas and marking missing evidence
- Summarize and compact long agent histories with source traceability and tests for lost constraints
- Run narrowly defined research or coding subagents under a larger planning model
- Handle latency-sensitive chat, live support and browser tasks with outcome checks and automatic fallback
- Route requests by task type, consequence and measured uncertainty rather than sending every job to one model
- Compare cost per accepted task across prompt lengths, effort settings, cache behavior, retries and reviewer time
KEEP A HAND ON THE WHEEL
Watch for independent evaluations, stable model snapshots, benchmark methodology, task-level quality by effort setting, actual token use after the updated tokenizer, cache-hit assumptions, prompts crossing the 100,000-token price boundary, p50 and p95 latency, tool-call failures, retry rates, escalation accuracy, human review time, incident reporting and whether low prices encourage teams to automate tasks before defining a reliable pass condition. Anthropic and its launch partners report the current benchmark, latency and customer results, so production decisions still need local hidden tests and outcome verification.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Model routing
The service decision that maps an API request or product name to the specific model that will handle it.
OPEN GLOSSARY CARD
Prompt cache
A saved reusable part of a prompt that can reduce repeated work, time, and cost.
OPEN GLOSSARY CARD
Benchmark
A fixed test used to compare how systems perform on the same tasks.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 8, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US