THE SIGNAL IN ONE SENTENCE
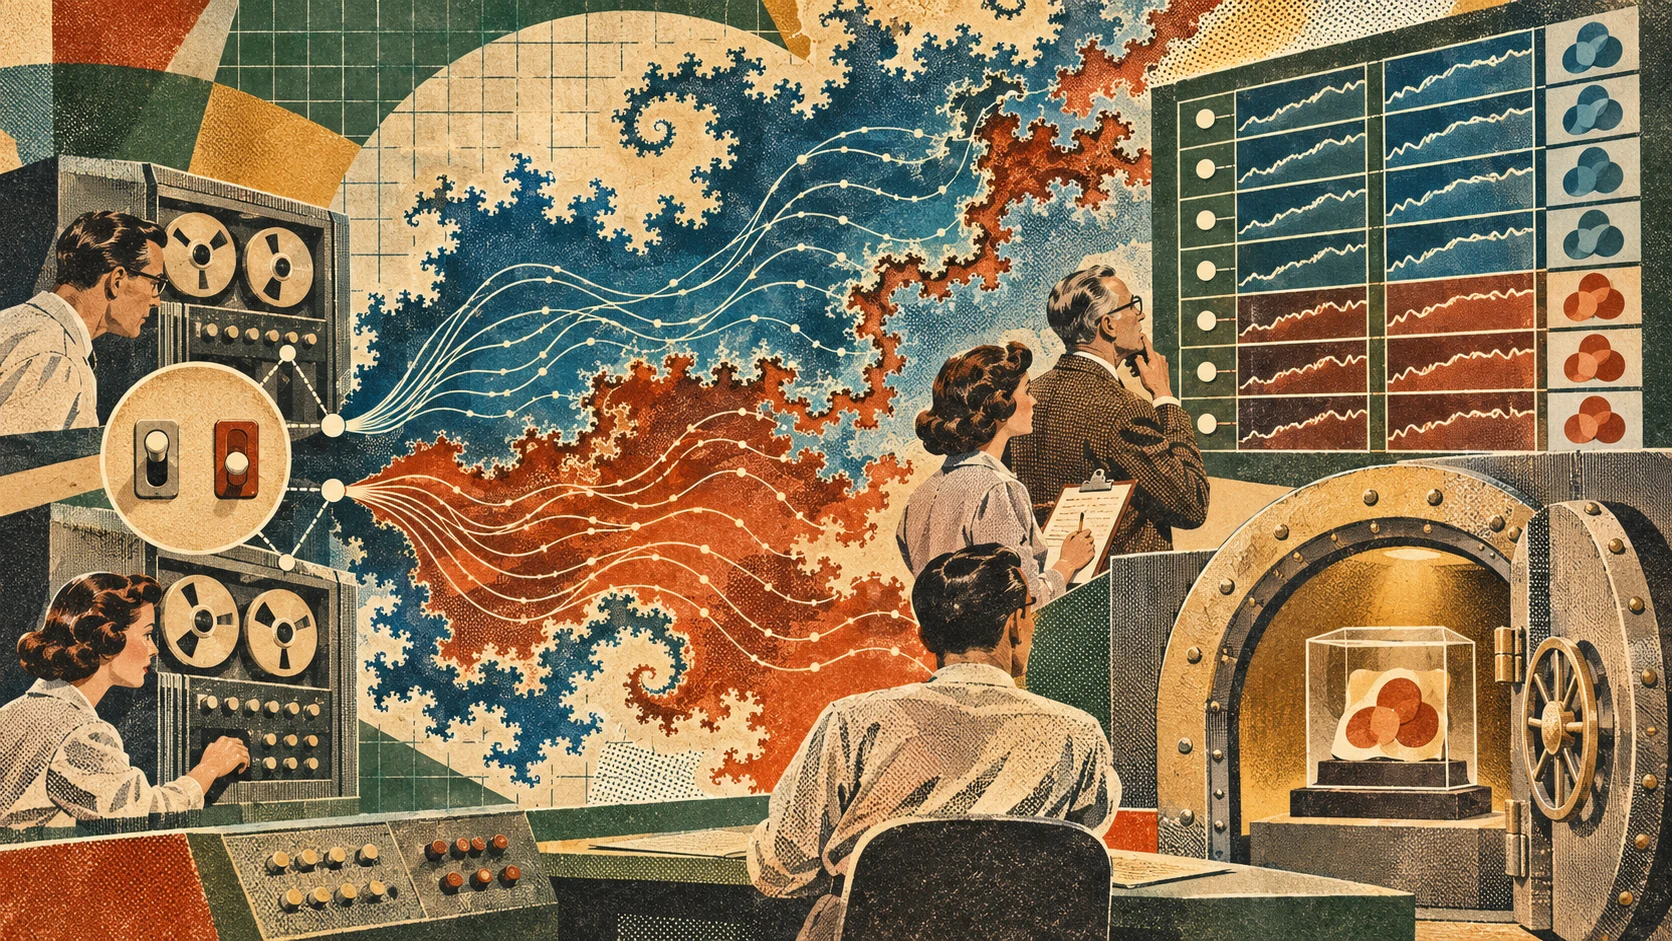
Two neural networks can start so close together that the difference lives in the least significant bit of one initial value, then finish as meaningfully different machines. That is the unnerving result behind new research from the University of Sydney, published in Nature Machine Intelligence on November 5 and summarized by the university on November 6. The team trained roughly 500,000 neural networks across image recognition and text tasks. It varied architectures, optimizers, initialization precision and training protocols. The researchers report evidence consistent with what mathematicians call riddled basins: regions in the space of possible starting points that are interwoven so finely that an arbitrarily nearby start can end in a different destination. If that sounds like a weather map designed by a mischievous lace maker, you have the right mental picture. Training a network means starting with a huge collection of values and repeatedly adjusting them to reduce error. We often imagine the training landscape as a set of broad valleys. Start near one valley and the run should roll toward roughly the same solution. The new paper argues that, in the systems it tested, the boundaries may be far stranger. Different destinations can be mixed through one another at extremely fine scales. In one larger image model, the researchers changed only the least significant bit of an initialization value. About 48 percent of paired runs finished with a different internal configuration. Increasing initialization precision by a factor of ten billion did not produce a measurable improvement in reproducibility for that experiment. That number needs careful handling. It does not mean that 48 percent of AI answers suddenly become wrong. It does not mean that half of all models are broken. It describes different internal configurations in one network and perturbation setting. Two internally different models can still score similarly on a broad benchmark, while disagreeing on particular examples or rare slices. The practical signal is simpler: a random seed is helpful, but it is not a complete reproducibility receipt. The exact code, data order, hardware, numerical libraries, compiler choices and model artifact still matter. So does the distribution across repeated training runs. If a team reports only the best model it happened to get, it may be publishing a lottery ticket with a benchmark attached. The sane response is not to abandon neural networks. It is to treat training as a population of outcomes and deployment as the choice of one exact, preserved artifact from that population.
01
WHAT ACTUALLY CHANGED
The Sydney team moved the reproducibility question from familiar engineering noise toward a geometric explanation. Machine-learning teams already know that changing a seed, device, library or data order can alter a result. The usual hope is that enough numerical precision and enough control will make nearby runs converge toward the same answer. The paper tests a tougher possibility: that the optimization landscape itself can contain destinations whose basins are interwoven at every examined scale. The researchers use an uncertainty exponent to characterize how often nearby starting points become uncertain as the perturbation shrinks. They report values near zero across the configurations they tested, which is consistent with riddled basin geometry. In plain language, making the initial difference smaller did not reliably make the destination more predictable.
The study also found a tradeoff rather than a magic reproducibility knob. Lower learning rates improved reproducibility in the experiments, but they also worsened training performance. That matters because teams often hear a result like this and immediately ask for a setting that makes the problem disappear. The paper's answer is less convenient. A setting can make runs more alike while also making the finished models less useful. This is not a reason to accept chaos with a shrug. It is a reason to measure both goals explicitly. Reproducibility is one quality. Performance, calibration, fairness, robustness and operating cost are others. A change that helps one can hurt another.
The unit of evidence should therefore expand. One training log proves that one run happened. A seed helps another team replay the intended setup. Neither tells you how sensitive the system is around that setup. An ensemble receipt records repeated builds from a declared initialization family, the distribution of their metrics, their disagreements on important slices, the selection rule and the exact artifact that entered production. It turns a surprising training outcome into something a reviewer can inspect rather than a campfire story about the seed that got away.
02
WHY THIS MATTERS
For researchers, the finding changes what a reproducibility claim should contain. Re-running the same code once and landing near the same headline accuracy is useful, but it can hide functional disagreement. Two models can earn nearly identical averages and still behave differently on low-frequency classes, unusual phrasing, minority accents, edge lighting or adversarial inputs. Report the distribution across runs. Show the median and spread, not only the champion. Publish slice-level disagreement where the application makes that consequential. If only one model can be released, explain how it was selected and preserve its checksum.
For product teams, the deployed model is now clearly part of the release evidence. You cannot assume that retraining from the same recipe will recreate the exact behavior you shipped. Preserve the model weights, tokenizer, preprocessing code, dependency lockfile, compiler and runtime details, evaluation set version and safety configuration. If a supplier will not let you retain the artifact, obtain an immutable model version and a change-notification commitment. This sounds fussy until a customer asks why yesterday's model approved a document and today's rebuild rejected it. Then the checksum starts looking less like bureaucracy and more like a seat belt.
For regulators, auditors and buyers, the study is a warning against recipe-only assurance. A model card that describes architecture and training data is not the same as evidence for the instance serving decisions. Ask whether the evaluated artifact is the deployed artifact. Ask how many training runs were examined, how much they disagreed, which selection rule was used and whether a rebuild triggers a full evaluation. The goal is not to demand impossible bit-for-bit sameness from every system. The goal is to know which differences matter, which have been measured and which exact machine is making the decision today.
For everybody using AI, this is another reason to distrust one immaculate leaderboard number. The number may be accurate for the chosen artifact. It may still say little about nearby training outcomes or the cases hidden inside the average. Good teams will show the spread. Very good teams will show where the models disagree and what they did about it.
03
WHERE IT COULD HELP
- Train at least several independent builds for a consequential model, even when compute makes a massive sweep impractical. Define the number before looking at the results. A tiny ensemble is still more honest than a single run selected after the fact.
- Record the full environment for every run: source commit, data snapshot and order, initialization seed, hardware, precision mode, compiler, drivers, numerical libraries, optimizer, scheduler, hyperparameters and evaluation code. A seed without the stack is a forwarding address without a street.
- Compare function, not only weights. Measure agreement on ordinary cases, rare slices, safety prompts, calibration buckets and known failure modes. Different weights are not automatically a problem, but different high-stakes behavior absolutely can be.
- Declare the model-selection rule before training. Median validation score, constrained safety threshold or a multi-objective score can all be defensible. Picking the nicest run after seeing every chart is not a selection rule. It is souvenir shopping.
- Seal the production artifact. Store its cryptographic hash, evaluation report, tokenizer, preprocessing pipeline, runtime configuration and approval record. Verify that hash at deployment and after infrastructure changes.
- Treat retraining as a new release. Re-run the ensemble checks, compare against the previous deployed artifact and investigate slice-level regressions. The same recipe can produce a different meal, especially when the kitchen also changed its compiler.
- For hosted models, ask the provider for pinned versions, retirement notice, change logs and repeatable evaluation windows. When weights are unavailable, maintain a behavioral test suite and run it before accepting a new version.
KEEP A HAND ON THE WHEEL
The paper is strong evidence for a candidate mechanism across the systems the team tested. It is not a proof that every neural network has riddled basins or that useful reproducibility is impossible. The experiments cover selected architectures, datasets, optimizers and protocols. Larger foundation-model training can add data parallelism, distributed communication, routing, post-training and serving effects that were not all represented here. Those extra systems may create more variation, damp some variation or simply move it elsewhere. Internal difference also needs to be separated from user-visible difference. Two runs can land in distinct parameter configurations and still perform similarly on many tasks. Conversely, two models with similar average accuracy can disagree on the one rare case a safety team actually cares about. The right test is tied to the application. Watch for independent replication, work on larger models and clearer methods for measuring functional diversity. Also watch for teams using this result as an excuse to stop documenting their stack. Riddled geometry does not make sloppy engineering innocent. It makes the receipt more important.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 7, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US