THE SIGNAL IN ONE SENTENCE
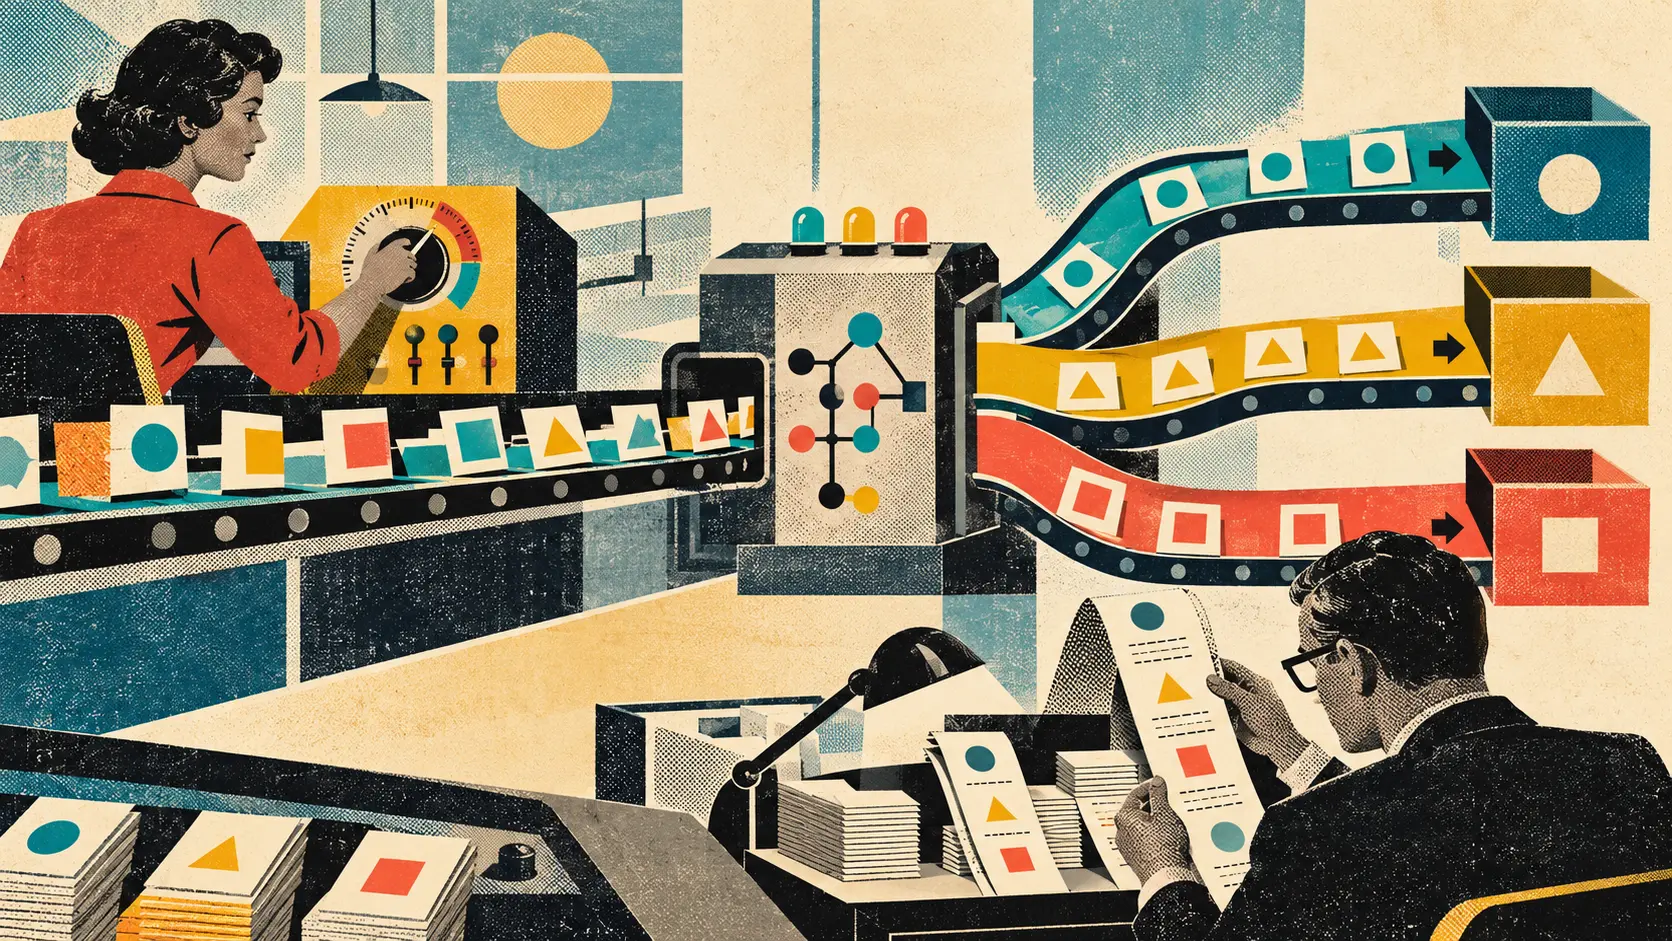
OpenAI has released an API for the small decisions hiding inside almost every application. Should this document go to claims or billing? Does this image show visible damage? Should an agent continue, retry or ask a person? How severe is this alert? These are not essay questions. They have bounded answers, and applications may need thousands of them before lunch. The Decisions API, generally available as of October 22, is built with GPT-6 Luna and accepts text, images and structured inputs. A developer defines the question and the allowed answer shape. The endpoint returns one of three things: a probability, a choice from a supplied list or a score against ordered levels. OpenAI says the dedicated endpoint can make these decisions up to ten times faster than GPT-6 Luna through the Responses API. It can handle as many as 400 questions in one request, supports prompt caching, integrates with GPT-Live, offers processing in the United States and European Union, and costs $0.10 per million input tokens. Cached input is listed at $0.01 per million tokens. There is no output-token charge. That price changes the shape of a product. A team no longer has to reserve an expensive frontier-model call for every little classification, routing or scoring step. A fast bounded model can sit between an input and an action: open a ticket, select a workflow, show a warning, send a case to review or let an agent proceed. That is useful. It is also where a probability becomes policy. A model may return 0.81. The consequential decision is not the number. It is the line someone drew at 0.80, the action attached to that line and the absence or presence of a safe route for the cases near it. The plain signal is simple: every production threshold needs a receipt. OpenAI presents early customer examples. Box says its evaluation on 30 certificate-of-insurance cases produced roughly five-times-faster routing with the same accuracy as the Responses API and sent lower-confidence cases to reviewers. Datadog says it uses Decisions to score the risk of agent-generated shell commands before autonomous remediation and observed forty-times-faster p95 latency than available frontier models with comparable accuracy. Ramp reports faster and cheaper cost attribution. Sierra reports sub-280-millisecond p95 routing in live customer conversations. Speak reports that a GPT-Live integration reduced its time to next action from 1.4 seconds to 0.13 seconds. Those examples are useful demonstrations. They are not a common independent benchmark. Each company selected its own task, data, comparison and outcome. The announcement does not provide the evaluation sets, subgroup results, calibration curves, false-positive costs or long-term production error rates. A claim of the same accuracy can be true while hiding a completely different error distribution. If a routing system is right 95 percent of the time, the missing question is what happened in the other 5 percent. Did a harmless command get blocked? Did a dangerous command pass? Did a damaged product get classified as clean? Did a customer with an unusual accent get sent down the wrong support path? Did a financial transaction receive the wrong category and quietly contaminate a report? Accuracy is an average. Operations live in the mistakes. Start the receipt with the decision itself. Record the question in plain language. Record every allowed answer. Record the input fields the model could see and the important fields it could not see. Record the model and endpoint version, prompt or rubric version, region, latency, probability distribution, selected answer and the threshold that converted that answer into an action. Then record the action. Did the application proceed automatically, ask for clarification, retry with more context, fall back to a deterministic rule or hand the case to a person? If a person overrode the result, what did they change? When the real-world outcome became known, was the original decision correct? That last field turns a log into an evaluation system. Without outcomes, a team can monitor speed, cost and model confidence forever while learning almost nothing about whether the routing helped. With outcomes, it can find where a threshold is too aggressive, where the model is poorly calibrated and where the input does not contain enough information for any system to decide responsibly. The probability deserves special care. A model score is not automatically a frequency guarantee. If cases assigned 0.8 confidence are correct only half the time, the number is not calibrated for that deployment. Calibration has to be tested on representative data from the actual task, not inherited from a product page or a demo. Split historical cases into development and holdout sets. Define the cost of false positives and false negatives before tuning the threshold. Plot outcomes by score band. Test important subgroups, languages, devices, document types and edge cases separately. Repeat the work after changing instructions, allowed answers, upstream extraction or model version. Do not optimize one threshold for every consequence. A playful avatar choosing between a wink and a smile can tolerate an occasional strange choice. A system deciding whether an agent may execute a shell command needs a much wider safety margin. A document router may automate familiar forms while sending damaged scans and unfamiliar templates to review. A support system may suggest a queue but should not quietly deny service based on a brittle score. Consequences set the review budget. Give the model a real way to abstain. A forced choice makes every uncertain case look like a decision. Add answers such as unknown, insufficient evidence or needs review. For probability and score outputs, create a gray zone around the operating threshold. Cases inside that band should collect more information or go to a person. The gray zone is not failure. It is the part of the system admitting that the input did not earn an automatic action. Teams should also test distribution shift. A routing rule may perform well on last quarter's clean English-language forms and wobble when a new supplier changes the template, a camera compresses the image, a product line launches or customers use a new phrase. Monitor input characteristics as well as output rates. A sudden jump in one category can signal a genuine change in the business, a broken upstream system or a model that found a shortcut. Run shadow mode before automation. Let the endpoint make decisions while the existing process continues. Compare results without changing customer, employee or system state. Review disagreements. Measure how often the proposed action would have helped, created extra work or caused harm. Only then allow the lowest-consequence, best-understood cases to proceed automatically. Expand by evidence, not enthusiasm. The very low listed price can tempt teams to put the endpoint everywhere because every individual call feels nearly free. The hidden costs arrive later: evaluation data, reviewer time, appeals, incident investigation, policy maintenance, version migration and the cleanup caused by wrong actions at scale. A cheap decision can produce an expensive consequence. For agent systems, keep the decision separate from execution. The model can recommend continue, retry, ask or stop. A policy layer should still decide which actions are permitted, which require approval and which are prohibited regardless of the score. The receipt should show both layers so an operator can tell whether the model chose badly or the policy mapped a reasonable score to a reckless action. For customer-facing decisions, add a correction path. Tell people when automation materially affected routing or access. Let them provide missing information. Escalate repeated disagreement. Track reversals and time to resolution. An appeal is not merely a kindness after a mistake. It is a sensor for cases the evaluation set failed to represent. OpenAI's launch makes bounded AI decisions fast enough and cheap enough to become ordinary infrastructure. That is the real change. The endpoint may disappear behind buttons, queues, alerts and agent actions, but its thresholds will still shape what people and systems experience. The mature implementation will not celebrate the number of decisions automated. It will show which decisions were eligible, what evidence supported them, where the system abstained, who reviewed the edge cases, how often people reversed the result and whether the eventual outcomes justified the threshold. Fast is a feature. Cheap is a feature. A receipt is how those features become accountable operations.
01
WHAT ACTUALLY CHANGED
OpenAI made the Decisions API generally available on October 22, 2026
The dedicated endpoint is built with GPT-6 Luna for bounded decision tasks
Inputs can include text, images and native structured data
Developers can request a probability, a choice from supplied options or a score
OpenAI says the endpoint can be up to ten times faster than GPT-6 Luna through the Responses API
A single request can contain as many as 400 questions
The API now integrates with GPT-Live and supports prompt caching
OpenAI lists processing residency in the United States and European Union
Listed pricing is $0.10 per million input tokens and $0.01 per million cached input tokens
The launch includes customer-reported speed, cost and workflow examples rather than one common benchmark
02
WHY THIS MATTERS
Low latency lets probabilistic model outputs sit directly in operational action paths
The threshold chosen by a product team can matter more than the raw probability
Average accuracy can hide costly false positives and false negatives
A bounded answer can still be wrong, poorly calibrated or based on insufficient evidence
Very low per-call prices can create large volumes of automated decisions before evaluation catches up
Different consequences require different thresholds, gray zones and review rules
Outcome logging is necessary to learn whether a decision actually helped
Appeals and overrides reveal cases that the original evaluation set missed
Agent recommendations should remain separate from the policy that permits execution
Distribution shift can quietly break a previously useful routing rule
03
WHERE IT COULD HELP
- Route documents to the correct workflow while sending unfamiliar formats to review
- Choose whether an agent should continue, retry, clarify or stop
- Score the risk of a proposed shell command before a separate policy layer decides execution
- Classify transaction descriptions for human-auditable financial workflows
- Prioritize support conversations without silently denying service
- Score visible product damage while preserving a review band for uncertain images
- Select low-consequence reactions in real-time voice and avatar experiences
- Run candidate decisions in shadow mode before allowing automatic state changes
- Compare confidence bands with eventual outcomes to test calibration
- Monitor subgroup errors, overrides, reversals and time to resolution
- Fall back to deterministic rules when a regulated policy already defines the answer
- Publish a decision receipt for every consequential automated route
KEEP A HAND ON THE WHEEL
OpenAI and named customers supplied the launch measurements. The announcement does not provide one independently reproduced benchmark, representative evaluation sets, calibration curves, subgroup error rates, fairness tests or long-term production outcomes. Treat the published speed, cost and accuracy examples as workload-specific reports. Before automatic action, test representative cases, define the cost of both error types, create an abstention band, separate model recommendation from execution policy and preserve a human correction path.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Distribution shift
A change in the people, data, devices or environment that makes production inputs differ from the conditions used to test a model.
OPEN GLOSSARY CARD
False positive
A result that incorrectly labels a negative case as positive, such as calling human writing AI-generated.
OPEN GLOSSARY CARD
Calibration
Measuring and adjusting a system so its controls and readouts match how the hardware actually behaves.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 23, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US