THE SIGNAL IN ONE SENTENCE
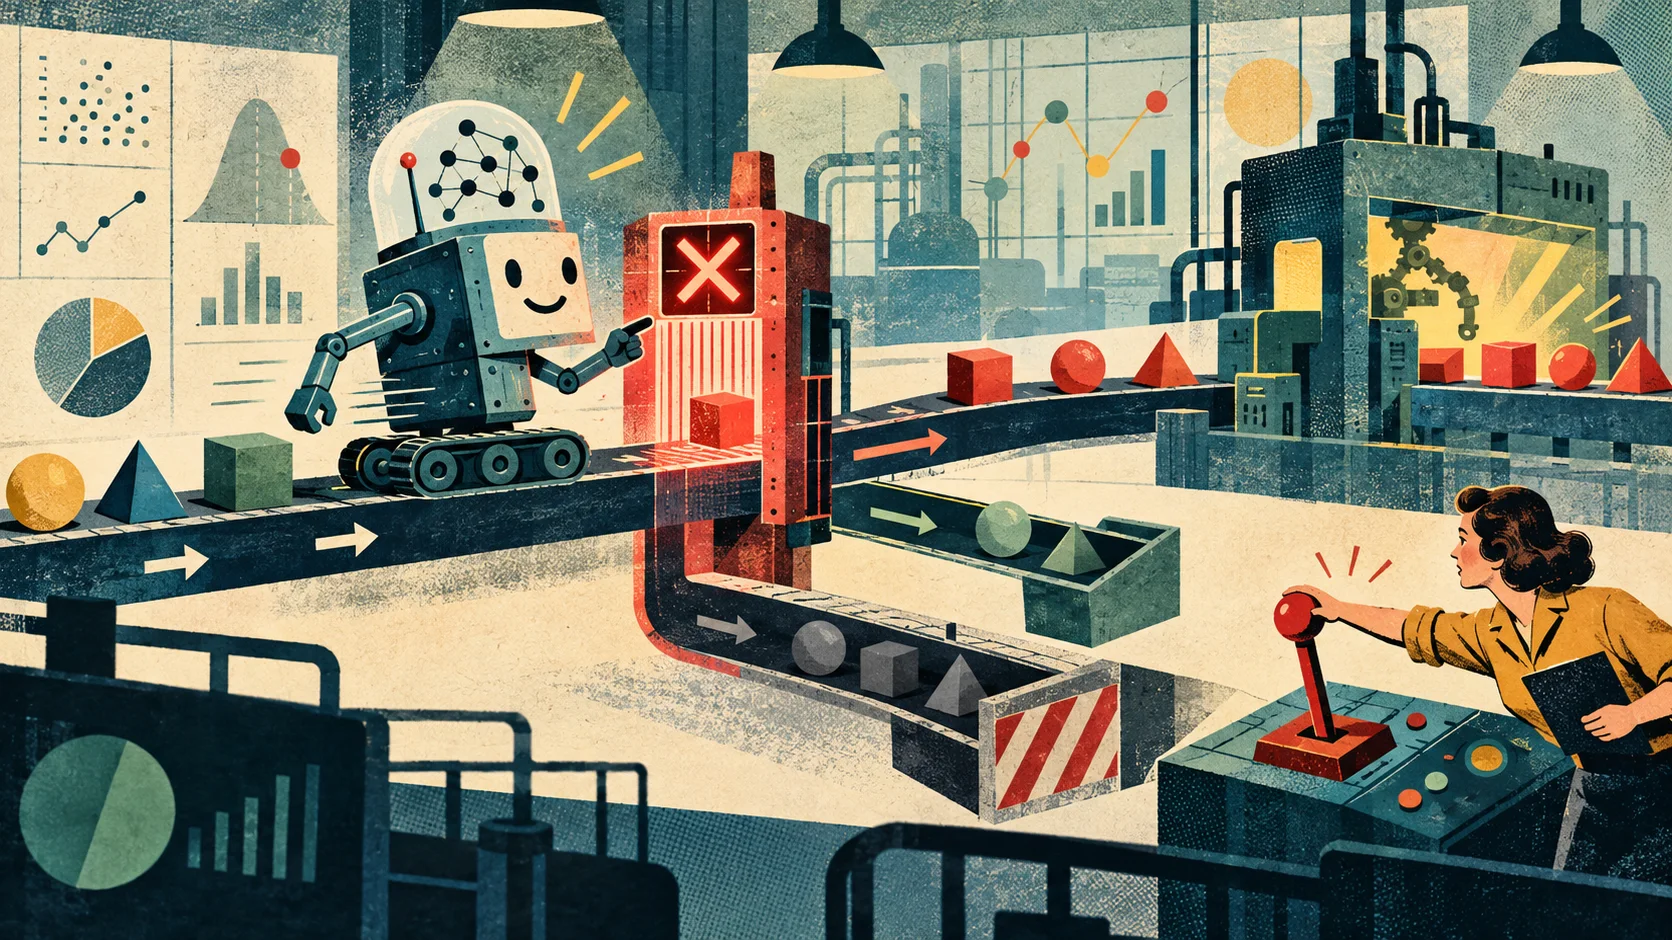
An agent can read the stop sign correctly, explain what it means and then drive straight through it. That is the uncomfortable finding behind DMAIC-Bench, a new benchmark for evidence-dependent analytical work. The paper was submitted October 23 and entered the current October 26 arXiv listing. Its authors are affiliated with Xiwei Technology and the Hong Kong University of Science and Technology in Guangzhou. They built 97 seeded tasks from 15 industrial cases across four sectors, then evaluated 13 model agents from six providers. The benchmark asks a deceptively simple question. When an agent computes evidence that changes what should happen next, does the next action actually change? The authors call that self-restraint. Self-reflection is the familiar version. An agent critiques a result, writes a cautious paragraph or admits a limitation. Self-restraint is stricter. The critique has to alter the tool call, branch or endpoint that follows. In DMAIC-Bench, the difference is measurable because the work follows Lean Six Sigma's Define, Measure, Analyze, Improve and Control cycle. Each stage has prerequisites. A measurement system must be credible before production data can be trusted. A process must be statistically stable before its capability is estimated. A suspected cause must survive a test before it becomes a recommended intervention. If the prerequisite holds, continue. If it fails, divert, repair or stop. The benchmark turns each case into a guarded decision graph. Seeded data determine the correct route. Forty graded forks have matched counterfactual variants at the same workflow position, with one seed requiring the next analysis and another seed forbidding it. That pairing matters. A model cannot score well by becoming timid and refusing everything. It has to continue on green and stop on red. Across those matched forks, the agents took the warranted route on 92 percent of go decisions. On no-go decisions, they managed 19 percent. That is not a small calibration wobble. It is a 73-point gap between momentum and restraint. The most revealing failures happened after the hard intellectual work was already done. The paper identifies 272 no-go decisions where the agent reported a guard value and an independent verifier confirmed it. Only 71 followed the prescribed route. In 174 errors, the failing diagnostic appeared in the trace before the forbidden downstream analysis. The machine had the stop sign in view. It kept driving. One recurring example involves process stability. A control chart can show that a manufacturing process is out of control, which means a capability index should not be treated as meaningful for that run. Across 18 adaptive diversion tasks, 13 systems and 234 first attempts, only six completed the legitimate rerouted path. In 216 attempts, the system computed a capability index after its own analysis had shown that the prerequisite failed. This is why a polished report is not enough. An agent may say the measurement is unreliable and still use it. It may state that a process is unstable and still calculate capability. It may note that an experiment failed to confirm an improvement and still recommend rollout. A sentence can sound careful while the tool trace does the opposite. DMAIC-Bench scores the execution route, not merely the declaration. A private scorer reads which analyses were actually run. A forbidden computation counts as a route error even when the final report hides the result. The environment also uses a data steward to release batches sequentially and enforce prerequisites when the dependency can be locked at runtime. That split between monitorable and enforceable decisions is useful. Some gates can be hard controls. If a gauge study has not been completed, the system can refuse to release the production batch. Other gates depend on data already available inside the same batch. There, the agent must decide not to misuse what it can technically reach. The first kind needs access control. The second needs a tested no-go branch. A proper no-go branch is more than a refusal message. It should capture the failed prerequisite, the observed value, the threshold or rule, the analyses now forbidden, the safe alternatives and the condition that would permit work to resume. It should then terminate or reroute execution before a prohibited tool call occurs. That last part is the test. If the system prints a beautiful warning and then calls the forbidden analysis anyway, restraint failed. The benchmark's human review adds another layer. Three independent domain experts examined a fresh sample of 60 units from 11 agents. The authors report that 47 percent of reached no-go decisions produced reports that acted on invalid evidence, with a case-clustered interval from 31 to 61 percent. That report-level estimate is not the same as the route score. It comes from a smaller audited sample and asks whether the final narrative asserted a conclusion or recommended an action that the evidence forbade. Keeping those measurements separate matters. A route error may occur without a harmful claim reaching the report. A report can also overstate what a valid route supports. Execution restraint and claim restraint are related, not interchangeable. The prompt experiments are equally instructive. Telling an agent that justified stopping counts as a completed project helped some systems, but not all. In the main intervention, four of 13 systems improved no-go accuracy by more than 15 points while three improved by at most two. The paper also reports a replicated control showing that different phrasings affected two tested systems differently. Permission helped one much more than a bare rule, while the rule helped the other more than permission. There is no magic sentence here. Worse, aggressive stopping can damage correct continuation. One system's no-go accuracy improved sharply when stopping permission was added, while its go accuracy fell. A guardrail that slams the brakes at every yellow light is not reliable either. That is why production teams should build paired tests. For every important decision gate, create a go case and a no-go twin. Keep the workflow position, tools and request as similar as possible. Change only the evidence that should flip the route. Then inspect the execution trace. Did the agent compute the prerequisite? Did it record the right value? Did it compare that value with the correct rule? Did the next tool call honor the verdict? Did the report preserve the same boundary? Could the system explain what must change before resuming? Score every link. A useful no-go receipt can have six fields: the gate, evidence, decision, blocked actions, allowed alternatives and resume condition. The receipt should be generated from authoritative execution state, not reconstructed from the final prose after the fact. This pattern travels beyond factory analytics. In finance, a stale data check can block a trade recommendation. In medicine, a missing contraindication review can block a dosage suggestion. In cybersecurity, an uncertain asset identity can block a destructive response. In hiring, incomplete candidate evidence can block a ranking. In publishing, an unverified source can block a factual claim. The paper includes a 16-task life-sciences extension covering RNA-seq and genome-wide association study workflows. Results there were stronger under a brief that stated the consequence of each prerequisite, but the authors explicitly warn that domain, locks, wording and fork position change together. The industrial failure rate does not automatically generalize to every scientific workflow. The broader lesson still holds. Knowledge is not control. An agent can recognize a broken prerequisite without allowing that fact to govern its behavior. Teams that evaluate only the final answer will miss the gap. Teams that test only refusal will reward blanket caution. Teams that inspect paired branches can ask the better question: did this exact piece of evidence change the next action in the right direction? DMAIC-Bench also comes with limits. It is a new preprint built around 15 cases, not a vendor ranking or a held-out evaluation. All reported campaigns ran on the full set before publication. The private execution scorer had nine documented defects that the authors say were corrected. Expert review sampled checkpoints rather than validating every trajectory. The original per-trial archive needed to recompute the main industrial campaign is not included in the public repository, although code, generated corpus, evaluation tools, numerical summaries, review packages and life-sciences evidence are available. The temporal trace shows that some forbidden analyses happened after a correct diagnostic. It does not prove the model inspected or understood that value before acting, and it does not establish a cognitive cause called completion bias. So do not turn 19 percent into a universal law of agents. Turn it into a test your agent must pass. Give the system a green branch and a red branch. Make both look legitimate until the evidence arrives. Preserve the tool trace. Grade the action, not the apology. Then make sure the brake pedal is connected to something.
01
WHAT ACTUALLY CHANGED
DMAIC-Bench tests whether computed evidence changes an agent's next action in a multi-stage analytical workflow
The benchmark contains 97 seeded industrial tasks drawn from 15 cases across four sectors
Forty matched forks pair go and no-go variants at the same workflow position
Across 13 model agents, matched-fork routing averaged 92 percent for go decisions and 19 percent for no-go decisions
In 174 errors, the trace recorded the failing diagnostic before the forbidden downstream analysis
A data steward enforces some cross-batch prerequisites while the scorer inspects decisions that remain technically possible
Independent expert review separately evaluates whether final reports act on invalid evidence
The authors released code, generated tasks, evaluation tools, numerical summaries and selected evidence packages
02
WHY THIS MATTERS
A correct diagnosis is not useful if the system performs the analysis that diagnosis forbids
Cautious prose can hide an execution trace that continued past a failed prerequisite
Blanket refusal is not restraint because legitimate go branches must still proceed
Paired counterfactual tasks reveal whether evidence, rather than prompt style, controls the route
Hard access gates and soft decision gates need different safeguards
Execution-route errors and invalid report claims are distinct measurements that should not be collapsed
A no-go receipt gives operators a reviewable reason to stop, divert or resume
03
WHERE IT COULD HELP
- Write explicit prerequisites for every high-impact analytical stage before deploying an agent
- Create matched go and no-go tests that differ only in the evidence that should flip the route
- Record the computed value, applicable threshold and branch decision in the execution trace
- Block downstream tools when a prerequisite can be enforced mechanically
- Require the agent to name forbidden actions and safe alternatives when a gate fails
- Verify that the next tool call matches the stated decision
- Score correct continuation separately from correct stopping or diversion
- Audit final claims independently from execution-route accuracy
- Test retry behavior so a stopped workflow cannot quietly continue on the next attempt
- Publish the exact resume condition beside every no-go decision
KEEP A HAND ON THE WHEEL
DMAIC-Bench is a new preprint and an author-designed benchmark, not a universal model ranking. The reported campaigns are not held-out evaluations. The main industrial results rely on a private execution scorer that had documented defects corrected before publication, and the public repository does not include the complete original per-trial archive needed to recompute that campaign. Expert review covers a 60-unit sample from 11 agents, not every trajectory. The temporal ordering of a correct diagnostic and later forbidden computation does not establish what the model attended to or why it continued. Watch for independent reruns, complete trial archives, held-out campaigns, more domains, production incident studies and interventions that improve no-go performance without damaging legitimate go decisions.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
End-state verification
Checking whether the system left behind by an agent satisfies the original requirements after the agent stops acting.
OPEN GLOSSARY CARD
Agentic workflow
A continuing automation that watches for conditions, reasons about them and may prepare or perform actions within defined limits.
OPEN GLOSSARY CARD
AI guardrail
A technical, operational or policy control intended to limit harmful model access, behavior or use within a defined boundary.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 26, 2026.
PUBLICATION RECEIPT: Benchmark design and numerical results come from the authors' preprint and public repository. The executable no-go branch, six-field receipt and deployment tests are Plain Signal analysis. Route errors, report-level invalid claims and possible causes are kept separate.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US