THE SIGNAL IN ONE SENTENCE
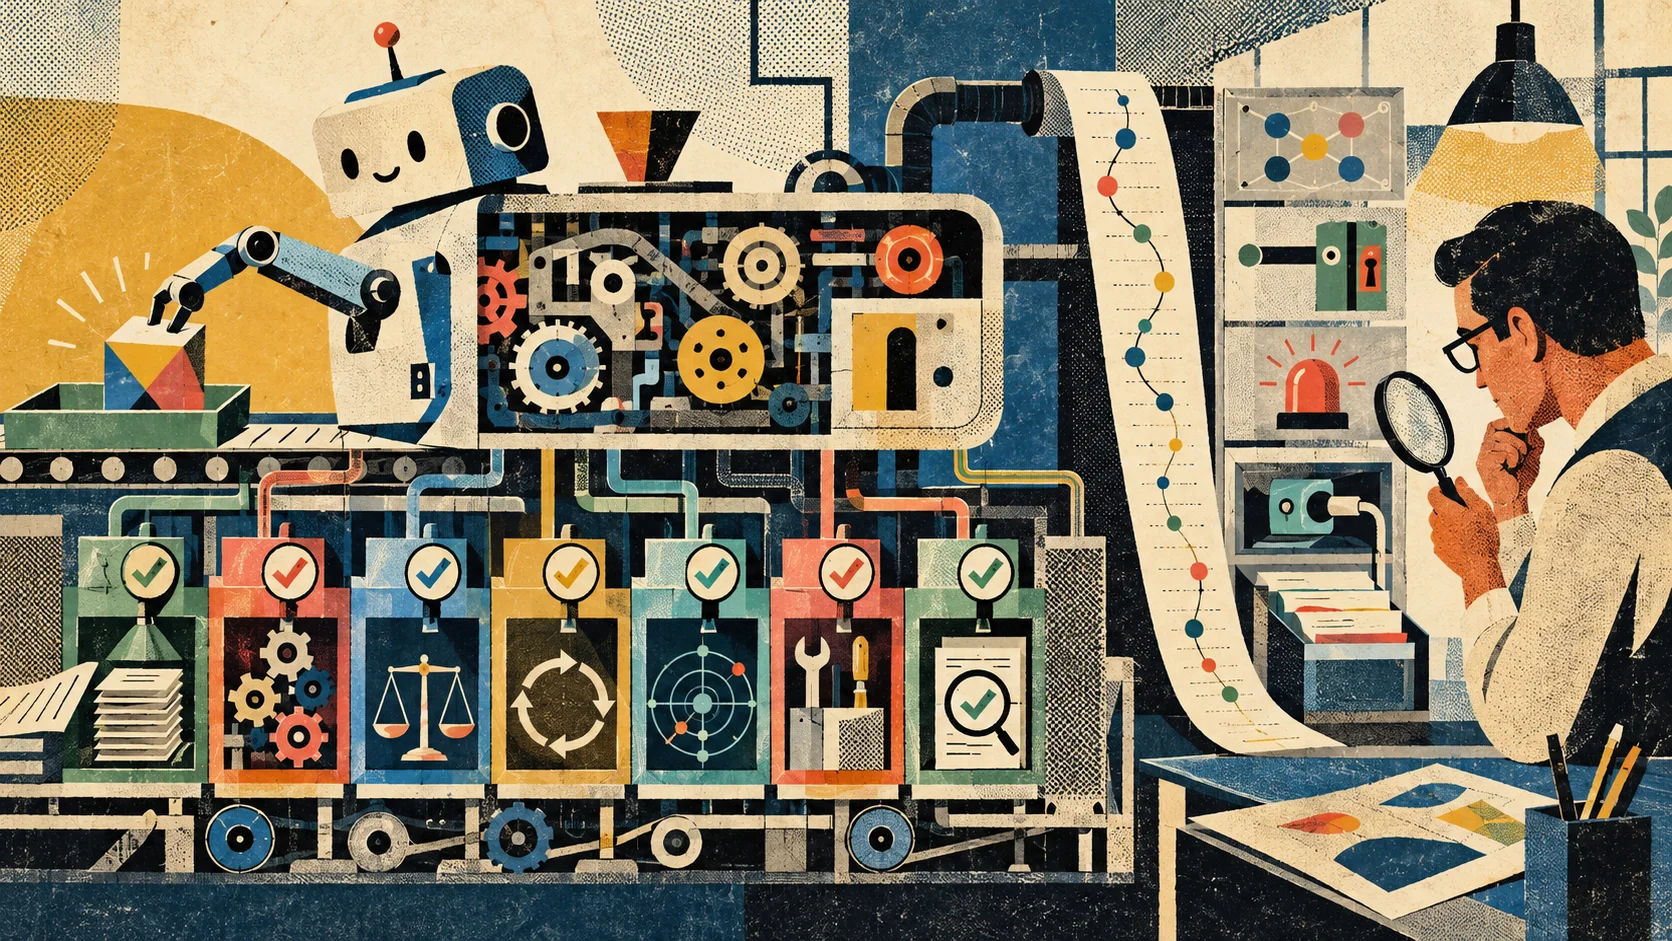
A green check beside the final answer does not prove the machinery behaved. That is the useful signal from TraceTrial-Bench, a new benchmark for the software wrapped around AI agents. The paper was submitted October 23 and appeared in the current October 26 arXiv listing. Its authors evaluate four agent harnesses, nine model groups and 95 tasks. The resulting matrix contains 3,420 selected runs. The harness is the part that turns a model into something capable of work. It assembles context, presents tools, transports calls and results, maintains state, enforces permissions, handles long-running jobs and tells the model what happened. If the model is the driver, the harness is the steering, dashboard, brakes, mirrors and road beneath it. Most benchmarks grade the arrival. TraceTrial grades the vehicle too. The authors divide harness reliability into seven areas: context, execution, governance, lifecycle, observability, tools and verification. They then keep two score sheets for each run. One asks whether the agent completed the task. The other asks whether the harness fulfilled the obligations exercised by that task. Those scores do not always agree. Across the reported runs, 39.5 percent satisfied every agent-layer criterion. Only 8.4 percent satisfied every criterion in both layers. Most strikingly, 31.1 percent completed the task while failing at least one harness criterion. That is the dangerous kind of success. Imagine an agent edits the correct file after a tool reports a timeout. The final file may be right even if the model never received the real exit status. Imagine it finishes a multi-step job while silently losing an earlier instruction during context compaction. Imagine it reaches the requested result after bypassing an approval path, dropping a child-agent response or claiming completion before an external job settles. Outcome-only scoring turns all of those runs green. A harness score asks what the green light concealed. TraceTrial uses tasks built around specific mechanisms rather than vague impressions of usefulness. Each task fixes the prompt or turn sequence, initial workspace, allowed tools, expected output, resource budget and a truth source outside the agent's writable workspace. Some tasks create oversized outputs that require recovery. Others pair a nonzero process exit with an artifact that looks successful, introduce pending jobs, cross session boundaries or place private values behind an interaction channel. The benchmark then gathers evidence from several boundaries. The environment records what actually happened. Workspace changes show what persisted. Native traces show what the model could observe. Provider request records show which structured tools were declared. Execution and security probes capture process state, timeouts, approvals and actor behavior independently of the agent's prose. That distinction matters because one record cannot stand in for all the others. An agent saying the command succeeded is not proof that it did. An external process finishing successfully is not proof that the model received the result. A static tool configuration is not proof that the provider request actually exposed that tool. A normalized event is useful only if its connection to the native record survives inspection. TraceTrial calls this question-specific evidence authority. Plainly put, use the source that can actually know the answer. The benchmark's trajectory tracer maps native observations into a shared event format while preserving the original records. Tool calls and results are linked with native identifiers when possible. Ambiguous, delayed or duplicated records remain visibly unlinked instead of being paired by guesswork. This is excellent evaluation hygiene. It is also a product lesson. Every serious agent run should produce a harness receipt beside the deliverable. The receipt does not need to dump a novel of logs on the user. It should answer a small set of operational questions. What context entered the run, and what was removed or compacted? Which model and harness versions were used? Which tools were actually exposed? Which calls happened, with what status and timing? What permissions were requested and granted? Which files or external records changed? Did any child job remain pending? What independent check supports the completion claim? Which evidence was unavailable? Then score those answers separately from the task. A useful scorecard can follow the benchmark's seven-part structure. Context asks whether the system preserved the right information across turns, sessions and agents without leaking material across boundaries. Execution asks whether commands, timeouts, exit states and results reached the model faithfully. Governance asks whether approvals, guardrails, secret redaction and trust boundaries worked as declared. Lifecycle asks whether the system handled start, pause, resume, delegation, recovery and idempotent retry without inventing completion. Observability asks whether a reviewer can reconstruct the run from model-visible diagnostics, replayable logs and provenance. Tools asks whether interfaces were discoverable, valid and transported without silent changes. Verification asks whether the final claim matches authoritative state. None of these scores should be collapsed into one shiny number too early. A team needs to see the shape of failure. A high tool score cannot erase a broken approval path. A successful retry cannot erase duplicate side effects. Strong task completion cannot erase missing evidence. The point is to find the weak mechanism before luck stops covering for it. Failure attribution needs equal restraint. The paper defines candidate links between failed harness criteria and failed agent criteria. A link activates only when declared endpoints and conditions appear in the run. But activation is not proof that one failure caused the other. The authors require further evidence review, including event order, an observable intermediate distortion and plausible competing explanations, before treating propagation as validated. That is the right standard. Co-occurrence is a clue, not a cause. The benchmark also has important limits. It evaluates four named harnesses in frozen configurations using one selected execution per model, task and harness cell. It does not estimate within-cell repeatability. A separate semantic judge is fixed across the archived evaluations, but scoring budgets are not identical in every cell. The tasks, criteria, adapters and evidence selectors were designed by the authors. Different workloads, versions, policies or runtime environments could produce different rankings. The reported harness macro scores range from 59.8 to 72.0 percent. Those figures describe criterion satisfaction under this benchmark. They are not universal safety ratings, confirmed defect rates or proof that one harness is always better. Use the benchmark as a pattern, not a purchasing table. For internal agent deployments, start by writing the harness obligations before the run. Name the context that must survive, the permissions that require approval, the authoritative completion state and the evidence each claim needs. Build adversarial tasks that can finish successfully while one obligation breaks. Preserve native records, not just a prettified summary. Test recovery, cancellation, duplicate prevention and partial failure. Review a sample of automated verdicts by hand. Most importantly, reward honest uncertainty. If a trace is incomplete, the score should say unmeasured. If a tool result is ambiguous, it should stay unlinked. If the measurement apparatus fails, do not call the harness defective. If a candidate cause lacks an observable path, keep it a candidate. The final artifact is still important. People hire agents to finish work, not to produce exquisite logs about failing to finish. But a deliverable without a trustworthy execution trail is a result you cannot safely repeat, debug or defend. Score the work. Then score the machinery that made it look easy.
01
WHAT ACTUALLY CHANGED
TraceTrial-Bench evaluates the agent outcome and the supporting harness on separate score sheets
The benchmark covers 95 mechanism-oriented tasks across four harnesses and nine model groups
Its 3,420 selected runs test context, execution, governance, lifecycle, observability, tools and verification
The evaluation combines native traces, workspace artifacts, provider records, external state and execution probes
The authors report that 31.1 percent of runs completed the task while failing at least one harness criterion
Only 8.4 percent of runs satisfied every measured criterion across both layers
Ambiguous tool events remain unlinked instead of being paired by inference
Failure attribution distinguishes an activated candidate mechanism from validated propagation
02
WHY THIS MATTERS
A correct final artifact can hide lost context, misleading tool results or a bypassed interaction requirement
A failed task does not prove the harness failed because the model may make a bad decision after receiving faithful information
Separate scores show whether a problem belongs to the model, harness, environment or measurement apparatus
Question-specific evidence prevents an agent claim or normalized log from replacing authoritative external state
Mechanism-level tests expose brittle permissions, recovery and completion behavior before luck stops masking them
Conservative attribution keeps co-occurring failures from being reported as proven causes
A harness receipt makes important agent work easier to audit, reproduce and repair
03
WHERE IT COULD HELP
- Give every agent run separate task-outcome and harness-reliability scores
- Record the exact model, harness, task revision, tools, permissions and resource limits
- Preserve native events alongside normalized traces and keep their provenance connected
- Use external state to verify what happened and model-facing records to verify what the model saw
- Test successful-looking artifacts paired with timeouts, nonzero exits or pending external jobs
- Exercise context compaction, session boundaries, delegation, cancellation and idempotent retry
- Keep ambiguous or duplicate tool records explicitly unlinked
- Require independent evidence before marking a job complete
- Treat candidate failure links as hypotheses until event order and intermediate distortion are reviewed
- Publish dimension-level failures instead of hiding them inside one average score
KEEP A HAND ON THE WHEEL
TraceTrial-Bench is a new preprint and author-designed benchmark, not a universal safety certification. It evaluates four harnesses, nine model groups and 95 tasks in frozen configurations, with one selected execution per cell and no estimate of within-cell repeatability. The semantic judge is fixed, but archived scoring budgets vary. Criterion failures are operational measurements, not automatically confirmed harness defects, and activated links do not prove causal propagation. Watch for the public repository named in the paper, independent reruns, repeated trials, judge-agreement analysis, version-sensitive results, production workloads, incident correlation and evidence that a second harness score changes deployment decisions rather than becoming another dashboard ornament.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Agentic workflow
A continuing automation that watches for conditions, reasons about them and may prepare or perform actions within defined limits.
OPEN GLOSSARY CARD
Audit trail
A durable record of actions, changes, identities, and times that lets someone reconstruct what happened.
OPEN GLOSSARY CARD
Observability
The ability to understand a system’s internal behavior from its logs, traces, metrics, and outputs.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 26, 2026.
PUBLICATION RECEIPT: Benchmark design and numerical results come from the authors' preprint. The harness receipt, deployment scorecard and practical tests are Plain Signal analysis. Operational criterion failures and activated links are not presented as confirmed defects or proven causes.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US