THE SIGNAL IN ONE SENTENCE
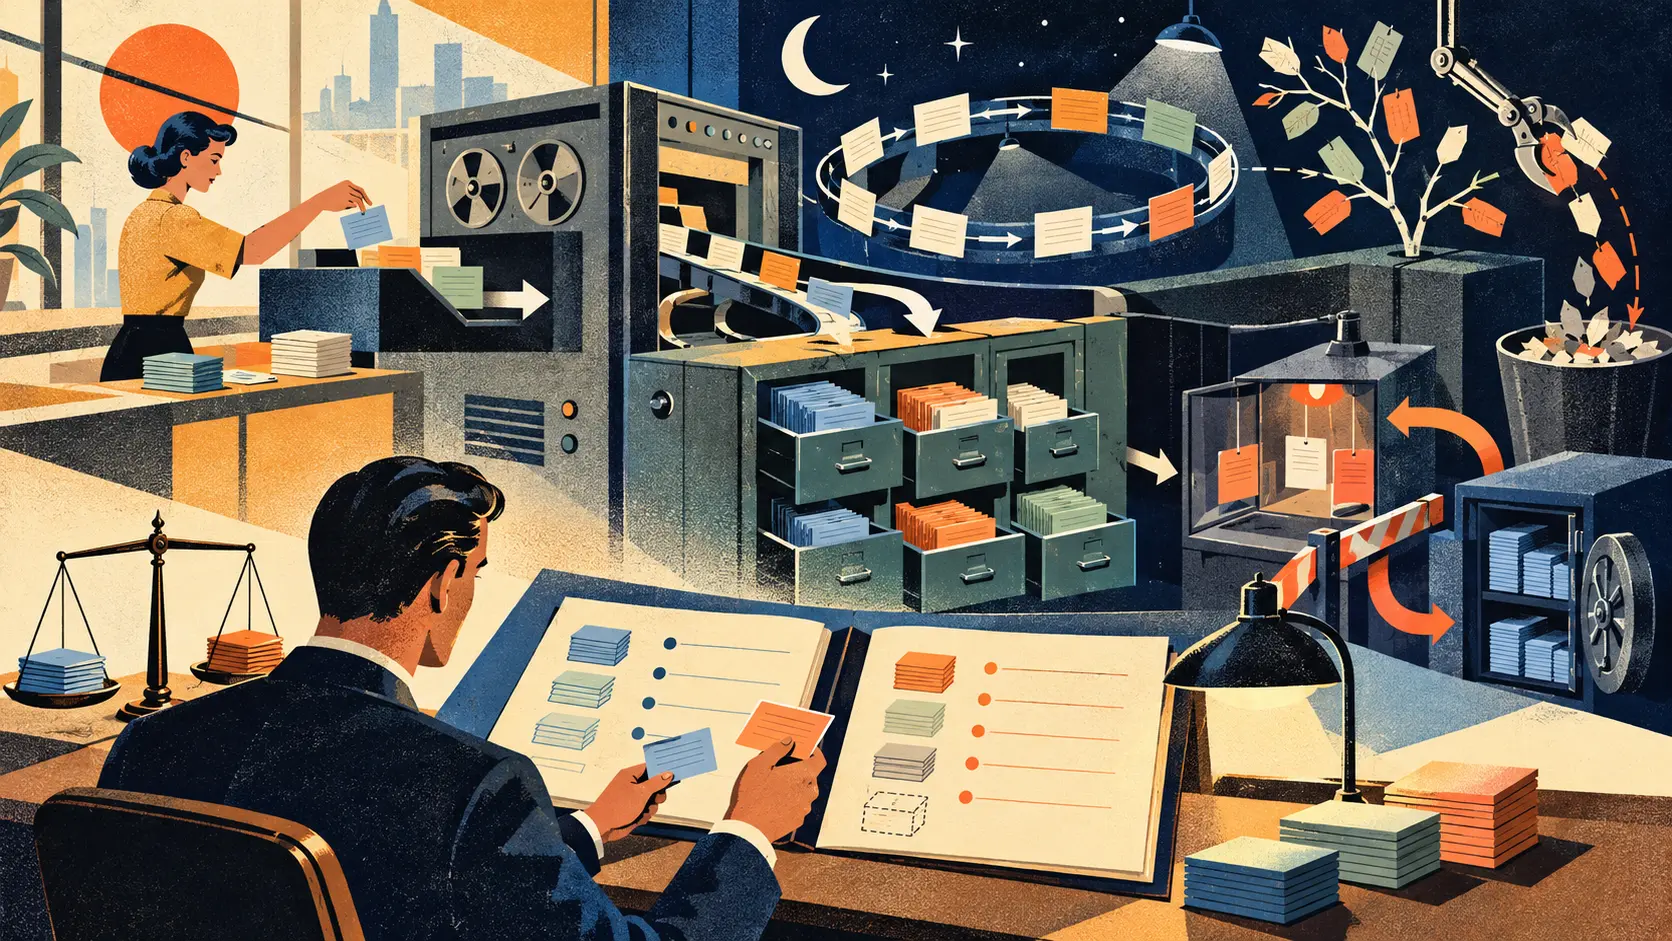
A language model does not go to bed. It does not dream about electric sheep, forget its alarm or wake up with a suspiciously confident idea for opening a food truck. Google Research has published a technical overview of a framework that borrows the language of sleep to describe something mechanical: a model works for a while, pauses, moves selected short-term information into longer-lived parameters and trains on synthetic practice before returning to work. The research paper first appeared as a preprint on June 2. Google's new October 27 overview gives the idea a clearer public explanation and reports results across continual translation, long-context understanding, factual knowledge incorporation and mathematics. The proposal addresses an awkward choice in today's models. Put fresh information in the prompt and the model can use it temporarily. When the context disappears, so does that temporary memory. Update the model's weights repeatedly and the new training can damage older capabilities, a problem called catastrophic forgetting. The sleep framework tries to create a periodic third path. During an active, or wake, phase, the model receives inputs and stores temporary information in fast-changing memory components. During an offline sleep phase, it stops accepting new inputs and performs two jobs the authors call consolidation and dreaming. Consolidation starts by opening pre-allocated low-rank experts inside a mixture-of-experts memory system. The model transfers selected behavior from faster, fragile memory into those more stable parameters through a process the paper calls knowledge seeding. The transfer combines on-policy distillation with reinforcement-learning-based imitation. A smaller current state acts as teacher. An expanded state acts as student. The student practices continuations and receives feedback based on semantic similarity and token-level distance. Once the transfer is complete, temporary high-frequency parameters can be reset to make room for another active period. Then comes dreaming. The model randomly activates unusual expert combinations, generates synthetic training examples and filters those examples using gradient-based selection. The most promising samples are used for supervised fine-tuning and reinforcement-learning refinement. That is the loop. Work. Pause. Expand. Distill. Rehearse. Test. Return. Google is explicit that the neuroscience terms are analogies. The method operates within a fixed model design and human-defined training rules. No model is literally sleeping, dreaming or choosing a new personality while the engineers make coffee. That distinction matters because the reported results are research results, not a product announcement. The authors report near-zero performance decline during sequential learning of unseen translation languages including Manchu and Kalamang. On BABILong, the method is reported to retain information across contexts up to 10 million tokens by consolidating it into parameters. For factual knowledge incorporation, Google reports 48.9 percent on a single-task SQuAD evaluation and 46.2 percent in a 200-passage continued-pretraining setting. On the mathematics evaluations cited in the overview, the sleep-enhanced models reached 79.2 percent on AIME 2024, 69.0 percent on AIME 2025 and 46.1 percent on HMMT 2025. Those numbers do not mean a deployed assistant can safely remember ten million tokens of ordinary human life. They are author-reported benchmark outcomes produced under specific experimental setups. They do not establish faithful retention of private conversations, contested facts, corrections, permissions or knowledge that expires. The paper calls this proof-of-concept work. There is no announced consumer feature, public API, production schedule or guarantee that the method scales cleanly to the largest deployed models. Still, the design raises a useful question for anyone building a system that changes after launch. What would you audit before accepting a new memory? Start with the candidate memory ledger. Every item proposed for consolidation should carry its source, timestamp, owner, consent status, sensitivity, confidence, expiration rule and the exact interaction that produced it. A sentence extracted from a user conversation is not just training text. It may be personal data, a joke, an unverified assumption or information supplied for one task only. Do not let the model decide that all repeated statements deserve permanence. Separate observations from conclusions. If a user says a shipment is late, that is an event report. If the model infers that the supplier is unreliable, that is a derived judgment. They require different evidence and different retention rules. Build a quarantine stage. Candidate memories should sit outside stable parameters until automated checks and human-defined policies decide whether they may be consolidated. High-risk categories such as health, identity, employment, finances, children and access credentials should default to rejection or require explicit authority. Deduplicate before training. The same claim repeated across a conversation can look more important than it is. A coordinated flood of identical false statements can look like strong evidence. Group claims by source and provenance so repetition does not quietly become truth. Check contradictions. Compare each proposed memory with current authoritative records and earlier retained knowledge. If two claims conflict, do not force the model to average them into a polished hallucination. Preserve the conflict, ask for a decision or keep retrieval as the source of truth. Then freeze a before-state. Record the model version, active experts, weights, prompts, safety policies, tokenizer, evaluation suite and the exact data entering the sleep cycle. A consolidation run is a model release, even if nobody changes the public product name. Give it a version number. Test new knowledge and old behavior together. A useful audit has at least four columns: what the model learned, what it retained, what it distorted and what it forgot. Improved answers about recent material do not cancel a regression in mathematics, refusal behavior, language quality or tool authorization. Use held-out questions for the new material. Use a stable regression suite for older capabilities. Add counterfactual questions that look similar but should not inherit the new memory. Measure provenance recall separately from answer recall. A model may reproduce a fact after consolidation and lose the ability to explain where it came from. That is especially dangerous when the source can change. Where auditability matters, keep the canonical record in an external store and require the answer to retrieve and cite it rather than relying only on parameters. Test correction and deletion. If the new fact is wrong, can the team remove it without damaging neighboring knowledge? If a person revokes consent, can their data be identified and unlearned? If the answer is no, the system should not promise durable personal memory. Keep a rollback image. The pre-sleep model and the consolidated candidate should run side by side until the new version passes. Rollback must restore weights, expert activation, safety configuration and external memory indexes together. Audit the dreams too. Synthetic rehearsal is not free evidence. A model can generate a plausible example from its own misconception, select it because it produces a useful gradient and then train itself to repeat the error more confidently. Store every synthetic sample that influences the update, the model state that produced it, its selection score and the downstream metric it changed. Run contamination checks against evaluation data and screen for unsafe or sensitive content. The reward deserves suspicion. If the dream filter optimizes a benchmark, the system may learn shortcuts that improve the score without improving the intended capability. Test alternative prompts, adversarial examples and independent evaluations that were not visible during selection. Expansion has a bill. Unlocking new experts gives the model room to store knowledge without overwriting old parameters. It can also increase storage, training, serving and maintenance complexity. Track parameter growth, consolidation compute, energy, inference latency and which experts activate for which users. Without a capacity budget and retirement policy, a memory hierarchy can become an attic with excellent branding. Finally, assign human authority. A model may propose a sleep cycle, candidate memory or synthetic curriculum. Named people should approve the data boundary, evaluation threshold, release and rollback. For high-impact systems, a failed retention or privacy test should stop the update automatically. This does not make continual learning a bad idea. Static models have real limits. Knowledge cutoffs age. Long prompts are expensive. Retrieval can fail. Repeated full retraining is slow and costly. A system that can consolidate useful experience without erasing old capability would be valuable. The sleep framework offers a structured research direction: protect old parameters, add controlled capacity, distill selected traces and rehearse before deployment. The phrase self-improvement makes the glamorous part sound automatic. The responsible part should be stubbornly manual. Before state. Candidate memories. Synthetic samples. Regression results. Privacy decisions. Cost. Approval. Rollback. If a model wakes up changed, the team should be able to explain exactly what it remembered and why they let it keep it.
01
WHAT ACTUALLY CHANGED
Google Research published a detailed October 27 overview of a continual-learning framework first released as a June 2 preprint
The framework alternates an active phase with an offline consolidation and synthetic-rehearsal phase
Low-rank mixture-of-experts capacity is unlocked to receive distilled knowledge from faster temporary memory
Temporary high-frequency parameters can be reset after selected information moves into more stable components
A dreaming stage generates synthetic examples, filters them by expected learning value and refines the model on selected samples
Google reports results across continual translation, long-context retention, factual incorporation and mathematical reasoning
02
WHY THIS MATTERS
Continual learning could reduce the gap between temporary context and expensive full retraining
Dedicated new capacity may protect older knowledge better than repeatedly updating the same parameters
A consolidation cycle is still a model change that can introduce regressions, privacy problems and false durable memories
Synthetic rehearsal can reinforce useful skills or amplify a model-generated misconception
Parametric memory is harder to inspect, correct and delete than an external record
Responsible deployment requires versioning, provenance, consent, regression testing and rollback
03
WHERE IT COULD HELP
- Attach source, consent, sensitivity, confidence and expiration metadata to every candidate memory
- Quarantine proposed memories before any parameter update
- Separate direct observations from model-inferred conclusions
- Detect duplication, coordinated repetition and contradictions before consolidation
- Freeze the full pre-update model and evaluation state
- Measure learned, retained, distorted and forgotten knowledge separately
- Keep authoritative changing facts in retrieval systems with visible provenance
- Test correction, deletion and rollback before accepting durable personal memory
- Preserve and review every synthetic rehearsal sample that influences the update
- Track parameter growth, consolidation compute, latency and named human approval
KEEP A HAND ON THE WHEEL
The Sleep results are author-reported research, not evidence of a deployed Google product or safe autonomous self-improvement. The neuroscience terminology is an analogy. The 10-million-token result is a benchmark claim about consolidation, not proof that a model faithfully remembers arbitrary conversations or can cite their provenance. The published work does not establish production cost, privacy compliance, reliable deletion, resistance to poisoned inputs or general performance at frontier-model scale. The preprint first appeared June 2, while Google published the current technical overview October 27. Watch for released code, independent reproduction, explicit forgetting metrics, capacity and energy costs, privacy evaluations, deletion tests, synthetic-data audits and a production rollback design.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 28, 2026.
PUBLICATION RECEIPT: The article labels the findings as author-reported research, discloses the June preprint date, treats sleep language as analogy and separates benchmark retention from safe product memory.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US