THE SIGNAL IN ONE SENTENCE
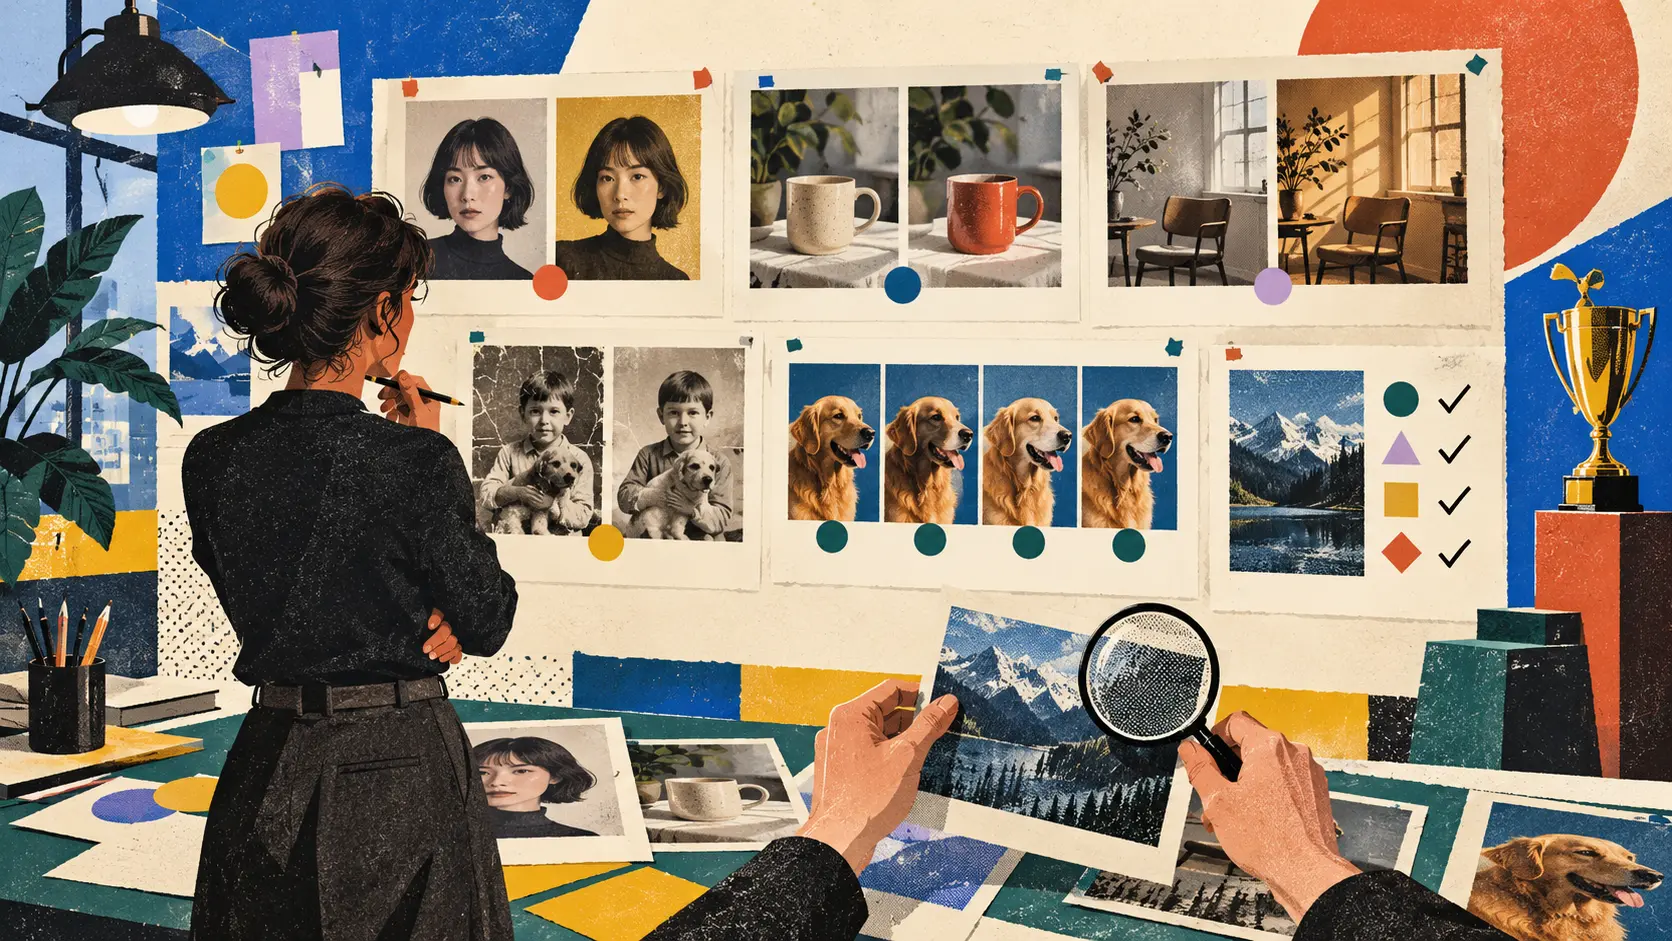
A leaderboard can tell you which door to open. It cannot tell you whether the room contains your furniture. Microsoft AI announced MAI Image 2.7 Preview on October 27. The company says the image-editing model debuted at number three on Arena Edit and number two on Artificial Analysis. The second table is especially useful because it publishes more than a single rank. On October 28, Artificial Analysis listed MAI Image 2.7 Preview at 1,193 Elo from 4,891 samples, with a 95 percent interval from 1,178 to 1,208. The table placed it behind GPT Image 2.5 Sunburst at 1,199 and ahead of GPT Image 2.5 Flare at 1,182. Those intervals overlap. So the honest reading is not that one system has permanently defeated another. It is that the preview sits in the current top group under this particular pairwise preference test. Artificial Analysis describes the evaluation as people comparing two edited images produced from the same source image and instruction, without the model names deciding the vote. The resulting Elo score reflects which output people preferred more often. That is meaningful evidence. It is not the same thing as a creative team approving a file for print, a product page, a film shot, a historical archive or a regulated campaign. Microsoft says 2.7 improved over MAI Image 2.6 across all 10 use cases and all seven editing actions evaluated by Artificial Analysis. It highlights enhancement and restoration, reasoning-based edits, scene and style changes, and text or symbol editing. The company says the model leads the next system by 24 Elo in scene and style. The examples of intended work are familiar: move a product into a new setting, change the lighting, alter one object without breaking the surrounding image, repair an older asset or replace text while keeping it visually integrated. That is the good news. The useful release is also narrower than the headline can sound. Microsoft calls the model a preview. Editing can be tried through MAI Playground, Arena and Artificial Analysis. Text-to-image generation is coming soon rather than available now. The Artificial Analysis table lists no API for 2.7, and Microsoft's announcement does not publish production pricing, latency, rate limits, licensing terms, a full model card or a separate safety evaluation. In other words, a studio can inspect the editing behavior today. It cannot yet infer a complete production contract. The gap between those two things is where an acceptance set earns its keep. Start with identity preservation. Use people, pets, products, rooms and landmarks that your team is permitted to test. Ask for a narrow change such as a jacket color, a background object or a lighting adjustment. Compare faces, body proportions, distinctive marks, packaging geometry and scene layout before and after. Do not score only whether the requested change appeared. Score what should not have changed. An image editor can satisfy the sentence and still quietly move an eye, invent a label, flatten a surface, alter a hand or replace the exact product with a plausible cousin. Those are not decorative errors when the subject is a real person or a catalog item. Next, test local edits. Mask one object or describe one region. Ask the model to change only that area. Measure spill into the background, shadows, reflections, depth of field and nearby objects. A red cup becoming blue is not a clean edit if the tablecloth, window light and person's sleeve also drift. Then test composition under pressure. Move a subject, add an object behind it, change the viewpoint or alter the environment. Check occlusion, perspective, contact shadows, reflections and physical support. An object should not hover merely because the prompt forgot to mention gravity. Text and symbols need their own lane. Use permitted mock labels, signs and interface elements with known spelling. Test short words, long words, repeated characters, punctuation, mixed case and the scripts your audience actually reads. Verify that the model changes only the requested text and keeps typography, alignment, contrast and neighboring marks stable. A pretty label with one wrong character is still wrong. Restoration also needs a truth boundary. Separate removing damage from inventing missing history. A model may clean scratches, balance tone and improve legibility. If it reconstructs a face, uniform, storefront or document detail that the source never preserved, label the result as a generated interpretation. Do not let a confident texture become archival evidence. Relighting should survive a physics check. Change time of day, mood or light direction. Inspect every shadow, reflection, highlight and translucent material. If the key light moves but the window reflection does not, the image may feel wrong before a viewer can explain why. Now repeat everything. Run each instruction several times with the same input and settings. Record how often the requested change lands, how often protected details drift and how many attempts a reviewer needs before approval. The cost of an editing model is not just a listed price per image. It is generations multiplied by retries, reviewer minutes, rejected outputs, file preparation and downstream correction. There is no published 2.7 API price to compare yet. Even when one arrives, a cheaper generation can be a more expensive approved asset if it requires five rounds and a retoucher. Build adversarial pairs. Put a protected logo near the edit area. Use a person with asymmetrical features. Include a mirrored surface, a transparent bottle, fine hair, patterned fabric, small print and a shadow crossing the mask. Try instructions that contain two changes but explicitly forbid a third. The goal is not to embarrass the model with a carnival trick. It is to find the point where your normal work stops being reliable. Keep provenance attached. Every test output should carry the source asset, permission basis, prompt, edit region, model name, model version, settings, timestamp, reviewer, decision and reason. Preserve the untouched original. If the product later exposes content credentials or other provenance metadata, verify that your export, resize, retouch and publishing chain does not strip it. Rights need a separate decision from quality. A model can produce an excellent edit that a team should not use. Confirm the rights to the source image, the authority to alter the subject, any restrictions on likenesses or cultural material, and the terms governing outputs. Do not use a leaderboard as a substitute for legal review. Create a stop list. Some jobs should remain human-led or require a second reviewer: identity-sensitive portraits, evidence, medical images, journalism, historical restoration, political material, children's images and regulated claims. The preview announcement does not establish suitability for those uses. Finally, decide before the demo what counts as a pass. Choose a weighted threshold for instruction success, protected-region fidelity, text accuracy, physical consistency, repeatability, provenance, review time and cost. Keep a few tests hidden from the people tuning prompts. Compare against the current human workflow and at least one alternative model. Then rerun the set whenever the preview changes. The version number matters because leaderboards move. Models are added, vote counts grow and the rank can change while the actual score remains within uncertainty. Your own asset mix can move even faster. A fashion studio, game team, museum and grocery catalog do not share one definition of a good edit. MAI Image 2.7 Preview has earned attention. It appears competitive in large human-preference evaluations, improves on Microsoft's prior version across the categories the company cites and is available for hands-on editing tests now. That is enough to put it in the trial queue. Promotion to the production queue needs a different receipt. Real assets. Protected regions. Repeat runs. Rights. Provenance. Reviewer time. Failure examples. A named person willing to approve the result. The leaderboard opens the door. Your acceptance set decides whether the model gets a key.
01
WHAT ACTUALLY CHANGED
Microsoft announced MAI Image 2.7 Preview on October 27 as an image-editing release
Microsoft reported a launch position of number three on Arena Edit and number two on Artificial Analysis
Artificial Analysis listed the preview at 1,193 Elo from 4,891 samples on October 28, with a 95 percent interval from 1,178 to 1,208
Microsoft says 2.7 improved over 2.6 across all 10 use cases and all seven editing actions in the Artificial Analysis evaluation
The company highlights restoration, reasoning-based edits, scene and style changes, and text or symbol editing
Editing is available through evaluation sites and MAI Playground, while text-to-image generation is still listed as coming soon
02
WHY THIS MATTERS
A strong human-preference result can identify a model worth testing without proving it fits a specific production workflow
Overlapping score intervals make a permanent winner claim less defensible than a top-group interpretation
Creative acceptance depends on both the requested change and the preservation of everything that should remain untouched
Retries, human review and downstream repair can matter more than a per-image price
Preview availability does not provide a full production contract, model card, safety case or API service level
Rights, provenance and high-risk subject matter remain separate approval questions from visual quality
03
WHERE IT COULD HELP
- Build an acceptance set from representative, permitted production assets
- Score requested changes and unintended drift as separate measures
- Test identity, product geometry, local edits, text, lighting, restoration and physical consistency
- Repeat identical tasks to measure reliability and reviewer effort
- Include mirrors, transparency, fine texture, small type and protected marks in stress tests
- Record source rights, prompts, edit regions, versions, settings, reviewers and decisions
- Keep restoration separate from invented historical reconstruction
- Define a stop list for identity-sensitive, evidentiary, medical, journalistic and regulated work
- Compare total approved-asset cost rather than one generation price
- Rerun the hidden acceptance set whenever the preview or service terms change
KEEP A HAND ON THE WHEEL
MAI Image 2.7 is a preview. Microsoft reported the launch ranks, improvement over 2.6 and 24-Elo scene-and-style lead. Artificial Analysis provides a current independent table based on pairwise human preferences, but its rank and sample count can change. Overlapping confidence intervals do not establish a permanent ordering. The announcement does not publish a full model card, independent safety evaluation, production API, price, latency, rate limits or complete rights terms. Text-to-image generation is described as coming soon. Watch for stable API access, versioned model documentation, pricing, service limits, provenance support, independent safety testing and performance on representative production assets.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 28, 2026.
PUBLICATION RECEIPT: The article treats leaderboard positions as time-bound preference evidence, identifies the preview and missing production terms, and separates visual quality from rights, provenance and high-risk use approval.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US