THE SIGNAL IN ONE SENTENCE
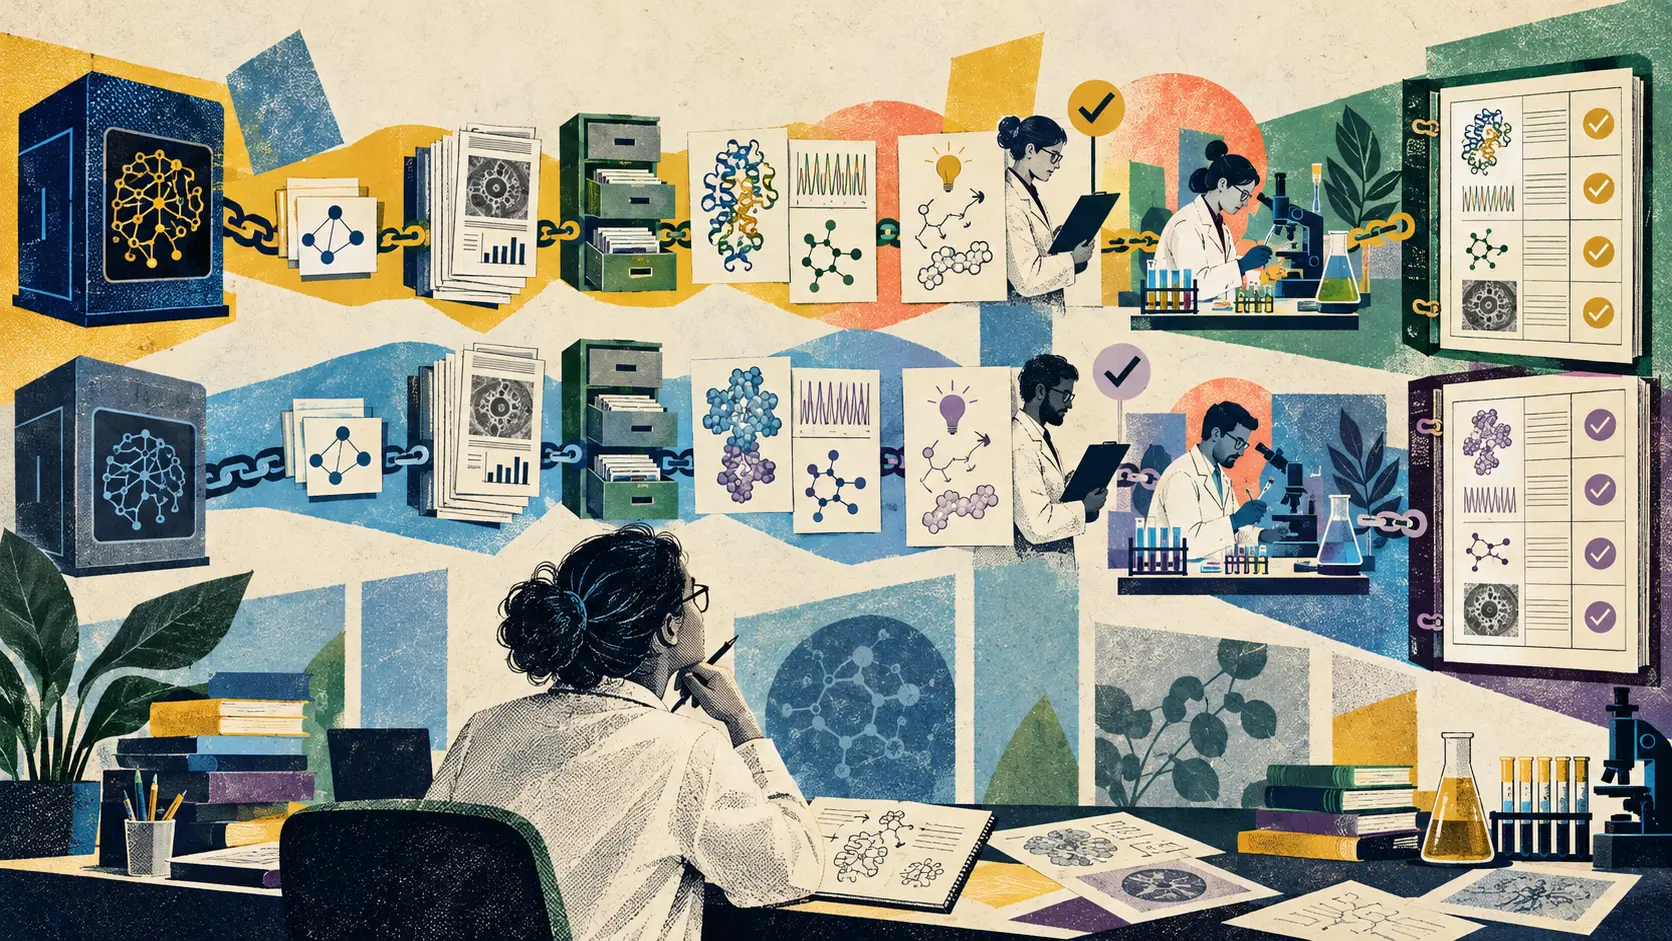
A scientific workflow can survive a new pipette. It can survive a new database. It can even survive a new colleague who insists the shared folder needs twelve more subfolders. What it cannot survive is an invisible change to the reasoning system that helped choose the hypothesis, find the sources, write the analysis and plan the next experiment. OpenAI added GPT-6 Rosalind Research to its model release notes on October 30. The company describes it as bringing GPT-6 reasoning to multistep life-sciences research with safeguards designed for biological work. It is rolling out to a limited set of approved Research customers in Work, Codex and the API. The rollout is narrow. GPT-6 Rosalind Research is not available in the Chat tab. Access requires Rosalind Research approval for both the organization and the authorized user. Approval for the Discovery tier does not grant Research access. API access requires a separately approved API organization. The model identifier is gpt-6-rosalind. OpenAI says approved API use is for internal research tools, workflows and applications, not customer-facing products or external commercial applications. Enterprise workspaces begin with a two-week Admin Preview. The model is off by default during that period. Administrators can enable it for approved Research users and configure access for after the preview. Existing Research approval does not bypass the preview. Customers can keep using GPT-5.5 Rosalind Research for existing workflows. Rosalind Discovery remains on the 5.5 model. That coexistence matters. It gives research teams a chance to compare the new model with the old one instead of quietly replacing the engine under an active project. OpenAI says GPT-Rosalind is meant for life-sciences work that can include target research, genomics, sequence and protein analysis, medicinal chemistry, literature synthesis, wet-lab troubleshooting and experiment planning. In Codex, the Life Sciences Research plugin connects the model to scientific tools, databases and data sources. Those are consequential workflows. A model can help a scientist find a paper, write code or organize evidence without becoming the author of a scientific result. But once it selects sources, transforms data, invokes tools or proposes an experiment, it becomes part of the path that produced the claim. That path must stay visible. The release notes do not publish independent scientific benchmarks for GPT-6 Rosalind Research. They do not establish clinical validity. They do not turn generated hypotheses into observations, validate a protocol or authorize a medical use. A model upgrade is not a laboratory result. It is a change to the instrument chain. Treat it that way. The practical response is an upgrade evidence chain. Start before the switch. Freeze a representative set of current projects and tasks under GPT-5.5 Rosalind Research. Include literature reviews, sequence analyses, tool-driven workflows, code generation, evidence synthesis, experiment planning and the ugly cases that caused corrections. Do not select only tidy demonstrations. Include incomplete data, conflicting papers, missing metadata, ambiguous targets, tool failures, inaccessible sources and tasks where the correct answer is to stop. For every baseline run, record the exact model, product surface, date, workspace, access tier, system instructions, enabled skills, installed plugins, tool versions, database versions, source snapshots, parameters and output. The model name alone is not enough. The same model can behave differently when a database updates, a plugin changes, a prompt is revised or an administrator alters permissions. Next, define the claim. Every model-assisted artifact should say what it is evidence for. A literature table can support a statement about what selected papers reported. A sequence-analysis output can support a statement about what a named tool produced from a specific input under specific parameters. A generated hypothesis can support the claim that the team considered an idea. It cannot support the claim that the idea is biologically true. Make that boundary explicit. Record inputs with durable identifiers. For literature, preserve the query, databases, search date, filters, result set and document versions. A later search may return a different paper or a corrected preprint. For sequences and structures, preserve accession identifiers, versions, checksums, assemblies, reference genomes and preprocessing steps. For internal data, preserve a protected reference to the governed dataset, schema, consent boundary, access decision and transformation history. Do not paste sensitive material into a general project log. For every tool call, record the tool, version, parameters, environment, input digest, output digest, warnings and exit state. If the model changed a parameter after a failed run, keep both attempts. Failure is part of provenance. Record the prompt chain. Keep the user request, system instructions, supplied context, retrieved documents, intermediate decisions, tool requests and final response in the form allowed by the organization's security and retention rules. When full reasoning traces are unavailable or inappropriate to store, keep a structured action record. What task was attempted? Which sources were selected? Which tools were called? What assumptions were stated? What uncertainty was reported? Which human approved the next step? The goal is not to collect private thought for decoration. It is to preserve enough evidence to reconstruct the scientific workflow. Now compare models. Run the same frozen cases under GPT-5.5 Rosalind Research and GPT-6 Rosalind Research. Keep the environment as stable as practical. Do not ask only whether the new answer looks better. Ask what changed. Did it choose different papers? Did it omit a contradictory study? Did it change the order of evidence? Did it select a different tool? Did it write different code? Did it alter a filtering threshold? Did it become more willing to recommend a wet-lab follow-up? Did it express uncertainty differently? Did it refuse a task the previous model attempted, or attempt a task the previous model refused? Every difference should enter a comparison record. Classify it as an improvement, regression, neutral variation, unresolved difference or scope change. Require a domain reviewer to sign off on high-consequence differences. Do not let the new model grade itself. Use independent checks where possible. Run deterministic tools against known controls. Test code with fixed inputs. Compare citations to the cited passages. Recalculate numerical results. Use blinded expert review for hypotheses and plans. Repeat nondeterministic runs enough times to see whether the apparent improvement is stable. For biological work, include negative controls. Give the system a target with insufficient evidence. Give it sources that disagree. Give it a sequence with a known annotation trap. Give it a workflow where a tool is unavailable. Give it a request outside the approved scope. A research model should be evaluated on how it handles the missing and the contradictory, not just how elegantly it narrates the complete. Keep tools inside the chain. The Life Sciences Research plugin can connect Codex workflows to external scientific tools, databases and data sources. Installing the plugin does not grant model access, and model access does not guarantee permission to every connected source. That separation should appear in the record. For each action, show whether authority came from the model approval, workspace role, plugin permission, source account or human confirmation. A model that can propose a database query is not automatically authorized to retrieve every dataset the user can name. Record where data moved. Show which content entered the model context, which content stayed inside a tool, which outputs were stored and which external systems received data. OpenAI's access page tells organizations to check their data-handling requirements before connecting internal sources. That is the beginning of the governance work, not the end. Treat the two-week Admin Preview as a study period. An administrator can enable the model only for approved Research users. Use that narrow window to test access controls, role assignments, logging, retention, plugin permissions and incident response. Start with a small cohort. Choose researchers who can evaluate the science and document the workflow. Give them representative tasks, not unrestricted novelty hunting. Ask them to label corrections, missing evidence, false confidence, unsafe suggestions, tool failures and work that the model improved. Publish a preview scorecard inside the organization. Include task coverage, model differences, reviewer disagreement, unresolved risks, data sources, plugin versions, access exceptions and whether rollback to GPT-5.5 remains available. The preview should end with a decision, not simply the passage of fourteen days. After activation, keep the old baseline. OpenAI says customers can continue using GPT-5.5 Rosalind Research. That makes rollback and reproduction possible, at least while both models remain available. Record which model produced every artifact. Pin gpt-6-rosalind in API workflows rather than using a vague family label. Preserve a reproducible test set for model or tool changes. When the older model is eventually unavailable, keep its outputs, configurations and validation results so the research record still explains the transition. Version the evidence chain itself. The chain should include: The research question. The model and product surface. The prompt and instructions. The source set and versions. The tools, plugins and parameters. The generated artifacts. The human reviews and corrections. The physical or computational validation. The final claim and its limits. The model-upgrade comparison. The release decision. Each link needs an owner, timestamp and durable identifier. If one link changes, the chain should show which downstream artifacts may need to be rerun. That dependency map matters. A corrected source can invalidate a summary. A new reference genome can change an alignment. A plugin update can change a tool call. A model update can change which evidence enters the analysis. Research teams already understand versioned protocols, instrument calibration, data lineage and laboratory notebooks. Model provenance belongs in the same family of practice. It should not live in a separate AI policy document that nobody opens during actual work. Put it beside the assay, the notebook, the repository and the review. Keep a plain-language receipt for every model-assisted milestone. The receipt should say: Which model helped. What it was asked to do. What evidence it could access. Which tools it used. What it produced. Who checked it. What was independently reproduced. What remains uncertain. What would trigger rerunning the work. That receipt protects the scientist from two bad stories. The first is that the model did everything. The second is that the model did nothing important. Both erase the real workflow. The useful account is more specific. The model may have widened a search, proposed a hypothesis, written analysis code or coordinated tools. A scientist chose the question, governed the data, reviewed the evidence, corrected the output, ran the experiment and decided what claim the result could support. The chain shows those contributions without turning either party into a mascot. GPT-6 Rosalind Research may prove more capable for approved teams. The public materials do not yet let an outside reader measure how much more capable, on which scientific tasks, under which tools or with what failure distribution. That evidence has to come from careful evaluation and reproducible work. The new model can enter the laboratory. It should not enter invisibly.
01
WHAT ACTUALLY CHANGED
OpenAI announced GPT-6 Rosalind Research on October 30, 2026 for multistep life-sciences research
The model is rolling out to a limited set of approved Research organizations in Work and Codex, and through the API where separately approved
GPT-6 Rosalind Research is not available in the Chat tab and requires Research approval for both the organization and authorized user
Enterprise workspaces begin with a two-week Admin Preview in which the model is off by default
The API identifier is gpt-6-rosalind, while GPT-5.5 Rosalind Research remains available for existing workflows and Rosalind Discovery stays on 5.5
02
WHY THIS MATTERS
A model change can alter source selection, hypotheses, code, tool calls, parameters, uncertainty and experiment plans
Keeping GPT-5.5 and GPT-6 Rosalind Research available together creates a practical window for controlled comparison and rollback
Scientific provenance must include the model, prompt, sources, tools, permissions, outputs, reviewers and validation rather than only the final artifact
A model-assisted hypothesis or analysis is part of an evidence path, not independent proof that a biological claim is true
The release materials do not publish independent scientific benchmarks or evidence of clinical validity
03
WHERE IT COULD HELP
- Freeze representative research tasks and rerun them under GPT-5.5 and GPT-6 Rosalind Research with matched tools, sources and settings
- Record model identifiers, prompts, source versions, plugin versions, tool parameters, input and output digests and human approvals for every consequential workflow
- Classify model differences as improvements, regressions, neutral variations, unresolved differences or scope changes
- Use deterministic checks, negative controls, citation verification, blinded domain review and physical or computational reproduction
- Turn the two-week Admin Preview into a documented study of access, permissions, logging, data movement, failure handling and rollback
- Attach a plain-language evidence receipt to every model-assisted milestone and map which downstream artifacts need rerunning after a change
KEEP A HAND ON THE WHEEL
Watch for a dedicated GPT-6 Rosalind Research model card, independent scientific evaluations, task-specific benchmarks, documented failure categories, updated biological safeguards, broader organizational availability and any change to GPT-5.5 rollback. Also watch for clarity on reproducibility across Work, Codex, API, plugins and changing scientific databases.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 31, 2026.
PUBLICATION RECEIPT: First edition. Verified against OpenAI’s October 30 model and managed-workspace release notes plus current GPT-Rosalind access and setup documentation.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US