THE SIGNAL IN ONE SENTENCE
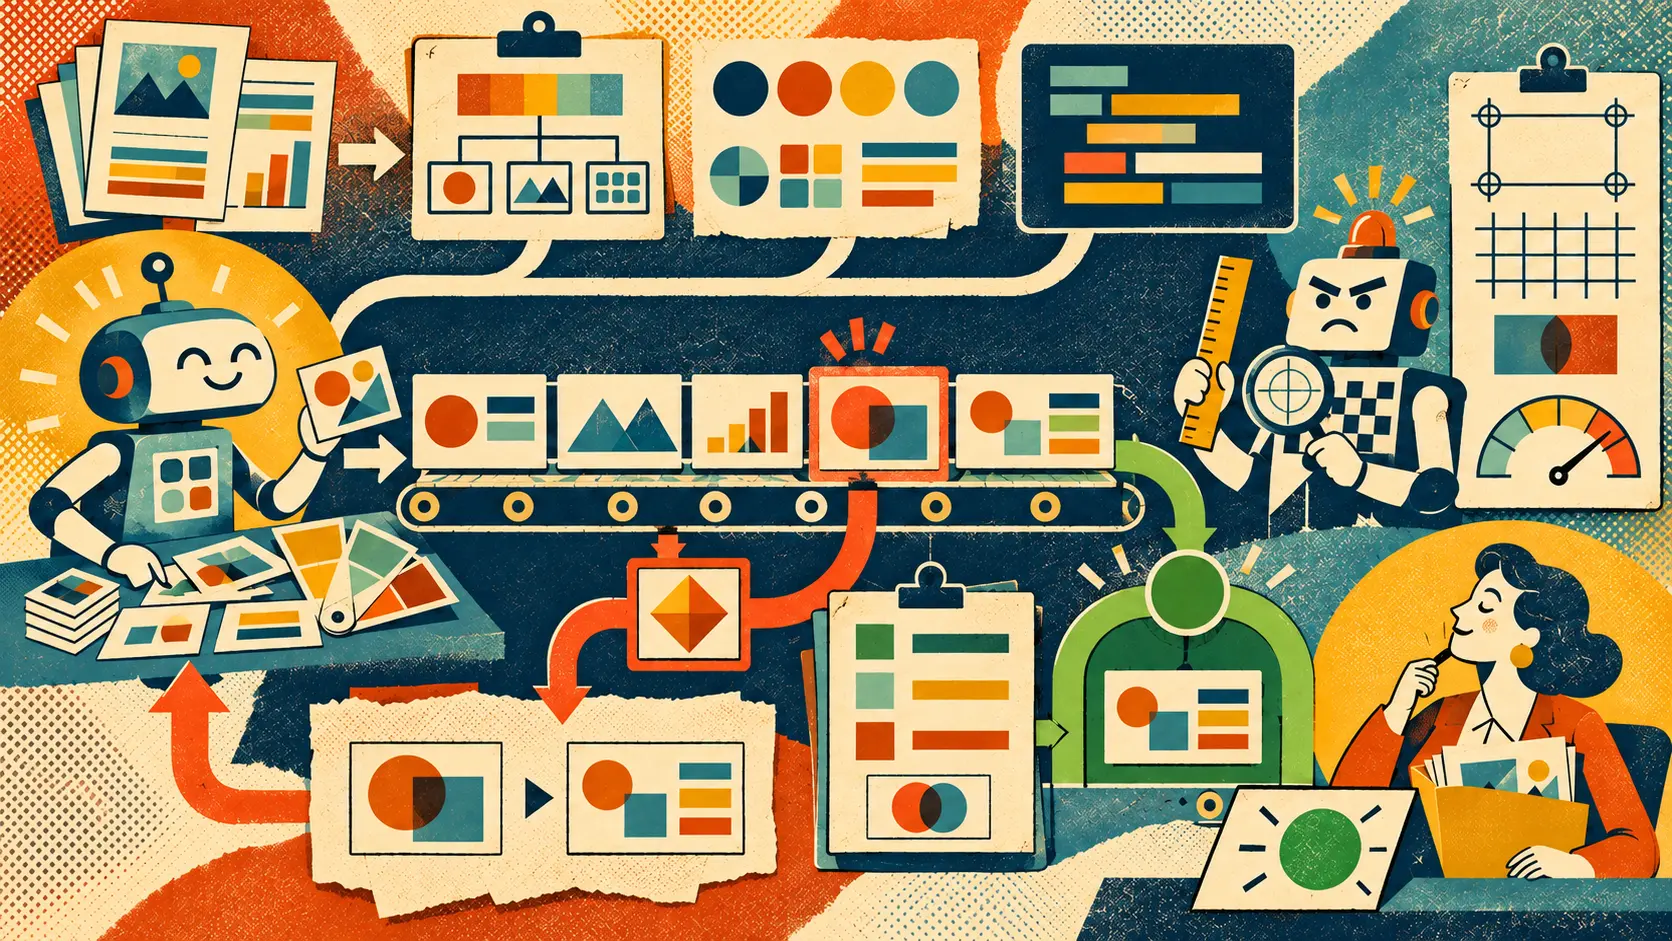
The small model made the deck. The checker made it shippable. IBM Research has described Palette, an experimental system that turns source material into presentation slides following IBM's own design language. The interesting part is not simply that a model can arrange boxes and colors. We have plenty of machines that can make a handsome rectangle. The interesting part is the division of labor. Palette starts with a 20-billion-parameter open-weight model fine-tuned through one LoRA adapter. The same adapted model plays two roles. As the designer, it creates a structured JSON brief covering the deck's palette, typography, exact content and visual reasoning. As the coder, it turns that brief into JavaScript for PptxGenJS, which produces editable presentation files. Those two roles make the plan visible. A reviewer can inspect the proposed content and design system before admiring the rendered slides. That is much better than asking a model for a deck and receiving an opaque file full of plausible choices. IBM says coder calls can run in parallel, making generation six to seven times faster than producing every slide in one long sequence. The model was trained on roughly 1,000 synthetic decks containing about 10,000 slides. IBM also says examples were rendered and repaired during training, including counterfactual cases that teach the model what bad layout decisions look like. Reference decks proved more reliable than written rules for steering the desired style, according to the team. That makes sense. A house style is not only a list of approved colors and font sizes. It is a collection of recurring judgments about density, hierarchy, rhythm, whitespace and when to stop adding another chart. Still, imitation is not verification. Palette's harness runs simple rules and geometry checks after rendering. It looks for problems such as overlap, clipping and overflow. When a slide is flagged, an editor model rewrites the slide code. The crucial rule is wonderfully unromantic: the replacement is kept only if the checker confirms that it improved the score. If the repair is worse, the original survives. The checker gets veto power. Across 131 decks, IBM reports that this harness improved results by an average of 3.5 points. That figure is company-reported and depends on IBM's own pipeline, tasks and measurements. It is still a useful design pattern because the acceptance test sits outside the model that proposed the repair. A model can talk itself into believing that a second attempt is better. A deterministic measurement can simply notice that the footer is still hanging off the slide. The same principle should govern production deck systems. Keep the model creative where judgment helps. Make the checker stubborn where measurement is possible. Start with source fidelity. Every factual claim, quotation, number and chart should point back to the exact source fragment used in the brief. Preserve the source file, page or cell, retrieval time and any transformation applied. If the deck says revenue rose 18 percent, the reviewer should be able to reach the underlying evidence without spelunking through a chat transcript. Then freeze the design inputs. Store the version of the brand tokens, reference decks, templates, color roles, typography rules and component library used for the run. A deck cannot be reproduced if the friendly label "company template" quietly changes next Tuesday. Preserve the structured plan and generated code. The plan explains what the system intended. The code shows what it actually asked the renderer to build. The rendered slide shows the final pixels. Those are three different artifacts, and all three belong in the receipt. Run deterministic checks after rendering. Measure bounds, clipping, collisions, alignment, margins, empty placeholders, missing assets, tiny type and broken links. Confirm that slide dimensions and export settings are correct. Hash the rendered output so a reviewer knows which exact file passed. Add accessibility checks too. Test contrast, minimum font size, reading order, descriptive alternatives for meaningful images and whether information encoded by color has another cue. Some of these checks can be automated. Others need a person. A slide that fits perfectly can still be impossible to read. Keep the repair diff. Record the original slide code, the flagged condition, the proposed change, the new measurements and the accept or reject result. If the model moves a chart to fix an overlap but disconnects it from its label, a reviewer should see the trade. Finally, require a human sign-off that names the reviewer and the scope of the decision. Did the person verify facts, brand fit, accessibility and audience appropriateness, or merely confirm that the file opens? "Reviewed" is not a useful status unless the review boundary is visible. The checker also needs boundaries of its own. A geometry test can prove that two boxes do not collide. It cannot prove that the chart tells the truth, the hierarchy makes sense or the slide respects the audience. A slide can pass geometry and still lie beautifully. PresentBench, the public benchmark IBM used for comparison, measures presentation generation across domains such as economics, education and talks. IBM reports that Palette ranked first on economics and education, third on talks and second on the three-domain mean, with 59.7 compared with 60.8 for NotebookLM. The evaluation used plans drafted from source documents by a separate frontier model rather than Palette's own designer role. That last detail matters. The benchmark result does not isolate the full end-to-end system, and PresentBench does not test whether a deck follows IBM's specific house style. IBM says so directly. A general presentation score and a brand-fidelity score are different exams. The training data deserves similar caution. Synthetic decks make scale and control easier, but they can reproduce the habits and blind spots of the systems that created them. The public post does not provide an independent audit of factual fidelity, accessibility, style adherence or failure rates on real internal work. A 20-billion-parameter model is also "small" only by frontier-model standards. Self-hosting it still requires serious inference infrastructure, deployment expertise and monitoring. Teams should compare that operational cost with smaller specialized models, hosted services and simpler template-driven systems. The pattern is useful well beyond slide generation. Sales proposals, board reports, training materials, recurring analytics and client updates all mix creative judgment with measurable constraints. Give the generator room to propose. Give independent tests authority to reject. Give a person enough evidence to decide. Let the model draw. Let the checker veto. Let the human decide.
01
WHAT ACTUALLY CHANGED
IBM Research described Palette, a presentation-generation system built around a 20-billion-parameter open-weight model fine-tuned with one LoRA adapter for designer and coder roles.
The designer role produces a structured JSON brief with palette, typography, exact content and rationale, while the coder role turns that brief into PptxGenJS code for editable slides.
IBM says the model was trained on roughly 1,000 synthetic decks containing about 10,000 slides, including rendered and repaired examples.
The harness checks simple rules and rendered geometry, asks an editor model to repair flagged slides and keeps a rewrite only when the checker confirms an improvement.
IBM reports an average 3.5-point gain from the harness across 131 decks and a second-place three-domain mean on PresentBench, where evaluation plans came from a separate frontier model.
02
WHY THIS MATTERS
Separating the plan, code and rendered output gives reviewers three inspectable artifacts instead of one opaque generated file.
A deterministic checker can reject a model's confident but measurably worse repair without asking another model to judge the same mistake.
Reference decks can carry design judgment more effectively than prose rules, but they need versioning and provenance if teams want reproducible house style.
Geometry checks catch clipping, overflow and overlap, but they do not establish factual accuracy, accessibility or sound editorial hierarchy.
A benchmark built with a separate planner does not isolate the end-to-end quality of Palette's own designer and coder workflow.
03
WHERE IT COULD HELP
- Create a deck receipt containing source fragments, retrieval times, brief version, brand tokens, reference deck identifiers, generated code and render checksum.
- Run deterministic checks for bounds, overlap, clipping, alignment, margins, missing assets, tiny type, broken links and export settings after every render.
- Add accessibility checks for contrast, minimum type size, reading order, descriptive image alternatives and information encoded only by color.
- Store every repair diff with the original code, flagged condition, proposed edit, before-and-after measurements and acceptance result.
- Require human sign-off for factual fidelity, brand fit, accessibility and audience appropriateness, with the exact review scope recorded.
- Evaluate the full system and each component separately so a strong external planner cannot conceal a weak in-house planning stage.
- Test sales decks, board reports, proposals, training materials and recurring analytics with real source documents before broad deployment.
- Compare the infrastructure cost of a 20-billion-parameter self-hosted model with smaller specialized models and template-driven systems.
KEEP A HAND ON THE WHEEL
Palette's performance and efficiency figures are reported by IBM Research and rely heavily on synthetic training data. The public description does not provide an independent audit of factual fidelity, accessibility, house-style adherence or production failure rates. PresentBench does not test IBM Design Language compliance, and the reported benchmark used a separate frontier model to prepare the plan. Geometry checks can miss misleading charts, incorrect claims and weak editorial decisions. A 20-billion-parameter self-hosted model still requires substantial infrastructure and operational expertise.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 4, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US