THE SIGNAL IN ONE SENTENCE
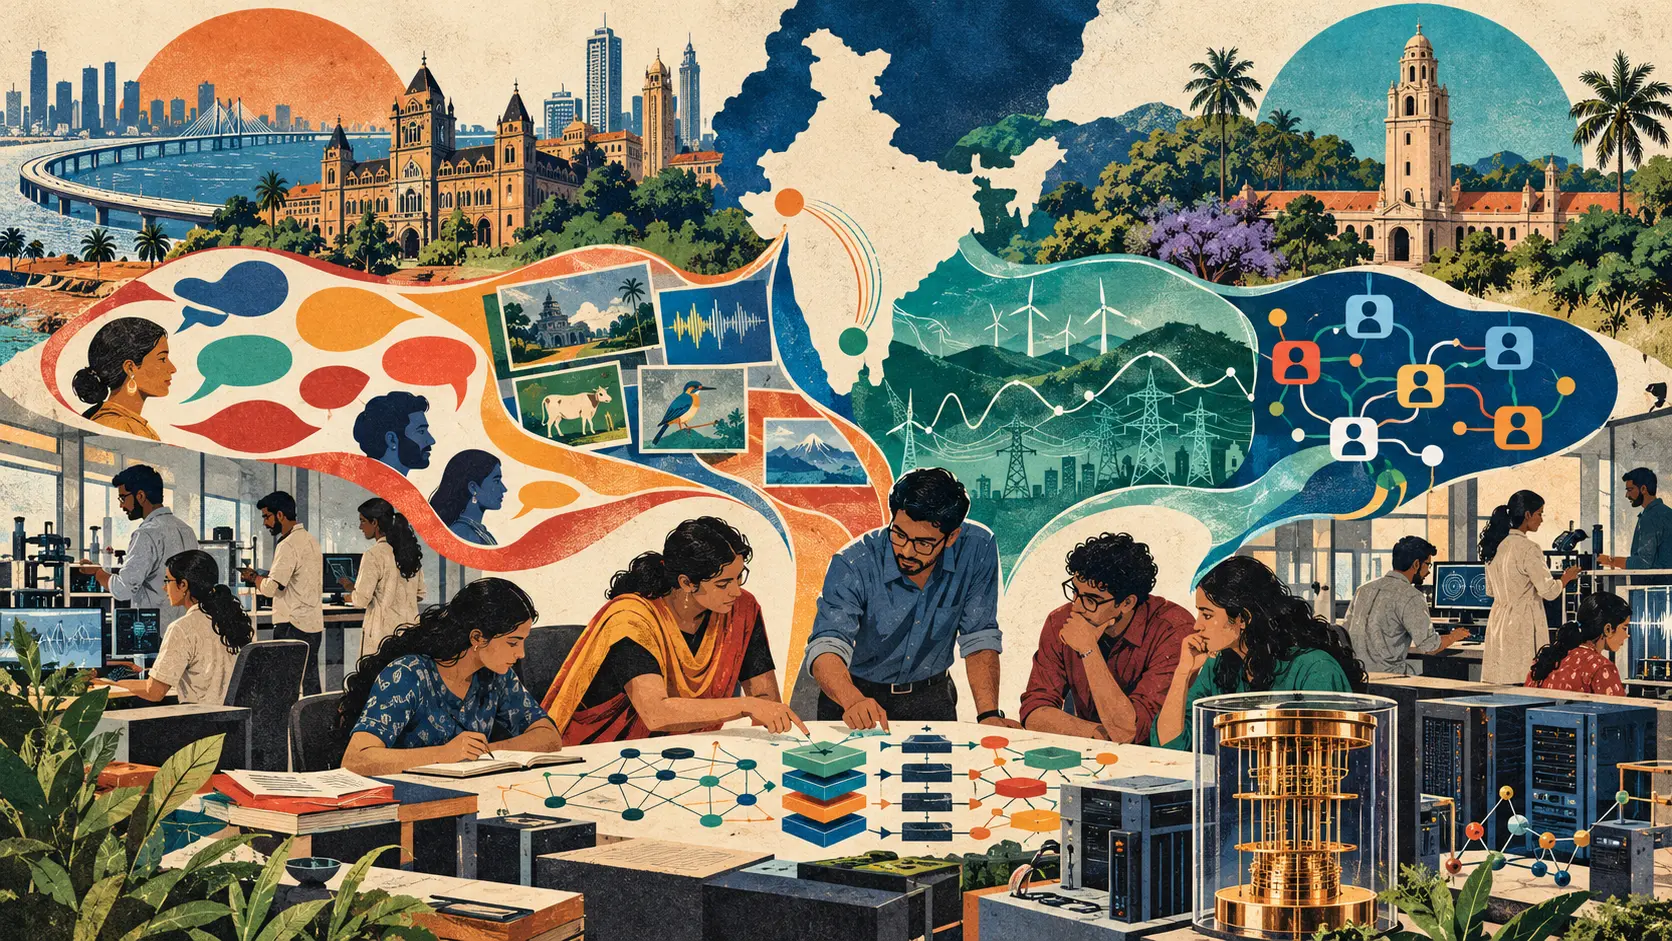
India's AI research agenda just grew wider without pretending that one giant model can solve every problem. On October 1, IBM announced expanded research collaborations with the Indian Institute of Technology Bombay and the Indian Institute of Science in Bengaluru. The two partnerships are not new. IIT Bombay began working with IBM through the AI Horizons Network in 2018. IISc launched a hybrid-cloud research lab with IBM in 2021. The latest announcement moves both relationships into another phase. The subjects now stretch from Indic language-model adaptation and multimodal systems to agent orchestration, energy forecasting and quantum-classical computing. That is a mouthful. It is also the interesting part. The plain signal is that two of India's leading research institutions are treating AI less like one product category and more like a connected layer of national capability. Language, education, enterprise knowledge, software operations, electricity systems and scientific computing each demand different data, models, infrastructure and tests. IIT Bombay's part of the expanded agenda focuses on three broad lanes. The first is sovereign and Indic language-model adaptation. The goal described by IBM is to improve multilingual capability for Indian languages through more efficient adaptation and optimization. That matters because a model that performs well in English can still fail when vocabulary, script, grammar, cultural context and code-switching change. India does not have one language problem. It has hundreds of language and dialect contexts, uneven digital representation and very different consequences when a system misunderstands a banking question, a school lesson or a public-service form. Model adaptation can be more practical than training every system from zero. Researchers can begin with an existing model, then change its behavior with carefully governed language data, task examples and evaluation. The hard part is proving that the adapted system works beyond a tidy laboratory set. A benchmark for Hindi does not automatically establish performance in Marathi, Tamil, Bengali or a code-mixed conversation. A fluent answer is not necessarily a correct one. A public model is not sovereign merely because it has an Indian name. Meaningful control includes the data, weights, computing environment, evaluation, deployment, maintenance and ability to leave a supplier. The expanded collaboration says sovereign AI is a research focus. It does not announce a completed sovereign stack. The second IIT Bombay lane is multimodal AI. The announcement connects this work to programming education, human-AI collaboration and intelligent operations across hybrid clouds. Multimodal systems combine forms of input such as text, images, audio, diagrams or code. That could be useful in a classroom where a learner submits code, a diagram and an explanation together. It could help an operations team connect a warning chart with logs and a repair procedure. It could help a knowledge system retrieve a table or image instead of flattening every question into prose. It also expands the evaluation burden. The system must interpret each input correctly, connect them without inventing a relationship and explain enough of the result for a person to challenge it. A model that answers the text while ignoring the chart is technically multimodal and practically useless. The third lane is AI infrastructure and knowledge retrieval. IIT Bombay and IBM plan to study faster, more accurate and scalable access to enterprise knowledge, along with runtime and distributed-inference optimization. Distributed inference divides the work of running a trained model across several processors or machines. It can increase capacity or reduce delay, but it adds communication, scheduling and failure points. An optimization that wins on one cluster may lose when the network, hardware or workload changes. For Indian institutions and companies, that systems work can matter as much as a new model. A multilingual assistant is not useful if it requires hardware that the intended school, hospital or business cannot afford. A retrieval system is not trustworthy if it returns an old policy without its date or source. IISc's side of the announcement begins with agentic systems. The researchers plan to study workflows that coordinate agents across hybrid-cloud environments while balancing performance, cost and operational complexity. An agent in this context is software that can pursue a goal through a sequence of model calls, tools and decisions. Orchestration decides which component acts, what it may access, how state passes between steps and what happens when a step fails. The glamorous demo is a group of agents finishing a task. The research problem is everything around the demo: permissions, scheduling, retries, conflicting outputs, cost limits, logs, human approval and recovery. An energy operator does not need five agents enthusiastically agreeing with one another. It needs a visible chain of authority and a safe state when the chain breaks. That leads into IISc's most concrete application lane. The collaboration plans lightweight time-series foundation models based on IBM's Granite family for energy analytics. The named tasks are forecasting, anomaly detection, load disaggregation and energy optimization. IBM also says benchmark datasets will be contributed to wider research. Time-series models look for patterns in measurements ordered over time. In an energy system, that may mean predicting demand, detecting an unusual equipment signal or separating a total load into likely sources. Lightweight models could make those tools usable closer to meters, substations or facilities instead of routing every reading through a very large remote service. That can improve response time and reduce computing needs. It does not eliminate the need for representative data or operational testing. Energy data changes with geography, weather, building type, industrial activity, tariffs and human behavior. A benchmark assembled from one set of conditions can reward a model that fails somewhere else. Dataset documentation should show coverage, missing periods, sensor quality, privacy treatment, intended uses and groups or regions that are poorly represented. The third IISc lane connects quantum computing with high-performance classical systems. The announced work includes orchestration for quantum-centric supercomputing and algorithms intended to improve quantum subspace iteration through approximation-tolerant classical diagonalization. That is exploratory computing research, not a claim that a quantum machine has displaced ordinary systems. In most practical workflows, classical computers prepare data, choose or optimize circuits, control jobs and interpret results. The research question is how to divide work sensibly and whether the combined method produces a measurable benefit for a defined scientific problem. The announcement does not provide a benchmark, finished algorithm or demonstrated scientific result for this new phase. It names the lane. That same caution applies across the entire expansion. IBM, IIT Bombay and IISc have long records of joint work. IIT Bombay's 2018 announcement described research in knowledge representation, multimodal content and domain-specific agents. IISc's 2021 lab promised an open-access approach, conference publications, workshops and open-source material. A 2023 renewal covered natural-language processing, time-series models, misinformation, hybrid-cloud orchestration and sustainable computing. The October 2026 agenda is therefore an evolution, not a blank-sheet launch. Continuity can be valuable. Students and faculty gain access to long-lived research problems, industry collaborators and infrastructure. IBM gains contact with deep academic expertise and a pipeline of methods that may become useful products. India gains a chance to build technical capability around languages, energy and computing systems that matter locally. Continuity can also make accountability fuzzy. When a collaboration lasts for years and spans several institutions, it becomes easy to announce themes without showing which promised outputs arrived. A research paper, open-source library, dataset, student placement, patent, model, course and enterprise product are not interchangeable results. The current announcement does not specify funding, project counts, milestones, hardware access, data-governance rules, intellectual-property arrangements or licenses for each planned output. It does not say which datasets, models or benchmarks will be public. It does not define how many students will participate or who receives access to the resulting infrastructure. Those omissions do not mean the work will be closed or underfunded. They mean the public cannot measure the next phase from the announcement alone. The simplest improvement would be a collaboration ledger. Each project could publish its problem, participating laboratory, student roles, funding source, starting date, expected output, data rules, evaluation method, intended license and current status. A research result could link to its paper, code, model card or dataset documentation. A private result could state why it is restricted and what public evidence remains available. For Indic systems, the ledger should name languages, dialects, domains, data sources, speaker communities and evaluation gaps. For energy models, it should document geographic and operational coverage. For agents, it should show permissions, failure tests, cost and human handoffs. For quantum-classical work, it should compare the complete workflow against a serious classical baseline. Student opportunity deserves its own row. Industry-academic partnerships often promise talent development. The public should be able to see how many students receive research positions, mentorship, compute, authorship, internships or open-source experience, and whether participation reaches beyond a small circle of well-connected labs. Ownership deserves another row. If a student helps build a dataset or model, who may publish it, reuse it, commercialize it or continue the work after the agreement ends? If public university resources contribute, what public value returns? None of this requires turning research into bureaucracy soup. A concise record can make ambitious collaboration easier to trust, reproduce and reuse. India's advantage is not simply a large pool of technical talent or a large market. It is the opportunity to frame frontier research around unusually varied real-world conditions: many languages, uneven infrastructure, dense cities, distributed energy systems, large public services and enormous differences in device and network access. That complexity can produce better science if it remains visible. It can also produce impressive announcements that work only for the easiest users if it is flattened into an average. IIT Bombay, IISc and IBM have drawn a serious research map. The next signal is not another list of topics. It is the trail of datasets, benchmarks, open tools, student work and verified applications left behind as the map becomes actual research.
01
WHAT ACTUALLY CHANGED
IBM announced an expanded phase of its research collaborations with IIT Bombay and IISc on October 1, 2026.
The IIT Bombay collaboration began in 2018 and now includes sovereign and Indic model adaptation, multimodal systems, knowledge retrieval and AI infrastructure.
The IISc collaboration began with a hybrid-cloud lab in 2021 and now includes agentic systems, energy-focused time-series models and quantum-classical workflows.
The energy research names forecasting, anomaly detection, load disaggregation and optimization as target applications.
IBM says the IISc work will contribute benchmark datasets intended to support broader research.
The agentic-systems work will examine orchestration across hybrid-cloud environments while balancing performance, cost and complexity.
The quantum work will explore orchestration between quantum and high-performance classical systems.
The announcement describes an expanded research agenda, not completed models, benchmarks or deployments.
It does not provide funding amounts, project milestones, output licenses, data-governance terms or ownership rules for each workstream.
The collaborations continue earlier joint work in language technology, multimodal systems, hybrid cloud, time series and computing orchestration.
02
WHY THIS MATTERS
Indian languages and code-mixed use require local data, evaluation and adaptation rather than assuming English performance will transfer.
Sovereign AI depends on control over data, models, compute, operation and exit paths, not branding alone.
Multimodal education and operations tools need tests that reveal whether every input contributes to the answer.
Distributed inference research can make models more usable, but hardware and network assumptions must be published for results to travel.
Agent orchestration turns permissions, logs, recovery and human approval into core systems research.
Energy models can support forecasting and optimization only when datasets represent the locations and operating conditions where they will be used.
Quantum-classical research should be measured against complete classical baselines rather than isolated component speedups.
A public output ledger would help students, researchers, funders and communities see what a long partnership actually produces.
03
WHERE IT COULD HELP
- Adapt and evaluate language models for specific Indian languages, dialects, domains and code-mixed conversations.
- Build programming-education tools that interpret code, diagrams and learner explanations together.
- Improve enterprise retrieval while preserving document sources, dates, permissions and revision history.
- Optimize inference across local servers, accelerators and cloud infrastructure with reproducible hardware assumptions.
- Orchestrate agents with explicit permissions, cost budgets, logs, human approvals and safe recovery states.
- Forecast energy demand and detect anomalies with lightweight models that can operate near local systems.
- Publish documented benchmark datasets for energy and Indian-language research.
- Compare quantum-classical workflows with strong classical methods on complete scientific tasks.
- Track student positions, mentorship, authorship, compute access and open-source contributions.
- Publish project-level funding, milestones, data rules, ownership, licenses and reusable outputs.
KEEP A HAND ON THE WHEEL
This is an expansion of continuing research collaborations, not a finished product release or an independent performance result. The October 1 announcement does not specify funding amounts, project deadlines, hardware allocations, participant counts, data-governance rules, intellectual-property terms or licenses for every output. It names benchmark datasets for the energy work but does not identify their contents, publication date or license. Sovereign, trustworthy, sustainable and real-world impact are goals stated by the partners, not measured outcomes. Watch for named projects, student opportunities, public datasets, model and system cards, reproducible benchmarks, open-source repositories, peer-reviewed papers, field pilots and a clear record of which institution controls each result.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Indic language
A language originating in the Indian subcontinent, spanning several language families, scripts and many regional or code-mixed forms.
OPEN GLOSSARY CARD
Distributed inference
Running a trained model by dividing its computation or data across several processors or machines.
OPEN GLOSSARY CARD
Quantum-classical workflow
A computing process that assigns selected steps to a quantum processor while classical computers prepare, control, optimize and interpret the overall job.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 2, 2026.
PUBLICATION RECEIPT: Original publication. Verified October 2, 2026 against IBM India, IIT Bombay and IISc primary materials for the current and earlier collaboration phases.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US