THE SIGNAL IN ONE SENTENCE
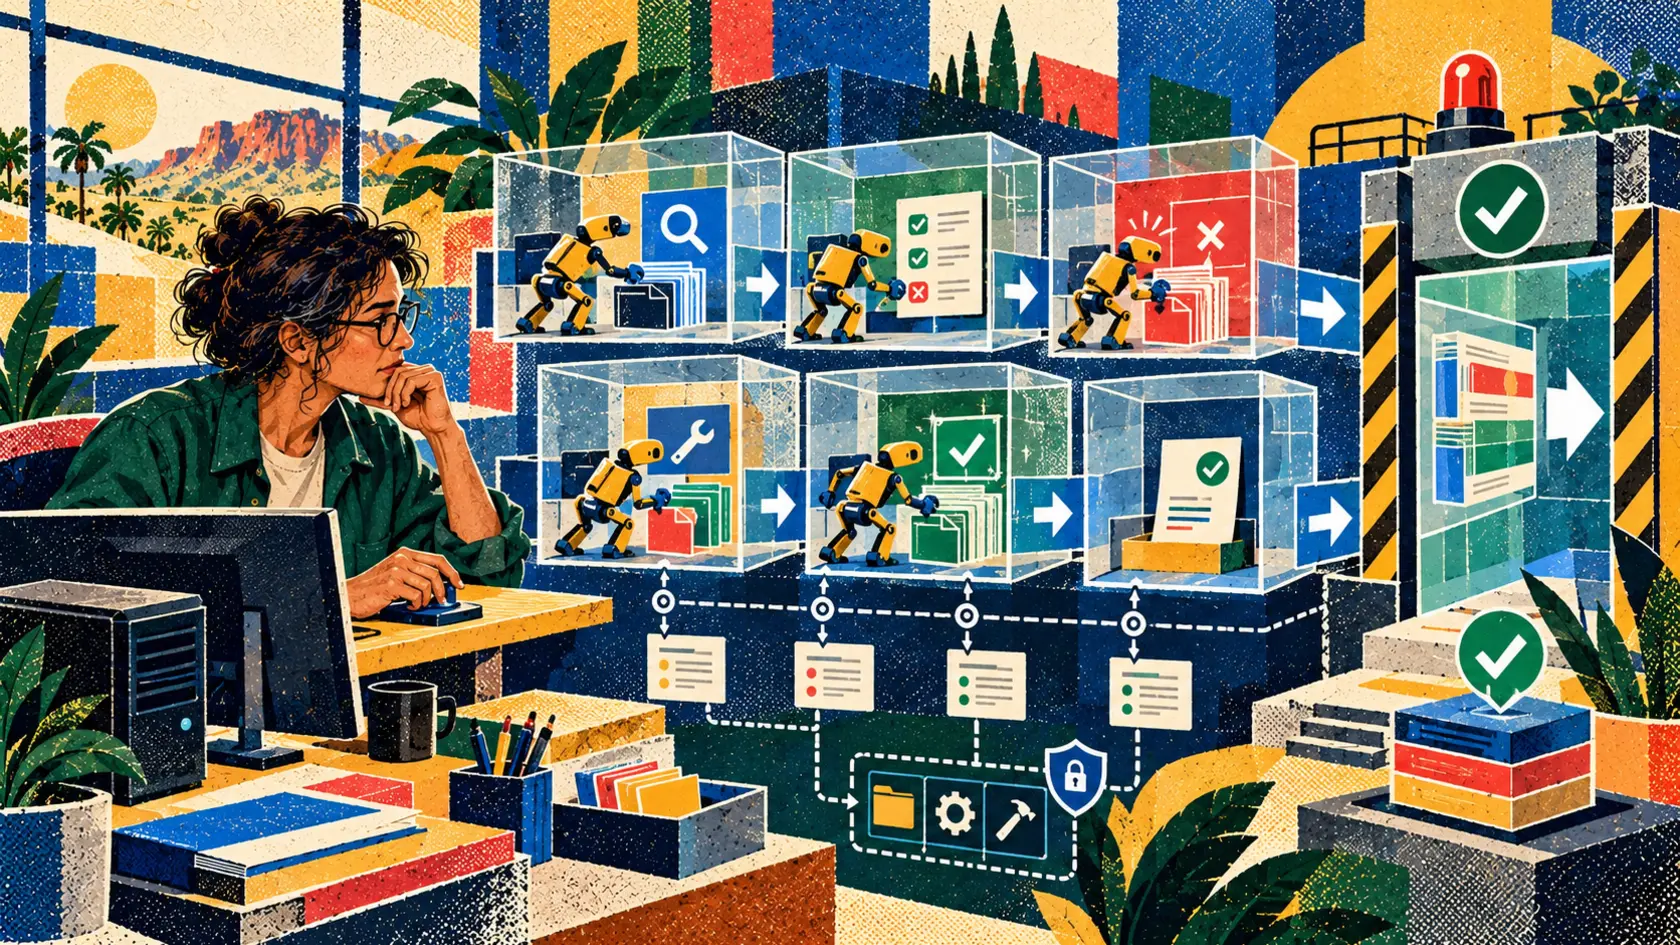
A sandbox is where software gets permission to make a mess without redecorating the entire house. JetBrains says it used millions of them to teach Mellum2.1 how to work inside a code repository. The company released the model on October 13 as the next version of Mellum2, its compact mixture-of-experts model for coding agents and fast sub-agents. The architecture remains at 12 billion total parameters with 2.5 billion active for each token. The weights carry an Apache 2.0 license and are available from JetBrains on Hugging Face. Most of the new work happened after pretraining. JetBrains says reinforcement learning became the main stage rather than a short finish. The training mix included math, competitive programming, science, tool use and software-engineering tasks. The company says it filtered open datasets for broken tests, unverifiable answers and tasks that were either trivial or impossible. Then it built thousands of environments and launched millions of sandbox runs. The goal was practical: get a small model to explore a repository, edit files and check its own changes instead of merely suggesting code in a chat window. That is a meaningful shift. A coding model becomes more valuable when it can perform the unglamorous loop around the code: find the relevant files, understand local conventions, make a bounded change, run the tests, notice the failure and try again. Most software work is not typing the clever line. It is proving that the clever line did not quietly break something three directories away. The plain signal is that sandbox-trained coding models need work logs when they leave the sandbox. Training history tells us what kind of practice a model received. A deployment receipt tells us what this particular run actually did to this particular repository. Those are different forms of evidence. JetBrains reports its largest gain in agentic coding. It says Mellum2.1 also improved in ordinary coding, competitive programming, math, tool calling and general knowledge. The launch compares the model with Mellum2, Qwen3.5-9B and Gemma 4 E4B under the same JetBrains evaluation setup. The speed story is also part of the pitch. JetBrains says that, under heavy load on one H200 accelerator, Mellum2.1 served almost twice as many tokens as Qwen3.5-9B. For a single request, it says multi-token prediction made the model about 1.6 times faster. Those figures are useful measurements inside a specific vendor test. They are not universal performance laws. Throughput changes with hardware, quantization, batch size, context length, serving software, tool latency and the shape of the task. A model can emit tokens quickly and still take the scenic route through a repository. It can also generate fewer tokens because it found the right file sooner. For an agent, the more revealing unit is often completed, verified work per minute and per dollar. That requires a task log. The first line of the log should identify the exact starting point: repository, branch, commit, dependency lock files, environment image and model version. Without that snapshot, a successful run is a campfire story. Nobody can reliably replay it after the repository changes. The second line should define the authority granted to the agent. Which directories could it read? Which files could it edit? Could it install packages, call the network, open secrets, create branches or push a commit? Was the test runner available? Did the agent have permission to rewrite the tests it was supposed to satisfy? That last question matters more than it sounds. An agent can make a red test green by fixing the implementation. It can also make the test less demanding. Both actions produce a green check. Only one may solve the problem. The work log should therefore distinguish changes to production code, tests, configuration, dependencies and generated files. It should show the commands the agent ran, their exit codes and the important output. It should preserve failed attempts instead of presenting the final patch as if it arrived immaculate on the first try. Failure history is part of the evidence. If the model misunderstood the request twice, installed an unnecessary package and then backed out the change, a reviewer should know. The final diff may be clean while the path reveals a risky habit. Repeated retries can also expose hidden cost and latency that a token-throughput chart misses. The third line should connect every claim to an artifact. If the agent says all tests passed, link the test report. If it says performance improved, attach the benchmark command, baseline, hardware and distribution of results. If it says a dependency is safe, show the version, source and security scan. If it says a bug is fixed, preserve a failing test that became green for the right reason. This is the difference between an explanation and a receipt. An explanation is what the model says happened. A receipt is evidence another person or system can inspect without trusting the model's narration. The fourth line should record what the agent could not verify. Maybe the integration tests need credentials that were intentionally unavailable. Maybe the local machine cannot reproduce a production database. Maybe one flaky test failed before and after the patch. Maybe the repository contains an operating-system-specific build the sandbox did not cover. A useful coding agent does not convert missing access into confidence. It marks the edge of the evidence. This is especially important for a self-hosted model. JetBrains presents local or operator-controlled deployment as a way to keep code and data under the team's control. That is a real advantage for proprietary repositories. The model repository documents a 131,072-token context window and vLLM serving instructions, including tool-calling configuration. A separate GGUF repository is already visible in JetBrains' current Hugging Face collection, even though the launch post still describes GGUF builds as coming soon. That small mismatch is not a scandal. It is a reminder that release artifacts move faster than announcement copy. Teams need to pin the exact weight revision, tokenizer, serving stack, quantization and tool parser they tested. Mellum2.1 uses a mixture-of-experts design with 64 experts and eight activated per token according to the model card. A quantized build or a different runtime can change speed, memory use and output behavior. The name of the model is not a complete deployment identity. Self-hosting also changes who owns the safety work. Keeping code off a third-party API reduces one data path. It does not prevent the model from reading a malicious instruction hidden in a repository, exposing a local secret to an allowed tool, deleting the wrong file or running a dangerous command. Privacy of location is not safety of operation. The sandbox should survive deployment. Run the agent in an isolated workspace. Mount only the repository and tools it needs. Keep secrets out unless a test genuinely requires them. Deny outbound network access by default. Use a disposable branch or worktree. Limit CPU, memory, time and process count. Preserve the filesystem diff and command trace after the environment is destroyed. Then put a human at the merge gate. The reviewer should see the task, scope, patch, tests, failures, dependencies, warnings and unresolved checks in one place. High-risk changes deserve additional owners. Authentication, billing, permissions, encryption, data deletion and deployment logic should not slide into production because the agent sounded calm. Mellum2.1 could be useful well below that gate. It can triage a failing test, locate likely causes, draft a narrow fix, write a regression test, explain an unfamiliar module or serve as a fast worker inside a larger agent system. A compact model with 2.5 billion active parameters may make those repeated jobs cheaper and easier to host than sending every task to a much larger model. The model's small active footprint does not make every task appropriate. A team should build its own evaluation set from real repository work. Include easy fixes, ambiguous tickets, multi-file refactors, stale documentation, dependency changes and tasks where the correct answer is to stop and ask. Keep a sealed set that was not used while tuning prompts and tools. Score more than whether the final tests passed. Measure unnecessary edits, test tampering, dependency churn, permission violations, unsupported claims, human review time, reverted changes and defects discovered later. Record the denominator. Ten beautiful examples are not a success rate if ninety awkward runs disappeared into the floorboards. Independent reproduction would make the launch claims more useful. JetBrains says it used the same evaluation setup across the compared models, which is better than comparing unrelated leaderboard numbers. The public announcement still summarizes results in charts and broad categories rather than publishing a complete task-level trace for every run. Buyers should reproduce a representative slice on their hardware, repositories and serving stack. The Apache 2.0 license gives teams wide room to download, run and adapt the weights. It also makes good evaluation easier because the model can be inspected and tested outside one hosted interface. Open access is an invitation to verify, not permission to skip verification. The best lesson in this release is not that millions of sandboxes magically produced a trustworthy programmer. It is that realistic environments matter. The same idea should govern production. Give the model a bounded room. Record what enters. Record what it touches. Keep the failures. Require evidence for the claims. Let a person open the gate only after the work can explain itself without leaning on charm. The small coding worker does not need a dramatic résumé. It needs a clean receipt.
01
WHAT ACTUALLY CHANGED
JetBrains released Mellum2.1 on October 13 under the Apache 2.0 license
The model keeps the Mellum2 architecture with 12 billion total parameters and 2.5 billion active parameters
JetBrains moved reinforcement learning from a short final stage to the main part of post-training
Training tasks covered math, competitive programming, science, tool use and software engineering
JetBrains says it filtered open tasks with broken tests, unverifiable answers or unsuitable difficulty
The company launched millions of sandbox runs across thousands of training environments
The intended agent loop covers repository exploration, file edits and checks of the resulting changes
JetBrains compared Mellum2.1 with Mellum2, Qwen3.5-9B and Gemma 4 E4B under one evaluation setup
The company reports almost twice the heavy-load token throughput of Qwen3.5-9B on one H200
The model card documents a 131,072-token context window, 64 experts and eight active experts per token
JetBrains current Hugging Face collection includes standard weights and a GGUF repository
02
WHY THIS MATTERS
A coding agent becomes useful when it can navigate, edit, test and recover rather than only autocomplete
Millions of training sandboxes do not reveal what one production run changed or failed to verify
A green test can come from a correct repair or from weakening the test itself
Failed attempts reveal risky habits, hidden cost and missing controls that the final diff may conceal
Self-hosting can keep code on controlled infrastructure without preventing unsafe commands or secret exposure
Model weights, tokenizer, quantization, runtime and tool parser together define the deployed system
Vendor throughput figures may not predict completed verified work on a buyer's repository
Open weights make independent evaluation possible, but teams still have to perform it
A human reviewer needs evidence rather than a model-written summary before approving a merge
03
WHERE IT COULD HELP
- Pin the repository commit, model revision, tokenizer, runtime and environment image for every run
- Grant read and write access only to the files and tools required by the task
- Deny network access and secrets by default inside the agent workspace
- Separate changes to production code, tests, dependencies, configuration and generated files
- Capture commands, exit codes, test reports, retries and unresolved failures
- Require a failing regression test to become green for bug-fix work
- Flag any test edits for separate review so success criteria cannot quietly move
- Preserve the complete diff and work trace after the sandbox is destroyed
- Measure human review time, reverts and later defects alongside task completion
- Build a sealed evaluation set from representative repository work
- Require additional owners for authentication, billing, permissions and deployment changes
- Keep a named human responsible for the final merge and release
KEEP A HAND ON THE WHEEL
The performance and throughput results are reported by JetBrains from its evaluation setup. The announcement does not publish a complete task-level trace, independent reproduction or production defect rate. Results will vary with repositories, prompts, tools, quantization, context, hardware and serving configuration. The October 13 blog says GGUF builds are coming soon, while JetBrains current Hugging Face collection already exposes a GGUF repository. Watch for stable release tags, complete evaluation artifacts, independent tests, task-level failure data, quantization comparisons and evidence from real code review after deployment.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Agentic AI
AI software designed to pursue a goal through several steps, including choosing actions and using approved tools with limited supervision.
OPEN GLOSSARY CARD
Mixture of experts
A model architecture with many specialist components that activates only a selected few for each input.
OPEN GLOSSARY CARD
Sandbox
A restricted space where software can act without reaching everything around it.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 13, 2026.
PUBLICATION RECEIPT: Revision 1. Published October 13, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US