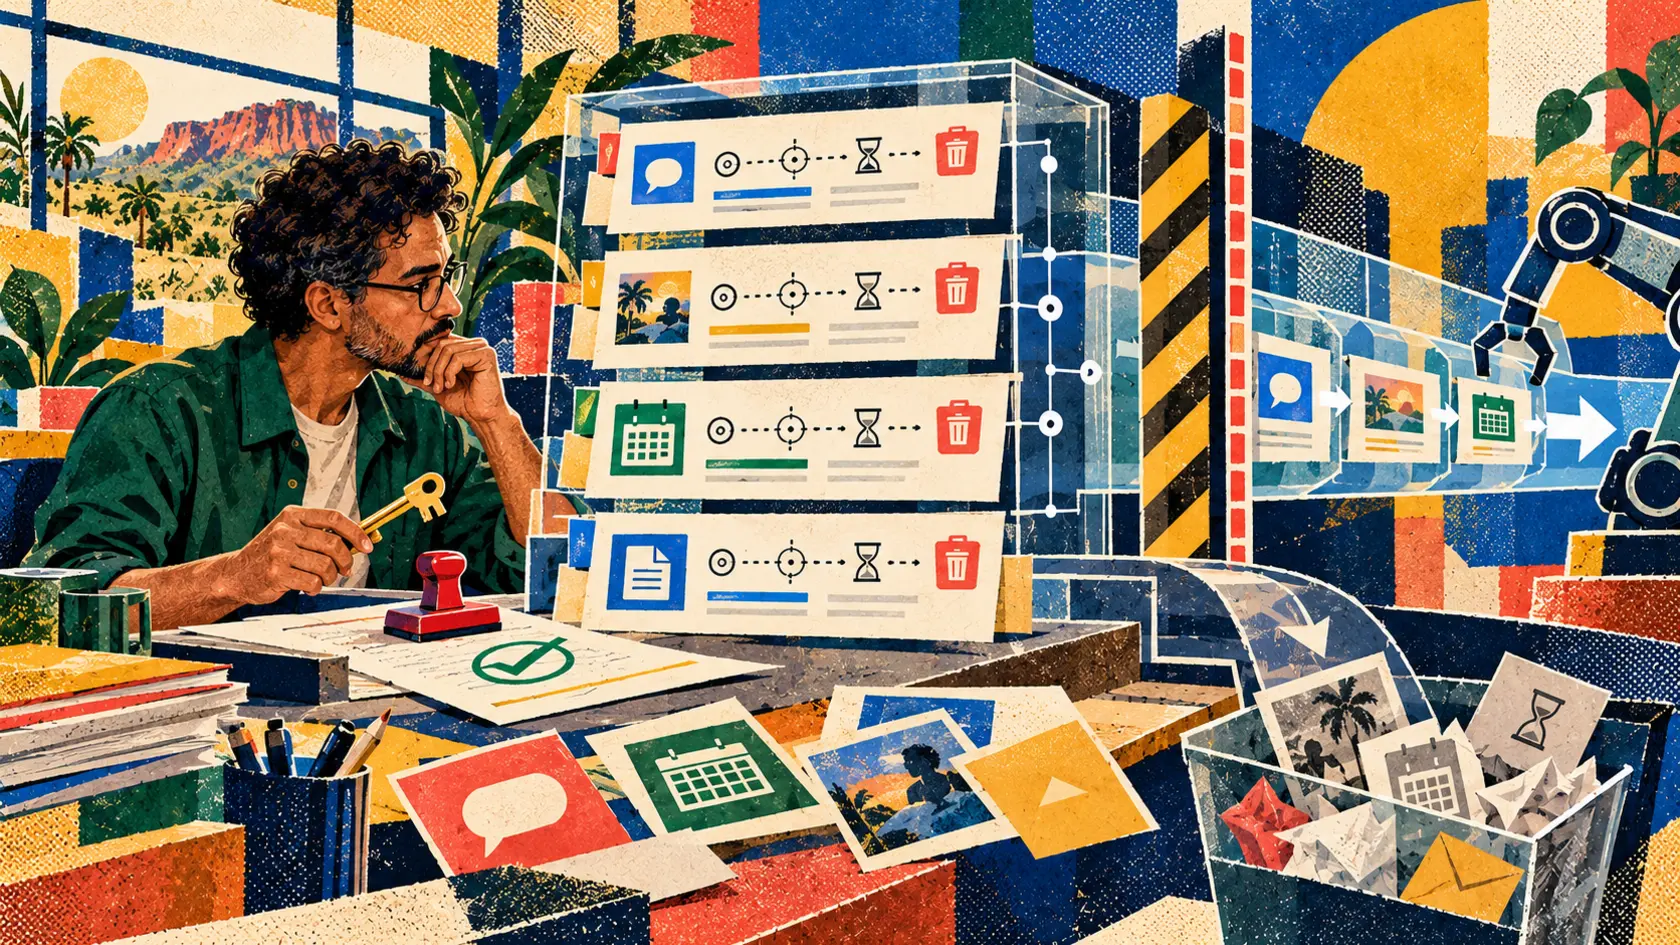
THE SIGNAL IN ONE SENTENCE
The sales pitch for a personal AI agent has always contained a contradiction. We want it to remember enough that we do not have to repeat ourselves. We also want it to forget enough that a stray confession, expired preference or bad inference does not follow us around forever. Meta has now put that contradiction near the center of a model launch. On October 12, the company introduced Muse Wonder and Muse Wonder Full, models it says are built for personal and professional agents. Muse Wonder is available through the Meta Model API and Muse Code. The Full version is available to Muse Code subscribers. Meta says the regular model will later power experiences in Muse, beginning with subscribers. The release joins two ideas Meta calls Active Memory and Active Focus. Active Memory is supposed to carry important context about a person across conversations, then retrieve the useful detail when a later task needs it. Active Focus is supposed to keep the model working through a longer task, trying another route when it hits a blocker and checking in before important actions. That combination can be genuinely useful. An agent helping with a lease could remember the move-in date and the building rules. A running planner could remember an injury and a preferred route. A coding agent could preserve a repository convention across sessions. A wedding planner could keep track of relationships that make one seating chart peaceful and another one a tiny diplomatic incident. Meta demonstrates examples involving a running plan, personalized gifts and a wedding seating chart. It also says the models can work with legal, financial and health information. The company notes that a personal agent may handle messages, calendars and private documents. That is not merely a longer chat history. It is a system deciding which facts about a person deserve to become durable operational context. The plain signal is that personal-agent memory needs a receipt. A memory receipt should answer nine small questions before a stored detail quietly becomes policy. What was stored? Where did it come from? Was it copied directly or inferred? Why was it considered useful? Which tasks may retrieve it? How confident is the system? When will it expire? Who changed it? Which actions later depended on it? Without those answers, memory looks like convenience while behaving like an invisible database. The first problem is selection. People say thousands of things that are true only for a moment. I am taking the train today is not the same kind of fact as I do not eat peanuts. My manager prefers a short weekly summary may be useful at work and wildly inappropriate in a family calendar. A frustrated sentence should not become a permanent personality label. The agent therefore needs to show when it proposes a memory instead of silently promoting conversational debris into a durable record. A useful interface might say: You mentioned that you avoid peanuts while discussing restaurant plans. Save this for dining tasks for ninety days? That little card carries more governance than a privacy policy nobody reads. It gives the person the item, source, purpose, scope and expiration at the moment the choice is understandable. The second problem is inference. Direct memories are already complicated. Derived memories are slipperier. A person might repeatedly reschedule early meetings. The system could infer that they prefer afternoons. Maybe they do. Maybe they are caring for a child this month. Maybe the morning meetings were with one particular colleague. Maybe the pattern was random. An inferred preference should be labeled as an inference, with its supporting observations and confidence. It should not be presented as something the user said. It should not be used in consequential domains simply because it was convenient once. This matters most around health, money, law, employment and relationships. An agent that infers financial stress from messages should not quietly alter which services it recommends. An agent that infers a medical condition should not reuse that conclusion in another context without explicit permission. The third problem is scope. Memory should not be one enormous bucket marked me. A detail can be valid for a project, a person, an app, a device or a period of time. The safest default is the narrowest useful scope. A codebase convention belongs to that repository. A surprise-party guest list belongs to that project. A temporary medication schedule belongs to a defined period and a clearly authorized workflow. Users should be able to see which tools and tasks can retrieve each memory. If a fact stored during a health conversation can later appear in a gift-shopping workflow, the system has not merely remembered. It has crossed a context boundary. The fourth problem is correction. Personal information changes. People move, recover, switch jobs, end relationships, change names and revise opinions. A memory system should make correction as easy as storage. Editing the record is only the beginning. The system also needs to show where the old record was used. If an obsolete address shaped a delivery plan, if an old employer appeared in a document or if an incorrect allergy changed a reservation, the correction should propagate to open work and flag completed actions that may need repair. This is where the receipt becomes an audit trail. The user should be able to open a memory and see the tasks that retrieved it, the decisions it influenced and the actions taken afterward. Otherwise deletion becomes cosmetic. The value disappears from the memory list while its consequences remain scattered across calendars, orders, drafts and messages. The fifth problem is action. Meta says Active Focus checks in before important actions. That is the right shape of a boundary, but important cannot remain an adjective the system defines for itself. Sending a draft to the user is different from sending it to a landlord. Suggesting a route is different from booking a ticket. Preparing an insurance claim is different from submitting one. Adding names to a seating-chart draft is different from emailing the table assignments. An action gate should show the intended action, recipient, cost, data being disclosed, memory items used and an undo or recovery path. The user should approve the final thing, not a vague permission granted three screens earlier. Some low-risk actions can be automated under a standing rule. Even then, the rule should have boundaries. Reschedule internal focus blocks within the same day is inspectable. Manage my calendar is a blank cheque wearing sensible shoes. The sixth problem is retention. Useful memory does not need to mean permanent memory. Every saved item should have an expiration or review date. The system can ask whether a frequently used preference should remain. It can archive an inactive project. It can delete sensitive source material after extracting a narrow fact the user chose to keep. Deletion should cover copies, indexes, embeddings and caches used to retrieve the memory. A button that hides the item from the interface while leaving it available to the retrieval system is not deletion. Export matters too. If a person leaves the service, they should be able to take a readable record of what the agent stored, why it stored it and how it was used. A personal history should not become the fee for switching providers. The seventh problem is testing. Meta says Muse Wonder and Muse Wonder Full achieve state-of-the-art results across benchmarks for personal and professional agents, memory and coding. It points to evaluations for domain expertise, sustained work and software tasks. It also says the models are trained to handle private information carefully and resist adversarial instructions. Those are company claims from a launch package. The release links an evaluation report for model results, but Meta says a full report with additional safety evaluations will arrive later. The company has not yet provided the public with long-term, independent evidence that the memory system consistently stores the right facts, refuses the wrong ones, obeys deletion, resists cross-context leakage and recovers cleanly from corrections. That missing evidence does not prove the system fails. It defines what a responsible buyer or developer should test before trusting it with a life. A useful memory evaluation should include false memories, stale memories, poisoned source material, conflicting instructions, shared devices, account compromise, ambiguous identity, deliberate deletion and repeated attempts by one tool to extract context belonging to another. It should report mistakes by type. Failing to recall a restaurant preference is annoying. Revealing a private health detail in the wrong chat is a different class of failure. One average score cannot flatten those consequences into a cheerful bar chart. The system should also be tested over time. Many memory benchmarks ask whether the model can retrieve an earlier fact. A personal agent faces a harder question: can it know that the fact no longer applies? Can it distinguish a direct statement from an inference? Can it remember the correction instead of the catchy first version? Can it explain why the memory was relevant before using it? There is a practical deployment path here. Start with bounded projects, not a complete autobiography. Let the agent remember repository conventions inside one codebase, preferences inside one travel plan or constraints inside one event. Require explicit approval for durable sensitive memories. Give every memory a visible source and expiry. Keep action permission separate from retrieval permission. Review the audit trail after real tasks. Teams using Muse Wonder through the Model API can build this layer even if the model does not provide the complete user experience by itself. They can keep memory in a system they control, store provenance next to each item, limit retrieval by task and log the model, prompt, tools and records used for an action. They should also make the off switch boring and reliable. A user needs one place to pause memory, review pending memory proposals, delete stored items, revoke tool access and stop outbound actions. The controls should work even when the model is unavailable or misbehaving. The system supervising memory cannot depend entirely on the system being supervised. Meta trained the models at its gigawatt-scale Prometheus data center. That detail tells us something about the ambition behind the release. It does not tell us whether the resulting personal memory is correct, appropriately scoped or easy to govern. The most valuable personal agent will not be the one that remembers the most. It will be the one that can show its memory, admit uncertainty, accept a correction, forget on command and prove which action came from which remembered fact. That sounds less magical than personal superintelligence. Good. A receipt is supposed to make the magic accountable.
01
WHAT ACTUALLY CHANGED
Meta introduced Muse Wonder and Muse Wonder Full on October 12
Muse Wonder is available through the Meta Model API and Muse Code
Muse Wonder Full is available to Muse Code subscribers
Meta says Muse Wonder will later reach Muse experiences, beginning with subscribers
The models combine Active Memory for cross-conversation context with Active Focus for sustained work
Meta reports leading results across its evaluation suite for personal agents, professional agents, memory and coding
The company demonstrates tasks involving a running plan, personalized gifts, a wedding seating chart and coding
Meta says personal agents may handle messages, calendars and private documents
The launch says a full report with additional safety evaluations will be published later
Muse Wonder and Muse Wonder Full were trained at Meta's gigawatt-scale Prometheus data center
02
WHY THIS MATTERS
Cross-conversation memory can reduce repetition and help an agent continue long projects
The system must decide which details become durable, creating a hidden policy layer if users cannot inspect it
An inferred preference is not the same as a statement the user made
Memories from health, financial, legal or personal contexts can cause serious harm if retrieved in the wrong task
A stale fact can keep shaping drafts, recommendations and actions after a user corrects it
Deleting a visible item is insufficient if copies, indexes, embeddings or consequences remain
Permission to retrieve a memory should not automatically grant permission to act on it
Company benchmarks and demonstrations do not replace independent, long-term testing of leakage, correction and deletion
A portable memory record can prevent personal context from becoming a switching cost
03
WHERE IT COULD HELP
- Ask before turning a conversational detail into durable memory
- Show the source, purpose, scope, confidence and expiration for every stored item
- Label inferred preferences separately from direct user statements
- Limit retrieval to the narrowest relevant project, app, person or time period
- Require fresh approval before external messages, purchases, submissions or sensitive disclosures
- Show which memories were used in each proposed action
- Propagate corrections to open tasks and flag completed actions that may need repair
- Delete retrieval indexes and cached copies when the underlying memory is deleted
- Export a readable memory and action history when a user changes services
- Test stale, false, conflicting and poisoned memories before wider deployment
- Report severe privacy failures separately from ordinary retrieval mistakes
- Keep pause, delete and permission controls outside the model being supervised
KEEP A HAND ON THE WHEEL
Meta supports the release with company-run benchmarks and demonstrations. The launch does not establish independent long-term reliability for memory selection, correction, deletion, context separation or action safety. Meta says a full report with additional safety evaluations will be available later. Watch for the model and system cards, independent tests, retention controls, memory export, per-item provenance, cross-app access rules, deletion verification, action approval design and incident reporting from real deployments.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Context window
The amount of input and generated material a model can consider during one call.
OPEN GLOSSARY CARD
Data retention
The rules and time periods that determine how long information, copies, logs, and backups are kept before deletion.
OPEN GLOSSARY CARD
Context window
The amount of information a model can actively consider at one time.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 13, 2026.
PUBLICATION RECEIPT: Revision 1. Published October 13, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US