THE SIGNAL IN ONE SENTENCE
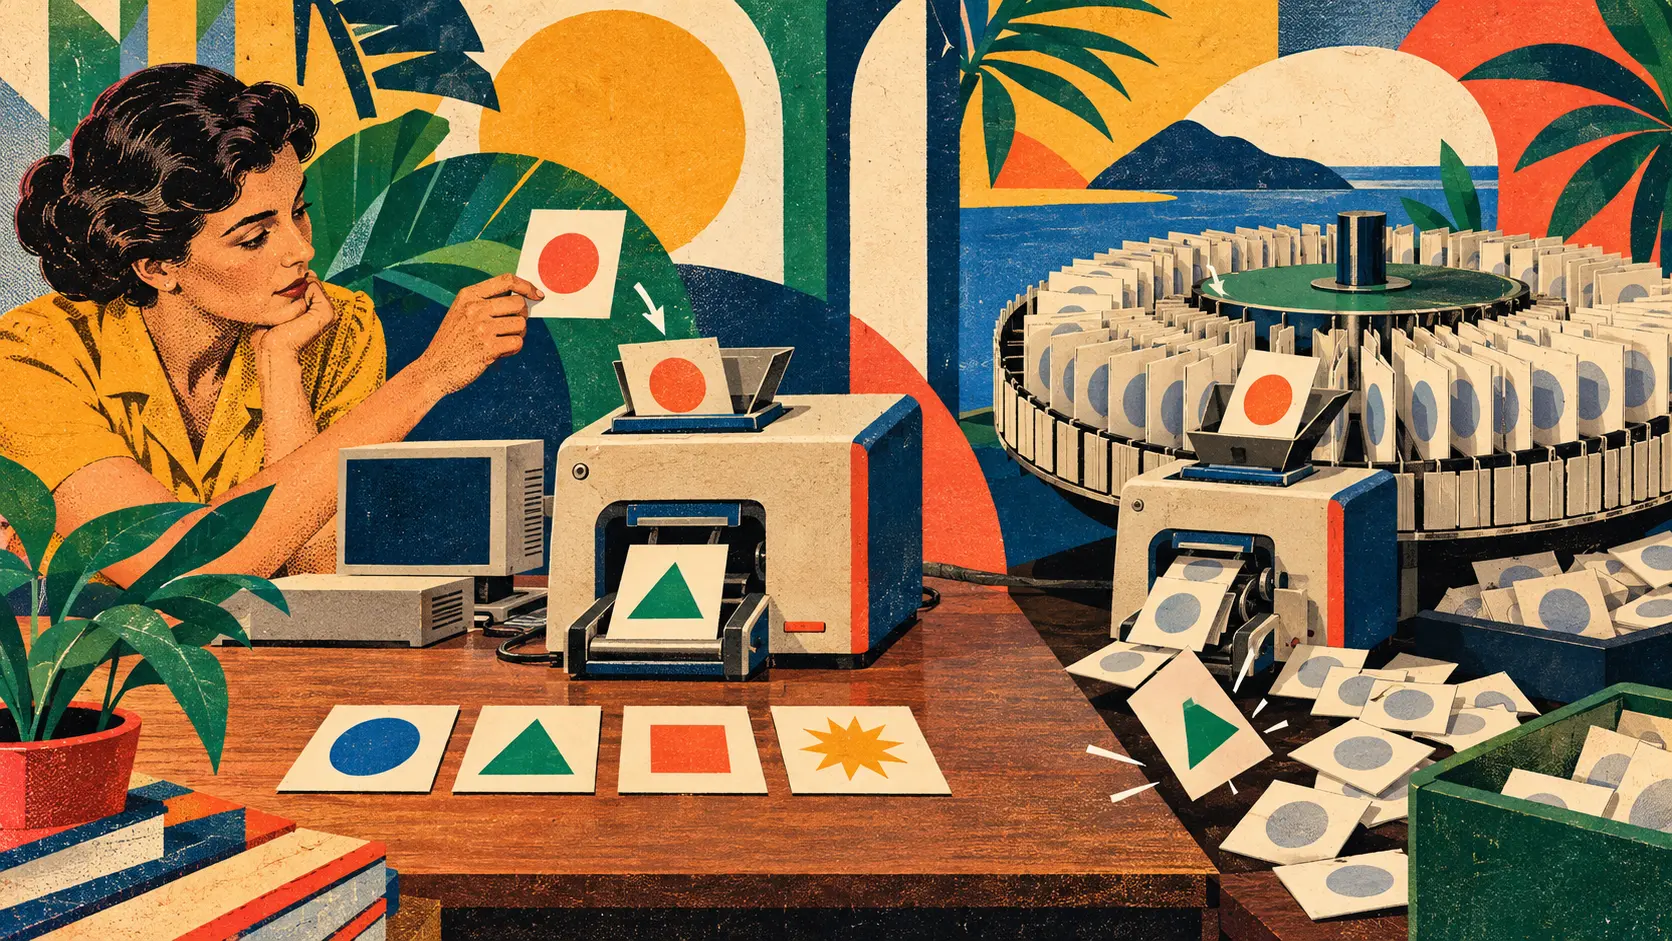
Supersonic Labs, a small Brazilian AI company, has released Julia 1, a compact model designed to choose among options rather than write an answer from scratch. Give it some context, a question and between two and twenty possible answers. It returns a score for each option in the same order. That sounds modest next to models that produce essays, code and video, but modest can be useful. Many real systems do not need a tiny novelist. They need a sorter: send this request to billing or fraud, classify this support message, pick the next workflow, or decide that none of the supplied actions is safe enough. Julia 1 has 144.3 million parameters, uses mmBERT-small as its base and ships as roughly 550.5 MiB of FP32 weights. Supersonic Labs says it runs on CPUs, including an Apple M4 laptop, an Intel i5 computer and a Samsung tablet. The company published the weights and inference code under Apache 2.0. It did not publish its private training pipeline. The attraction is straightforward. A small decision layer can run near the data, avoid a round trip to a large hosted model and return a stable set of scores instead of a fresh paragraph every time. It can also be cheap enough to place inside an application that already has rules, retrieval and human review. Julia 1 is not a general assistant. It does not generate missing knowledge, invent an extra option or perform open-ended multi-step reasoning. If the correct answer is absent from the menu, the model cannot rescue the question. If the menu is badly worded, the scores can move. That boundary is a feature when teams respect it and a trap when they pretend a score is judgment. The company ran a series of its own evaluations from September 24 through 26. In a 2,000-example typed-decision suite, the first reported GPU run scored 1,463 correct, or 73.15 percent. A later CPU run scored 1,451, or 72.55 percent. On three small classification samples, the CPU run reported 94 percent on AG News, 86 percent on DAIR Emotion and 60 percent on a Banking77 pilot. The banking result is the useful splinter. Banking77 is a customer-service intent dataset with many closely related labels. Julia 1 accepts at most twenty options in a native request, so the company used a router to narrow 72 labels to a top-sixteen shortlist before final scoring. That helper can discard the correct label before Julia 1 sees it. The model card explicitly warns that the final probabilities cover only the finalists, not the full label universe. In the GPU table, the banking pilot scored 64 percent against a listed reference of 87 percent. On CPU it scored 60 percent, with three abstentions across one hundred items. The tiny samples do not establish a production ranking, and the reference systems were not independently rerun under one neutral protocol. Still, the pattern is instructive. Julia 1 looked comfortable when the menu was short and distinct. It became much less convincing when the labels were crowded and a separate stage controlled admission to the menu. That is not merely a benchmark footnote. It is the architecture. A two-stage classifier can fail twice: the router can remove the answer, then the decision model can rank the survivors incorrectly. The final score may look tidy even though the right choice is no longer in the room. A system should therefore log shortlist recall, not only final accuracy. Ask how often the correct label survived the first cut. If it did not, no amount of confidence calibration in the second stage can fix the decision. The company also tested MASSIVE, a multilingual intent dataset, and reported 110,573 correct predictions across 154,648 examples, or 71.50 percent macro accuracy across 52 locales. The listed locale results include 86.75 percent for United States English and 86.25 percent for Portugal Portuguese. That is encouraging evidence of breadth, but Portugal Portuguese is not a substitute for Brazilian Portuguese. Supersonic Labs says Brazilian Portuguese and some additional tasks remain for future evaluation. A model built by a Brazilian lab still needs Brazilian language tests before a Brazilian bank, public service or retailer should assume local wording will behave well. Hardware results require similar care. On an Apple M4, the company reports a 33.15 millisecond median for single decisions and 51.2 decisions per second in batches of sixteen. On a Samsung SM-X510 tablet it reports about 203 milliseconds per decision and roughly 393.1 MB of peak resident memory, with the weights memory-mapped. Those numbers show that compact local inference is plausible. They are not one controlled device race. The Intel i5 Banking77 run had a 3,713.54 millisecond median while simpler tasks stayed under 300 milliseconds. The crowded banking workflow does more work because it evaluates a 72-label space through a shortlist. Workload shape, sequence length, option count, batching, runtime and thermal limits belong beside every speed number. The model card says the runtime can accept up to 8,192 combined tokens, but the historical accuracy results used a 1,024-token limit. An 8K smoke test passed. That proves the path can run, not that task accuracy remains intact across eight thousand tokens. The release contains another excellent warning for implementers. An earlier named-question interface had a bug that discarded Boolean option descriptions. The company fixed it and documented that descriptions materially affected the result. This is why a decision model needs interface tests as much as model tests. The system is sensitive to option wording, order, evidence and encoding. Changing a label from a terse code to a clear action description can change performance. A wrapper that silently drops the description can turn a good model into a bad product while every weight hash remains correct. The released CPU reproduction also showed smaller differences from the earlier GPU run that the company has not isolated. That is not scandalous. It is precisely the kind of detail an open model card should expose. It means adopters should rerun their own tasks on their own processor and pin the model, tokenizer, code, precision and prompt format. Supersonic Labs says total cloud GPU spending for the project was about R$540, or US$104.08. That figure is company-reported and does not include salaries, earlier research, local computing, data work or the full cost of making the company. It does suggest that a narrow model can be built without a frontier laboratory budget. The company also lists a planned API price of US$0.025 per million input tokens and zero charge for output because the model does not generate tokens. Access was not open in the reviewed materials, so this is a proposed price, not a service record. There is no published uptime, capacity, retention policy, regional availability or service agreement to evaluate yet. The practical use for Julia 1 is as a bounded component with visible exits. Give it a small, mutually exclusive set of actions. Include a none-of-the-above or human-review path. Calibrate thresholds on local data. Measure accuracy separately for each language, device and slice of users. Record whether the correct answer reached the shortlist. If the decision affects money, employment, health, benefits or access to a service, require human review and a route for appeal. A probability is not certainty, fairness or permission. The plain signal is that Julia 1 makes a credible case for small decision models on ordinary hardware, and its weakest public result explains where that case can break. The model can sort a short menu efficiently. A crowded menu needs a router, and the router can throw away the answer before the model begins. Edge AI becomes useful when teams keep the task narrow, test the whole pipeline and treat abstention as part of the product. The little machine does not need to know everything. It does need an honest menu.
01
WHAT ACTUALLY CHANGED
Supersonic Labs released Julia 1 as a compact model for scoring supplied choices rather than generating prose.
The model has 144.3 million parameters and is based on mmBERT-small.
A native request accepts context, a question and between two and twenty possible answers.
The result preserves option order and returns a score for each supplied choice.
The release includes roughly 550.5 MiB of FP32 weights and inference code under Apache 2.0.
The private training pipeline is not included in the public artifact.
A company-run GPU evaluation scored 1,463 of 2,000 typed decisions, or 73.15 percent.
A later CPU run scored 1,451 of 2,000 typed decisions, or 72.55 percent.
The CPU run reported 94 percent on an AG News sample and 86 percent on a DAIR Emotion sample.
The same CPU run reported 60 percent on a one-hundred-item Banking77 pilot with three abstentions.
The GPU table reported 64 percent for the Banking77 pilot against a listed reference of 87 percent.
Banking77 used a router to narrow 72 labels to a top-sixteen shortlist because the model natively accepts no more than twenty options.
The model card warns that the router can remove the correct answer before final scoring.
Final probabilities in the routed workflow cover only the shortlisted labels, not the complete label set.
A company-run MASSIVE evaluation reported 71.50 percent macro accuracy across 52 locales.
The listed results include 86.75 percent for en-US and 86.25 percent for pt-PT.
Brazilian Portuguese evaluation remains future work in the reviewed materials.
The company demonstrated CPU inference on Apple, Intel and Samsung hardware.
Historical accuracy evaluations used a 1,024-token limit even though an 8,192-token smoke test passed.
Supersonic Labs documented and fixed an interface bug that had discarded Boolean option descriptions.
02
WHY THIS MATTERS
Many production systems need a bounded choice among actions rather than open-ended text generation.
A compact model can keep data on a local device and reduce dependence on a hosted inference service.
Stable option scores can be easier to audit than free-form text when the action set is fixed.
The model cannot choose an answer that was never included in its menu.
A two-stage classifier can fail when the router drops the correct label before final scoring.
Final confidence among shortlisted labels can look strong even when the globally correct label is absent.
Shortlist recall is therefore a separate production metric from final classification accuracy.
A twenty-option native limit can be enough for a narrow workflow and awkward for a large intent catalog.
Option wording, order, descriptions and evidence can change the result.
A wrapper bug can alter model behavior even when the weights and runtime are unchanged.
CPU availability does not guarantee equal latency across tasks, devices or option counts.
A long-context smoke test does not establish accuracy at the advertised maximum context.
Portugal Portuguese results should not be treated as validation for Brazilian Portuguese.
Company-run samples are useful release evidence but not independent production validation.
Open weights and code make inspection possible without exposing the private training pipeline.
A small reported cloud bill does not represent total research, labor, data and operating cost.
A proposed API price does not establish availability, privacy, reliability or support.
Abstention is valuable when the evidence or menu cannot support a safe choice.
High-consequence decisions need human review even when a model score is calibrated.
The Banking77 weakness offers a practical design lesson rather than a reason to dismiss compact models.
03
WHERE IT COULD HELP
- Use the model for narrow routing tasks with a small and clearly distinct set of actions.
- Add an explicit none-of-the-above or human-review option to every consequential workflow.
- Measure whether the correct label survives the shortlist before measuring final accuracy.
- Tune the router and decision model as separate components with separate failure logs.
- Keep option descriptions complete, stable and versioned across training and production.
- Test option order changes to reveal position sensitivity.
- Pin the model, tokenizer, inference code, precision and prompt format for every evaluation.
- Run the full task on the exact CPU or tablet intended for deployment.
- Report median, tail latency, memory, power and thermal behavior for each workload.
- Benchmark short and long inputs separately rather than quoting one maximum context number.
- Evaluate Brazilian Portuguese with local vocabulary, accents and service categories before a Brazilian launch.
- Break accuracy out by language, intent, device, user group and confidence band.
- Calibrate thresholds on an untouched local validation set.
- Route low-margin or unfamiliar examples to a person instead of forcing a label.
- Monitor distribution drift when new products, policies or customer language appear.
- Preserve the original menu, scores, shortlist and model version in an audit log.
- Test what happens when the correct action is deliberately omitted from the menu.
- Compare the compact model with rules, embeddings and a larger model on the same task.
- Calculate total cost per accepted decision, including review and correction.
- Require human review and an appeal path for decisions involving rights, money, health or access.
KEEP A HAND ON THE WHEEL
Supersonic Labs verifies that Julia 1 is a 144.3-million-parameter decision model based on mmBERT-small, accepts two to twenty supplied options, runs on CPUs and is released with weights and inference code under Apache 2.0. The launch page and model card publish company-run typed-decision, AG News, DAIR Emotion, Banking77 and MASSIVE results. They also document the top-sixteen router used for the 72-label Banking77 pilot, the risk that routing removes the correct label, hardware measurements, a fixed option-description bug and smaller CPU-versus-GPU differences that remain unexplained. The reviewed material does not provide an independent reproduction, production deployment study, formal abstention analysis, calibration report, fairness audit, Brazilian Portuguese result, service agreement or open API access. The 8,192-token path has a smoke test, while historical accuracy results used 1,024 tokens. Watch for independent task reproductions, Brazilian Portuguese evaluation, global calibration for routed label sets, larger Banking77 runs, stable cross-device results, published energy measurements and evidence that the planned API meets its availability and privacy promises.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 28, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 28, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US