THE SIGNAL IN ONE SENTENCE
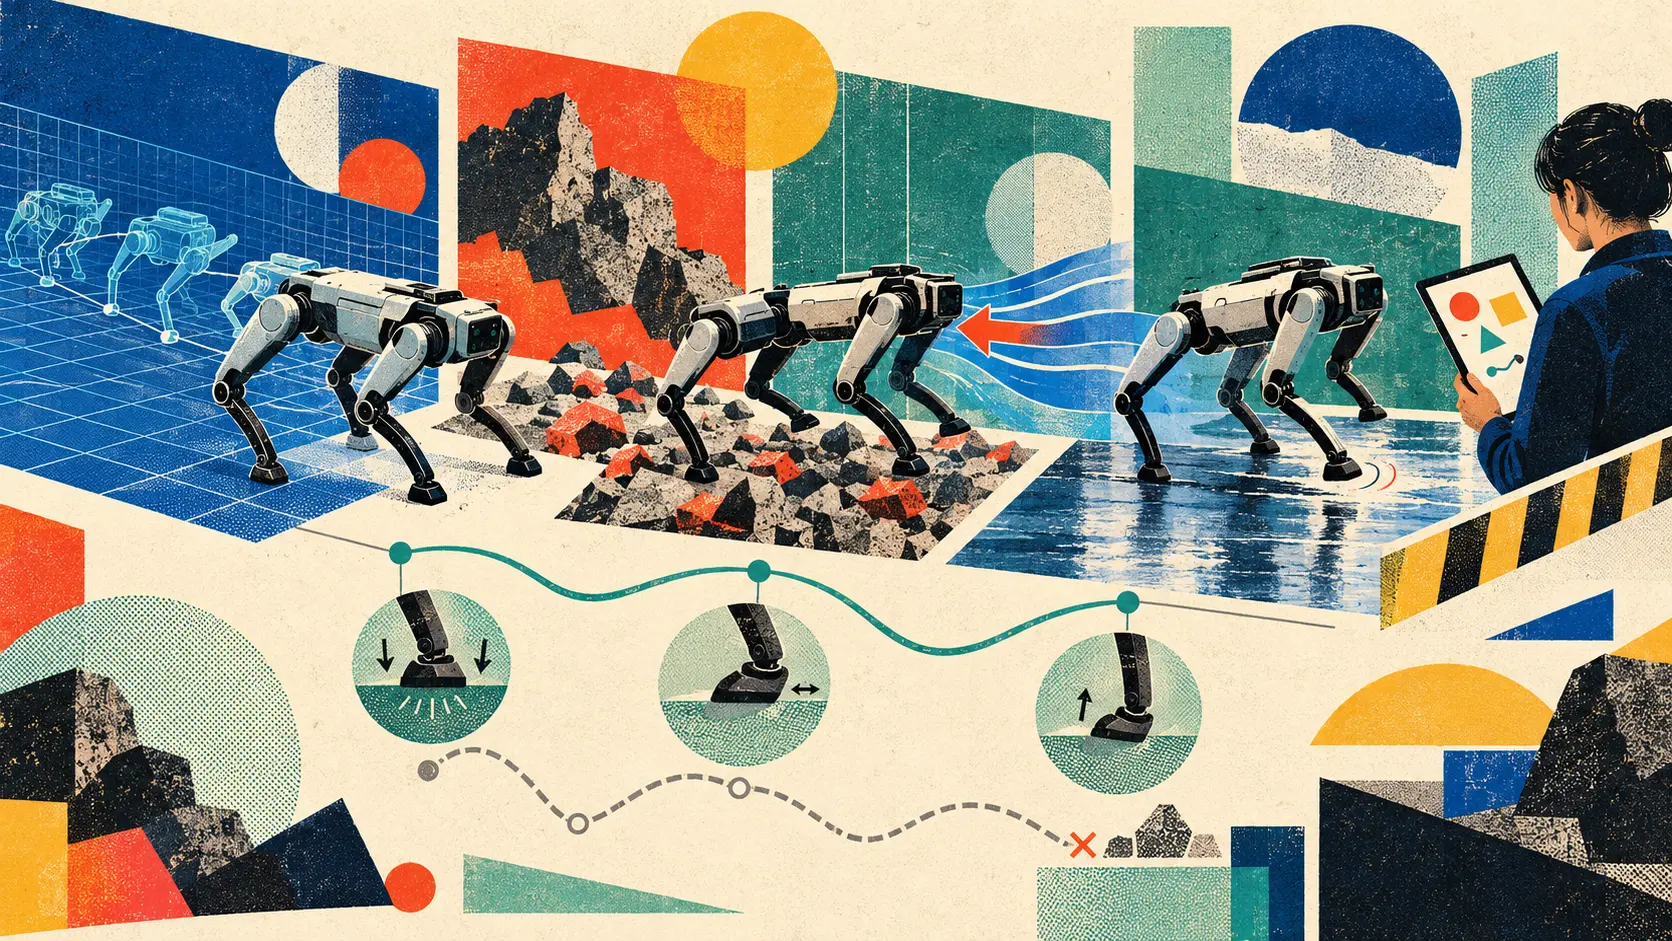
A robot foot does not care that the training graph looked smooth. It cares whether the ground grips, slides, separates or changes its mind halfway through a step. That messy boundary is the focus of a new robotics preprint from Gijeong Kim, Seungbin Oh, Dongyun Kang and Hae-Won Park at the Korea Advanced Institute of Science and Technology in Daejeon, South Korea. The team reports training trotting and pacing policies from 100,000 simulated control steps in 108 seconds on a desktop computer, then transferring them to a 45 kilogram quadruped without fine-tuning. That is the number that will travel. The more useful story is what the researchers changed underneath it. Many robot-learning systems use a simulated world to calculate how a small change in an action changes the final result. That derivative, or gradient, tells the optimizer which direction to move. Contact makes this awkward. A foot can be separated from the floor, clamped to it or sliding across it. The exact contact sensitivity can describe changes inside the current mode. A clamped foot is treated as staying clamped. A separated foot is treated as staying separated. At the boundary between modes, the gradient can jump or provide no first-order direction toward the switch the robot actually needs. The KAIST method keeps the hard-contact simulation for the forward rollout. The robot still experiences the realized contact mode in the simulated motion. During the backward pass, where the system calculates the learning direction, the researchers relax the full frictional contact condition along a smooth central path. That creates gradient information toward separating, clamping and sliding without making the forward rollout itself soft. Plainly: the robot lives in the hard world, but the teacher draws a smoother route through the lesson. The distinction matters because some contact-smoothing methods change the forward physics as well as the gradient. That can make learning easier while making the training world less like the deployed one. Here, the relaxation is used only to calculate the direction of improvement. The team tested the gradient in two settings. The first was policy learning through backpropagation through time, or BPTT. Each update used one rollout from a single simulation environment. The trotting and pacing policies ran for 5,000 iterations of 20 control steps each, producing the 100,000-sample total and 108-second training time. The machine was not a data-center cluster. The paper specifies a 10-core Intel Core i9-10900K desktop CPU. A gait-free policy trained for 160,000 steps in 172 seconds. It was designed for low-friction locomotion without a prescribed gait. The second setting was contact-implicit trajectory optimization, where the optimizer chooses contact timing and footholds rather than following a preplanned contact sequence. In simulation, the proposed gradient found lower-cost motions for translation and rotation tasks and recovered from stronger unmodeled pulls than the compared exact and normal-only relaxed gradients. The authors report an average simulated pull limit of 272 newtons, compared with 81 newtons for the exact gradient and 107 newtons for the Signorini-relaxed version. The success threshold required at least 90 percent of perturbed pull directions to finish without failure. That result belongs in the simulation column. It was not the hardware push test. On hardware, the researchers deployed the learned policies without fine-tuning. The trotting and pacing policies tracked commands on a treadmill. A trotting policy crossed scattered debris. In 14 external-push trials, lateral tracking error rose during the push and moved back toward zero afterward. For the slippery-ground demonstration, a policy trained across friction coefficients from 0.4 to 1.0 was tested on a boric-acid-coated surface measured near 0.25. The robot slipped, recovered and continued walking without falling in the reported trial. Those are meaningful demonstrations. They are not a universal terrain license. The paper does not establish performance across rain, mud, loose gravel, stairs, compliant surfaces, side slopes, damaged feet or a range of robot bodies. The authors list non-point feet, uneven terrain and arbitrary-shape contacts as future work. Their learning rollouts span 0.5 seconds, and they propose adding a learned terminal value for longer horizons. Even the comparison with model-free reinforcement learning needs a careful label. The study used the same observation and action spaces, simulator, low-level control law and per-step cost for its BPTT and PPO tests. In the authors' setup, BPTT learned the trot with one environment and roughly 100,000 samples. PPO first learned it at 128 environments and roughly 10 million samples. The one-environment BPTT case was tested over 20 seeds. Other configurations used five. But the algorithms do not solve the optimization problem in exactly the same way. BPTT differentiates an undiscounted truncated cost without a terminal value or critic. PPO uses a learned critic and discounted returns. The reported efficiency gap is strong evidence inside this task and implementation, not proof that differentiable simulation will beat model-free learning across robotics. This is where the two-minute headline needs a receipt. First, define the sample. A simulated control step is not the same thing as an image, a human demonstration or a hardware trial. Report the control frequency, horizon, number of environments, updates, total simulated time and whether resets or failed rollouts count. Second, report the clock honestly. Name the CPU, simulator, compilation time, initialization, policy architecture and any preprocessing excluded from the 108 seconds. Separate training wall time from the engineering time needed to build the simulator and tune the objective. Third, preserve the distribution. List every velocity command, friction range, mass variation, delay, disturbance and sensor-noise setting used in training. Then mark each hardware test as inside or outside that envelope. The low-friction test is useful precisely because the measured coefficient was below the training range. Fourth, count failures, not just successful video. For each terrain, publish the number of trials, falls, emergency stops, recoveries and incomplete runs. Record tracking error, time to stabilize, foot slip, body tilt, joint limits, actuator temperature, energy use and peak contact load. The paper gives a 14-trial push trace and a detailed low-friction episode. A deployment decision needs repeated trials across operators, surfaces, robot units and days. Fifth, move the shortcut between bodies. Repeat training on different masses, leg geometries, feet, actuator limits and contact solvers. A gradient that works beautifully for point-contact assumptions may behave differently when a broad rubber foot bends, catches an edge or contacts two surfaces at once. Sixth, test the fallback. A fast learner still needs a safe controller when state estimation drifts, a motor saturates or the ground falls outside the model. Define the stop condition, stability monitor, recovery posture, human exclusion zone and emergency control before adding harder terrain. Finally, make reproduction possible. The project page provides the paper, figures and demonstration media. At verification time, it did not present a public code or checkpoint link. Releasing the contact-gradient implementation, simulator configuration, policy checkpoints, random seeds and full trial logs would let other laboratories test whether the shortcut survives their hardware. The contribution here is not merely that a robot learned fast. It is that the researchers found a way to provide useful learning directions across contact-mode changes while keeping the simulated forward motion hard. The method produced unusually sample-efficient learning in their setup and crossed the sim-to-real boundary on a full-size quadruped. That deserves attention. It also deserves terrain labels, trial counts and a failure ledger. Two minutes can teach a policy in one carefully defined world. Trust begins when the team shows what happens on the next patch of ground.
01
WHAT ACTUALLY CHANGED
KAIST researchers proposed a backward-only relaxation of the complete frictional contact condition
The forward rollout keeps hard contact while the backward pass gains smooth directions across separation, clamping and sliding
Trotting and pacing policies trained from 100,000 control steps in 108 seconds on a 10-core desktop CPU
The policies transferred to a 45 kilogram quadruped without hardware fine-tuning
Hardware demonstrations included treadmill locomotion, debris, 14 push trials and a low-friction surface outside the training range
Simulated contact-implicit optimization recovered from stronger unmodeled pulls than two compared gradients
02
WHY THIS MATTERS
Contact-mode transitions can make an exact local gradient unhelpful exactly when a foot must lift or slide
A backward-only relaxation can improve the learning signal without softening the realized forward motion
Training on one desktop in minutes could make locomotion research more accessible and iterative
Direct hardware transfer is more informative than simulation performance alone
A small set of successful surfaces cannot establish broad terrain robustness or safe operation near people
The dramatic wall-clock claim is useful only when hardware, sample definitions, seeds and excluded work remain visible
03
WHERE IT COULD HELP
- Record the simulator version, CPU, policy architecture, control rate and every component included in wall-clock time
- Define a sample precisely and count resets, failed rollouts and discarded runs
- Publish training ranges for friction, commands, mass, delay, disturbances and sensor noise
- Label every hardware test as inside or outside the training distribution
- Report falls, emergency stops, recoveries and incomplete trials for every terrain
- Measure tracking error, recovery time, slip, body tilt, joint limits, contact load, energy and actuator temperature
- Repeat across robot units, seeds, foot shapes, contact solvers and terrain materials
- Test rain, loose gravel, slopes, stairs, compliant ground and mixed-contact edges
- Define a stability monitor, recovery posture, emergency stop and human exclusion zone
- Release code, checkpoints, random seeds and complete trial logs for independent reproduction
KEEP A HAND ON THE WHEEL
This is an author-reported preprint submitted to Transactions on Robotics, not an independent reproduction or a general safety certification. The hardware evidence comes from one 45 kilogram quadruped and selected treadmill, debris, push and low-friction tests. The 272-newton pull result is from simulated contact-implicit model predictive control, not the hardware demonstration. The paper identifies non-point feet, uneven terrain, arbitrary-shape contacts and longer horizons as future work. The project page offered the paper and demonstration media at verification time but no public code or policy-checkpoint link. Watch for independent reproduction, broader terrain distributions, full failure counts, multiple robot bodies and complete released artifacts.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 27, 2026.
PUBLICATION RECEIPT: All training, hardware and trajectory-optimization results are attributed to the October 26 preprint and author project page. The new-ground receipt and deployment controls are Plain Signal analysis. Simulated pull tolerance is not presented as a hardware result or general safety claim.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US