THE SIGNAL IN ONE SENTENCE
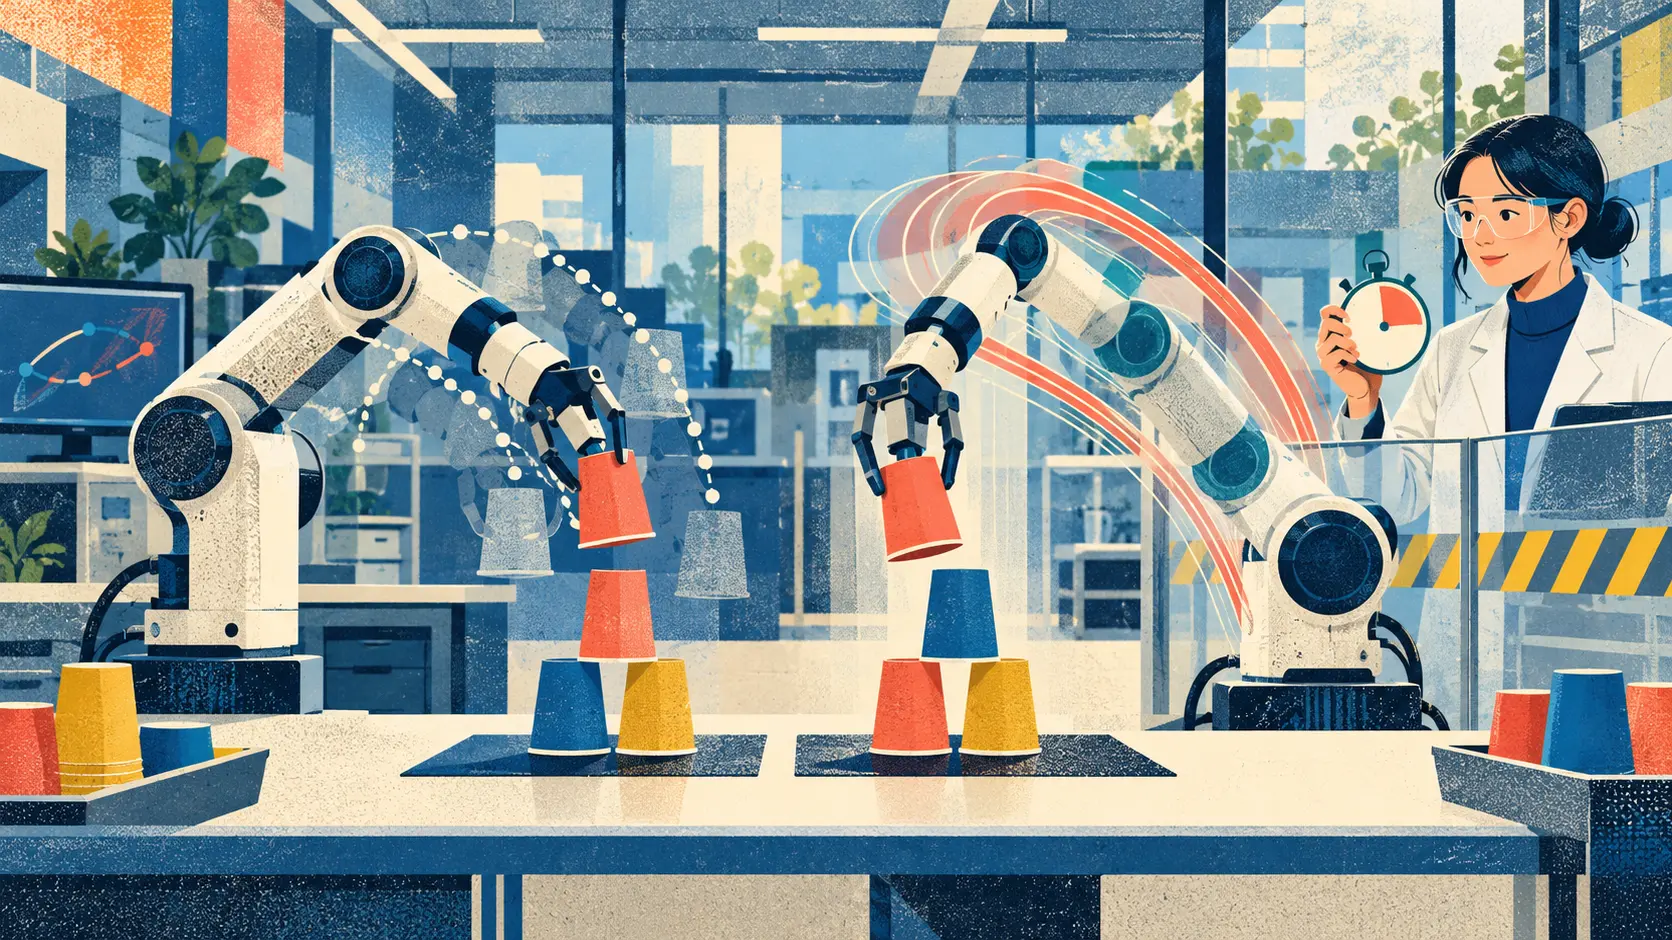
A robot can learn the shape of a task and still inherit the wrong clock. That clock often belongs to whoever collected the demonstration. A cautious teleoperator pauses before a grasp. A handheld demonstrator moves directly. A novice hesitates. The resulting training set quietly mixes what the robot should do with how quickly one particular person happened to do it. Researchers at Seoul National University have proposed separating those two lessons. Their new preprint learns a speed prior from large collections of demonstrations. Given a task instruction, a local motion path and wrist-camera images, the model predicts a distribution over how fast a demonstrator would move along each part of the path. A chosen quantile becomes a new clock. The geometric path stays in place while its timing changes. That is more subtle than pressing fast-forward. A uniform speed-up preserves every hesitation and makes every delicate moment faster by the same amount. The learned clock can shorten dead time while keeping a different pace around a grasp, turn or release. In the authors' analysis, retiming with the median learned clock improved the smoothness of held-out DROID demonstrations, while uniform acceleration to the same duration largely preserved their stops and hesitations. The system learns that clock from two kinds of data. DROID contains robot teleoperation demonstrations. FastUMI-100K contains handheld demonstrations in which a person moves the gripper directly. The researchers train a transformer from scratch to predict speed distributions across both domains, then ask how a handheld demonstrator would traverse a robot path. The model reads the path in windows of 17 nodes spaced two centimeters apart. Each window includes the task instruction, local positions and rotations, gripper state and nearby camera images. It predicts separate speed distributions for the arm and gripper. Integrating the chosen speed along the path produces the replacement clock. The team then fine-tunes a released vision-language-action policy on DROID demonstrations retimed to the handheld pace. The policy learns a median clock plus faster tempo channels based on higher quantiles. At deployment, a user can choose one of those channels. The policy does not get the last word about speed. Human motion can exceed a robot's velocity, acceleration or torque limits. Predicted action chunks can also disagree where one chunk hands off to the next. The authors add a real-time optimal-control layer that treats the learned pace as an upper bound. It fits a minimum-jerk path, joins it to the robot's current motion and slows only where a hardware limit binds. The resulting plan is checked before installation. If smoothing fails, the solver relaxes its waypoint boxes, and a plan that still fails is replaced by a braking plan. That controller is not decorative plumbing. It is part of the result. On the RoboLab simulation benchmark, the researchers evaluated 120 language-conditioned tasks, including stacking, pick-and-place, tool use and rearrangement, with ten episodes per task. They compared their learned clocks with uniformly accelerated policies at matched average speed. At roughly twice the default end-effector speed, the learned-clock policy reached a 57.7 percent success rate, compared with 53.3 percent for uniform acceleration. At the faster setting, the learned-clock policy ran at 2.38 times the default speed and reached 60.8 percent success, while a uniformly accelerated policy at 2.48 times reached 53.0 percent. The motion was also less violent by the paper's measures. At that faster setting, peak end-effector speed was 24 percent lower and integrated squared jerk was 52 percent lower than uniform acceleration. The authors also report an average advantage of 4.9 percentage points in success rate across the learned clocks, with a 95 percent confidence interval from 2.8 to 7.1 points. Jerk needs a translation before it becomes a slogan. In mechanics, jerk is the rate at which acceleration changes. A lower integrated squared jerk suggests fewer abrupt changes across a trajectory. It does not prove that the robot kept a safe distance from a person, protected every object or would stop correctly after a bad perception. Smoothness is useful evidence, not a safety certificate. The real-robot tests make the tradeoff easier to see. The team collected 412 handheld demonstrations of stacking cups, 242 of folding a towel and 61 of cleaning trash. On the cup task, the October 23 preprint reports that the default policy took 6.02 seconds and succeeded in 29 of 30 trials. The learned-clock policy on its 0.95 tempo channel also succeeded 29 times, but averaged 3.50 seconds. The fastest cup setting averaged 3.25 seconds and succeeded in 28 of 30 trials. One more notch of speed bought a quarter second and lost one success. That is exactly the kind of tradeoff a production team should expose instead of hiding behind a single fastest run. On towel folding, the fastest tested tempo completed all 30 trials in an average of 3.85 seconds, compared with 29 successes and 5.52 seconds for the default policy under the new controller. On trash cleaning, the authors report throughput rising from 444 to as many as 809 items per hour, but that measure came from only five episodes per condition. The controller comparison is equally important. With a standard position controller, the default policy folded the towel in only 4 of 30 trials. With the authors' controller, it succeeded in 29. The speed model and execution layer should therefore be audited as one system, not marketed as if a clever training clock did everything. There is also a source-version wrinkle worth keeping visible. The October 23 arXiv preprint reports the 3.50 versus 6.02 second cup comparison with 29 successes in each condition. The current anonymous project page, which says the work is under review at ICLR 2027, reports 3.43 versus 5.67 seconds with 30 successes. The page also says Table 2 separates the training and controller effects. Those numbers may reflect a revised experiment or a different project-page snapshot. The sources do not explain the mismatch. Until a revised paper or changelog does, the defensible choice is to cite each set with its source and avoid combining them. The broader idea is genuinely useful. Demonstration data is expensive, and recollecting every task at a cleaner pace is not always practical. A learned prior can preserve a diverse set of paths while removing some operator-specific delay. A factory could use the method to propose faster cycles for familiar manipulation. A lab could compare novice and expert timing without discarding the novice's successful paths. A teleoperation dataset could become less tied to the latency of its interface. The useful product, though, is not a faster clock. It is a speed-and-safety receipt. For every task, publish the source of the target pace, the selected quantile and the actual speed after hardware constraints intervened. Report success and completion time together. Add peak speed, jerk, smoothness, collision margin, emergency stops, braking-plan fallbacks, controller interventions and damaged-object counts. Break results out by task, object, scene and distance from people. Keep the slower baseline in the room. Averages across 120 simulation tasks can hide the handful that become brittle. A cup pyramid can hide failures on a sharp tool, a liquid container or an object that changes weight. A smooth end-effector path can hide grip force, joint stress or a camera mistake. A 30-trial laboratory test can miss the rare event that matters on shift number ten thousand. The paper names two boundaries plainly. The speed prior can transfer only paces that some demonstrator has already shown. It cannot invent a genuinely faster style beyond the observed data. And the ethics statement says the real-robot work occurred in a controlled laboratory, with additional safety validation required before operation near people. That should shape deployment. Use learned timing first where the workspace is guarded, objects are known and a failed cycle is recoverable. Establish task-specific speed ceilings instead of one global aggressive mode. Require a physical safety layer independent of the learned policy. Recheck timing after the robot, gripper, payload, camera or environment changes. Give operators a clear slower mode and a real stop control. Moving faster is valuable. Moving smoothly is better. Knowing when the evidence is too thin to accelerate is the part that turns a quick robot into a trustworthy one.
01
WHAT ACTUALLY CHANGED
A Seoul National University team learned a reusable speed prior from teleoperated and handheld robot demonstrations
The model predicts a distribution of speeds along a path instead of applying one uniform acceleration factor
Demonstrations are retimed before a vision-language-action policy is fine-tuned
Higher prediction quantiles become selectable tempo channels at deployment
A real-time controller smooths action chunks and enforces velocity, acceleration and torque limits
The authors report faster, more successful and lower-jerk motion in simulation and controlled laboratory tests
02
WHY THIS MATTERS
Robot policies can inherit operator hesitation that is unrelated to the task itself
Retiming may reuse diverse demonstrations without recollecting every task at an expert pace
Task-aware timing can outperform pressing fast-forward on the entire trajectory
The controller contributes materially to reliability and must be evaluated with the learned policy
Lower jerk is evidence of smoother motion, not proof of safe operation around people
A visible speed receipt can keep cycle-time gains tied to success, constraints and intervention data
03
WHERE IT COULD HELP
- Retiming teleoperated demonstrations before policy fine-tuning
- Comparing novice and expert timing without discarding successful paths
- Proposing faster cycles for guarded manipulation workcells
- Learning when to slow near grasps, releases and direction changes
- Publishing the target demonstrator and selected speed quantile
- Reporting success, completion time, peak speed and jerk together
- Logging every controller intervention and braking-plan fallback
- Testing fragile, heavy and contact-rich objects separately
- Setting task-specific speed ceilings and protected human zones
- Revalidating after changes to hardware, payload or environment
KEEP A HAND ON THE WHEEL
This is an author-reported October 23 preprint. Its real-robot evaluations were conducted in a controlled laboratory, and several conditions use 30 trials while trash cleaning uses five. The current project page reports different cup-stacking times and success counts from the preprint without explaining the revision. Lower jerk and compliance with modeled robot limits do not establish safe operation near people, protect every object or cover perception failures. The learned prior can transfer only paces present in its demonstration data. Watch for a reconciled paper and project page, independent reproduction, task-level failure tables, collision and near-miss measurements, force and object-damage data, long-run durability, safety-layer interventions and tests with people, unfamiliar payloads and changed hardware.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Vision-language-action model
A model that connects visual input and instructions with physical actions a robot can execute.
OPEN GLOSSARY CARD
Fine-tuning
Extra training that shapes a model for a narrower job or behavior.
OPEN GLOSSARY CARD
Benchmark
A fixed test used to compare how systems perform on the same tasks.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 26, 2026.
PUBLICATION RECEIPT: All performance results are identified as author-reported. The article cites the October 23 preprint for its main tables and separately preserves the unexplained result mismatch on the current project page. The speed-and-safety receipt is Plain Signal analysis.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US