THE SIGNAL IN ONE SENTENCE
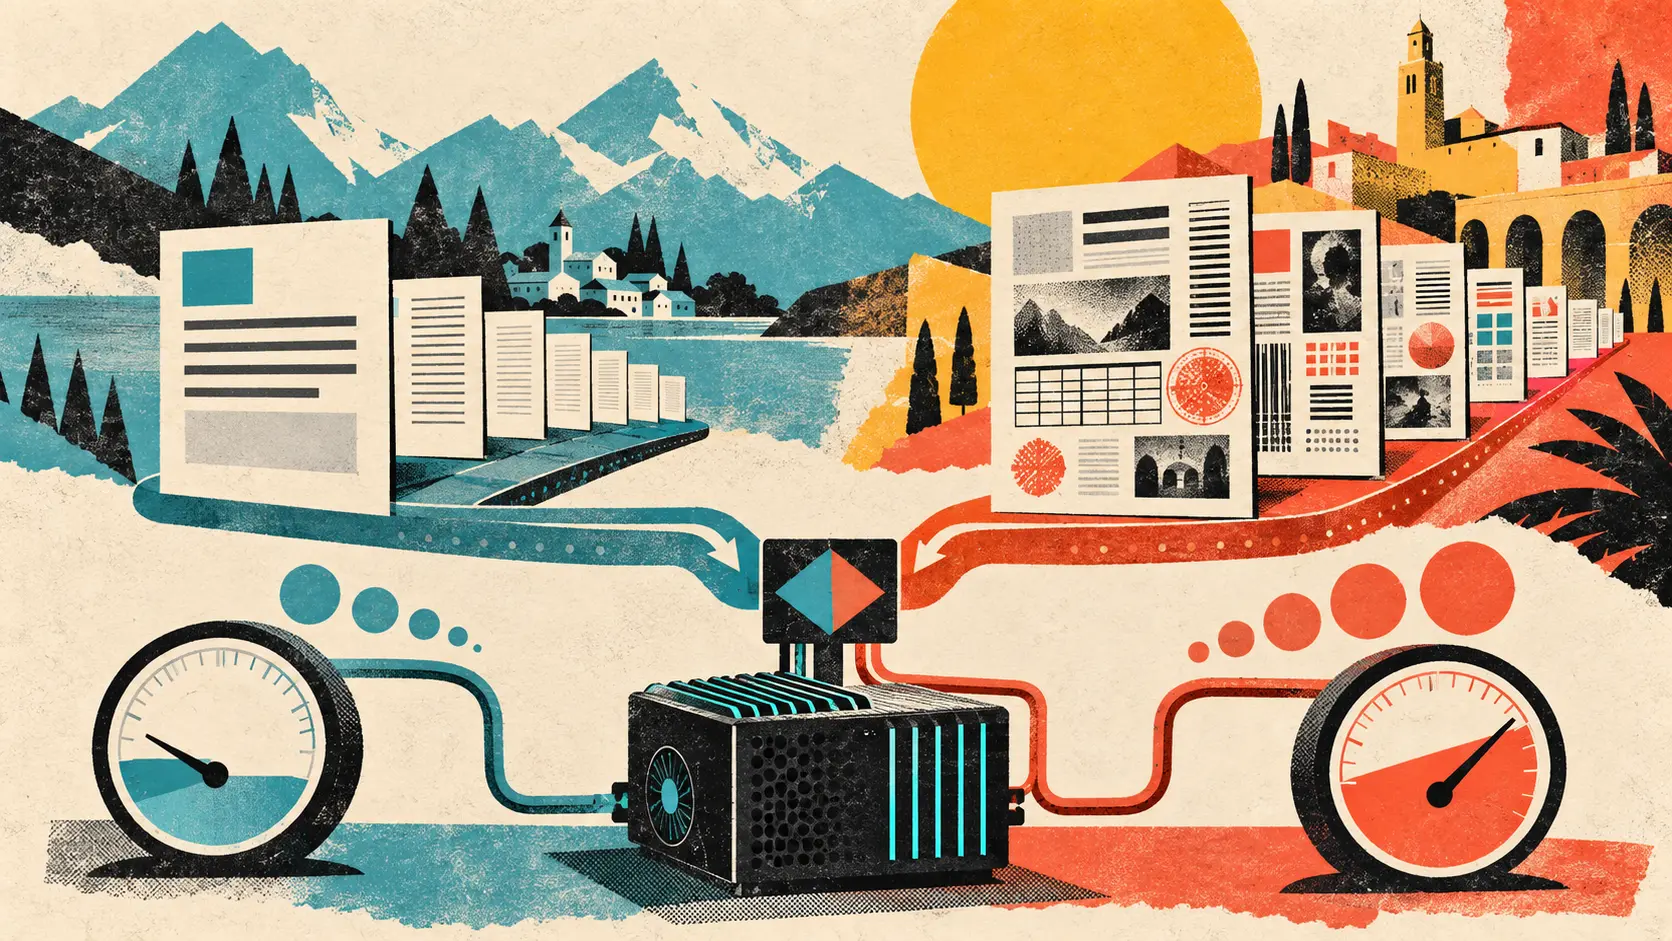
There is no greenest document AI. There is a cheap path for one kind of page, a better visual path for another, and a very expensive way to pretend those pages are the same. That is the practical result of a September 25 preprint by Christoph Walser and Jonathan Fürst at Zurich University of Applied Sciences and Mauricio Fadel Argerich at Universidad Politécnica de Madrid. The researchers tested local information-extraction pipelines built from models with no more than eight billion parameters. They measured both the accuracy of the fields extracted from documents and the energy consumed per page. Their answer changed with the document. On contracts whose useful information mostly follows ordinary text, small text-only models paired with a cheap parser were more accurate and used less energy than the vision-language configurations tested. On scanned registration forms where boxes, columns and position carry meaning, vision-language models reading the page image moved to the front. The paper is less a beauty contest for models than a routing manual for paperwork. Before choosing a model, look at the page. The study compares two deliberately different document collections. Kleister-NDA contains near-plain-text contracts. The evaluation uses 337 documents with up to four requested fields, while the energy profiling covers 500 documents. Those 500 contracts contain 2,934 pages, or 5.87 pages per document. VRDU Registration contains short, scanned forms where spatial arrangement matters. The evaluation and profiling use 500 documents, totaling 915 pages, or 1.83 pages per document. That difference matters. Layout and length move together in this experiment, so the authors do not claim they isolated layout as the only cause. They describe a contrast between two document types: long, text-heavy contracts and short, layout-rich forms. This is an unusually useful restraint. A benchmark with two datasets is a comparison, not a constitution for every invoice, medical record, permit and handwritten note on Earth. Each pipeline has three decisions. First, represent the document as page images or convert it into text. Second, choose a vision-language model, a text-only language model or a specialized layout model. Third, choose how the server handles inference, including batch size and numerical precision. The team evaluated Qwen3 vision and text models at several sizes, Llama, Ministral, Mistral, NuExtract and Arctic-TILT. General-purpose inference ran through vLLM on one NVIDIA L4 GPU. Batch sizes ranged from one to sixty, subject to memory. The paper compares FP16 and FP8 precision. Text conversion used Tesseract, Docling or DeepSeek-OCR 2, depending on the experiment. This full-pipeline view is the paper's best decision. A document system does not begin when the model receives its tokens. It begins when a file is opened, rasterized, parsed or photographed. Charging only the final model call is like publishing a fuel economy number after towing the truck to the test track. The parser may be the expensive part. On both datasets, DeepSeek-OCR 2 consumed an order of magnitude more parsing energy per page than the classical alternatives. The paper reports about seventeen times Tesseract's per-page energy on Kleister-NDA and eighteen times on VRDU. Neural OCR improved extraction accuracy for most text-only models on the scanned forms, often by seven to fifteen exact-match points over the better classical representation. Yet no DeepSeek-OCR 2 configuration reached either end-to-end Pareto frontier. A vision-language model could read the layout-rich page directly and supply the relevant accuracy more cheaply. On the born-digital contracts, Docling could use embedded text rather than visually reading every page. That made it especially efficient. Tesseract was cheaper on the scanned forms, where Docling had to perform visual OCR. The lesson is not that one parser wins. The lesson is that a parser changes jobs when the file changes. The most concrete comparison comes from matching similarly sized Qwen models. On Kleister-NDA, Qwen3-4B with Docling reached 75.4 percent exact match at 5.0 milliwatt-hours per page. Qwen3-VL-4B reached 70.1 percent at 8.1 milliwatt-hours per page. The text path was both more accurate and cheaper. On VRDU, the ordering reversed. The text model with Docling reached 56.1 percent at 19.5 milliwatt-hours per page, while the vision model reached 65.6 percent at 12.2. The messy page did not merely justify more energy. It justified a different representation that also used less energy in that comparison. This is why one global model policy is silly. A procurement team that sends every page through vision pays for pixels that may add nothing. A team that strips every page into plain text can destroy the spatial relationships that make a form understandable. The right unit of optimization is the route from document to verified field, not the model name. Batching was the strongest energy lever the researchers measured. Moving from one request at a time to the best tested batch size reduced energy per page by 38 to 85 percent without changing extraction accuracy. Most of the gain arrived by batch size ten. For Qwen3-8B, energy fell from 39.5 to 9.8 milliwatt-hours per page by batch ten, then reached 6.9 at batch sixty. The final sixfold increase in batch size bought only eight of the total eighty-three percentage points of savings. The largest vision model behaved differently. Qwen3-VL-8B reached its minimum at batch ten and then flattened because it was already near the L4's memory budget. Batch size is not a dial to turn forever. It is a utilization curve to measure. There is an operational catch. Batching improves energy per page by grouping work, but it can make an individual document wait for companions. A back-office archive can tolerate a queue that fills for a few seconds. A person standing at an emergency intake desk may not. The paper measures energy and extraction quality, not user-visible tail latency, queue delay, service deadlines or failure recovery. Production routing needs all of them. The green setting at midnight may be the wrong setting at noon. FP8 quantization helped most when the server handled one request at a time. The abstract reports savings of 27 to 32 percent in that setting. Once batching was applied, FP8 saved less than one milliwatt-hour per page, or roughly 9 to 19 percent. The techniques overlap because both improve how efficiently the hardware works. The paper's blunt advice is correct: batch before you quantize. Quantization can still create memory headroom or help a workload that cannot batch, but it is not a magic second copy of the same savings. This study also makes accuracy harder to oversell. Its headline measure is average field exact match. The output must match the gold value set after normalization. But fields a model declines to answer are not counted in that metric's denominator, so exact match acts more like field-level precision than a complete success rate. The authors publish value-level F1, which penalizes omissions, and say the two should be read together. A system that answers only its favorite fields can look clean while leaving the job unfinished. Real document operations need field coverage, confidence, exception rates and human correction time alongside exact match. One specialized model needs another warning label. Arctic-TILT was already fine-tuned on Kleister-NDA, and some evaluated documents may overlap with its training material. Its 92 percent exact-match result is an in-domain reference, not a zero-shot comparison. The authors exclude it from the best-configuration and Pareto claims on that dataset. That does not make the number useless. It shows the possible value of domain adaptation. It cannot be used as proof that the architecture beats models that never saw the target corpus. The energy numbers are also estimates with a defined boundary. GPU power is sampled through NVIDIA's management interface at ten hertz. CPU and memory contributions are modeled rather than directly metered. CodeCarbon profiles parsing and specialized models, while Bench360 profiles models served through vLLM. Model loading is excluded, so the measurements describe steady-state serving rather than a cold start. Cooling and other facility overhead are excluded. The paper cites validation work suggesting CodeCarbon can underestimate total consumption by 20 to 30 percent. Most configurations were measured once, although the close FP16 and FP8 comparisons were repeated three times. These limitations do not erase a 38 to 85 percent batching effect or an order-of-magnitude parser difference. They do stop a team from copying the reported milliwatt-hours into an environmental report as if they were a utility meter. Energy per page is not carbon per page. The carbon effect depends on where and when the electricity is produced, how long the hardware lasts, what was required to manufacture it, how often the server sits idle and whether a local deployment replaces a cloud request or merely duplicates it. Local processing can improve governance for sensitive documents because the files need not be sent to a closed third-party service. It does not make the system private by location alone. Parsed text, page images, prompts, outputs, logs, model caches and exception queues can all expose personal or commercial information. Organizations still need access controls, retention limits, encryption, audit records and a rule for which documents may enter the system. The practical product is a document router with a receipt. Begin with a cheap layout assessment that does not send the file elsewhere. Is the PDF born digital? Does it expose embedded text? Are fields carried by reading order or by position in boxes, tables and columns? Is it scanned, handwritten or damaged? Route near-plain text to an embedded-text parser and a small text model. Route layout-rich pages to a tested vision model. Use classical OCR for scanned text when it preserves enough information. Add neural OCR only where its measured accuracy gain repays its energy, latency and operational cost. Then batch within each service-level class instead of mixing every request into one queue. Save the route, parser, model, precision, batch size, page count, energy estimate and output confidence. Sample documents for human review, especially when a route changes. Track corrections by document type and field. If a visual route repeatedly adds no value for one template, move that template to the cheaper path. If text extraction breaks a new form, send it back to vision. The system should learn routing policy from verified operating results, not from the aesthetic confidence of a model card. Switzerland and Spain matter here for more than the flags beside the author list. European organizations handle dense flows of contracts, forms, public records, financial documents and health information under strong privacy expectations and growing pressure to account for computing energy. A small local pipeline can be an attractive alternative to a closed cloud service. The paper shows why local does not mean one-size-fits-all. Efficiency comes from matching representation, model and serving behavior to the document. That is a systems result, not a model launch. The plain signal is wonderfully unglamorous. Do not run a visual model because the document is a PDF. Do not run neural OCR because it sounds smarter. Do not process one page at a time because the demo arrived alone. Inspect the page, choose the cheapest route that preserves its meaning, batch when the service can wait, and measure the whole path. The greenest document AI is not one model. It is the routing rule that knows when the page got messy.
01
WHAT ACTUALLY CHANGED
Researchers from Zurich University of Applied Sciences and Universidad Politécnica de Madrid posted the preprint on September 25.
The study compares local information-extraction pipelines using models with no more than eight billion parameters.
The authors evaluate a long, near-plain-text contract dataset and a short, layout-rich registration-form dataset.
Kleister-NDA evaluation uses 337 documents with up to four requested fields.
VRDU Registration evaluation uses 500 documents with up to six requested fields.
Energy profiling covers 500 documents from each dataset.
The profiled contracts contain 2,934 pages while the forms contain 915 pages.
General-purpose inference runs through vLLM on one NVIDIA L4 GPU.
The study tests page images, embedded-text parsing, classical OCR and neural OCR.
Tested batch sizes range from one to sixty, subject to memory limits.
Batching reduces measured energy per page by 38 to 85 percent without changing extraction accuracy.
Most batching gains arrive by batch size ten.
FP8 saves 27 to 32 percent for single-request serving but less than one milliwatt-hour per page after batching.
DeepSeek-OCR 2 uses about seventeen times Tesseract's per-page energy on Kleister-NDA and eighteen times on VRDU.
No DeepSeek-OCR 2 configuration reaches either end-to-end Pareto frontier.
Vision-language models lead the tested frontier on layout-rich forms.
Small text-only models with a cheap parser lead the tested frontier on text-heavy contracts.
The authors published configurations, measured results and figure-generation scripts in an MIT-licensed repository.
02
WHY THIS MATTERS
A document pipeline can waste energy before the model begins because parsing and OCR are part of the workload.
Page layout can carry meaning that disappears when a form is flattened into plain text.
Page images can add cost without useful information when a document already exposes clean embedded text.
A single default model route is unlikely to be efficient across contracts, forms, invoices and scans.
Batching can deliver a larger energy gain than changing model precision.
Batching also introduces queue delay, so energy must be balanced against service deadlines.
Quantization and batching recover some of the same hardware inefficiency and should not be counted as independent full savings.
Neural OCR can improve scanned-form accuracy while still losing the end-to-end energy trade-off.
Exact match can look better when unanswered fields are excluded from its denominator.
Value-level F1, coverage and human correction time are necessary companions to exact match.
An in-domain fine-tuned result is not directly comparable with zero-shot systems.
Modeled CPU and memory power cannot support a utility-bill-level environmental claim.
Steady-state energy excludes loading, cooling, idle time and recovery costs.
Energy per page is not carbon per page because electricity sources and hardware lifecycle differ.
Local processing can reduce third-party exposure while leaving logs, access and retention risks inside the organization.
A routing policy can be improved from verified corrections without forcing every page through the largest model.
The study's two datasets support a useful contrast but not a universal rule for every document class.
Publishing the result files and scripts makes the claims easier to inspect and reproduce.
03
WHERE IT COULD HELP
- Classify incoming documents as born digital, scanned, text-heavy or layout-rich before model selection.
- Use embedded-text parsing for clean digital documents when it preserves the required fields.
- Use a tested vision-language route when position, boxes, columns or tables carry meaning.
- Keep classical OCR as a low-cost baseline for scanned text.
- Add neural OCR only after measuring whether its field-level gain repays the full pipeline cost.
- Batch requests within the same latency and privacy class rather than creating one universal queue.
- Measure the energy curve from batch one through the point where gains flatten or memory pressure rises.
- Use FP8 when requests cannot batch or when lower precision creates useful memory headroom.
- Record parser, model, precision, batch size, page count and hardware for every evaluation run.
- Include parser and preprocessing energy in the same ledger as inference energy.
- Measure cold starts, idle power, queue delay and tail latency before production rollout.
- Read exact match beside F1, field coverage, exception rate and human correction time.
- Separate zero-shot, fine-tuned and potentially overlapping evaluation results.
- Validate on the organization's real document templates instead of importing one global benchmark winner.
- Sample routed documents for human review and track corrections by field and document type.
- Move stable templates to cheaper routes when vision adds no verified benefit.
- Escalate damaged, handwritten or unfamiliar pages instead of forcing a confident extraction.
- Protect source files, parsed text, prompts, outputs and logs with the same data-governance controls.
- Publish uncertainty ranges and measurement boundaries beside every energy claim.
- Translate energy per page into carbon only with location, time and lifecycle assumptions stated.
KEEP A HAND ON THE WHEEL
This is a September 25 preprint tested on two datasets and one NVIDIA L4 system. The low-layout dataset is also the longer dataset, so layout complexity and document length are partly confounded. Vision models see at most ten Kleister-NDA pages or five VRDU pages per document. Arctic-TILT was already fine-tuned on Kleister-NDA and may overlap with evaluated documents, so its result is an in-domain reference rather than a comparable zero-shot score. Average field exact match excludes declined fields from its denominator and must be read with value-level F1. Most configurations were measured once. GPU power was sampled through NVIDIA's management interface, while CPU and memory power were modeled rather than directly metered. CodeCarbon and Bench360 were not cross-validated for their CPU and memory estimates. Model loading, cooling and facility overhead are excluded, so the numbers describe steady-state compute rather than total operational or lifecycle energy. The authors cite evidence that CodeCarbon can understate total power consumption by 20 to 30 percent. The study does not measure carbon emissions, production latency, privacy incidents, human correction cost or performance on handwritten, multilingual and damaged documents. Watch for direct-meter replication on more hardware, layout-matched datasets, deterministic decoding, cold-start and latency measurements, broader document types, real organizational pilots and a router evaluated against one fixed-model policy.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Information extraction
Turning unstructured material such as documents into named fields or structured records.
OPEN GLOSSARY CARD
Vision-language model
A model that can interpret visual inputs and language together.
OPEN GLOSSARY CARD
Batch inference
Processing several requests together so computing hardware spends less time idle and shares work efficiently.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 28, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 28, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US