THE SIGNAL IN ONE SENTENCE
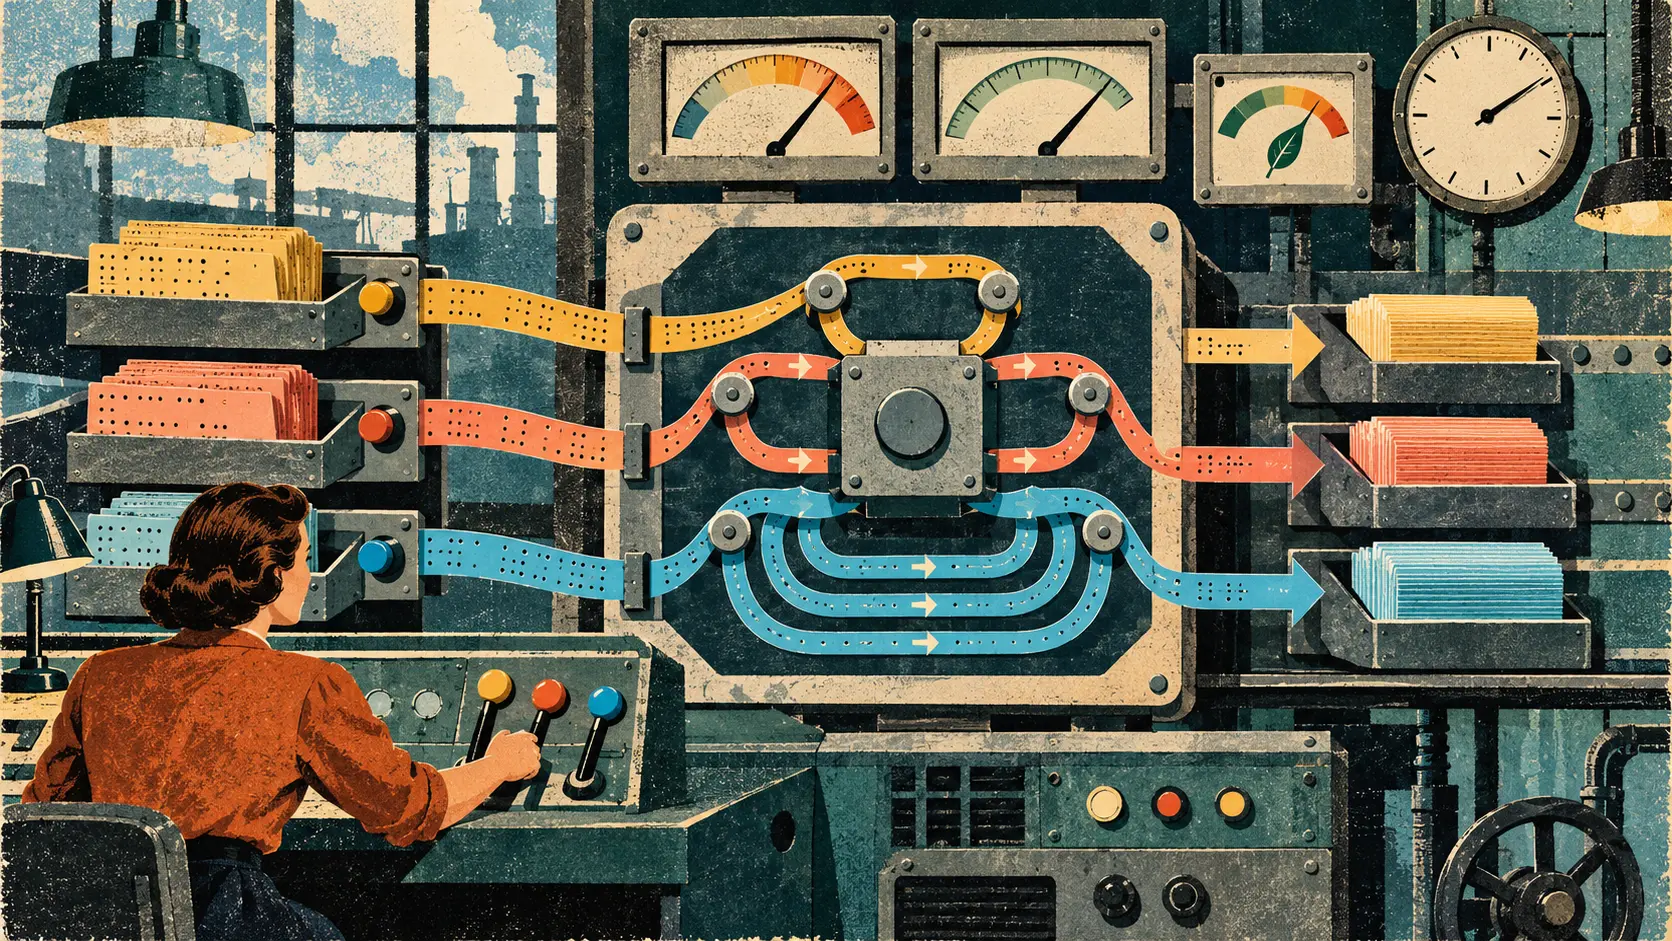
Most language models arrive with a fixed appetite. You can change the portion, but the kitchen stays the same size. NVIDIA's Dory offers a stranger menu. The same four-billion-parameter checkpoint can run a shared block of layers once, twice or four times for each generated token. One loop spends less compute. More loops let the model work longer inside its hidden representations before it produces the next word. No checkpoint swap is required. No separate larger model needs to warm up. The operator changes the number of times the recurrent block runs. That sounds like a small architectural detail. In production, it is a scheduling decision. A password-reset answer probably should not receive the same inference budget as a code migration. A local document classifier may need speed and predictable power use. An agent editing a repository may deserve another pass if that pass raises task success enough to save a human from cleaning up afterward. The plain signal is this: adjustable depth is useful only when somebody owns the dial. NVIDIA released Dory1.0-4B on October 16. The official model card describes a looped, or latent-recurrent, normalized-GPT architecture with a context window of up to 256,000 tokens and English as its supported language. The model is available in BF16, MXFP8, NVFP4 and Q5_K_M formats under the OpenMDW 1.1 license. The architecture has three sections. An input block processes the token representation. A recurrent block of twenty layers can be applied repeatedly. An output block completes the path. The input is reinjected into every recurrent pass. NVIDIA says the input and output sections contain eight layers each. The useful trick is parameter sharing. Reusing the recurrent block lets the model spend more computation without storing a separate set of weights for each extra pass. The checkpoint stays four billion parameters even when the operator asks for deeper processing. This is not free thinking. Each loop still performs computation. NVIDIA's benchmark table shows why the dial is tempting. Under the company's evaluation harness, Dory's SWE-bench Verified score rises from 50.3 with one loop to 59.5 with two and 61.8 with four. Terminal-Bench 2.1 moves from 12.5 to 18.1 to 22.2. IFBench rises from 74.29 to 77.94 to 79. The long-context AA-LCR result goes from 63 to 71 to 73. Those are company-run measurements, not independent deployment results. They also refuse to support the neat little story that more is always better. On GPQA Diamond, Dory moves from 69.19 with one loop to 72.41 with two, then slips to 72.16 with four. Humanity's Last Exam goes from 8.25 to 10.89, then down to 10.43. The reported general-knowledge accuracy is essentially flat. SciCode gains sharply on the second loop and only slightly on the fourth. The second pass often does most of the useful work. NVIDIA recommends two loops as a starting point and suggests evaluating four for tasks where extra accuracy matters. That is a sensible default, not a law of nature. The right loop count depends on the whole request. Extra loops increase compute per token. They may also reduce the number of generated tokens needed to solve a task, according to NVIDIA's measurements. A deeper run could therefore cost more for each token while producing fewer tokens overall. Latency, throughput, energy and quality do not move in one tidy direction. This is where a benchmark table stops and operations begin. A deployment team should record time to first token, time to completion, total generated tokens, energy consumed, peak memory, concurrent-request capacity and task success for every supported loop setting. Measuring only tokens per second can make a shorter but more expensive answer look cheap. Measuring only accuracy can hide a queue that became too slow for the people waiting behind it. The task set must be local. A help desk should test its actual tickets. A coding tool should test repositories with the languages, build systems and permissions it will encounter. A document workflow should include the messy scans, tables and exceptions that arrive on an ordinary Tuesday. The comparison also needs a human-cost column. If four loops improve a code patch by two points but double response time, the trade may still be worthwhile when a failed patch burns thirty minutes of review. If the same setting adds latency to a short factual lookup without improving correctness, the extra pass is mostly expensive theater. That suggests a routing policy with a few boring rules. Start cheap. Use one or two loops for low-risk, reversible work. Increase the budget only for tasks that local tests show benefit from it. Put a hard ceiling on agent steps and generated tokens. Route uncertain or high-consequence requests to a stronger model or a person rather than spinning the same block and hoping confidence appears. The router should not judge difficulty from vibes. Useful signals include request type, input length, tool use, prior failure, output constraints and the cost of being wrong. A static classifier can route known task categories. A staged system can begin with one loop, run a cheap verifier and retry with more depth only when a defined condition is met. Either design needs protection against requests that manipulate the router into spending more resources. Budget abuse is not theoretical. If users or downstream agents can trigger the deepest setting without limits, one small model can become a large bill wearing a compact nametag. Public endpoints need quotas. Internal agents need per-job ceilings. Batch systems need a queue policy that prevents a pile of four-loop experiments from starving routine work. Memory needs its own receipt. Standard recurrent looping can keep a separate key-value cache for every pass, which makes cache memory grow with loop count. Dory also supports a last-loop cache mode. In that mode, each pass overwrites the earlier recurrent cache so the model keeps the same recurrent cache footprint as one loop. NVIDIA says its experiments found accuracy close to the per-loop cache mode with nearly unchanged output length. That claim should be tested on the chosen tasks and context lengths. Cache savings can improve concurrency, but a long advertised context window does not guarantee that every server, quantization and loop setting can use 256,000 tokens efficiently at the same time. Serving support is another practical caveat. At verification, Dory support in vLLM was still under review in a pull request. NVIDIA's quick-start instructions tell users to install from that pull request rather than from a released package. The llama.cpp path likewise points to a Dory-enabled revision and notes that the model's support is not yet in a regular release. That is workable for evaluation. It is a flashing yellow light for production. Pin the runtime commit. Record the checkpoint hash, quantization, loop count, cache mode, context limit and sampling settings. Run load tests. Watch for output changes when upstream support lands. A model with an adjustable recurrent block introduces one more configuration surface where two nominally identical deployments can behave differently. The quantized files deserve separate testing too. NVIDIA's published benchmark table is for the BF16 checkpoint. A Q5_K_M build on a laptop or an NVFP4 deployment on accelerated hardware is not automatically represented by those scores. Quantization can change quality, memory use, speed and hardware compatibility. Dory is described as a small-footprint model, but small is a relative adjective. Four billion parameters can fit into places where much larger systems cannot. It still needs compatible memory, runtime support and power. NVIDIA lists Hopper and Blackwell as supported hardware for the official PyTorch integration, while the reference llama.cpp instructions target Apple Silicon using a quantized export. Edge deployment therefore means measurement at the actual edge. A laboratory server, a developer laptop and an embedded system are not interchangeable just because all three can load a file. There is also a training receipt. NVIDIA says Dory was pretrained on six trillion tokens, with roughly the first 4.5 trillion using its NVFP4 format and the remainder in BF16. A later phase extended context over another 300 billion tokens. The company describes post-training across math, code, science, instruction following, tool use, conversation and structured output. Scale at training time does not remove the need for evaluation at use time. The card lists English as the supported language. It does not establish reliability across languages, professional domains or high-stakes decisions. The model can generate false information, insecure code and persuasive explanations for wrong answers, just like larger relatives with more expensive wardrobes. The most useful experiment is not a general leaderboard rematch. Choose three task classes. Give each a clear success measure and consequence level. Run one, two and four loops under the same runtime, hardware, prompt and tool policy. Repeat enough times to see variance. Record the complete cost and quality envelope. Then set a default and publish the exceptions. For example, a local assistant might use one loop for classification, two for summarization and four only for repository repairs that pass a verifier. A field device might cap everything at two loops when operating on battery. A shared inference service might allow four loops only when the request includes an approved project code. The policy should be visible to operators. Dashboards should show what fraction of requests use each setting, which tasks escalate, how often deeper runs reverse an earlier wrong answer and what the extra passes cost. If four loops are being used everywhere, the router is not routing. If one loop never survives validation, the cheap tier may be imaginary. Adjustable inference has a healthy implication beyond Dory. Model size does not have to be the only lever. A system can vary the amount of computation spent on a request while keeping one set of weights resident. That could simplify memory management, reduce model swaps and make capacity more responsive to task value. It could also make cost harder to see. A four-billion-parameter label sounds reassuringly compact even when the server quietly performs four recurrent passes for every token. So give the dial a budget, a meter and an owner. One checkpoint can contain several useful operating points. The best one is not the deepest. It is the shallowest setting that meets the task's quality requirement under the latency, energy and review budget people actually have.
01
WHAT ACTUALLY CHANGED
NVIDIA released Dory1.0-4B on October 16, 2026
One four-billion-parameter checkpoint can run the shared recurrent block one, two or four times
The architecture uses eight-layer input and output blocks around a shared twenty-layer recurrent block
The model supports an advertised context length of up to 256,000 tokens and lists English as its supported language
NVIDIA publishes BF16, MXFP8, NVFP4 and Q5_K_M formats under the OpenMDW 1.1 license
Company-run benchmarks generally improve from one to two loops and improve further on some tasks at four loops
Four loops perform slightly worse than two on several reported reasoning tests
NVIDIA says deeper looping can reduce generated-token counts even while increasing compute per token
A last-loop key-value cache mode keeps recurrent cache memory at the one-loop footprint
At verification, official vLLM and regular llama.cpp release support had not yet landed
02
WHY THIS MATTERS
A single resident checkpoint can serve several compute budgets without loading separate model sizes
Task routing can reserve deeper inference for requests where local evidence shows a useful gain
Parameter count alone no longer describes the compute spent on each generated token
More loops can increase per-token work while reducing output length, so total cost needs end-to-end measurement
The reported results show that deeper inference is not uniformly better across tasks
Adjustable loop count adds a configuration surface that must be logged and reproduced
Cache mode can change the relationship among memory, concurrency and accuracy
Unreleased runtime integrations increase operational risk and make commit pinning important
Quantized checkpoints need separate evaluation because published BF16 scores may not transfer
Compute policies should include latency, energy, task success and human review rather than one leaderboard score
03
WHERE IT COULD HELP
- Route routine classification and extraction work through a shallow loop setting
- Reserve deeper passes for code repair, tool use or other locally validated complex tasks
- Keep one checkpoint resident while serving several service levels
- Retry a failed low-budget attempt with more loops after a verifier produces a defined signal
- Cap loop depth on battery-powered or thermally constrained devices
- Use last-loop caching when concurrency or long-context memory is more important than keeping every recurrent cache
- Compare BF16 and quantized deployments on the exact target hardware
- Attach loop count, cache mode and runtime revision to every production trace
- Build quotas that prevent users or agents from triggering unlimited deep inference
- Measure whether deeper inference reduces downstream human correction enough to justify its cost
KEEP A HAND ON THE WHEEL
Watch for released vLLM and llama.cpp support, independent reproduction of loop-count results, latency and energy measurements across hardware, quality under last-loop caching, quantization effects, multilingual evaluation, long-context performance at realistic concurrency, routing policies, budget-abuse controls, stable runtime APIs and evidence that adaptive loop selection beats a simple two-loop default.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 18, 2026.
PUBLICATION RECEIPT: The article attributes all benchmark, architecture and training claims to NVIDIA, notes tasks where four loops trail two, distinguishes BF16 results from quantized deployments and treats routing, energy accounting and budget controls as deployment analysis.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US