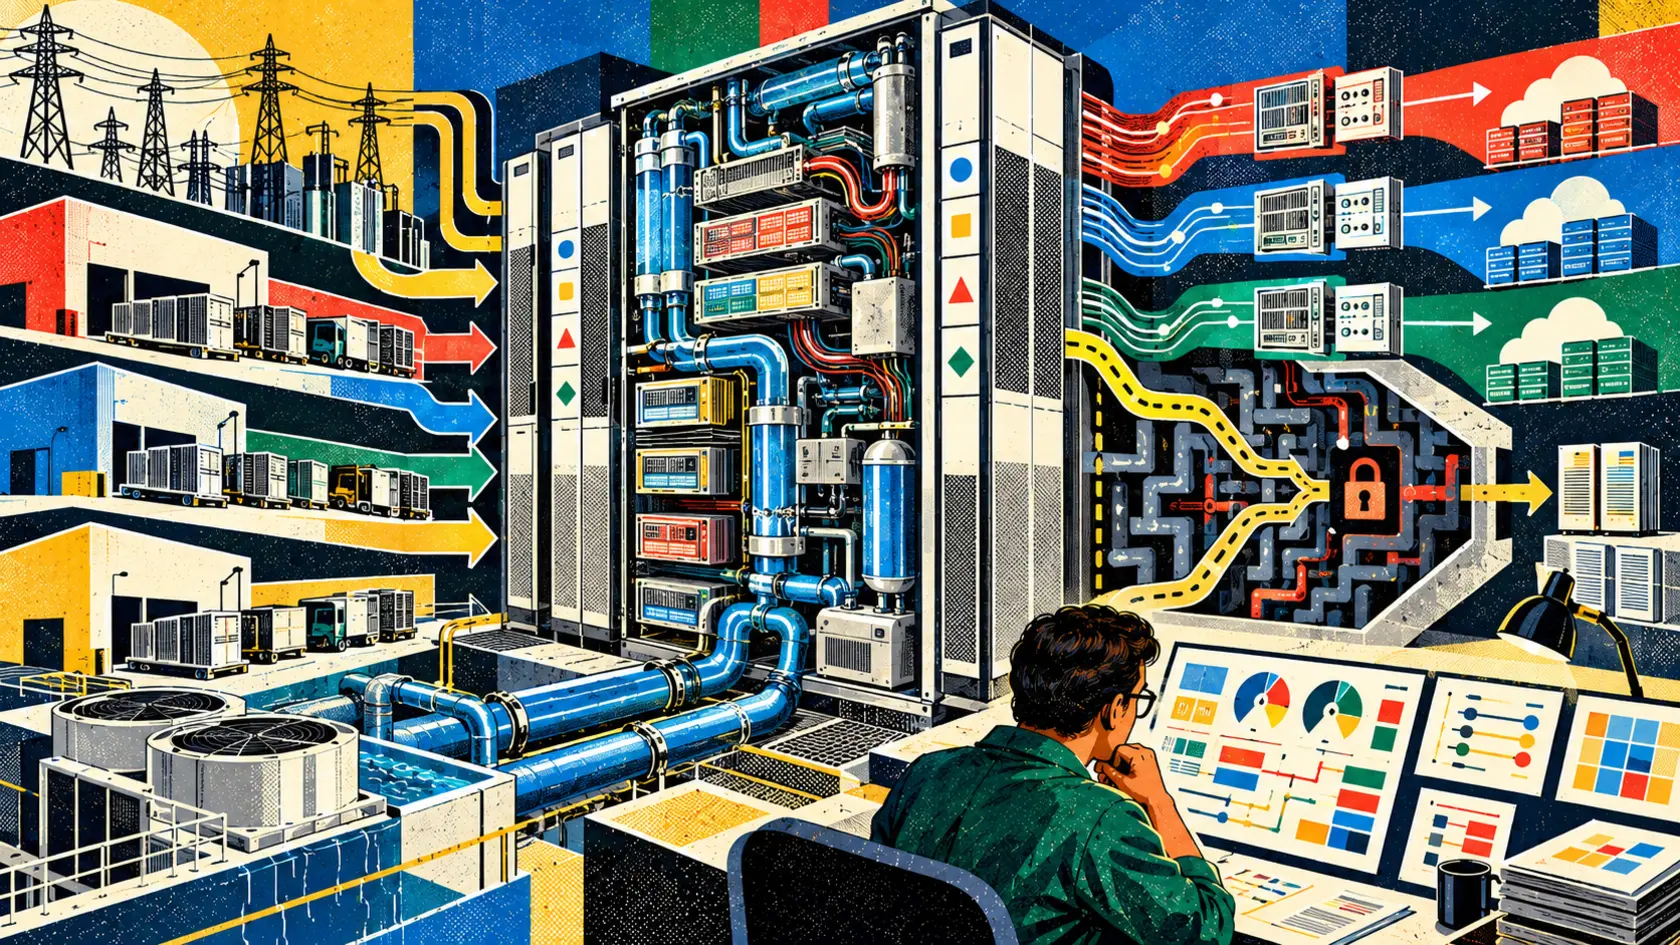
THE SIGNAL IN ONE SENTENCE
A data-center rack can be open around the edges and proprietary in the middle. That is not hypocrisy. It is architecture. It is also where the bill hides. At the Open Compute Project Global Summit on October 12, NVIDIA announced that it had contributed key Vera Rubin rack and compute-tray designs through its MGX architecture. The company also pointed to new open specifications for data-center buildings, grid resilience, cooling, networking and operations. The work is real. The updated MGX 1.2 specification covers blind-mate liquid cooling, rack-scale interconnects, a liquid-cooled 5,000-amp busbar, configurable I/O bays, standardized power and cooling interfaces and racks designed for deployments up to 250 kilowatts. Those details matter because an AI system at this scale is not a server that happens to live in a building. The building becomes part of the computer. Floor loading, aisle width, pipe diameter, busways, substations, network topology, coolant quality and utility behavior all decide whether expensive chips produce useful work or sit politely in the dark. Open interfaces can help equipment makers and operators build to a common target. A standard connector is less glamorous than a new accelerator, but it can keep a failed pump, unavailable cable or custom tray from turning into a six-month archaeology project. The plain signal is that open infrastructure should be measured by two ledgers. The first is an energy ledger. The second is an exit ledger. NVIDIA's announcement blends several layers of openness. Rack and tray designs are contributed through OCP. A separate Open Data Center specification from AMD, Google, Meta and NVIDIA describes shared structural, power and cooling requirements. Google, Meta, Microsoft and NVIDIA published a grid-disturbance specification. Meta is using its open FBOSS network operating system with NVIDIA Spectrum-6 switches. NVIDIA released four DSX operations components through public repositories. Each contribution can reduce a particular kind of friction. None, by itself, proves that a customer can replace the accelerator, interconnect, management layer or software stack without redesigning the system. The word open needs an object. Open rack dimensions are not open silicon. An open network operating system does not make every switch equivalent. Public provisioning code does not eliminate dependencies on the platform it provisions. A facility that can accept equipment from several manufacturers may still be optimized around one vendor's power envelope, cooling geometry, cables and control plane. This is not an argument against standards. It is an argument for reading the label all the way to the bottom. Start with the physical layer. The Open Data Center specification, revision 0.7, was published in August by AMD, Google, Meta and NVIDIA. It gives 2027 and 2028 design guidance for data halls that may hold extremely dense machine-learning systems. It sets targets for rack size and weight, row layouts, power density, cooling capacity and minimum cluster size. The document calls for a baseline cluster of at least 12 megawatts, with 24 megawatts preferred. It describes a maximum rack weight of 8,000 pounds and high-density zones that depend heavily on liquid cooling. Those are design targets, not a declaration that every new facility will consume the maximum. They still show the direction of travel. A rack standard can make infrastructure more reusable while the total campus becomes much larger. Efficiency per token can improve while electricity use, water demand, backup generation and grid construction rise in absolute terms. That is why every deployment needs an energy ledger that begins outside the rack. List the facility's contracted megawatts, hourly electricity use, peak draw, utilization, grid region, marginal generation, backup fuel, water withdrawals, water consumption and cooling method. Separate electricity used by compute from power conversion, networking, storage and cooling. Then connect energy to useful output. Tokens per watt is one measure. It is not the only one. Report successful jobs, completed inferences, failed runs, idle capacity, retries and discarded experiments. A highly efficient rack running unnecessary work is still an expensive room heater with good marketing. The grid ledger matters because giant loads can behave like industrial machinery with very fast reflexes. The new OCP grid-resilience specification responds to the risk that large data centers could disconnect during a disturbance and suddenly remove enormous demand from the grid. Its authors include Google, Meta, Microsoft and NVIDIA. The specification describes voltage ride-through and recovery behavior intended to keep facilities connected and restore load predictably. NVIDIA's summary says compliant infrastructure should return to near-full load in less than two seconds after certain disturbances. That may help grid operators plan around large customers. It does not answer who pays for new transmission, generation, substations or resilience work. The public ledger should. For each project, disclose utility upgrades, cost allocation, curtailment agreements, emergency operating rules and the effect on other customers. Publish what happens when the site cannot restore load, and who receives the call. Now open the exit ledger. Imagine a buyer chooses Vera Rubin because the rack architecture, cooling interfaces and operating components are publicly documented. Three years later, a competing accelerator offers a better fit. What can the buyer reuse? The building may survive. The busway may survive. Some cooling infrastructure may survive. The network operating model may survive. But the answer gets murkier around compute trays, scale-up interconnects, management firmware, drivers, collective libraries, compilers, schedulers, telemetry, validated configurations and application code. The exit ledger should name each layer and assign a switching cost. For hardware, include replacement trays, cables, optics, manifolds, power shelves and spare parts. For software, include CUDA dependencies, container images, orchestration hooks, observability, security controls and model-serving code. For operations, include retraining, certification, validation, downtime and staff skills. Do not reduce this to a red or green portability badge. Give operators a bill of dependencies. NVIDIA's own announcement offers a good example of why the layers must be separated. Meta is adopting Spectrum-6 102.4-terabit-per-second Ethernet switches in a liquid-cooled network rack. Its switch runs FBOSS, Meta's open-source network operating system, through the OCP Switch Abstraction Interface. That is a genuine portability mechanism at the control layer. The physical switch remains NVIDIA hardware. The broader fabric uses Spectrum-X technology and ConnectX-9 network cards. NVIDIA says a multiplane design can scale beyond 100,000 GPUs while shifting traffic around failures. An operator should test what happens when one plane, switch, cable, network card or control service fails. It should also test whether another vendor's hardware can enter the fabric without changing the operating contract. Resilience is not the same as substitutability. The four public DSX components deserve the same practical examination. NVIDIA released tools for switch configuration, cluster-readiness testing, rack management and bare-metal provisioning. Public code can improve inspection, integration and repair. It also lets operators see where assumptions about NVIDIA hardware and services are embedded. That is useful even when the answer is: deeply. The right test is a clean-room rebuild. Can a team deploy the tools from their repositories using documented dependencies? Can it export configuration and state? Can it run without calling a private service? Can it replace one component? Can it audit privileges? Can it roll back? Are the issue trackers active, licenses clear and release artifacts reproducible? Open source becomes operationally meaningful when another party can run, inspect, modify and maintain it. A repository with one approved path and no practical migration route is transparency, not independence. The ledger also needs failure receipts. NVIDIA says its Cluster Readiness Engine stress-tests GPU clusters with real workloads before training begins. That sounds like exactly the kind of dull, valuable tool giant systems need. Publish the results. Show how many nodes failed validation, which components were replaced, how often jobs crashed, mean time to repair, spare inventory, network degradation and cooling alarms. Report useful compute delivered against installed compute. A 100,000-GPU system can lose a tiny percentage of components and still create a very large repair queue. Standards make comparison possible only when operators report comparable outcomes. The energy ledger should follow every failure. A crashed training run consumes power before it produces nothing. A throttled rack may protect equipment while extending job duration. Spare capacity improves resilience but carries embodied materials and idle electricity. Measure the whole job, not just the chip at its favorite benchmark point. The same discipline applies to water. Liquid cooling can move heat more efficiently than air cooling, especially at very high rack densities. It does not mean a facility has no water footprint. The effect depends on the loop design, heat rejection, climate, source water and whether water is consumed on site or upstream in electricity generation. Publish the cooling architecture, annual water use, peak-day demand and local watershed context. A standardized manifold does not make a dry town wet. There is a larger promise here worth protecting. If rack, power, cooling and network interfaces become common, more manufacturers can build compatible parts. Operators can avoid bespoke facilities for every generation. Repairs can become faster. Designs can improve through public review. A site built for one system may adapt to the next rather than becoming a stranded concrete monument. That is what open infrastructure can do. It should not be asked to prove something it cannot. An open facility specification does not establish competitive silicon markets. A public rack drawing does not reveal the economics of accelerators. An interoperable network layer does not guarantee portable applications. A power-efficiency claim does not establish lower total electricity use. The honest version of the story is still impressive. Several of the companies building the largest AI systems are agreeing on parts of the physical and operational foundation. They are publishing documents for factories, utilities and suppliers to use. NVIDIA is exposing more of a rack-scale platform that was once treated mostly as a finished black box. Now buyers, communities and regulators need the receipts. For every project, show total energy and water. Show grid behavior. Show failures and useful output. Show which interfaces are open, which parts have multiple qualified suppliers and which dependencies still point back to one vendor. Then price the exit. If the architecture is truly reusable, the ledger will make that value visible. If the door only opens inward, the ledger will show that too.
01
WHAT ACTUALLY CHANGED
NVIDIA contributed key Vera Rubin rack and compute-tray designs through the OCP MGX architecture
MGX 1.2 adds standardized power, cooling and interconnect interfaces for racks supporting deployments up to 250 kilowatts
AMD, Google, Meta and NVIDIA published Open Data Center revision 0.7 for 2027 and 2028 infrastructure
The Open Data Center specification gives a 12-megawatt minimum cluster baseline and says 24 megawatts is preferred
Google, Meta, Microsoft and NVIDIA published an OCP grid-disturbance specification
NVIDIA released four DSX operations components for configuration, cluster readiness, rack management and bare-metal provisioning
Meta is adopting NVIDIA Spectrum-6 102.4-terabit-per-second Ethernet switches with the open-source FBOSS network operating system
NVIDIA says its multiplane network design can scale beyond 100,000 GPUs and reroute traffic around component failures
NVIDIA and Cisco announced the proposed USFP optical module form factor for higher-density networking
Google Falcon Transport support is planned for future ConnectX-10 network cards and BlueField data-processing units
02
WHY THIS MATTERS
Common rack, power and cooling interfaces can lower manufacturing, repair and deployment friction
A facility can use open specifications while remaining dependent on proprietary accelerators and software
Efficiency per unit of work can improve while total electricity and water use increase
Multi-megawatt data centers can affect grid stability, infrastructure spending and other utility customers
Portability at one layer does not guarantee substitutability across hardware, networking and applications
Public operating tools can improve auditability without eliminating platform-specific assumptions
Standardized failure and utilization reporting would show whether installed compute produces useful work
Migration costs determine whether an open architecture creates meaningful buyer choice
Communities need facility-level energy and water evidence rather than chip-level efficiency claims alone
Open specifications gain value when multiple suppliers can implement them and operators can validate alternatives
03
WHERE IT COULD HELP
- Publish a layer-by-layer bill of dependencies for every AI factory
- Separate open specifications, open-source code, interoperable interfaces and multi-vendor supply
- Record contracted power, hourly use, peak demand, utilization and grid carbon intensity
- Report cooling design, water withdrawals, consumption and local watershed conditions
- Measure successful jobs, retries, failed runs, idle capacity and useful compute delivered
- Test whether the facility can substitute trays, switches, network cards and management services
- Price migration across hardware, software, validation, training and downtime
- Run grid-disturbance and load-restoration exercises with utilities
- Publish cluster-readiness failures, repair time, spare inventory and recurring component faults
- Rebuild public DSX tools from clean repositories and document every private dependency
- Require export, rollback and disaster-recovery tests before production approval
- Compare total cost and resource use per completed workload, not only per-chip benchmarks
KEEP A HAND ON THE WHEEL
The scale, performance and efficiency statements in the October 12 announcement come from NVIDIA and its partners. The OCP specifications establish shared design targets, not measured outcomes for a completed facility. Rack and facility openness should not be treated as proof that accelerators, networking, software or validated configurations are interchangeable. Watch for final specifications, independent implementations, multi-vendor qualification, facility-level energy and water reporting, utility agreements, failure data and credible migration tests.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 13, 2026.
PUBLICATION RECEIPT: The article distinguishes published OCP specifications and public software from NVIDIA and partner claims about scale, efficiency and future deployments.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US