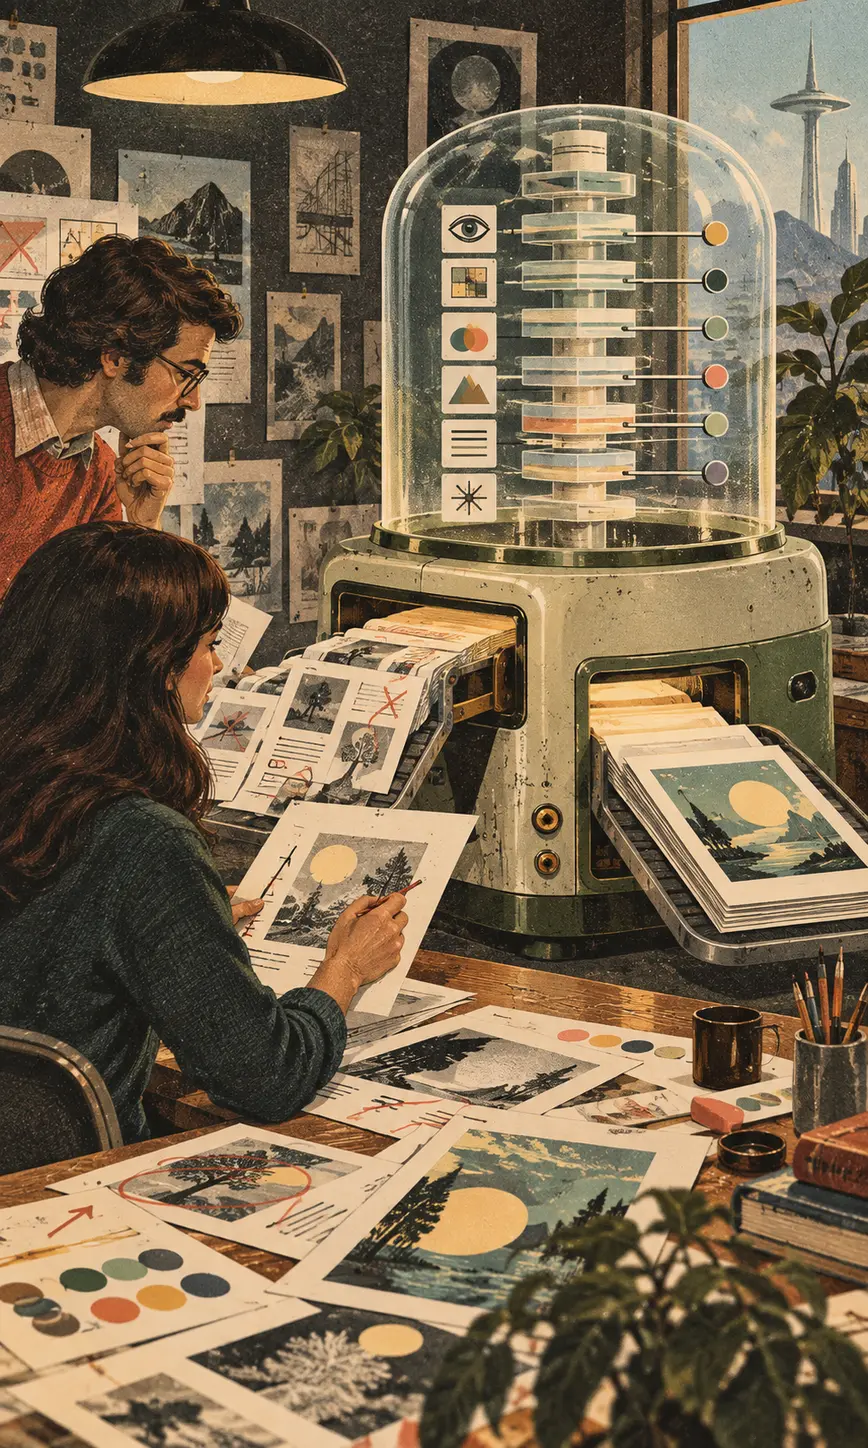
THE SIGNAL IN ONE SENTENCE
A research system learns one person's working standards from repeated feedback, then uses those standards to improve future work and judge its own output.
01
WHAT ACTUALLY CHANGED
Researchers introduced test-time adaptation through human-agent interaction, or TAHI. Instead of relying only on preferences written before a project begins, the system learns from the corrections, rejections, and refinements that appear while a person and an agent work together.
TAHI updates two things. It adapts the agent toward the individual user, including changes to context and model weights. It also maintains an evolving rubric that attempts to express the person's standards as reusable evaluation criteria.
The researchers tested the approach with 30 people completing 600 open-ended writing and visual-creation tasks. After only tens of examples, the personalized agents improved independent task success by 4.5 to 20.9 percent, depending on the setting.
The evolving rubrics also detected 16 to 22.3 percent more failures than criteria produced by language models or people alone. Some benefits generalized across users, with improvements reaching 8.8 percent, suggesting that a personal correction can occasionally reveal a broader quality rule.
02
WHY THIS MATTERS
Professionals rarely possess a complete written manual for their own judgment. They discover standards while looking at the work. The headline feels off. The chart is technically accurate but visually misleading. The evidence is strong but placed in the wrong paragraph. Those corrections contain knowledge that a generic preference form cannot capture.
Most assistants treat that knowledge as disposable conversation. The next assignment starts with another explanation of the same habits and the same avoidable mistakes. TAHI treats interaction history as training material and turns recurring judgment into a working evaluation system.
That power requires care. A model that learns your standards can become genuinely useful, but it can also memorize private work, amplify inconsistent feedback, or overfit to one irritated afternoon. Personalization needs inspectable criteria, deletion controls, version history, and a way to reject what the system believes it learned.
03
WHERE IT COULD HELP
- Teach an editorial agent recurring publication standards
- Preserve design preferences across separate projects
- Convert repeated corrections into quality checks
- Build team-specific evaluation rubrics from reviewed work
KEEP A HAND ON THE WHEEL
The evidence comes from a preprint with 30 participants across two creative domains. The reported improvements do not establish durable behavior over months, safe handling of private feedback, or resistance to contradictory and low-quality corrections. A useful product would need clear controls over what is learned and retained.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Context window
The amount of information a model can actively consider at one time.
OPEN GLOSSARY CARD
Fine-tuning
Extra training that shapes a model for a narrower job or behavior.
OPEN GLOSSARY CARD
Evaluation gate
A required test or review that a system must pass before it advances to the next stage.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 6, 2026.
PUBLICATION RECEIPT: Revision 1. Approved by Zak and published September 6, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US