THE SIGNAL IN ONE SENTENCE
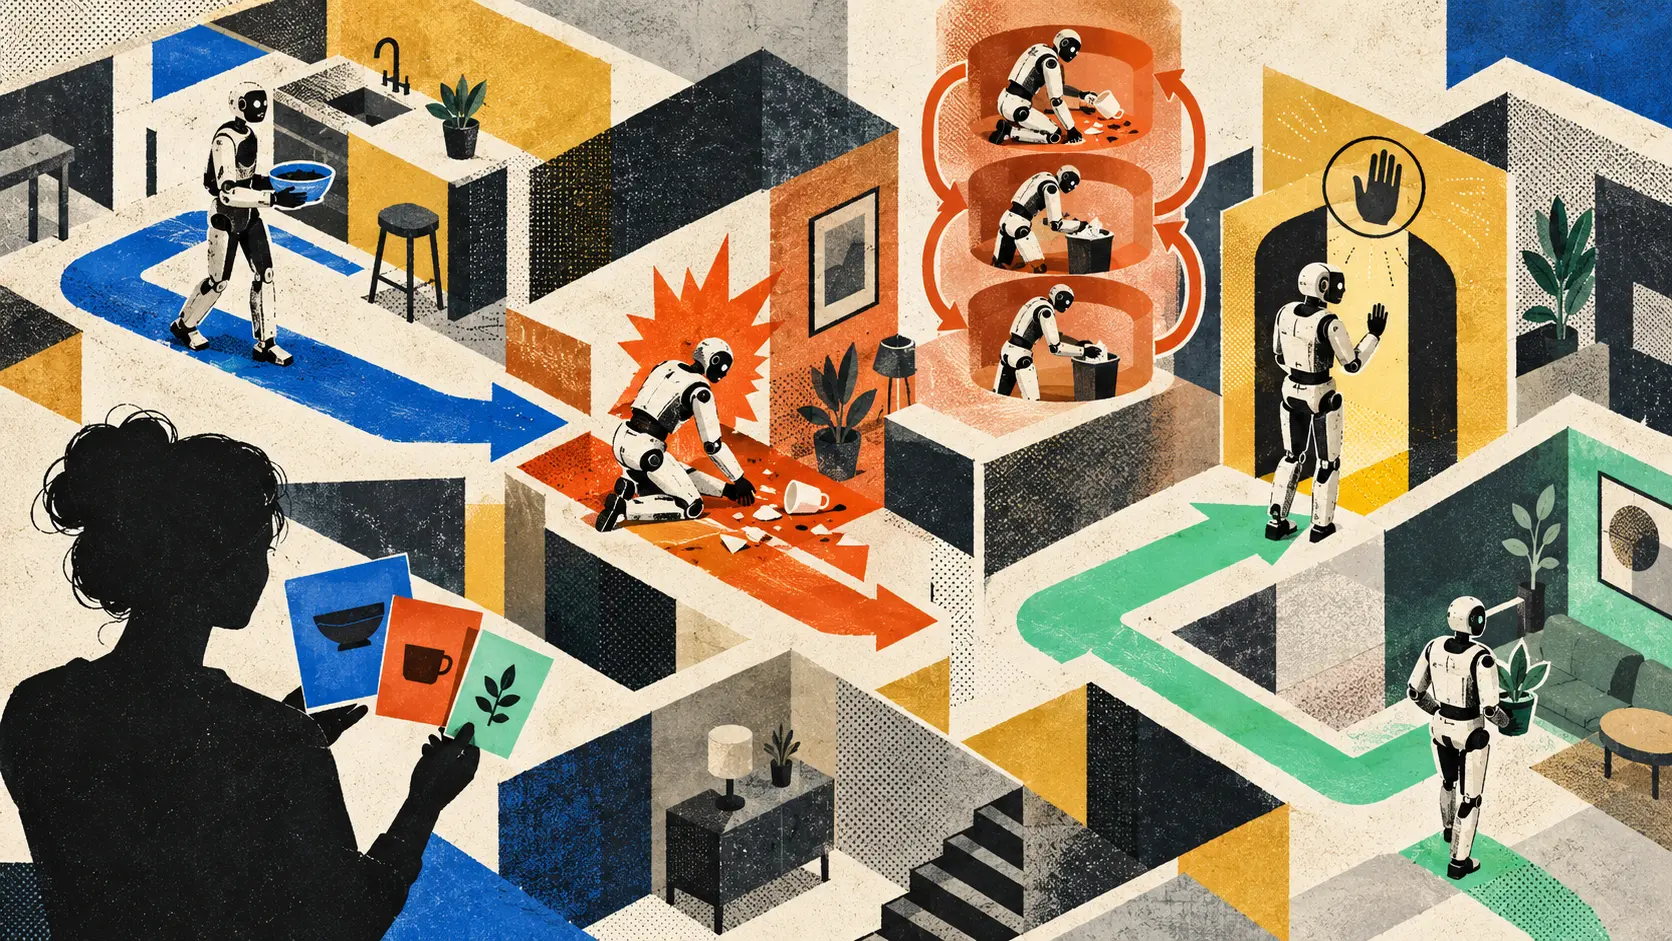
A robot that can follow a ten-step plan may still become deeply confused when someone says, "Before you do that, handle this instead." That small interruption creates a surprisingly large problem. The robot has to know whether to stop immediately or finish the atomic action already under way. It has to suspend the original sequence without losing its place, complete the inserted job, then identify the next unfinished objective from wherever it now stands. The camera view may be different. The available routes may have changed. An object that was once visible may no longer be a candidate. Simply replaying the old plan is not recovery. That is the premise of Preemptive Instruction Following with Resumption, or PIFR, a new benchmark from researchers at Hefei University of Technology. It turns interruption recovery into a measurable navigation problem instead of treating it as a conversational flourish. The useful distinction is right in the word resumption. In PIFR, resuming does not mean returning to the position where the interruption began. It means restoring the logical progress of the suspended plan, finding the next unfinished atomic task and grounding that objective again in the robot's current surroundings. Imagine a household sequence: retrieve some food, retrieve a book, then continue to a third destination. While the robot is handling the food, a new instruction arrives to organize the cabinets. The agent finishes the current atomic task, executes the higher-priority insertion, then resumes with the book. It does not blindly walk backward to an earlier waypoint and pretend nothing happened. The benchmark tests three shapes of interruption. A single interruption follows the familiar A-B-A pattern. The robot suspends a base sequence, completes one inserted sequence and returns to the base. A repeated interruption inserts multiple jobs at different points in the base sequence. The paper represents this as A-B-A-C-A. The agent has to leave and recover the same plan more than once. A nested interruption is the dangerous little matryoshka doll. The robot begins A, switches to B, gets interrupted again by C, then unwinds in last-in, first-out order: A-B-C-B-A. The inner job resumes before the outer plan can resume. That structure matters because one overall success number can hide where the agent became lost. PIFR therefore reports ordinary navigation success and path efficiency alongside separate interruption and resumption success rates. An atomic segment counts as successful when the agent terminates within 0.25 meters of a valid target viewpoint. The stage-specific measures ask whether the agent entered the inserted task correctly and whether it grounded the next unfinished task correctly when it returned. This is more than benchmark bookkeeping. On the seen-goal split of PIFR-OVON under a single interruption, the authors' PIFR-Rank system produced a higher overall success rate than the MTU3D baseline, 51.7 percent versus 49.6 percent. But its resumption success rate was lower, 49.0 percent versus 56.1 percent. If a team watched only the overall number, it could call the new system better while missing a regression in the exact capability this benchmark was built to expose. The full benchmark contains 80,417 composite episodes assembled from SG3D, GOAT-Bench and HM3D-OVON. There are 74,223 training episodes and 6,194 validation episodes. A typical episode is not short: the average contains 9.78 atomic navigation segments, with a median of eight. The three source families add different grounding demands. PIFR-SG3D uses description-based instance grounding. PIFR-GOAT includes category, language and image goals. PIFR-OVON tests open-vocabulary object-category navigation. The resulting task is not merely, "Can you remember what came next?" It is, "Can you recognize what came next from a new view, with a new active instruction and a possibly different list of plausible targets?" The authors' lightweight baseline, PIFR-Rank, trains a candidate scorer to rank valid navigation targets above distractors. It gives extra weight to decisions made at a resumption point. At inference time, the agent receives the active instruction, visual observations, navigation context and candidates produced by the navigation system. It does not receive the training-only answer labels, future tasks or execution-role annotations. The results are mixed in the useful way. PIFR-Rank beats MTU3D on overall success across all three interruption structures for PIFR-SG3D and PIFR-OVON. On PIFR-GOAT, MTU3D leads on the single-interruption setting, while PIFR-Rank leads on repeated and nested interruptions. In the nested PIFR-GOAT setting, overall success rises from 44.3 to 49.6 percent. But recovery does not decline in one neat curve as interruptions accumulate. For repeated interruptions, PIFR-Rank's first and second resumption scores fall from 32.5 to 17.5 percent on PIFR-SG3D and from 53.8 to 38.7 percent on PIFR-OVON. On PIFR-GOAT, they rise from 44.0 to 66.0 percent. In nested episodes, inner and outer recovery also vary sharply by source benchmark. The lesson is not that the second interruption is always harder. The lesson is that recovery depends on the goal type, the world representation and the precise place where the plan was suspended. That should change how embodied agents are accepted for real work. A warehouse test should not merely ask whether the robot eventually delivered every tote. It should insert a blocked aisle, a spill response or an urgent retrieval while the base plan is active. A hospital simulation should interrupt a supply run with a higher-priority request, then verify that the robot resumes the correct ward, item and permissions. A home robot should be tested when a person moves the target object during the detour. Each run needs a resumption receipt. The receipt should name the current atomic task, the suspended sequence, the inserted instruction, its priority and owner, the point at which execution was suspended, the world state on return, the next unfinished objective, the candidate targets considered and the reason one candidate won. It should record what changed while the robot was away. Did the viewpoint move? Did a door close? Did the intended object disappear? Did a new person enter the path? Did permissions or safety conditions change? Was the old target still valid but no longer visible? A system that cannot answer those questions should not silently improvise its way back into the plan. Sometimes the correct resumption action is to ask. If two identical packages remain, if the destination is now occupied or if the original instruction conflicts with the current environment, a safe system needs an explicit branch for uncertainty. Re-ground, verify and continue when the evidence is sufficient. Pause and request help when it is not. PIFR is still a simulated navigation benchmark built from existing research datasets. It does not test the full mess of physical manipulation, moving people, degraded sensors, permissions, battery constraints or consequential mistakes in an operating facility. Its results are author-reported in a new preprint. A geometrically navigable composite episode is not proof that a real robot can recover safely. The benchmark also makes a design choice worth preserving in the caution label: it lets the agent finish the current atomic task before switching. That is reasonable for many navigation sequences. It may be wrong when an emergency instruction demands an immediate stop. Production systems need a preemption policy before they need a resumption policy. The policy should define which actions are atomic, which interruptions can wait, which require an immediate safe stop and who is allowed to change priority. Only then can the recovery test ask whether the agent returned to the right work. Long plans are easy to admire in a demo because they look like persistence. Interruption reveals whether that persistence has structure. The useful robot is not the one that stubbornly completes yesterday's route. It is the one that can handle today's detour, look around again and know exactly what remains unfinished.
01
WHAT ACTUALLY CHANGED
Researchers introduced PIFR, a benchmark for embodied navigation with runtime task preemption and resumption
The benchmark includes single, repeated and nested interruption structures
Resumption means re-grounding the next unfinished task from the current state, not returning to an old position
The dataset contains 80,417 composite episodes drawn from three established navigation benchmarks
Evaluation separates overall success and path efficiency from interruption and resumption success
PIFR-Rank adds candidate-level supervision, ranking loss and extra weight for resumption decisions
02
WHY THIS MATTERS
Real robots will be interrupted by people, hazards, urgent jobs and changing environments
An agent can complete the inserted task while silently losing the original plan
Old waypoints may be invalid after a detour even when the logical objective remains the same
Aggregate task success can improve while resumption performance gets worse
Repeated and nested interruptions expose recovery failures that one A-B-A test cannot show
A visible resumption receipt gives operators evidence for when the agent continued or asked for help
03
WHERE IT COULD HELP
- Interrupting warehouse delivery routes with blocked aisles or urgent picks
- Testing hospital supply robots with priority changes and refreshed permissions
- Resuming home tasks after people move objects or close doors
- Separately scoring the inserted task, each resumption and the complete sequence
- Logging the suspended plan, current atomic task and next unfinished objective
- Re-scanning the environment before reusing an old waypoint or target
- Comparing candidate targets after the viewpoint or available routes change
- Using last-in, first-out recovery for genuinely nested instructions
- Defining which interruptions may wait and which require an immediate safe stop
- Escalating to a person when the resumed target is missing, ambiguous or newly unsafe
KEEP A HAND ON THE WHEEL
PIFR is an October 26, 2026 author-reported preprint about simulated embodied navigation. Its 80,417 composite episodes are built from existing research benchmarks and validated for geometric navigability, not real-world safety. The evaluation does not establish safe recovery around people, physical manipulation, permissions, battery limits or dynamic hazards. Aggregate success can hide weak interruption or resumption stages, and finishing the current atomic task before switching may be inappropriate during an emergency. Watch for released code and data, independent reproduction, real-robot trials, adversarial environment changes, explicit stop policies and evidence that uncertainty triggers a human handoff instead of a confident guess.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 27, 2026.
PUBLICATION RECEIPT: Benchmark construction, metrics and numerical results come from the authors and are presented as preprint findings. The resumption receipt, deployment tests, stop-policy boundary and human-handoff recommendations are Plain Signal analysis. No real-world safety conclusion is inferred.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US