THE SIGNAL IN ONE SENTENCE
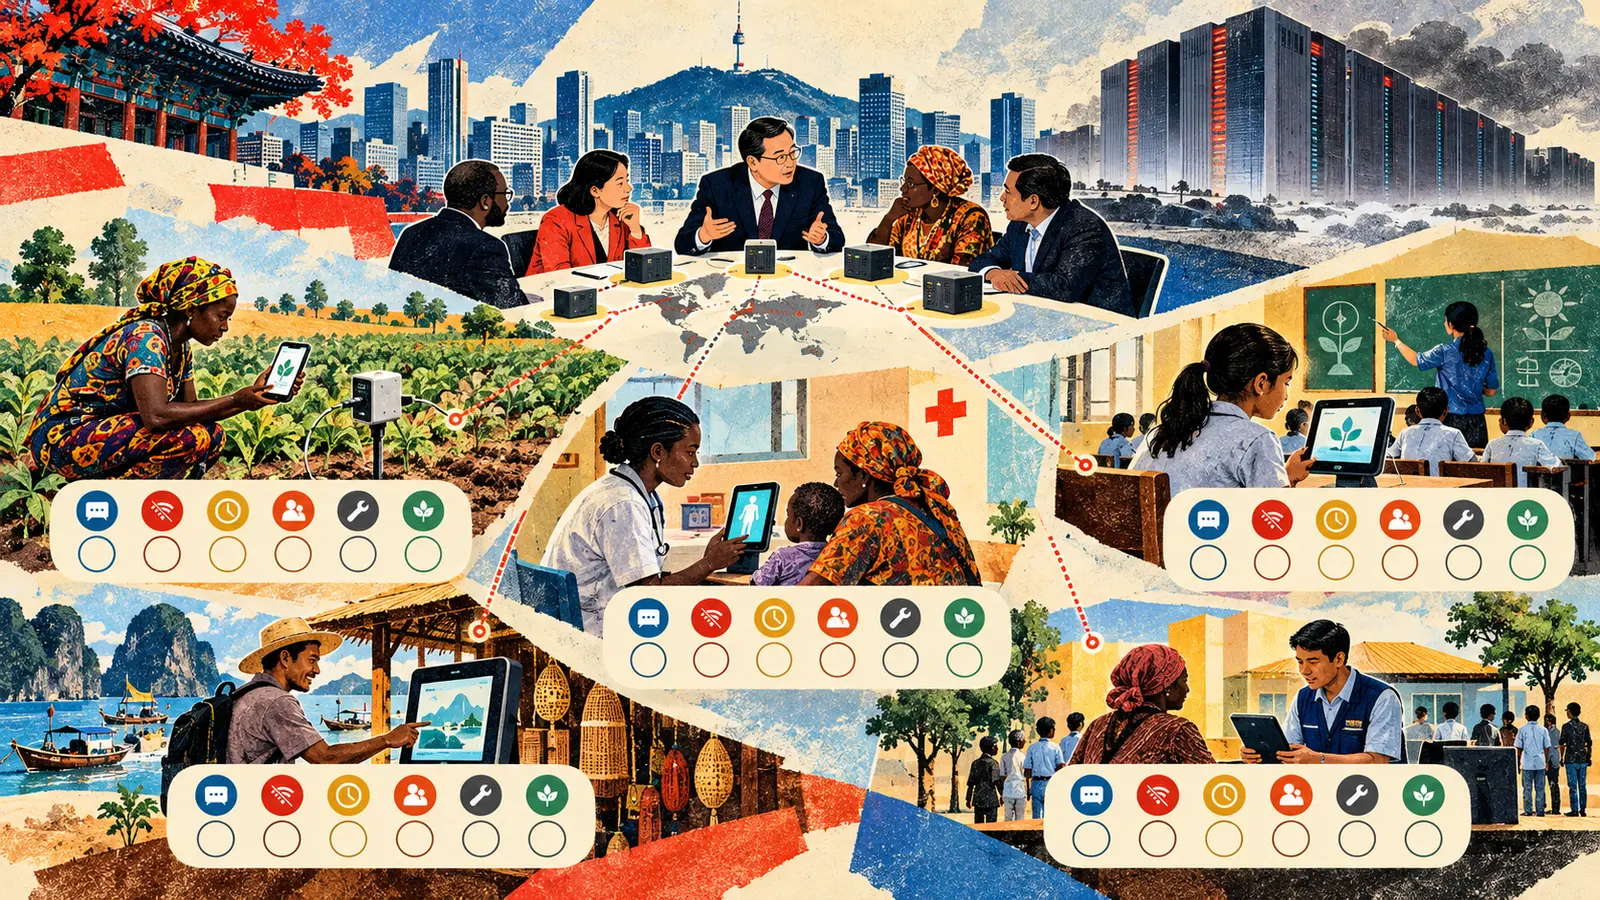
The most interesting artificial intelligence conversation in Seoul this week is not about building the largest possible model. It is about building a smaller system that solves one stubborn problem in the place where that problem actually lives. The World Bank Group and two Republic of Korea ministries opened the Global AI and Digital Summit in Seoul on October 19. The four-day program puts jobs, public services and what it calls Small AI near the center of the agenda. That phrase needs a little unpacking. The summit describes Small AI as targeted, use-case-driven technology that can work on basic phones, sensors or microcontrollers, sometimes with limited connectivity and local data. It can be predictive, generative or agentic. The point is not simply a tiny parameter count. The point is a bounded job in a constrained setting. A crop adviser that works through voice on an inexpensive phone may be Small AI. So might a clinic support tool that runs locally when the network drops, a teacher aid in a language poorly served by global systems or a sensor that helps a public utility spot a failing pump. That is a welcome change from treating every local problem as an excuse to rent the largest available chatbot. The plain signal is this: a problem-first approach can make AI cheaper, more relevant and easier to operate. But the summit program and its hackathon are a starting line, not evidence of durable impact. The impact claim needs a local scoreboard. The summit page is unusually candid about the dependencies. Small systems still need broadband where communication is required, digital literacy and trusted local institutions. Without those foundations, the World Bank says promising pilots may not scale. That warning should sit beside every showcase. The flagship Small AI session is scheduled for October 20. Hackathon winners in agriculture, health and tourism are scheduled to present on October 21. At publication time, those Seoul presentations have not happened. Their inclusion in the program shows what organizers want to explore. It does not show that any featured project has improved health, income, learning or public service delivery over time. This distinction is not pedantry. It is the difference between a demonstration and a public investment case. A demonstration asks whether the thing can work once. A local scoreboard asks whether it keeps working for ordinary people, under ordinary constraints, after the stage lights and cloud credits disappear. Start with language. Do not count a language as supported because a menu has been translated or a model can produce a polite sentence. Count whether people with different dialects, literacy levels and disabilities can understand the advice, correct it and complete the task. Measure error rates by language and region, not just in one pooled average. Then test the network. If a tool is advertised for limited-connectivity settings, publish how often it completes the job offline, how it behaves during an interrupted sync and what happens when local data becomes stale. A rural clinic cannot call a system resilient if one dropped connection silently loses a referral. Count worker time honestly. An assistant may save ten minutes at the front of a task and create twenty minutes of checking, data cleanup or appeal work at the back. Ask the teacher, nurse, extension officer or clerk how much total time changed. Include training and troubleshooting. Hidden labor is still labor. Measure the service, not the sparkle. For agriculture, the relevant question is not how many diagnoses an app generated. It is whether farmers made better decisions, avoided preventable losses or improved income across seasons without taking on unacceptable risk. For health, do not stop at a triage score. Measure whether patients received appropriate follow-up, whether clinicians could override the system and whether errors were detected before harm. For education, a local-language tutor should be judged by comprehension, teacher workload and access for students who share devices or connectivity. More generated exercises are not automatically more learning. For tourism and small business, count verified bookings, revenue distribution and costs. A recommendation engine that sends every visitor to the same already crowded street may look active while making local inequality worse. For government services, measure completion time, error rates, abandoned applications and successful appeals. A faster rejection is not a better service. Ownership belongs on the scoreboard too. Who can repair the system when the original vendor is gone? Who updates the model when seasons, prices, medical guidance or eligibility rules change? Can a local institution export its data, replace a component and continue operating? A cheap pilot can become expensive infrastructure if every update requires an overseas contract and a new procurement cycle. Total cost should include devices, connectivity, power, data preparation, staff training, security, maintenance, monitoring and complaint handling. The model bill may be the smallest line. The scoreboard also needs a fairness column. Break results down by geography, gender, disability, income, language and other locally relevant groups. A project can improve its overall average while failing the people it was supposed to reach. Aggregate success has a talent for hiding uneven service. Every deployment needs a correction path. Someone should know where to report a wrong diagnosis, bad recommendation or missing benefit. The operator should acknowledge the complaint, preserve a useful record, explain the decision and provide an appeal. Small AI does not mean small consequences. Finally, measure durability. Check the same outcomes three, six and twelve months after launch or after grant funding ends. Is the system still used? Is it still maintained? Did local staff take ownership? Did service quality hold? Did the benefit remain after free credits, visiting experts and demonstration deadlines disappeared? None of this argues against Seoul's Small AI theme. It strengthens it. The World Bank's framing recognizes that useful technology does not always need frontier scale. A local, tightly scoped tool can be easier to audit, cheaper to run and better matched to the job. Running on a familiar device, with local data and a language people actually use, can matter more than a leaderboard score. Small AI can also fail in very ordinary ways. A sensor breaks. A phone is shared. A dataset reflects one district. A voice interface misunderstands an accent. A ministry changes a rule. A vendor stops answering email. A worker learns that correcting the tool takes longer than doing the task alone. Those are not side issues. They are the operating environment. Seoul has put a useful question on the table: what if AI started with the local problem and the available tools instead of with the biggest model? Now give every showcase a public scorecard. Name the task. Publish the baseline. Test the language and network. Count the worker's full day. Measure the service outcome. Show who owns maintenance and complaints. Return after the pilot ends. The model can be small. The receipt should be big enough for the community to read.
01
WHAT ACTUALLY CHANGED
The Global AI and Digital Summit opened in Seoul on October 19, 2026
The World Bank Group is hosting the summit with two Republic of Korea ministries
The four-day program connects AI and digital technology to jobs, productivity and public services
Small AI is presented as targeted technology designed around specific local problems
The official framing includes systems that run on basic phones, sensors or microcontrollers
Limited connectivity, local data and voice or SMS interfaces are part of the design context
Featured application areas include agriculture, health, education, tourism and government
A dedicated Small AI session is scheduled for October 20
Hackathon winners in agriculture, health and tourism are scheduled to present on October 21
The official page warns that broadband, digital literacy and trusted institutions remain necessary for scale
02
WHY THIS MATTERS
A problem-first tool may fit local budgets and infrastructure better than a general-purpose model
Local languages and familiar interfaces can determine whether a technically capable system is usable
Offline behavior matters when a service is intended for places with unreliable connectivity
Worker time savings can disappear when verification and cleanup are ignored
Usage totals do not reveal whether health, learning, income or service quality improved
Averages can hide failures affecting rural users, women, people with disabilities or minority-language communities
Maintenance ownership determines whether a pilot can become dependable local infrastructure
Total cost extends beyond model inference to devices, power, training, security and support
Complaint and appeal routes matter because tightly scoped systems can still make consequential errors
Post-funding checks distinguish a durable service from a successful demonstration
03
WHERE IT COULD HELP
- Publish a baseline for the local problem before deploying a model
- Test comprehension and completion rates separately for each supported language and dialect
- Measure offline completion, interrupted synchronization and stale-data behavior
- Count training, verification, correction and escalation time in worker productivity claims
- Track service quality or human outcomes rather than generated outputs alone
- Break results down by geography, gender, disability, income and other locally relevant groups
- Calculate total cost including devices, power, connectivity, data work, security and support
- Name the local organization responsible for maintenance, model updates and data governance
- Provide a visible complaint receipt, correction process and appeal route
- Repeat the evaluation three, six and twelve months after launch or funding ends
KEEP A HAND ON THE WHEEL
Watch for evidence from the October 20 Small AI session and the October 21 hackathon showcases; published baselines and outcome measures; language-specific error rates; offline and interrupted-network tests; full labor and ownership costs; locally controlled maintenance plans; complaint and appeal procedures; disaggregated results; independent evaluation; and follow-up after pilots lose special funding or technical support.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 19, 2026.
PUBLICATION RECEIPT: This article reports the World Bank summit agenda and official Small AI framing. It treats the scheduled sessions and hackathon presentations as plans and demonstrations, not as evidence of durable outcomes. The proposed local scoreboard is analysis.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US