THE SIGNAL IN ONE SENTENCE
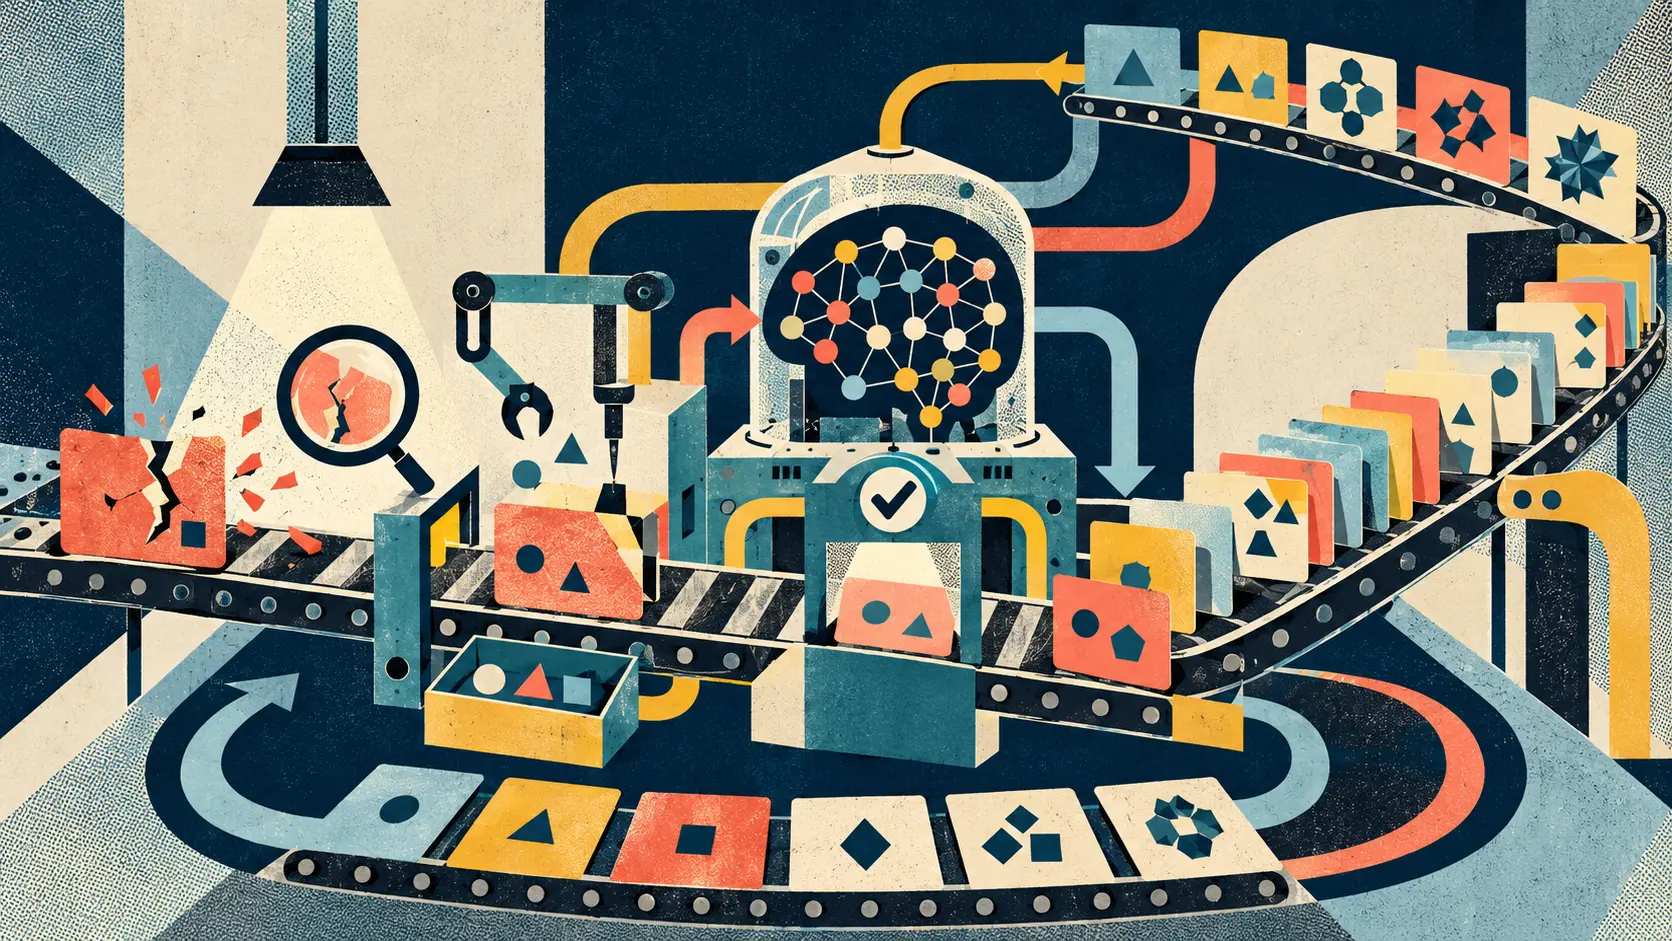
Most synthetic training data begins with a generator and a cheerful quantity target. Make ten thousand customer-service conversations. Produce fifty thousand tool calls. Vary the names. Shuffle the wording. Call it a dataset. The problem is obvious once you stop admiring the spreadsheet. A model does not need more examples of everything. It needs examples of the things it still cannot do. Those examples must also be possible inside the real environment, difficult without being absurd, and paired with a test that can tell success from a convincing-looking failure. ServiceNow CoreAI's AutoSynthData is an attempt to build that narrower and more useful loop. The system evaluates a target model in a simulated enterprise environment, studies the tasks it fails, uses a stronger teacher to identify solvable gaps, generates new tasks around those gaps, executes the tasks, tests their verifiers, repairs broken candidates and accepts the survivors for supervised fine-tuning. Then it evaluates the updated model again. The plain signal is not that synthetic data has finally become trustworthy. It has not. The signal is that training-data generation is starting to look less like bulk content production and more like a moving test laboratory. ServiceNow published the technical release on October 2, 2026. The experiments use EnterpriseOps Gym, the company's open benchmark for stateful enterprise agents. The dataset card describes containerized simulations, synthetic databases and executable SQL checks across calendar, customer service, drive, email, HR, IT service management, Teams and mixed-domain work. These are not chat questions with one expected sentence. An agent may need to inspect records, respect access policy, call several tools and leave the simulated system in the correct final state. That distinction gives AutoSynthData something valuable: a place to run a candidate task and see what actually happened. Every generated task has three parts. The system specification defines the environment, policies and initial state. The user prompt describes the requested work. The verifier checks whether the final state satisfies the request and its constraints. All three can be wrong. A generated prompt can ask for a tool the environment does not provide. The seeded database can omit a record required by the solution. A reference trajectory can fail halfway through. A verifier can approve an incomplete result or reject a perfectly valid alternative path. This is why AutoSynthData does much more than ask a large model for plausible tasks. It begins with diagnostic runs. The target model and a stronger teacher attempt evaluation tasks. The pipeline analyzes what capability is being tested, which tools and workflow structure are involved, where the target fails, how the teacher succeeds and what a correct final state must contain. Those observations become sanitized capability specification cards. The generator does not receive the original evaluation prompts, entities, trajectories or verifier details. It receives the capability card and must create new prompts, states and solution paths. That separation is an important defense against a familiar benchmark mistake: copying the exam into the study guide. It does not prove that no evaluation information leaks through a capability summary. A detailed summary can still reveal the shape of the test. But it is meaningfully different from paraphrasing the original task and calling the result new. Generation happens in two stages. The target stage creates a core set of examples around the selected capability gaps. Independent workers produce candidates, validate their structure, execute their reference solutions, ask solvers to attempt them and send failures through a bounded repair loop. The multiply stage creates variants of accepted core tasks. It changes the user request, entities, initial state, tool combinations, reference path and verifier. A multiplied sample cannot seed another multiplied sample. That last rule is a small but sensible brake on synthetic drift. Copies come from checked originals, not from copies of copies slowly wandering away from the environment. Difficulty is measured relative to the models in the loop. In the published configuration, ServiceNow favors tasks the target solves in no more than one of three trials while the stronger solver succeeds in at least two of three. Easy tasks offer little new signal. Impossible tasks offer no reliable demonstration. The pipeline hunts near the boundary between them. It also runs positive and negative verification. The positive gate replays the intended solution and asks whether the verifier accepts the resulting state. The negative gate mutates relevant parts of the expected outcome and checks that incorrect states fail. This matters because a verifier that accepts the reference solution may still be useless. If a task requires creating an account, assigning two permissions and recording approval, a weak verifier might check only that the account exists. An agent could skip the sensitive parts and still receive a reward. Negative tests look for that kind of generosity. When a candidate fails, a critic examines the prompt, initial state, trajectory, environment and verifier. It can diagnose an impossible workflow, inconsistent state, bad reference solution, weak verifier or mismatch with the intended capability. A targeted repair is attempted, then the gates run again. This is a better use of model criticism than merely asking, "Is this example high quality?" The critic has an execution result to explain. The repair has a concrete failure to address. The next run can show whether the fix worked. AutoSynthData also reviews batches rather than treating every accepted sample as an independent victory. A batch can contain valid examples and still be lousy training data. It may repeat one easy pattern, neglect a difficult capability or spend most of its generation budget on a low-yield family. The meta-review looks across accepted tasks, rejected tasks and critiques. The controller tracks coverage, reduces effort in overrepresented regions and pushes generation toward gaps. That is the curriculum part of the system. The curriculum does not sit still. After fine-tuning, tasks that the target now solves reliably should lose priority. Persistent failures should attract the next round of examples. The useful distribution moves with the student. ServiceNow tested the approach in two EnterpriseOps Gym settings. For the Hybrid domain, the target was Gemma-4-26B-A4B-it and the teacher was Qwen3.8-27B. AutoSynthData generated 2,000 accepted training samples in about eighteen hours. ServiceNow reports that the best supervised fine-tuning checkpoint improved mean Pass@1 by 7.2 percentage points, a 35 percent relative improvement, and raised verifier success from 63.01 percent to 68.55 percent. The release says this closed 59 percent of the original mean Pass@1 gap between the target and the reference model. For IT service management, the target was again Gemma-4-26B-A4B-it and the teacher was DeepSeek-V4.1-Flash. The pipeline produced 1,994 samples in sixty-six hours. Mean Pass@1 rose from 18.77 percent to 27.18 percent. ServiceNow says the ITSM run came first, used a larger teacher and preceded throughput improvements that made the later Hybrid run faster. Those numbers are interesting. They are also bounded. This is a controlled experiment in two domains of one benchmark, with selected target and teacher models. The reported gains do not establish that AutoSynthData will improve every model, transfer to a company's live software or survive messy production data. The release does not provide an independent replication, a full cost accounting, a comparison against equally sized human-authored training sets or a measure of whether the tuned model regressed on unrelated capabilities. There is also a metric wrinkle worth keeping straight. Mean Pass@1 and verifier success are not the same thing. A benchmark can average performance across task groupings or runs differently from a raw share of verifier checks passed. The release reports both for Hybrid, and the values should not be casually blended into one success rate. The more important limitation sits inside the verifier. AutoSynthData is only as grounded as the environment and checks allow. Executable SQL verification is stronger than asking another language model whether the answer feels right. It can inspect whether records were actually created, moved or modified. But even deterministic code can encode an incomplete idea of success. A database can show that a calendar event exists without showing whether a human understood why it was scheduled. It can prove a ticket was reassigned without proving the right person should own it. It can confirm a policy field while missing harm created outside the tables the benchmark observes. The negative gate helps. It cannot enumerate every wrong outcome. Teacher quality is another ceiling. The pipeline chooses tasks partly because a stronger solver can complete them and provide demonstrations. If the teacher's path is inefficient, brittle or subtly noncompliant, supervised fine-tuning can teach the target that behavior. If both models share the same blind spot, the curriculum may never name it. The teacher is not an oracle. It is a model with better scores in this setup. Generated realism also deserves skepticism. EnterpriseOps Gym uses synthetic databases inside isolated containers. That is excellent for reproducibility and much safer than turning experimental agents loose on payroll or customer accounts. It is not the same as a live organization full of contradictory tickets, undocumented customs, stale access rules, surprising integrations and people who change their minds halfway through a request. Teams considering this pattern should start with the environment, not the generator. Build a resettable simulator. Define the state that matters. Version the tool schemas and policies. Write deterministic checks for outcomes that can be expressed precisely. Add negative cases. Preserve the execution trace. Make repair attempts visible. Keep a holdout set that never informs the capability cards. Then audit what the system rejects. Rejected examples are not trash. They reveal missing tools, confusing policies, brittle verifiers and parts of the workflow the generator cannot model. A generation pipeline that quietly discards ninety percent of one capability family may be pointing at a broken environment specification, not merely a stubborn model. Human review belongs at the boundaries. Experts should inspect capability cards before a large generation run, sample accepted and rejected tasks, review verifier logic for high-impact actions, and test tuned checkpoints on unrelated work. Production deployment needs separate safety evaluation. Passing a synthetic enterprise gym does not authorize an agent to modify real records without oversight. The most useful idea in AutoSynthData is not synthetic scale. It is allocation. Training examples are expensive even when software writes them. They consume teacher inference, execution time, verification effort, fine-tuning compute and reviewer attention. Spending that budget on tasks the model already solves is wasteful. Spending it on impossible tasks is worse. AutoSynthData tries to spend near the current edge of competence, with an executable receipt for each example. That is a promising direction for agent training. The model fails. The failure becomes a specification. The specification becomes a task. The task must survive reality checks. The surviving examples become a lesson. Then the exam moves again. Not infinite data. A curriculum with a reason for being there.
01
WHAT ACTUALLY CHANGED
ServiceNow CoreAI released AutoSynthData, a pipeline that turns target-model failures in an agent environment into checked synthetic training tasks.
The system distills diagnostic runs into sanitized capability cards rather than sending original evaluation prompts, entities, trajectories or verifier details to the generator.
Candidates pass environment execution, solver-based difficulty selection, positive verification, negative verification and bounded critique-and-repair loops.
A target phase builds vetted core examples, while a multiply phase creates variants that cannot recursively seed further variants.
Batch-level review tracks coverage, repetition, rejected samples and low-yield task families to redirect later generation.
ServiceNow reports gains after supervised fine-tuning in the Hybrid and ITSM domains of EnterpriseOps Gym.
02
WHY THIS MATTERS
Synthetic data becomes more useful when it targets measured capability gaps instead of adding generic volume.
Executing tasks in a resettable environment can catch impossible requests, broken reference paths and mismatches between prompts and state.
Positive and negative tests make verifiers harder to satisfy with incomplete or incorrect outcomes.
Difficulty selection focuses generation near a target model's current frontier, where a stronger teacher can still provide a useful demonstration.
A curriculum that moves after fine-tuning can avoid repeatedly training on skills the model has already learned.
The same pipeline can expose weak policies, missing tools and unreliable environment specifications before a model reaches production.
03
WHERE IT COULD HELP
- Create targeted supervised fine-tuning sets for agents that work across tickets, calendars, email, HR systems and customer records.
- Turn recurring production failure patterns into sanitized capability specifications without copying live prompts into training data.
- Generate multiple executable variants of a rare but important workflow while controlling how far variants drift from vetted seeds.
- Test reference solutions and final-state verifiers inside resettable containers before accepting an example.
- Use negative mutations to discover verifiers that reward partial completion or ignore policy constraints.
- Balance a training set by capability coverage rather than accepting whichever task families are easiest to generate.
- Route failed candidates through diagnosis and targeted repair instead of regenerating blindly.
- Preserve rejected-task analytics to find broken environment rules, missing tools and low-yield generation targets.
- Re-evaluate a tuned checkpoint and move the next generation round toward persistent weaknesses.
- Keep separate holdouts and regression suites to test whether local gains damage unrelated capabilities.
KEEP A HAND ON THE WHEEL
The evidence comes from ServiceNow's own controlled EnterpriseOps Gym experiments, not an independent replication or a live production deployment. Results cover selected target and teacher models in Hybrid and ITSM environments; they should not be generalized to every agent, company or workflow. Synthetic task quality depends on the system specification, generator, teacher, reference solver and verifier. Deterministic SQL checks can still encode incomplete notions of success, while negative tests cannot cover every wrong outcome. A stronger teacher may contribute its own brittle or noncompliant behavior. The release does not report a full cost comparison with human-authored data, broad capability regressions or long-term production outcomes. Watch for released AutoSynthData code, independent reproductions, ablations against random and human-curated curricula, contamination audits, cross-environment transfer, cost per accepted sample, reviewer disagreement and evidence that gains persist outside the benchmark.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 4, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US