THE SIGNAL IN ONE SENTENCE
The most interesting part of Shiksha Copilot is not that an AI wrote lesson plans. It is that teachers kept getting between the draft and the classroom. Microsoft Research added the study to its publication site on October 10 after the paper received an honorable mention at CSCW 2026. That recognition is new. The classroom evidence is older. The system was deployed from December 2024 through March 2025, the paper was first posted in July 2025 and its latest arXiv revision is dated March 11, 2026. Those dates matter because a conference award can make an old pilot look like a new rollout. This is better read as a newly recognized study with a practical result: an AI-assisted workflow reportedly reduced paperwork and planning time for teachers in Karnataka public schools, but it worked because educators curated the material before other teachers adapted it. The study involved 1,043 teachers across 757 schools in 35 educational districts, plus 23 curators. It covered grades 5 through 10 in science, mathematics, social science and English. The schools were Kannada-medium, with some also offering English-medium classrooms, and many had limited digital infrastructure and teaching materials. The workflow had two human checkpoints before a lesson reached students. First, language-model tools drafted learning objectives and English lesson plans using curriculum material retrieved through a RAG system. Fifteen English-medium curators reviewed objectives, accuracy, pedagogy and whether activities could work in low-resource classrooms. The approved plans were translated into Kannada, where eight Kannada-medium curators reviewed grammar, terminology and style. Teachers then opened the curated plans on a mobile-friendly web tool, copied them and adapted them for their own classes. That is less like an automatic teacher and more like a small publishing operation. The paper reports that teachers saved an average of 2.02 hours per week on lesson planning. More active users reported 2.64 hours saved, compared with 1.50 hours among less active users. Teaching-demand stress fell by an average of 0.72 points on a seven-point scale, a small effect. Teachers also described using the plans for required documentation and for activity-based teaching ideas that did not depend on classroom devices. Useful findings. Not a randomized verdict. The time and stress figures came from pre- and post-intervention surveys. The deployment lasted part of one academic year. The study was confined to Karnataka, and the researchers did not measure student learning outcomes. Teachers who used the tool more may differ from teachers who used it once. The standard deviations around reported time savings were large. Treat the averages as evidence worth testing, not a universal promise that every teacher gets two hours back. The Kannada edit trail is the sharper result. In the researchers' analysis of 26 Kannada-medium lesson plans across three subjects, curators edited 94.4 percent of content blocks. Only 2.5 percent of the edited blocks involved formatting alone. Mathematics plans had edits in 99.0 percent of blocks, science 97.2 percent and social science 88.9 percent. The underlying problem was not that Kannada could not carry technical ideas. It was that literal translation produced awkward sentences, imprecise terms, unnecessary code mixing and vocabulary that did not match textbooks. Human curators replaced near-miss words with the terms students would actually encounter and rewrote sentences that were grammatically plausible but confusing. That distinction should travel far beyond Karnataka. A model can produce a translation that looks complete while a local educator sees three different failures: the term is wrong for the subject, the sentence is wrong for the classroom and the example is wrong for the place. A generic fluency score may miss all three. The person reviewing the work is not adding cultural decoration. The reviewer is repairing the product. The English plans needed less editing in the study, but that should not be mistaken for proof that they were perfect or that English is naturally better suited to AI. The system was designed English-first, then translated into Kannada. Its models, source materials and orchestration gave English an architectural head start. If an education system wants equal quality across languages, translation cannot be the last mile after the important work is finished. Local-language teachers need a role in the curriculum corpus, terminology list, evaluation set, product interface and release decision. Their edits should become structured evidence for the next version, with attribution and review, rather than disappearing into a private document or a teacher's memory. The platform logs show why that last point matters. Teachers created 5,544 plans from curated material, including 1,480 Kannada plans. Yet only a small fraction were edited on the platform. Interviews suggested experienced teachers often adapted plans mentally or through other resources without recording the changes. Low recorded editing does not equal blind acceptance. It may mean the logging surface did not capture the real work. That is a familiar trap in workplace AI. Product analytics can count clicks, drafts and saved documents. They struggle to see the correction made aloud, the example swapped at the blackboard, the missing activity abandoned after looking around the room or the explanation simplified because students were tired. The teacher's most important contribution may happen after the software stops observing. Shiksha Copilot's mobile design was a sensible response to limited infrastructure. Teachers could prepare material during a commute or spare moment rather than staying at a desktop after school. The plans also suggested activities using ordinary local materials. That practical restraint matters. An activity that assumes one device per student is not helpful in a room without reliable connectivity. But convenience can hide a new workload. Someone still has to maintain textbook editions, curriculum mappings, retrieval sources, translation models and approved terminology. Someone has to examine corrections, resolve disagreements among curators, test regenerated content and remove plans when a rule or textbook changes. If those jobs land on teachers as invisible extra work, the system has moved the burden instead of reducing it. The 23 curators were the quality infrastructure. A serious scale-up should budget for them as such. That means publishing the staffing ratio, review time per plan, disagreement rate, correction backlog and pay for language and subject expertise. It means measuring whether a teacher can see who approved a plan and when. It means preserving the draft, the edit, the reason and the final classroom version so a bad term can be traced and corrected across related lessons. The next evaluation should put student learning beside teacher workload. Choose a defined set of grades, subjects and learning objectives. Randomize or otherwise create a credible comparison among existing planning, curated AI assistance and any lighter-weight template alternative. Measure preparation time, after-hours work, stress, plan quality, classroom implementation and student learning. Track whether the effect persists over a full academic year and whether schools with fewer staff experience the same benefit. Language quality needs its own scorecard. Use hidden samples written and reviewed by Kannada educators. Test terminology, factual accuracy, age appropriateness, naturalness, curriculum alignment, regional variation and the ability to abstain when the source material is insufficient. Report each dimension by subject instead of blending everything into one quality number. The system should also make human authority visible. A curator needs to reject or quarantine a draft, not merely polish it. A teacher needs to replace an activity without fighting the interface. A school needs a correction route. Researchers need to distinguish a model-generated block, a curator-approved block and a teacher-adapted block. Families and students should never be told that a lesson is trustworthy merely because an AI and an unnamed reviewer touched it. The plain signal is that the useful unit here is not the model. It is the review chain. Machine drafts can reduce the blank-page burden. Retrieval can keep plans closer to the curriculum. Curators can repair content, language and feasibility. Teachers can fit the plan to the students in front of them. Evaluation can reveal whether the whole chain saves time and improves learning. Remove the curators and Kannada quality drops. Remove teacher adaptation and the plan loses the room. Remove outcome measurement and the project cannot say whether convenience became education. That is not an argument against the tool. It is the reason this study is worth reading. Shiksha Copilot did not make teachers disappear. It made their hidden editorial labor easier to see.
01
WHAT ACTUALLY CHANGED
Microsoft Research listed the Shiksha Copilot study on October 10 after it received an honorable mention at CSCW 2026
The recognition is current, but the deployment ran from December 2024 through March 2025 and the latest arXiv revision is dated March 11, 2026
The mixed-methods study involved 1,043 teachers in 757 schools across 35 Karnataka educational districts and 23 educator curators
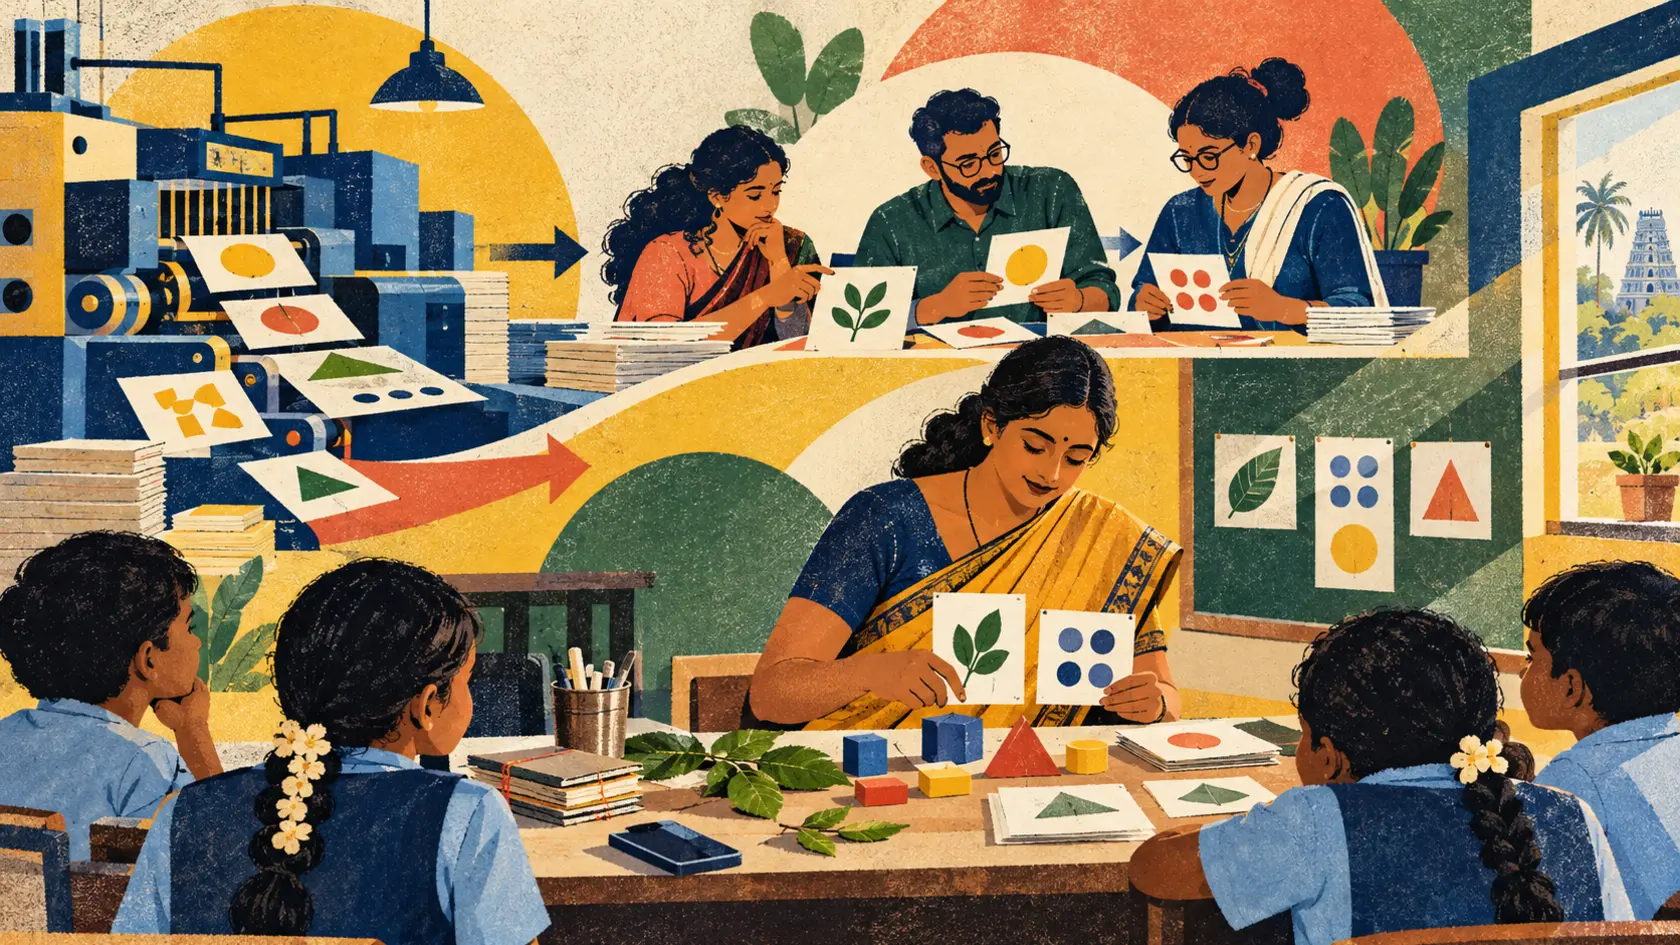
English lesson plans were drafted with language models and curriculum retrieval, reviewed by English-medium curators, translated into Kannada and reviewed again by Kannada-medium curators
Teachers reported saving an average of 2.02 hours per week on lesson planning, with a large spread across participants
Teaching-demand stress declined by an average of 0.72 points on a seven-point scale, which the paper characterizes as a small effect
Curators edited 94.4 percent of content blocks in the analyzed sample of 26 Kannada-medium plans, largely for substantive language issues rather than formatting
The study did not measure student learning outcomes and covered only part of one academic year in Karnataka
02
WHY THIS MATTERS
Teacher workload is a real product constraint, so even modest time savings can matter when they survive a full-year evaluation
An English-first pipeline can create an architectural quality gap that local-language reviewers must repair
Curriculum terminology, natural phrasing and classroom feasibility require language and subject expertise that generic fluency scores may miss
Human curation is part of the operating system, not a ceremonial approval click added after generation
Platform logs can undercount teacher adaptation when changes happen mentally, verbally or through off-platform resources
Reducing paperwork is not the same as improving learning, so teacher outcomes and student outcomes must be measured separately
Mobile access and low-tech activity ideas can make assistance more usable where connectivity and classroom devices are limited
Scaling the tool requires a funded plan for curators, curriculum updates, correction handling, audit records and language-specific evaluation
03
WHERE IT COULD HELP
- Education departments can begin with bounded lesson-plan drafting rather than automated grading or student decisions
- Curriculum teams can maintain versioned retrieval sources linked to grade, subject, textbook edition and learning objective
- Language reviewers can build approved terminology lists and hidden evaluation sets for each subject
- Curation interfaces can preserve the generated draft, human edit, reason, reviewer and approval date
- Teachers can receive editable plans with offline-friendly activities and a clear route to reject or report weak material
- Program managers can measure preparation time, after-hours work, review burden and correction backlogs across an entire school year
- Researchers can compare curated AI assistance with ordinary templates and existing planning, then measure student learning separately
- Product teams can collect voluntary, reviewed classroom corrections without treating every live interaction as training data
- School leaders can publish staffing ratios and pay for curators so quality work does not become invisible teacher labor
- Multilingual projects can design directly in local languages instead of assuming translation will produce equal quality
KEEP A HAND ON THE WHEEL
The current event is recognition at CSCW 2026 and Microsoft Research's October 10 listing, not a new statewide deployment. The cited study covered December 2024 through March 2025, was first posted in July 2025 and was revised March 11, 2026. Reported planning time and stress changes rely on pre- and post-intervention surveys rather than a randomized comparison. The average weekly time saving had substantial variation. The study covered grades 5 through 10 in Karnataka and did not measure student learning outcomes. The 94.4 percent Kannada edit rate comes from 26 plans across three subjects, not every Kannada plan in the deployment. Product architecture and performance claims are reported by the research team. Watch for a full-year comparison, independent replication, student outcomes, language-specific evaluation, curator workload and evidence that corrections improve later versions.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Retrieval-augmented generation
A method that retrieves material from a selected source collection and supplies it to a generative model as context for an answer.
OPEN GLOSSARY CARD
Human control
The practical ability and authority of people to understand, direct, interrupt or stop an automated process before unacceptable harm occurs.
OPEN GLOSSARY CARD
Grounding
Connecting an AI answer to specific outside information that can support it.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 11, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US