THE SIGNAL IN ONE SENTENCE
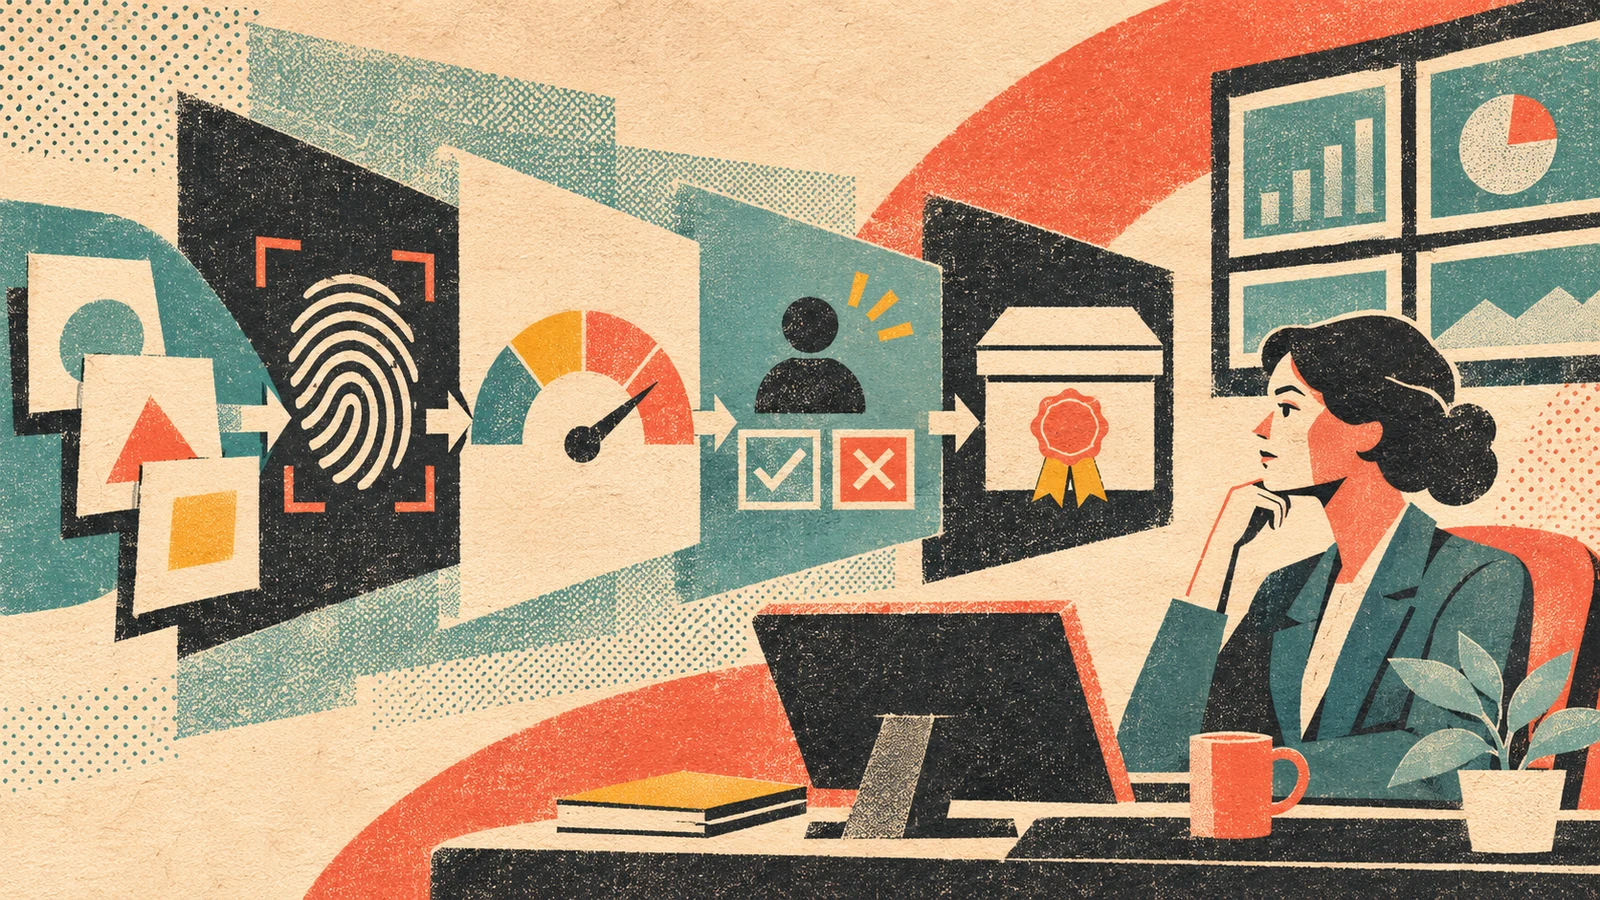
This article discusses systems used to detect child sexual abuse material. It does not describe abusive imagery. The most important word in OpenAI's new classifier is not AI. It is potential. On November 16, OpenAI released an image classifier for approved child-safety organizations. It is designed to identify images that may be child sexual abuse material, commonly shortened to CSAM, including potentially novel or AI-generated material that known-content matching may not catch. The classifier is available through the OpenAI Moderation API at no cost after an organization applies, is verified and completes onboarding. OpenAI says it was developed with assistance from the National Center for Missing and Exploited Children. It returns two separate signals: likely-csam and likely-csam/gen-ai. Those labels sound decisive. They are not verdicts. OpenAI's API documentation says the category scores run from zero to one, have no units and should not be read as calibrated probabilities. A score of 0.8 does not mean there is an 80 percent chance that an image belongs to a category. The model card says the AI-generated signal also does not verify where an image came from. The classifier can help a trained reviewer decide what to inspect next. It cannot establish that an image is illegal. It cannot determine the legal definition that applies in a particular jurisdiction. It cannot decide whether a report is required. It does not automatically send a report to authorities. That boundary is the product. Without it, a prioritization tool can quietly become an accusation machine. Start with the job the classifier is actually built to do. Known-content hash matching is very good at finding a previously confirmed image or a close transformation of it. A perceptual hash acts like a durable visual fingerprint. It can recognize related copies even when an image has been resized or lightly edited. That approach has a deliberate blind spot: it cannot match a genuinely new image that has no known fingerprint. OpenAI's classifier is intended to add another signal for that unfamiliar material. It uses a visual encoder to turn an image into a numerical representation, then a smaller classifier maps that representation to the two risk scores. The model card describes the design as an internal CLIP image encoder plus a three-layer multilayer perceptron. The company says it selected that architecture because it balanced generalization to unseen data with processing speed in internal evaluation. That is useful context, not permission to skip a workflow. The safe path begins before an API request. First, route any already confirmed material through the organization's established handling and reporting process. OpenAI explicitly says not to submit known CSAM to this service. Hash matching should handle known material. The classifier should examine imagery that has not already been confirmed. Second, decide why the image is being scored. Is the system prioritizing a human-review queue? Is it blocking an upload while a review happens? Is it restricting an account? Is it preserving material for an investigation? Is it helping determine whether content enters a legally required reporting process? Those actions do not deserve one universal threshold. A threshold that is reasonable for placing an image farther up a private review queue may be reckless for automatically closing an account. A preventive block may require a different balance than an investigator's triage list. A report to a hotline or authority still requires trained, appropriately authorized human review. Write the action beside the threshold. Do not store a naked number called 0.996324 and let future employees guess what it means. Record the model snapshot, category, threshold, intended action, evidence supporting that choice, reviewer requirements, escalation path and date of approval. OpenAI reports default thresholds of 0.996324 for likely-csam and 0.90 for likely-csam/gen-ai in the model card. Those are the company's launch choices for its evaluation and product context. They are not universal laws of moderation. Third, benchmark on the service's own representative traffic. OpenAI evaluated the classifier on a held-out set of about 46,849 access-controlled images, a roughly 1.25 million-image open-web sample used as a proxy for negative examples, sampled ChatGPT traffic and data supplied by alpha partners. That is more informative than a single polished accuracy number. It is still not your distribution. A family photo service, an art generator, a medical education platform and a general social network receive different images. They have different rates of abusive material, different legal duties and different costs when a safe image is flagged. The model card makes an important statistical point: when abusive material is rare, even a small false-positive rate can produce more incorrect flags than correct ones. The precision measured on a specially constructed evaluation set can fall when the same system meets real traffic. So run two tests. For incremental detection, take images that existing systems did not identify. Let trained reviewers examine classifier flags and measure whether the new signal finds additional true cases. For review volume, take the stream already routed to people. Measure whether the classifier can reduce irrelevant reviews without losing cases the existing process would have found. Count the burden as carefully as the detection. Track how many images are flagged, how many reviewers must inspect, how long each review takes, how many cases are escalated, how many are later reversed and how often reviewers disagree. Measure the queue at the busiest hour, not only the daily average. OpenAI says that, in one evaluation of user-uploaded images, the new classifier flagged 48 percent fewer images while finding roughly the same number of abusive images as its existing tool. It also says flagged images were about twice as likely to contain abuse. Those are OpenAI's results on OpenAI's evaluated traffic. They are promising evidence for testing the tool. They are not a service-level guarantee. Named early partners reported additional results. OpenAI says reviewers at fal confirmed 72 percent of high-confidence flags as novel CSAM, invideo AI found that one in four flagged cases led to a ban and SafetyKit detected 90 percent of a test set involving drawings or animations that sexualize children. Again, those figures describe particular partner tests. They do not share one population, one threshold or one outcome definition. Do not average them into a pretend global score. Fourth, inspect who the classifier misses. OpenAI's held-out demographic analysis found meaningful recall differences. At the default likely-csam threshold, the model card reports 61.27 percent recall for examples tagged Black, compared with 84.48 to 90.32 percent for the other reported race tags. It reports lower recall for male-tagged than female-tagged examples and lower recall for infant-tagged than prepubescent-tagged examples. The tags were assigned by an LLM annotator, some groups were small and OpenAI calls the results directional. That caveat matters. So do the disparities. Do not solve this by lowering one threshold and declaring fairness complete. A lower threshold can raise recall while sending more false positives to people. Test subgroup performance, error severity, reviewer capacity and downstream actions together. The question is not only whether the model makes the same number of mistakes across groups. It is what happens after each mistake. A false negative can leave abuse undiscovered. A false positive can expose innocent family, medical, educational or documentary imagery to a sensitive review process. An account restriction can affect a person who did nothing wrong. A mistaken provenance label can turn suspicion about an image into a false claim about how it was made. Fifth, protect the human reviewers. Human review is not a magic phrase that makes the rest of the system safe. It is difficult work performed by real people. Restrict access to trained and authorized staff. Minimize the number of people who must see sensitive material. Use secure review environments, access logs, least-privilege permissions, clear escalation rules, time limits, rotation, wellness support and a way for reviewers to stop without penalty. Do not place images in ordinary ticketing tools, chat threads, email attachments or analytics exports. Store only the identifiers and derived data each role needs. Keep retention rules aligned with legal obligations and the organization's evidence-handling process. OpenAI says images submitted to the classifier API are processed without retention and are not used for training or evaluation. That reduces one handling concern at the model endpoint. It does not govern the copies in the deployer's storage, logs, screenshots, reviewer tools or backups. Map the full path. For every image, document where it arrived, which systems copied it, which hash service checked it, whether it was sent to the classifier, which model snapshot and threshold applied, who reviewed the result, what action followed and when each copy is deleted or preserved under lawful authority. Sixth, preserve an appeal and correction path wherever a person or account can be affected. The classifier will make false-positive and false-negative errors. OpenAI says so plainly. If a flag contributes to blocking an upload, suspending an account or limiting access, people need a way to contest the action without being forced to re-upload sensitive content through an unsafe channel. A second authorized reviewer should see the evidence and the policy basis. Corrections should flow back into threshold review and error analysis. Do not let the raw score become a permanent reputation marker. The category score is meaningful only within the same category and model snapshot. It may change when the classifier changes. It should not travel between systems as if it were a universal probability or legal fact. Seventh, keep video outside the promise. The API accepts one still image at a time. The model card says the classifier has not been tested on video frames. Sampling a frame every second and combining the scores may sound easy, but it creates a different system with different recall, false positives and adversarial gaps. Evaluate video separately before using the still-image classifier that way. The same caution applies to provenance. The likely-csam/gen-ai signal indicates that an image resembles the model's AI-generated category. It is not a watermark checker, a chain-of-custody record or proof that a generative model made the image. Treat it as a routing signal. Never call it forensic attribution. Finally, publish an internal decision ledger. The ledger should contain the purpose of the deployment, approved organizations and roles, model name, API version, thresholds by action, test sets, subgroup results, review capacity, false-positive and false-negative analysis, legal review, retention rules, incident history, appeal outcomes and the date of the next reassessment. Update it when traffic changes, when abuse patterns change, when the model snapshot changes or when reviewer disagreement rises. OpenAI's release matters because novel and AI-generated abusive imagery can evade databases built around already known material. Giving vetted organizations another signal can help them find cases that would otherwise remain buried. But a classifier is not the conscience, the investigator or the court. It is a queueing instrument in a layered child-safety system. Use the hash first. Use the score to prioritize. Use trained people to judge. Use the law and established process to decide what happens next. Protect the reviewers. Protect innocent users from the cost of error. Keep the audit trail. The model can point to the next door. A responsible organization still has to decide whether, why and how to open it.
01
WHAT ACTUALLY CHANGED
OpenAI released the CSAM Image Classifier on November 16, 2026 for approved organizations through the Moderation API.
The classifier returns separate likely-csam and likely-csam/gen-ai risk signals for one still image.
OpenAI says access is available at no cost after application, verification, onboarding and acceptance of applicable terms.
The model was developed with assistance from the National Center for Missing and Exploited Children.
The classifier is intended to help find potentially novel or AI-generated material that known-content hash matching may miss.
The API documentation says category scores are unitless signals, not calibrated probabilities or universal thresholds.
The model card reports default launch thresholds of 0.996324 for likely-csam and 0.90 for likely-csam/gen-ai.
OpenAI says submitted images are processed without retention and are not used for training or evaluation.
The API accepts one still image at a time and does not support inline moderation or the Batch API.
OpenAI says the classifier has not been evaluated on video frames.
02
WHY THIS MATTERS
Known-content hashes can identify confirmed imagery and close transformations but cannot match genuinely new material without a prior fingerprint.
Novel and AI-generated abusive imagery can increase the amount of harmful content that requires detection and trained review.
A risk score can prioritize scarce reviewer attention without making the legal or factual determination itself.
Rare-event detection can generate many incorrect flags even when a model performs well on a constructed evaluation set.
A false negative can leave abuse undiscovered, while a false positive can expose innocent family, medical, educational or documentary imagery to sensitive review.
The model card reports demographic recall differences that deployers need to evaluate on representative traffic.
Reviewer volume, exposure and wellness are operational safety measures, not secondary staffing concerns.
The AI-generated signal does not verify provenance and should not be treated as forensic attribution.
Thresholds suitable for queue prioritization may be unsuitable for account enforcement, blocking or reporting.
Human review remains necessary before classifier-based reports to NCMEC or another hotline.
03
WHERE IT COULD HELP
- Send known confirmed material through established hash-matching, response and reporting processes instead of the classifier API.
- Define the exact action attached to each classifier threshold before deployment.
- Benchmark incremental detections on imagery that existing systems did not identify.
- Measure reviewer volume, review time, escalation rate, disagreement and reversals on representative service traffic.
- Separate thresholds for queue priority, preventive blocking, account enforcement and reporting workflows.
- Require trained and appropriately authorized human confirmation before any hotline or NCMEC report.
- Evaluate false positives on family, medical, educational, documentary and adult legal content relevant to the service.
- Measure recall and downstream consequences across age, race, skin tone and sex groups where lawful and appropriate.
- Version the model snapshot, category, threshold, test set and approval date in a decision ledger.
- Do not interpret category scores as calibrated probabilities or compare scores across model snapshots as if they were stable facts.
- Do not treat the likely-csam/gen-ai signal as proof of image provenance.
- Restrict sensitive review to least-privilege environments with access logging and clear evidence-handling rules.
- Minimize copies in storage, logs, tickets, analytics, screenshots, email and backups.
- Provide reviewer rotation, time limits, wellness support and a no-penalty stop path.
- Create a safe appeal and second-review process for users affected by automated blocking or account action.
- Track corrections and feed them into threshold review and regression testing.
- Reassess the system after traffic shifts, model updates, new abuse patterns or rising reviewer disagreement.
- Evaluate video as a separate system rather than assuming still-image performance transfers to sampled frames.
- Record every system that touches an image and the date each copy is deleted or lawfully preserved.
- Keep classifier output inside a layered system that also uses hashes, behavioral signals, policy, trained review and legal process.
KEEP A HAND ON THE WHEEL
The classifier's performance figures, threshold selection and partner results are reported by OpenAI and the named partners. They are primary evidence for what those organizations observed, not an independent industry benchmark or a guarantee on another service's traffic. The model card reports both false-positive and false-negative risk. It also reports demographic recall differences in its held-out evaluation, including lower likely-csam recall for Black-tagged, male-tagged and infant-tagged examples than for several comparison groups. The demographic tags were assigned by an LLM and some groups were small, so OpenAI describes the findings as directional. Perceptual deduplication reduces but does not eliminate overlap between training and evaluation material. OpenAI says it lacks the data needed to prevent all overlap across different images of the same children or series. The API accepts still images only, and OpenAI says it has not evaluated the classifier on video frames. The likely-csam/gen-ai score does not establish provenance. Category scores are not calibrated probabilities. Watch for independent benchmarking, more representative cross-platform evaluation, threshold changes, performance across demographic groups and content types, reviewer-wellness evidence, appeal outcomes, video-specific testing and documentation for later model snapshots.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
False positive
A result that incorrectly labels a negative case as positive, such as calling human writing AI-generated.
OPEN GLOSSARY CARD
Recall
The share of all relevant positive cases that a system successfully identifies.
OPEN GLOSSARY CARD
Perceptual hash
A compact visual fingerprint designed to remain similar when the same image is resized, compressed or lightly altered.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 17, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US