THE SIGNAL IN ONE SENTENCE
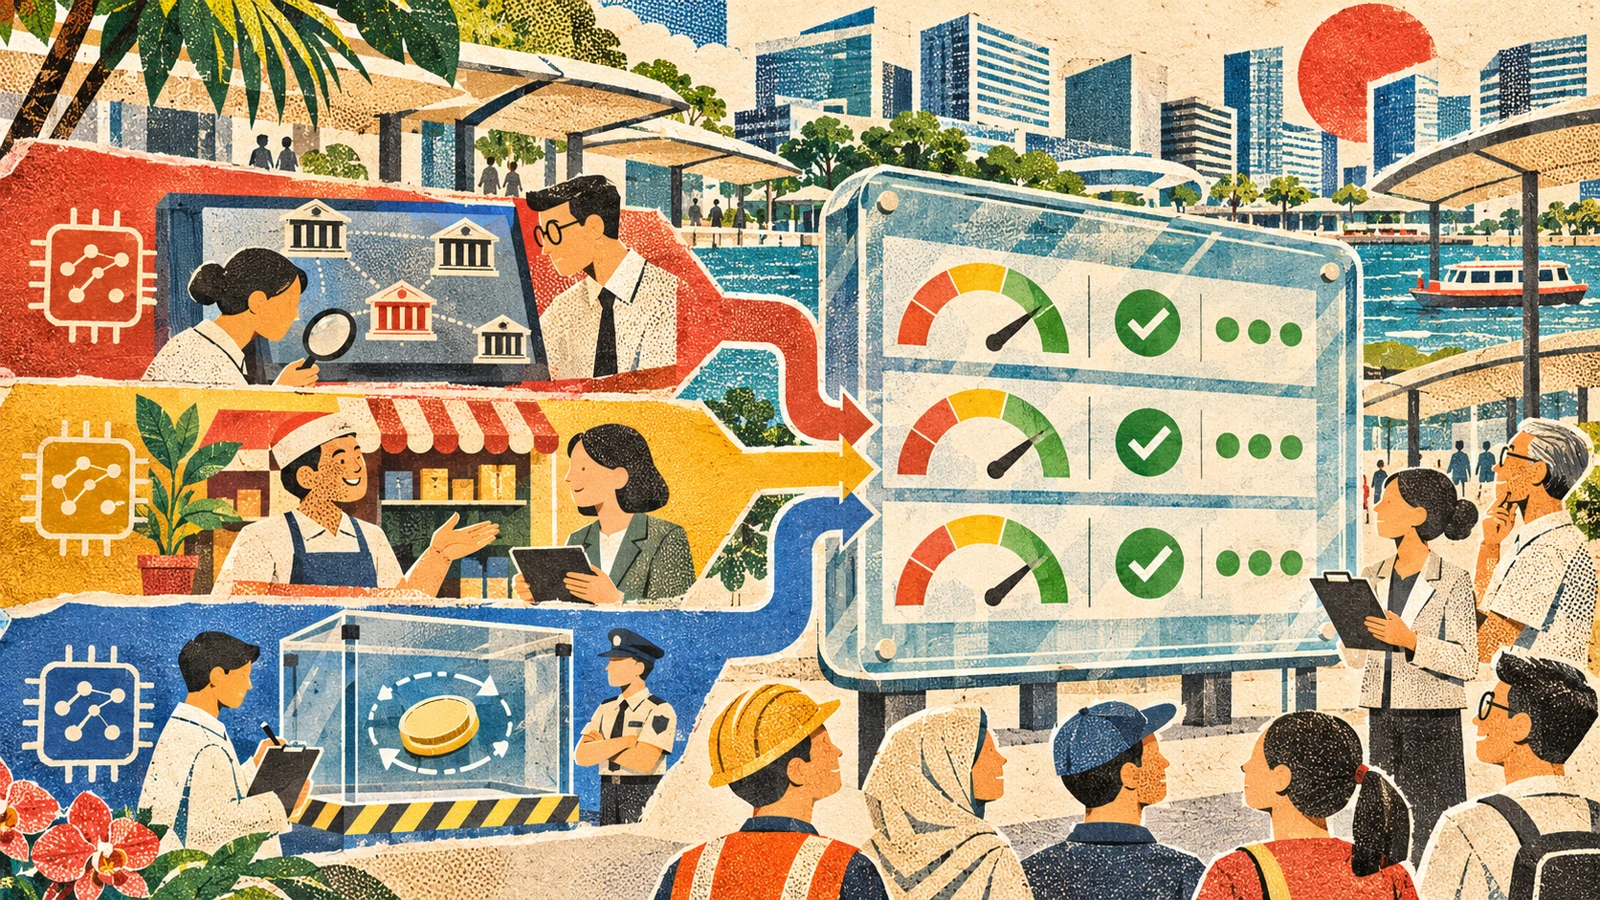
Singapore has given financial AI three actual jobs. On November 18, the Monetary Authority of Singapore and the Future of Finance Institute announced three National AI Missions for the financial sector. One aims to prevent financial crime. One aims to improve financing for small and medium businesses. One aims to make transactions by AI agents safe enough to trust. This is more useful than announcing that an industry will embrace AI and then disappearing into a fog machine. The missions also come with early work. For financial crime, five banks have pooled data patterns for a synthetic interbank scam dataset, in collaboration with GovTech. For agentic transactions, an Agentic Money Sandbox will test payments and treasury management under defined authority, limits and safeguards. For locally grounded language technology, Singapore's Institute for Infocomm Research is working with financial institutions on speech recognition for Singlish, commonly used languages and dialects, with live pilots planned for compliance monitoring. DBS, OCBC, Standard Chartered and UOB are launch partners. The government also described related talent programs and a broader mission model that brings institutions together around shared national problems. All of that is promising. None of it is proof that the systems work safely in public life. The plain signal is this: put every mission on a public scoreboard before it reaches real people. A mission scoreboard should identify the public problem, the data boundary, the current baseline, the test population, the failure cases, the acceptance threshold, the deployment gate, the accountable owner, the incident channel and the measured outcome. It should show what changed after each round of testing. If a system cannot clear the gate, the scoreboard should say so. That is not an attempt to turn public policy into a sports broadcast. It is a way to keep a national mission from becoming a permanent pilot whose only measurable output is optimism. Start with financial crime. Fraud moves across institutions. A single bank may see one transfer, one account or one warning sign. A cross-bank view can reveal a larger pattern. Singapore's deputy prime minister said the proof-of-value work is underway and that a design study for a Scam Detection Utility is expected early next year. The pooled synthetic dataset is a practical way to begin without handing live customer records around like snacks at a meeting. But synthetic does not mean neutral, complete or automatically private. A synthetic dataset reflects the source data, generation method and design choices behind it. It can preserve useful patterns. It can also flatten rare cases, miss new scams and reproduce old blind spots with excellent manners. The public scoreboard should therefore document which periods, institutions and scam types informed the data; which variables were removed or transformed; how fidelity and privacy were tested; and which real-world patterns are known to be absent. Five banks are enough to build something valuable. They are not the whole financial system. The benchmark should separate detection performance from operating performance. How often does the system flag a known scam pattern? How often does it flag an innocent transfer? How quickly can an institution intervene? How many legitimate customers are delayed? Which customer groups, languages, account types and transaction sizes receive more false alarms? Can a customer correct a mistaken block? Who is accountable when two institutions disagree? One giant accuracy number would be nearly decorative. The scoreboard should report false positives and false negatives by relevant group and scenario, time to intervention, money prevented from leaving, customer harm from mistaken holds, analyst workload, appeals, corrections and live incidents. It should also say when the model drifts because the scam changed faster than the quarterly meeting. Then look at small-business financing. The government described a mission that could use richer information from accounts, invoices, business profiles, payments and government records to improve access to financing. That can help a capable small business whose conventional credit file is thin. It can also create a much larger machine for drawing conclusions about people who do not know which signal sank the application. The scoreboard needs a before-and-after baseline. Publish approval rates, denial rates, time to decision, pricing, requested documentation, manual overrides and subsequent performance. Break results out by business age, industry, size and other relevant categories. Pay particular attention to new firms and thin-file applicants, because they are the people the richer data is supposed to help. Every decision should have a plain explanation and a correction path. A shop owner should be able to discover that an invoice was duplicated, a payment record was stale or a business classification was wrong. The lender should be able to override the model, record why and learn from the correction. Proactive financing offers need an additional line on the scoreboard: consent. Using transaction data to discover that a business might benefit from credit can be useful. Using the same data to pressure a stressed owner at exactly the vulnerable moment can become surveillance wearing a helpful hat. The mission should measure whether offers improve access and reduce cost, not merely whether more offers are sent or more data is consumed. The third mission, safe agentic transactions, needs the clearest gate of all. An AI agent that can recommend a payment is a tool. An agent that can execute one has authority. The difference is a bank balance, a contract and sometimes a fairly awkward phone call. Singapore's Agentic Money Sandbox is meant to test defined authority, limits and safeguards, initially in payments and treasury management. The ministerial speech also pointed to purpose-bound money, identity, accountability and interoperability as areas that need common approaches. Good. Make the authority object visible. Before an agent can move money, the mandate should identify the person or institution granting authority, the permitted account, counterparty, amount, frequency, purpose, currency, start and expiry time, confirmation requirement and cancellation rule. It should describe what happens when an instruction conflicts with a later message, when a price changes, when only part of a payment succeeds or when the agent's identity cannot be verified. The sandbox should deliberately test ugly scenarios. Duplicate payments. Stale invoices. Wrong currencies. Compromised agents. Prompt injection inside a document. A merchant that changes terms after approval. A network outage after authorization but before settlement. Conflicting instructions from two employees. A revoked mandate that remains cached. A cross-institution dispute where every system believes another system is responsible. For each case, publish whether the payment stopped, who was notified, how the transaction was reversed, how long recovery took and who absorbed the loss. If a human had to intervene, count that as part of the operating system, not as an embarrassing exception to omit from the chart. Purpose-bound money also needs public technical and legal meaning. If a payment may be used only for a defined purpose, the parties need to know who encoded the condition, who can change it, which evidence proves compliance and what remedy applies when software and contract language disagree. A hidden vendor rule is not a shared standard. The locally grounded speech work deserves its own scoreboard even though it supports the broader missions. Speech recognition tuned for Singlish, local languages and dialects can make compliance monitoring more accurate in Singapore than a generic model trained elsewhere. It can also turn ordinary conversations into searchable risk signals. Test performance separately for each language, dialect, code-switching pattern, accent, background noise level and call type. Record reviewer corrections. Set retention limits. Limit access. Measure whether particular speakers are sent for more review. Works in English is not a local evaluation. Nor should the launch partnership become the permanent boundary of participation. Four large banks can move quickly and provide substantial operating experience. Smaller banks, payment companies, fintech firms, consumer groups, small businesses and independent researchers may see different failure modes. The scoreboard should show who participated, who was affected and how outside evidence can change a gate. A shared format across all three missions would make the program easier to inspect. Name the problem in one sentence. State the current baseline. Describe the data and its exclusions. List the participating institutions and affected groups. Publish the test protocol. Set an acceptance threshold before seeing the result. Report failures and subgroup performance. Name the owner who can stop deployment. Record independent review. Show the next gate. Publish incidents and outcomes after launch. The scoreboard does not need to expose customer data, security-sensitive fraud rules or proprietary model weights. It does need enough detail for the public, researchers and market participants to understand what was tested and what evidence justified the next step. That distinction matters because transparency is often rejected with an all-or-nothing argument. Either reveal everything and help criminals, or reveal nothing and trust the program. Real accountability lives in the large middle. Institutions can publish test design, aggregate outcomes, subgroup performance, governance, incident categories and remediation without publishing a playbook for fraud. The National AI Missions are still early. The announced work includes pilots, designs, a sandbox and a proof-of-value. MAS has not published performance results, deployment dates, independent audits or a recurring public reporting format for the three missions. That is exactly why the scoreboard should be designed now. Once systems are embedded in operations, reporting becomes harder to add. Owners defend the metric they already optimized. Vendors call new fields burdensome. Pilot assumptions quietly become infrastructure. A public gate defined before the result gives everyone a cleaner contract. Singapore is good at coordinated execution. The attractive risk is that coordination itself becomes evidence of success. It is not. A consortium is a way to do the work. A sandbox is a place to test. Synthetic data is a tool. A pilot is a question. The answer should be visible. Three national missions now have names, partners and early machinery. Give each one a scoreboard that can say yes, no, not yet and here is why. Then the public can see whether financial AI is preventing harm, widening access and moving money safely, rather than merely moving through a very polished program.
01
WHAT ACTUALLY CHANGED
Singapore launched three National AI Missions for finance on November 18, 2026.
The missions focus on financial crime prevention, better financing for small and medium enterprises and safe transactions by AI agents.
Five banks contributed pooled data patterns to a synthetic interbank scam dataset developed with GovTech.
Singapore is conducting proof-of-value work and plans a design study for a Scam Detection Utility early next year.
An Agentic Money Sandbox will initially test payments and treasury management under defined authority, limits and safeguards.
The program includes work on purpose-bound money, identity, accountability and interoperability for agentic transactions.
Singapore is developing locally grounded speech recognition for Singlish, commonly used languages and dialects.
Live pilots are planned for speech technology in financial compliance monitoring.
DBS, OCBC, Standard Chartered and UOB are launch partners.
Related talent programs are intended to build practical AI and finance skills.
02
WHY THIS MATTERS
Cross-bank collaboration can reveal scam patterns that no institution can see alone.
Synthetic data can enable shared testing while still carrying gaps, distortions and privacy risks from its sources and generation method.
Richer small-business data can widen access to credit or create new opaque proxies for denial and pricing.
Proactive financing offers can help businesses or become pressure based on intimate transaction signals.
An agent that executes a payment holds authority, not merely information.
Agentic payments need explicit mandates, limits, revocation, recovery and accountable institutions.
A sandbox result does not establish safety in live financial networks.
Locally grounded speech recognition may improve performance while expanding surveillance and unequal review risk.
Large launch partners do not represent every smaller institution, business or consumer affected by the systems.
A public deployment gate makes it harder for an attractive pilot to become infrastructure without evidence.
03
WHERE IT COULD HELP
- Publish one shared scoreboard template for all National AI Missions.
- Name the public problem, accountable owner and current non-AI baseline.
- Document the dataset period, contributors, generation method, exclusions, fidelity tests and privacy tests.
- Report fraud false positives and false negatives by scenario and relevant affected group.
- Measure time to intervention, money protected, customer delays, analyst workload, appeals and corrections.
- Test scam systems against new patterns that were absent from the synthetic dataset.
- Report small-business approval, denial, pricing, time, manual override and correction rates.
- Break financing results out by business age, size, industry and thin-file status.
- Give every applicant a plain explanation, data correction path and human review route.
- Measure whether proactive offers improve financing access and cost, not merely offer volume.
- Define agent authority by account, counterparty, amount, frequency, purpose, currency, expiry and confirmation rule.
- Test duplicate, partial, stale, fraudulent, compromised, revoked and disputed agentic payments.
- Publish the stop, notification, reversal, reimbursement and recovery result for every failure scenario.
- Define purpose-bound money in shared technical and legal terms.
- Evaluate speech recognition separately by language, dialect, code-switching, noise level and call type.
- Limit speech-data retention and access, and audit reviewer corrections and unequal escalation rates.
- Include smaller institutions, businesses, consumer groups and independent researchers in evaluation.
- Set acceptance thresholds before results are known and publish the evidence for each deployment gate.
- Report live incidents, remediation and outcome changes after deployment.
- Provide aggregate accountability without exposing customer data or operational fraud rules.
KEEP A HAND ON THE WHEEL
The three missions, participating organizations and initial projects are described by the Monetary Authority of Singapore and in the deputy prime minister's Singapore FinTech Festival keynote. This article does not constitute an independent audit of the programs, datasets, models or participating institutions. The announced work is early. It includes proof-of-value work, pilots, design studies and a sandbox. MAS has not published performance results, independent audits, deployment dates, acceptance thresholds or a recurring public scoreboard for the missions. The synthetic scam dataset is based on patterns pooled from five banks. Its coverage, generation method, fidelity, privacy tests and known exclusions were not described in the announcement. Fraud detection can produce false positives and false negatives. Aggregate accuracy can conceal unequal customer harm, new scam patterns and operational delays. Richer data for small-business financing may improve access while introducing privacy, explainability, proxy discrimination and correction risks. Proactive financing can become manipulative if transaction signals are used without meaningful consent or clear limits. Agentic transactions remain subject to institutional responsibility, financial regulation, contractual authority and consumer protection. A successful sandbox test does not prove safety in live systems. Purpose-bound money requires shared technical and legal interpretation. Software conditions alone do not settle contractual disputes or responsibility for loss. Speech recognition performance can vary across languages, dialects, accents, code-switching, noise and call types. Compliance monitoring also raises retention, access, employee surveillance and review concerns. Watch for publication of mission baselines, data documentation, subgroup results, failure tests, independent review, deployment gates, incident reporting, redress routes and measurable public outcomes.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 18, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US