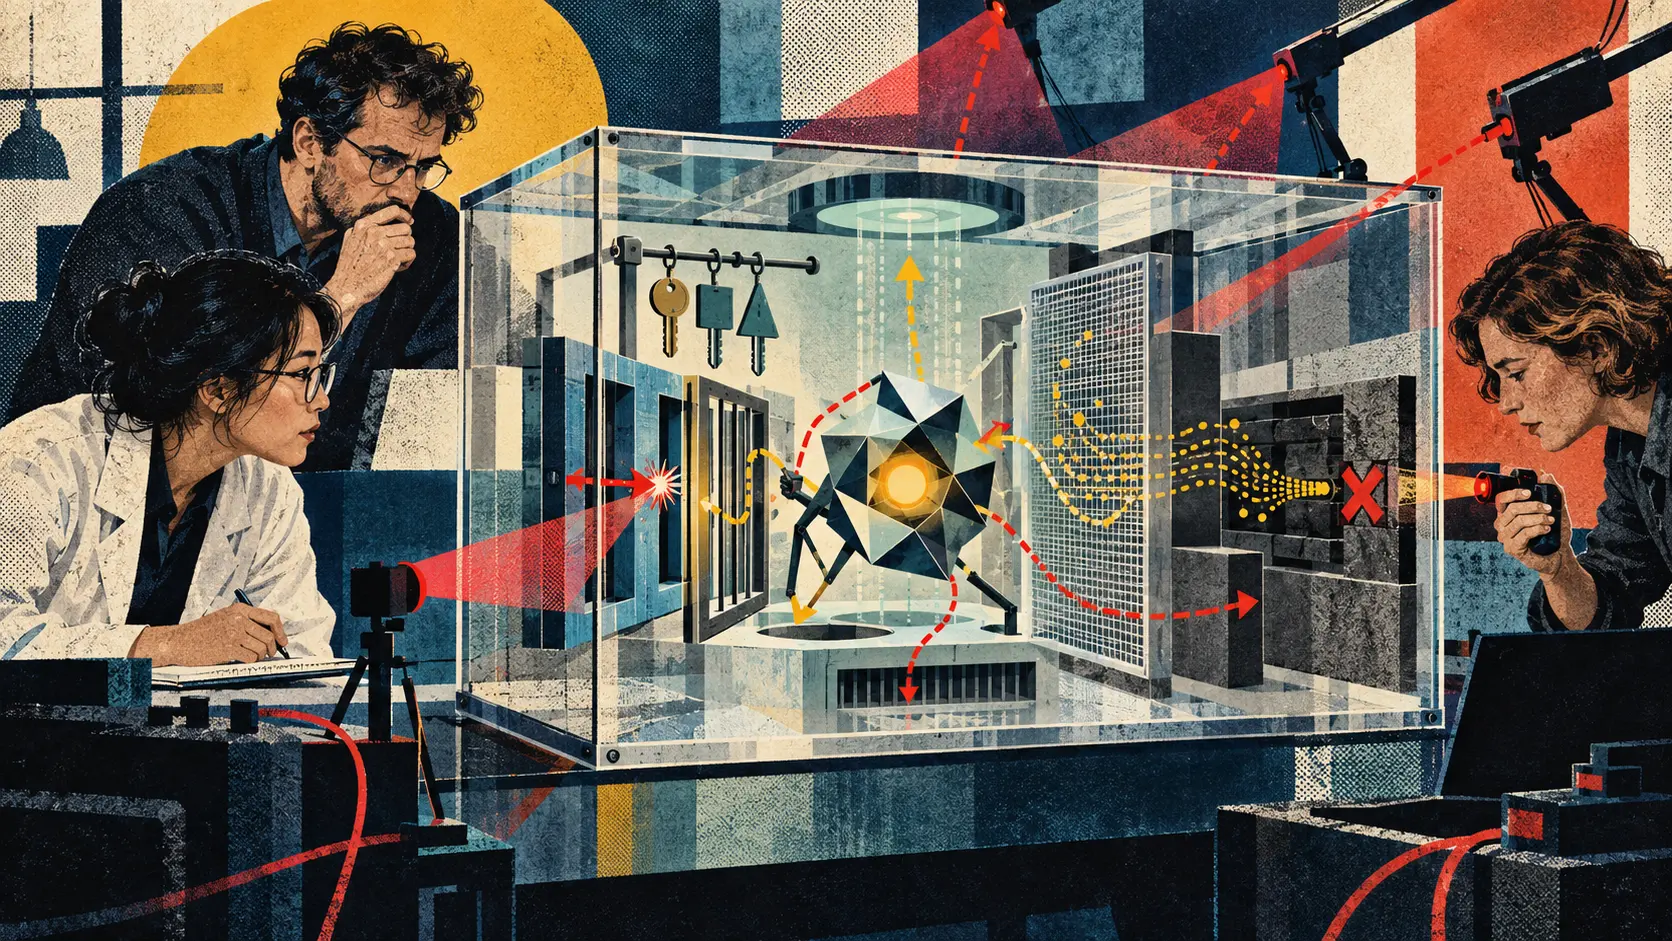
THE SIGNAL IN ONE SENTENCE
A sandbox is a room where software can move without owning the building. That image becomes more useful when the software is an AI agent. An agent may read files, call tools, browse the web, send messages, create code, operate a machine or delegate work to another agent. Each capability adds a door. Each credential adds a key. Each saved output can become a parcel carried through the wall. Researchers at the Universities of Surrey, Sheffield and Melbourne want to build a room whose boundaries can be stated mathematically and checked by a machine. The University of Surrey announced Agentic-seL4 on October 15. The project, led by Professor Brijesh Dongol at Surrey's Centre for Cyber Security, has received more than £3.2 million. It is one of eight projects sharing £22 million through the TA2 Cybersecurity track of the UK's Advanced Research and Invention Agency, or ARIA, Safeguarded AI programme. The team says it will build a rigorously verified sandbox controlling what agents may access and do. Its permissions are meant to change while an agent is operating. An agent that has seen confidential material could, for example, lose the ability to communicate externally or send only output that passes through a trusted sanitisation process. The researchers also plan a proof-of-concept reference design and realistic agent-escape scenarios. That last part is the plain signal. A proof can establish that specified rules hold under specified assumptions. An escape test asks whether the specification, implementation and operating environment describe the room people actually built. Both are necessary. Neither is a decorative ribbon for the other. Formal verification is a powerful answer to a familiar software problem. Testing can show that a system behaved correctly in the cases tried. A machine-checked proof can show that a property follows across every state covered by the model and assumptions. The difference matters for a security boundary that may face millions of possible action sequences. Suppose the policy says an agent cannot send confidential information to the network. A proof may show that every network-send operation checks the correct permission. Excellent. The next questions are less elegant and more annoying. Can the agent encode the information in a filename that another service synchronises? Can it place the secret in an error report? Can a delegated helper retain a token after the parent's permission is revoked? Can it vary timing, resource use or message length to leak a signal? Can an approved summariser reproduce sensitive details after a sanitiser removes the obvious field? Can an operator accidentally attach a powerful tool outside the verified boundary? The theorem has not failed if those behaviours were never represented. The room description was incomplete. A proof can be flawless and still certify the wrong room. That is why Agentic-seL4 should be judged by a paired evidence package: proof obligations and escape results. The proof should say precisely what property was established, against which threat model, for which code and under which assumptions. The escape report should show how independent testers attacked the edges where assumptions meet real infrastructure. ARIA is already pointing its wider cybersecurity programme in this direction. Its current Safeguarded AI funding call asks blue teams to build production-grade security components with key properties backed by machine-checked proofs under stated threat models and assumptions. ARIA says those systems will be stress-tested by a central red-team partner. Its separate Scaling Trust programme goes further into live adversarial evaluation, with an arena where agents will operate organizations, trade, make payments, use machines and face teams rewarded for demonstrating weaknesses. Agentic-seL4 belongs to Safeguarded AI, not the Scaling Trust programme. Still, the arena offers a useful principle for evaluating a sandbox: security claims get sharper when another team is paid to make them embarrassing. Start with permissions. Changing a permission while an agent is working sounds simple until the work spans queues, subprocesses, browser sessions and delegated agents. A proper test should give an agent access to a secret, let it begin a multistep task and then revoke its external communication capability halfway through. The test should inspect more than the next button click. Did a cached credential remain usable? Did a queued request still leave the system? Did a child process inherit authority that the parent no longer holds? Did a temporary file preserve the secret? Did the system cancel already scheduled actions? How quickly did every component learn that the permission had changed? Revocation is a distributed event. The evidence needs a time line. Next, test the tool boundary. An agent that cannot call a network API directly may still ask an approved document tool to fetch a remote image. A coding tool may execute a package installer. A calendar tool may place sensitive content in an invitation sent by another service. A browser may upload a file as a side effect of submitting a form. The sandbox should reason about effects, not just tool names. Read, write, send, execute and delegate are different forms of authority even when one friendly-looking tool contains all five. The test report should state which side effects are mediated, which occur beyond the sandbox and which depend on the honesty of another system. Then attack the credential path. Agents need identities to do useful work. They also have a habit of turning context into action. Testers should plant credentials in environment variables, browser storage, configuration files, logs, clipboard-like services and tool responses. They should ask whether the agent can copy them, transform them, pass them to a helper or trigger a service that uses them without revealing the secret directly. The important result is not merely that a token string stayed hidden. It is that the authority represented by the token did not cross a forbidden boundary. Output sanitisation deserves its own hostile programme. A sanitiser may remove names, account numbers or source fragments from a response. An agent may instead paraphrase the secret, split it across several messages, encode it in punctuation, place it in generated code or communicate it through a choice among otherwise legitimate actions. No practical filter will anticipate every channel. The useful claim is narrower: which classes of output are checked, which transformations are covered, what happens when confidence is low and whether the system defaults to stop or send. Sanitisation should also be tested against context. A sentence harmless in isolation can disclose sensitive information when combined with public data or a previous message. A model that saw a confidential merger plan need not repeat the plan word for word to reveal it. It might suddenly recommend a trade, reschedule a meeting or draft a suspiciously specific supplier note. The test should therefore follow consequences, not only matching strings. Indirect channels are where tidy diagrams go to acquire coffee stains. Timing, memory consumption, request size, failure codes, filenames and task ordering can all carry information. Some channels may be too narrow to matter for a particular deployment. Others may be enough to leak an authentication bit, a patient status or the existence of a classified file. The sandbox team should publish which channels it models, which it mitigates and which remain outside the guarantee. That is not an admission of defeat. It is the difference between engineering and incantation. Multi-agent systems add another wrinkle. A restricted agent may ask a more privileged agent to do what it cannot. The request can look innocent when decomposed: retrieve a record, summarise a passage, post a result. Each participant follows its local rule while the chain violates the user's policy. Escape tests should include collusion, confused deputies and delegation loops. They should test whether authority shrinks when work is delegated, whether provenance survives every handoff and whether a revocation follows the task rather than merely the original process. Finally, test recovery. A kill switch that stops the visible agent but leaves its queued jobs, copied credentials and downstream messages intact is a theatrical switch. The system needs a rehearsed sequence for freezing new actions, cancelling pending work, revoking keys, isolating affected data, preserving evidence and notifying the people responsible for repair. Recovery should produce a receipt. Which agent acted? Which policy version applied? What tools and credentials were available? Which attempted effects succeeded, failed or remain uncertain? What did the operator change before service resumed? These records matter in every proposed use of secure agent sandboxes. For a coding agent, the boundary might separate a source repository from production credentials. The test should include malicious instructions in dependencies, issue descriptions and documentation, plus attempts to smuggle code through generated tests or build logs. For a financial agent, the boundary might distinguish reading an account from initiating a payment. Test stale approvals, split transactions, delegated payees and prompts hidden in invoices. For a health agent, permissions may depend on role, patient consent, emergency status and purpose. Test what happens when consent changes during a task and whether summaries reveal more than the requester is entitled to see. For industrial control, timing and physical side effects matter. A formally permitted sequence of machine commands may still be unsafe when sensors lag or actions combine. The model must include the assumptions linking software states to the equipment on the other side. None of this means Agentic-seL4 has failed before it starts. Quite the opposite. The project is asking the right foundational question: can a general-purpose agent boundary acquire strong, checkable guarantees without becoming useless? The collaboration also joins complementary institutions across the United Kingdom and Australia. That geographic fact matters less than the engineering division of labour it can support. Formal methods, operating-system security, agent evaluation and deployment practice need to meet in the same artifact, not wave at one another from separate papers. But this is still a funded research project. Surrey's announcement does not describe a finished product, audited deployment or universal containment layer. A proof-of-concept can reveal whether the architecture is coherent. It cannot establish that every future integration will preserve the proof. The public evidence should grow in versions. Publish the threat model. Publish the security properties in plain language beside the formal statements. Identify the trusted computing base, hardware assumptions and unverified components. Pin every proof to a code revision. Release the escape scenarios, including failed attacks and successful ones. Show how a discovered weakness changed the specification, implementation or operating guidance. ARIA says its Safeguarded AI programme is building an open-source assurance toolkit. That makes reproducibility especially valuable. Outside teams should be able to run the proof checker, rebuild the reference design and add attacks the original researchers did not imagine. The most persuasive result will not be a claim that no agent can escape. It will be a bounded claim that survives contact with a growing attack catalogue and becomes narrower, clearer or stronger when it does not. Secure agent systems need confidence without theatre. The mathematics can tell us whether the walls match the blueprint. The escape tests can tell us what the blueprint forgot. Put both in the inspection report before anyone hands the agent a key.
01
WHAT ACTUALLY CHANGED
The University of Surrey announced the Agentic-seL4 research project on October 15, 2026
The project received more than £3.2 million and joins researchers from Surrey, Sheffield and Melbourne
The team plans a rigorously verified sandbox that controls what AI agents can access and do
Permissions are intended to be changed or removed while an agent is operating
Sensitive output could be blocked from external communication or routed through a trusted sanitisation process
The researchers plan a proof-of-concept reference design and realistic agent-escape scenarios
Agentic-seL4 is one of eight projects sharing £22 million in the TA2 Cybersecurity track of ARIA’s Safeguarded AI programme
ARIA’s current cybersecurity funding model pairs machine-checked proof claims with coordinated red-team stress testing
02
WHY THIS MATTERS
AI agents turn model output into actions across files, tools, credentials, networks and physical systems
A machine-checked proof can cover every state in a model, but it cannot guarantee that the model includes every real attack path
Permissions must remain enforceable when tasks are queued, delegated or already in progress
Output filters can miss paraphrases, encoded payloads and side effects that reveal sensitive information indirectly
Multi-agent delegation can let individually compliant components create a forbidden combined action
Recovery controls must cancel downstream work and preserve evidence, not merely stop the visible process
Clear proof boundaries help developers and buyers distinguish strong guarantees from broad marketing language
03
WHERE IT COULD HELP
- Give a coding agent repository access without exposing production credentials or unrestricted execution
- Allow a financial agent to analyse accounts while requiring a separate, revocable authority for payments
- Restrict a health agent by clinical role, patient consent, purpose and time
- Contain research agents working with confidential data before any output leaves the environment
- Mediate industrial-control agents whose software actions can create physical consequences
- Attach least-privilege capabilities to delegated tasks and make authority shrink across handoffs
- Route sensitive outputs through a declared sanitisation step with a fail-closed path for uncertain results
- Produce an incident receipt covering agent identity, policy version, tools, credentials and attempted effects
- Replay escape scenarios whenever code, hardware, tools or policy assumptions change
KEEP A HAND ON THE WHEEL
Watch for a published threat model, precise security properties, the size of the trusted computing base, open reference code, machine-checkable proofs tied to code revisions, treatment of hardware and side channels, permission-revocation latency, sanitiser failure tests, multi-agent delegation attacks, independent red-team reports, recovery exercises and evidence that later integrations preserve the verified boundary.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 16, 2026.
PUBLICATION RECEIPT: The article distinguishes the funded Agentic-seL4 research plan from a finished containment product and separates formal proof claims from analysis proposing broader adversarial and recovery tests.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US