THE SIGNAL IN ONE SENTENCE
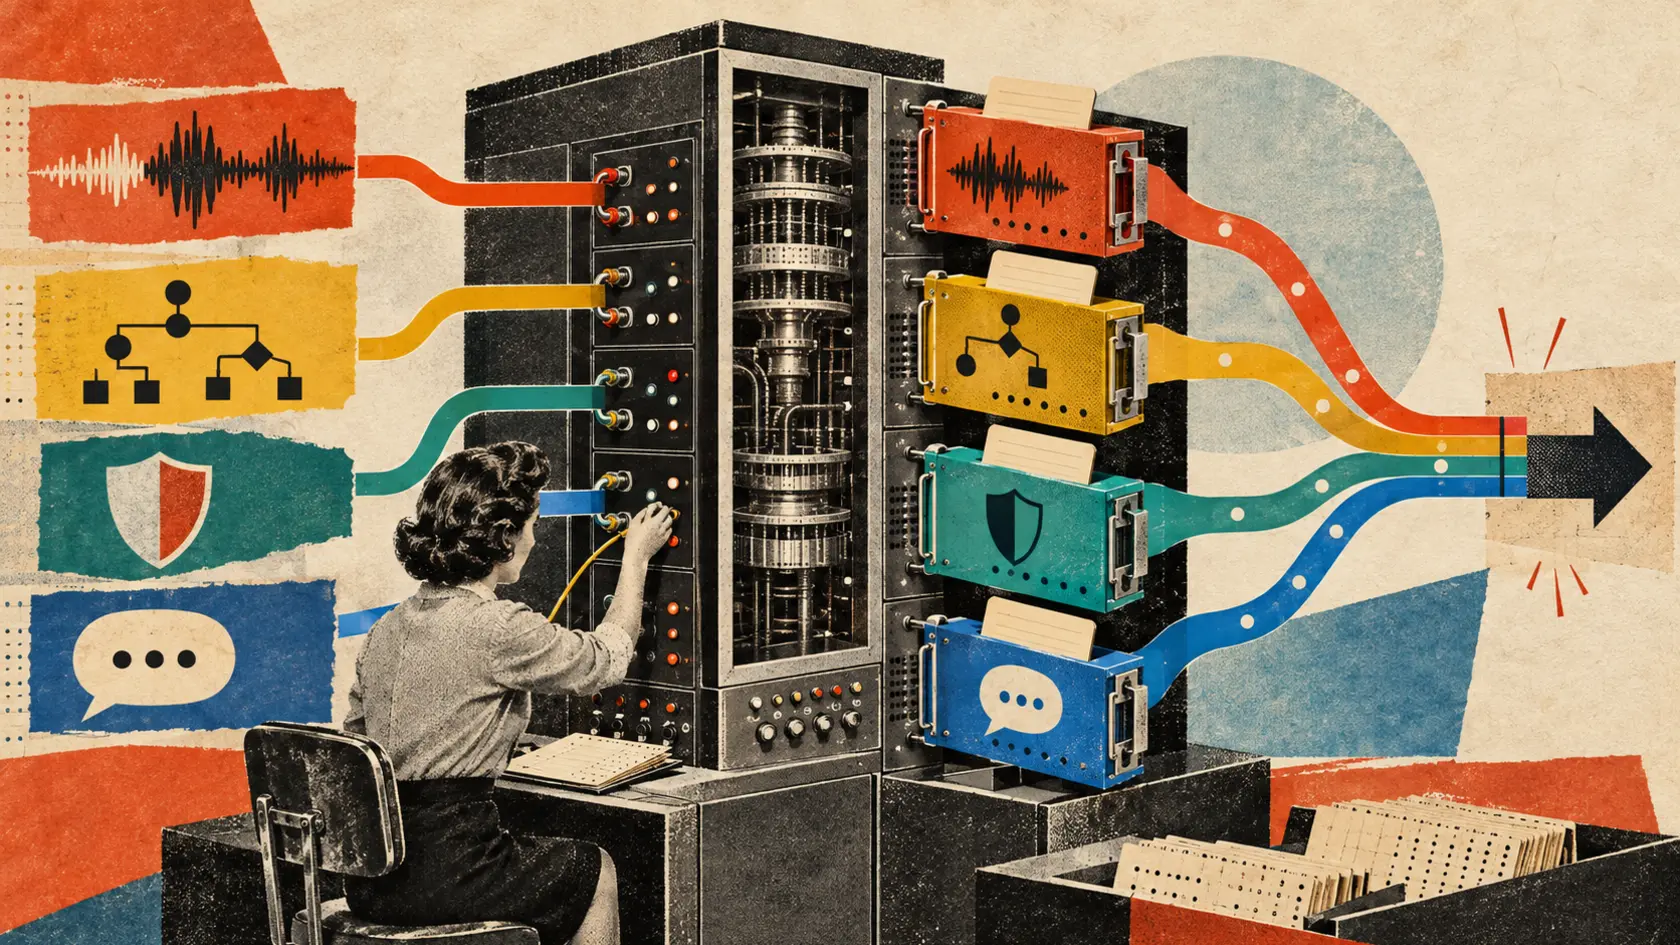
One model can now answer the question, classify the question, screen the question and transcribe the question before anyone has finished saying it. That is useful. It is also how a clean architecture diagram becomes a crowded control room. On October 15, IBM introduced Granite Switch 4.1, a pair of modular open models designed to move among ordinary language generation, general decision tasks, safety-related classification and speech-to-text from one hosted endpoint. The released checkpoints use Granite 4.1 base models in 8-billion and 30-billion parameter sizes, each with a published 128,000-token context window. IBM composed two adapters into each checkpoint. One is a general-purpose decision adapter. The other is a Guardian adapter for safety classification. The models also include IBM's Granite Speech 5.0 Turbo CTC encoder for English transcription. The pieces do not all run at once. Control tokens activate the relevant adapter when a workflow needs it. IBM built the adapters with Activated LoRA, or aLoRA, technology so they can reuse the base model's key-value cache rather than forcing the system to recompute the entire conversation each time a specialist takes over. IBM says the composed model occupies roughly the same GPU memory as the base model by itself, while a co-located speech encoder handles audio. The result is a model that behaves less like one general employee and more like a small office sharing one desk. The plain signal is that every adapter needs a task card. A task card is a compact operational record for one adapter inside a modular model. It should explain the job, trigger, input contract, output schema, evaluation set, calibration, known failures, latency, dependencies, fallback and version. Every production response should record which task card applied. Without that record, one endpoint can hide several different systems behind a single model name. Consider a customer-support call. The speech component transcribes the audio. The base model summarizes it. A decision adapter classifies the request. A safety adapter checks for harmful content. Another application rule decides whether the result can be sent automatically or must reach a human. The user sees one interaction. The system has made several different kinds of claim. The transcript claims what was said. The summary claims what mattered. The classifier claims which category applies. The safety adapter claims whether a risk threshold was crossed. The final response claims what should happen next. Those claims need separate evidence. Speech recognition should be evaluated across accents, dialects, background noise, microphone quality, overlapping speakers, technical vocabulary, numbers and names. A decision adapter should be evaluated for the exact labels it returns, including confusing boundary cases. A safety classifier needs category definitions, threshold calibration, false-positive and false-negative rates, and tests for oblique language. A conversational model needs checks for factuality, instruction following and unsupported confidence. One average score cannot cover that territory. The task card should start with a strict contract. What input does the adapter expect? What control token activates it? What output is valid? Does it return a label, probability, score, rewritten query or natural-language answer? What happens when the request falls outside the available labels? Can the adapter abstain? IBM's Granite Switch project treats adapters like software functions with defined input and output contracts. That is the right mental model. Software functions are not trusted because they share a codebase. They are tested against their own responsibilities. The same rule should apply here. The decision adapter should not inherit credibility from the speech model's leaderboard result. The safety adapter should not inherit credibility from the base model's chat quality. Efficient composition is an engineering property, not an accuracy guarantee. Trigger logic deserves its own line on the card. The Granite Switch checkpoints activate embedded adapters through dedicated control tokens. In a well-designed application, users should not need to handle those tokens directly. The orchestration layer decides when a specialist is needed. That routing decision can fail. The application may send a nuanced policy question to a binary classifier. It may run the safety adapter on an incomplete transcript. It may skip a specialist because the input was mislabeled. It may call two adapters whose results point in opposite directions. Teams should test the router separately from the adapters. For each task, record whether routing is rule-based, model-selected or manually requested. Test inputs that plausibly belong to two tasks. Measure missed activations and unnecessary activations. Require a visible reason when the system chooses a consequential adapter. Then define conflict rules. Imagine the conversational model says a request is ordinary, while the Guardian adapter assigns a high safety score. Which one wins? If the transcript contains uncertainty but the decision adapter returns a crisp label, does the workflow preserve the uncertainty? If a specialist refuses to classify, can the base model quietly fill in an answer anyway? The task card should state the precedence order, escalation path and abstention behavior before deployment. Shared context creates another subtle problem. The efficiency claim behind aLoRA is that adapters can reuse the base model's existing key-value cache. That can reduce repeated computation when a workflow switches tasks. It also means every adapter acts on a context assembled upstream. If the context is wrong, the specialists can be efficiently wrong together. A transcription error can enter the shared context and shape the summary, decision score and safety check. A stale instruction can influence several adapters. A prompt injection inside retrieved text may reach every downstream module unless the system separates trusted instructions from untrusted evidence. The task card should identify which context fields the adapter reads and which it ignores. It should show whether raw audio, transcript confidence, retrieved documents and prior model outputs remain distinguishable. Derived text should never silently become equivalent to the original evidence. Versioning is equally important. The 8B and 30B model cards list the Granite base model, two adapters and the 470-million-parameter English speech model used in the composition. They also identify Apache 2.0 licensing and support for Hugging Face Transformers and vLLM. The build manifest goes deeper, listing adapter names, types, control tokens, ranks, target modules and source revisions. That composition record should travel with every deployment. If a team replaces the Guardian adapter, changes the speech encoder or trains a custom classifier, the system is no longer the same operational model even if the endpoint name remains unchanged. A request log should preserve the base-model revision, adapter revisions, speech-model revision, orchestration code and task-card versions used at that moment. Otherwise a later audit can reproduce the prompt and still fail to reproduce the decision. IBM is encouraging developers to compose their own Granite Switch models from IBM, custom and third-party adapters. The project repository describes a composer that embeds compatible adapters, adds control tokens and emits a checkpoint usable through Transformers or vLLM. IBM also says it plans to release an adapter training kit through Mellea. That openness is promising. It also turns dependency management into model governance. Third-party adapters should come with provenance. Who trained them? On which data? Under what licence? Against which base revision? What labels and scoring rules did they use? What security review did their files receive? Can the source disappear or change after deployment? The task card should pin the exact artifact and its cryptographic digest. It should include the licence, training description, evaluation date and maintainer. A deployment should reject an adapter whose expected base model or control token collides with another component. Compatibility is not only whether the checkpoint loads. It is whether the components still behave correctly when they share a prompt, cache and serving process. Teams should run composition tests. Measure every adapter alone, then measure it alongside the complete set. Vary adapter order. Stress long contexts. Reuse caches across benign and adversarial inputs. Test whether one control token can trigger the wrong specialist or whether untrusted content can imitate a control instruction. Watch latency by stage. One endpoint can simplify infrastructure, but it can also make performance harder to diagnose. A fast base response may hide a slow transcription path. A cheap classification may cause an expensive retry. Cache reuse may help the median request while a long audio input dominates the tail. The task card should publish hardware, batch size, input length, cache assumptions and stage-level latency. It should separate model time from audio processing, routing and post-processing. Vendor demonstrations are useful invitations to test, not substitutes for production measurements. The same caution applies to IBM's benchmark claims. IBM says its Guardian adapter outperforms several general decision models on average across safety-related tasks, that its speech model leads the OpenASR speed rankings, and that a composed 30B model completed one five-step retrieval workflow faster than a competitor. The company also says fuller details and data will arrive in the coming weeks. Those claims should be treated as vendor-authored until the methods, task mix, hardware, thresholds and independent replications are available. The immediate value of Granite Switch 4.1 is architectural. It shows a practical route between two expensive habits: asking one general model to do everything, and deploying a separate full model for every narrow task. A shared base with lightweight specialists can make modular AI easier to operate, inspect and update. The danger is assuming modular automatically means understandable. It does not. Modularity creates boundaries. People still have to label them. A good task card turns an adapter from invisible model seasoning into a named production component. It tells operators when that component should run, what evidence supports it, what can go wrong and who owns the fix. The endpoint may be one address. The responsibility is still distributed across every switch behind it.
01
WHAT ACTUALLY CHANGED
IBM announced Granite Switch 4.1 on October 15 after releasing 8B and 30B checkpoints dated October 14
Each checkpoint combines a Granite 4.1 base model with a general decision adapter and a Guardian safety-classification adapter
The models include an English speech-to-text encoder based on Granite Speech 5.0 Turbo CTC
Dedicated control tokens activate adapters for different tasks
IBM says Activated LoRA adapters can reuse the base model key-value cache instead of recomputing prior context
IBM says the composed capabilities occupy approximately the same GPU memory as the base model alone
The released model cards list 128,000-token context windows, Apache 2.0 licensing and support for Transformers and vLLM
Developers can use IBM tools to compose custom Granite Switch checkpoints from compatible adapters
02
WHY THIS MATTERS
One endpoint can replace several separately hosted models for conversation, transcription and classification
Shared infrastructure can reduce memory use and repeated computation while keeping task specialists distinct
A single model name can hide different triggers, tests, thresholds and failure modes
Routing mistakes can send an input to the wrong specialist even when every adapter works as designed
Errors in shared context can propagate through transcription, summarization, decisions and safety checks
Custom and third-party adapters turn model composition into a software supply-chain problem
Adapter updates can change production behavior without changing the public endpoint name
Task-level records make modular systems easier to evaluate, audit, reproduce and roll back
03
WHERE IT COULD HELP
- Publish one task card for every embedded adapter and speech component
- Define the exact input contract, output schema, control token and abstention behavior
- Record whether routing is rule-based, model-selected or manually requested
- Measure missed activations, unnecessary activations and ambiguous routing cases
- Set precedence and human-escalation rules when components disagree
- Evaluate speech across accents, noise, microphones, overlapping speakers, names and numbers
- Calibrate decision and safety thresholds on the exact production categories
- Preserve transcript confidence and raw evidence separately from derived summaries
- Pin the base model, adapters, speech encoder, orchestration code and task-card revisions
- Test every component alone and again inside the full composition
- Publish hardware, batch size, input length, cache assumptions and stage-level latency
- Require provenance, licence, digest and security review for third-party adapters
KEEP A HAND ON THE WHEEL
Watch for the additional benchmark details IBM says it will release, independent evaluation of the decision and Guardian adapters, transcription quality across accents and noisy environments, cache behavior under long and adversarial contexts, control-token injection tests, conflicts among custom adapters, stage-level latency and memory measurements, supply-chain protections for third-party adapter files, and evidence that composed checkpoints preserve each component’s standalone performance.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 16, 2026.
PUBLICATION RECEIPT: The article separates IBM’s release specifications and performance claims from analysis about routing, calibration, provenance, conflicts, shared context and production accountability.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US