THE SIGNAL IN ONE SENTENCE
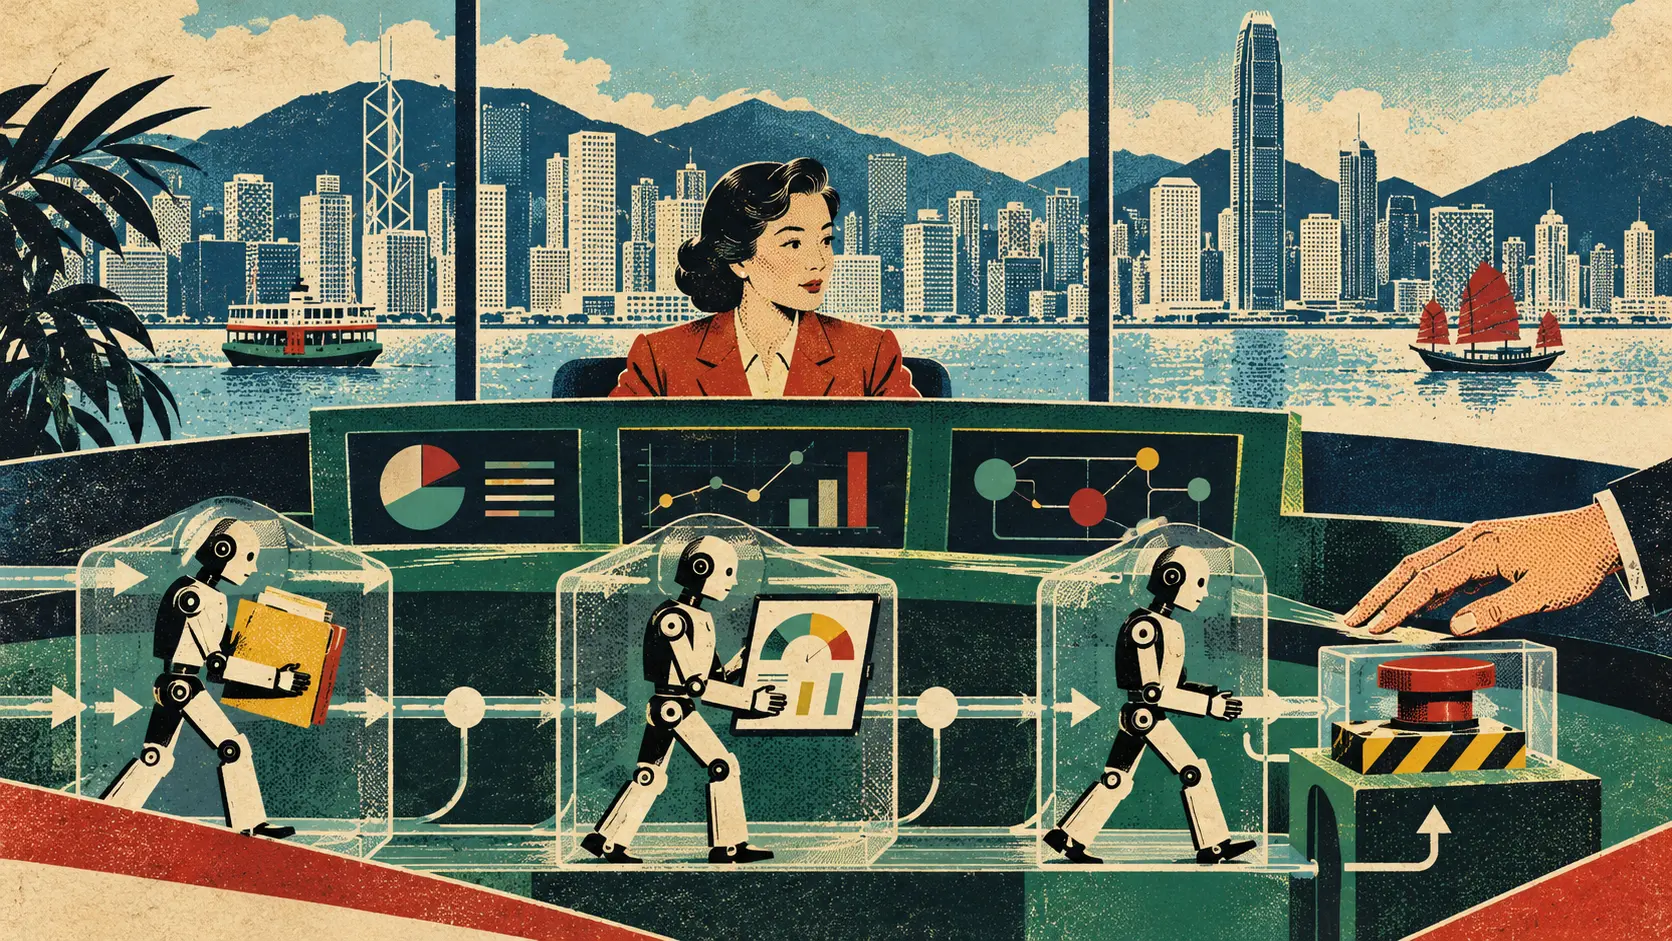
A bank's AI agent may soon move from suggesting the next step to taking it. That can mean gathering documents, planning a review, checking fraud signals, calling tools and handing a result to another agent before a customer knows a small mechanical committee has convened around the account. Hong Kong's banking regulator is trying to put rails around that committee. On October 15, the Hong Kong Monetary Authority introduced its ART framework for responsible AI adoption. ART stands for Accountability, Resilience and Trust. The framework arrives with supervisory guidance for authorized institutions, practical lessons from the second cohort of Hong Kong's generative AI sandbox and a concept note focused on agentic AI. The next morning, HKMA banking-supervision executive Carmen Chu supplied the useful operational detail. More than 60 percent of the use cases in the second sandbox cohort involved AI agents, she said, and half of those were multi-agent applications. The regulator wants banks to assign an owner to each AI use case, maintain an inventory of approved applications, map dependencies across models, data, tools, infrastructure and outside providers, and keep corrective or restrictive controls ready. For some systems, that may include a kill switch that suspends an agent before a problem grows teeth. The framework also points toward an industry registry for material AI agents and a new training-data sharing platform with Cyberport and the University of Hong Kong. A separate discussion paper on agentic AI governance is still coming. This is unusually concrete regulator language. It is also written mainly for the institutions running the systems. The plain signal is that customers need a receipt. If an AI agent materially influences onboarding, fraud review, credit handling, wealth support, complaints or market-risk analysis, the person affected should receive a compact record of what happened. Not a thirty-page model card. Not a cheerful notice that artificial intelligence may have been used. A usable account of the decision path. The receipt should name the bank service, the agent or approved application, the action it took, the data categories it accessed, the evidence it relied on, the authority it was given, the human oversight that applied, and the route for correction or appeal. That sounds administrative. It is actually the customer-facing version of the regulator's own control logic. Accountability begins with intent. HKMA says a bank should be clear about what an agent is designed to achieve and carry that intent through the data, tools and actions available to it. The receipt should therefore begin with the job. Was the agent checking whether an identity document matched an application? Was it prioritizing a fraud alert? Was it preparing a market-risk analysis for an employee? Was it offering general support, or making a recommendation likely to shape a financial choice? Vague purpose creates elastic authority. An agent introduced to summarize documents can quietly acquire the ability to query accounts, update a case and message a customer. Each added tool turns a language model into a participant in the bank's operations. The receipt should state the boundary in verbs. Read documents. Compare fields. Request missing information. Draft a recommendation. Block nothing. Transfer no money. Escalate before contacting the customer. Then it should show what the agent actually did. Agentic systems are sequences, not magic beans. An orchestration layer may send a case to one model, retrieve account history, call a fraud service, ask another model to critique the result, and push a recommendation into a human queue. A single final label can hide the entire chain. The record needs a short event trail: which approved components acted, in what order, with which version and what outcome. It should distinguish source evidence from model-generated summaries. It should preserve confidence or uncertainty rather than converting every intermediate guess into an official fact. This matters because multi-agent systems can make error ownership pleasantly slippery. The first agent blames the data. The second blames the summary. The orchestrator blames the policy. The vendor blames the implementation. The customer receives a frozen account and a phone tree. A receipt pins the event to a named institutional owner. HKMA's second pillar is resilience. The regulator wants lineage across models, data, tools, infrastructure and third-party providers. For customers, that lineage should become a clear answer to a simple question: what must the bank reconstruct if this goes wrong? A bank should be able to replay the relevant workflow without exposing sensitive internal defenses. It should retain the approved agent version, tool permissions, evidence identifiers, policy version, human interventions and final action. If an outside model or service failed, the bank remains responsible for the customer outcome. This is where the kill switch enters the story. A switch is useful only if it is outside the system being stopped, reachable by an authorized person, tested under realistic load and paired with recovery instructions. Stopping new agent actions is one job. Canceling queued work, revoking credentials, isolating affected records and finding every customer touched by the faulty workflow are separate jobs. The receipt should survive the shutdown. An incident must not erase the evidence needed to repair it. HKMA's trust pillar focuses on the agent harness, the surrounding controls that translate a bank's risk appetite into boundaries. The phrase can sound like a neat leather strap around a very excitable horse. In practice it means identity, authentication, permissions, monitoring, validation, rate limits, data controls and intervention. Customers do not need every technical setting. They do need to know whether a person reviewed a consequential result before it took effect. HKMA acknowledges a shift from human-in-the-loop toward human-on-the-loop oversight. The distinction matters. In the first arrangement, a person approves an action before it happens. In the second, the system acts while a person monitors and can intervene. Human-on-the-loop can be reasonable for low-risk, reversible work. It is a poor comfort when an agent blocks access to money and the monitor sees the alert after the rent is due. The receipt should name the oversight mode. It should also state the service promise around correction. How quickly can a person pause the outcome? Which evidence will that reviewer see? Can the customer add missing context? Will the bank restore the prior state while the dispute is investigated? The regulator's sandbox results show why this cannot remain theoretical. HKMA reported examples in which AI helped one bank reduce customer-onboarding time by 40 percent, a wealth-management chatbot received 98 percent positive feedback, and a market-risk agent cut the cycle for a case-specific analysis by 95 percent. The same cohort reportedly achieved more sophisticated output with around 30 percent less computing power for similar use cases. These are regulator-reported outcomes from participating trials, not independent audits. They are promising signals, not universal bank performance. A faster process can still be wrong faster. Positive feedback does not measure whether advice was suitable. A shorter risk-analysis cycle does not prove that the analysis captured the right risk. The customer receipt makes the speed claim testable at human scale. Did onboarding become faster without raising false rejections? Did fraud detection reduce losses without trapping legitimate payments? Did personalized support improve understanding, or simply produce warmer prose? Did human reviewers spend less time on routine cases and more time on the difficult ones, or did the queue merely move out of sight? Banks can publish aggregate versions of these receipts. Report how many material agent actions occurred, how often humans intervened, how many customers appealed, how many outcomes changed, how long correction took, which agent versions caused incidents and whether the kill switch was tested. This is not a request to expose customer data or hand attackers a manual. It is a request to make responsibility measurable. The planned data-sharing platform raises a related question. HKMA says data quality assurance will be a core design principle. Before banks contribute or use shared training data, the platform needs public rules for provenance, consent or legal authority, permitted uses, access, retention, security, bias testing, correction and withdrawal. Synthetic or de-identified data can reduce some risks, but those labels need methods and limits. Customers should not have to wonder whether a dispute, call transcript or account event became training material for a system that later judged somebody else. Hong Kong's ART framework is useful because it treats an AI agent as an operational actor with dependencies and consequences, not as a chat window with excellent posture. Ownership, inventories, lineage, intervention and testing are the right machinery. Now that machinery needs a window facing the public. The bank should be able to say which agent acted, why it was allowed to act, what evidence it used, who watched it, how it can be stopped and how a person can correct the result. If the system cannot produce that receipt, it is not ready to touch the customer's life.
01
WHAT ACTUALLY CHANGED
HKMA announced the ART framework for Accountability, Resilience and Trust on October 15
The regulator issued supervisory guidance, sandbox lessons and a concept note on agentic AI
More than 60 percent of second-cohort sandbox use cases involved AI agents, according to HKMA
Half of the agentic use cases in that cohort were multi-agent applications
HKMA wants clear ownership and an up-to-date inventory for approved AI use cases
The framework calls for lineage across models, data, tools, infrastructure and third-party providers
Possible controls include restrictive actions and kill switches that can suspend agents
HKMA is exploring a centralized registry for material AI agents
Cyberport and the University of Hong Kong are collaborating on an AI training-data sharing platform
A further discussion paper on agentic AI governance is planned
02
WHY THIS MATTERS
Bank agents can move beyond advice into tool use, case updates and multi-step operational action
Customers may experience a consequential outcome without seeing the chain of agents and data behind it
An inventory helps the bank, while a customer receipt makes the same accountability visible to the affected person
Multi-agent workflows can spread responsibility across models, vendors, tools and orchestration layers
Dependency maps are necessary to reconstruct incidents and correct every affected case
A kill switch is meaningful only when it is independent, tested and paired with recovery procedures
Human-on-the-loop oversight may be inadequate for high-impact or difficult-to-reverse actions
Aggregate receipts can show whether faster service also improves accuracy, fairness and correction
03
WHERE IT COULD HELP
- Give customers a receipt when AI materially affects onboarding, fraud review or account access
- Name the approved agent, owner, purpose, version and authority for every consequential action
- Record the sequence of models, tools, evidence and human interventions
- Separate source evidence from model-generated summaries and recommendations
- State whether oversight was human-in-the-loop or human-on-the-loop
- Provide a clear correction, appeal and restoration path
- Test kill switches for queued work, credentials, isolation, evidence preservation and recovery
- Publish aggregate rates for intervention, appeals, reversals, incidents and correction time
- Document provenance, permitted use, retention and withdrawal rules for shared training data
- Require banks to remain accountable when an outside model or provider fails
KEEP A HAND ON THE WHEEL
Watch for the promised agentic AI discussion paper, the scope and operating rules of any centralized agent registry, the data-sharing platform’s provenance and access controls, independent evaluation of the sandbox performance claims, disclosure of customer appeal and reversal rates, evidence that kill switches are tested rather than merely documented, and clear thresholds separating human-in-the-loop from human-on-the-loop oversight.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 16, 2026.
PUBLICATION RECEIPT: The article separates HKMA guidance and sandbox claims from analysis proposing a customer-facing receipt, independent kill-switch tests and public accountability metrics.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US