THE SIGNAL IN ONE SENTENCE
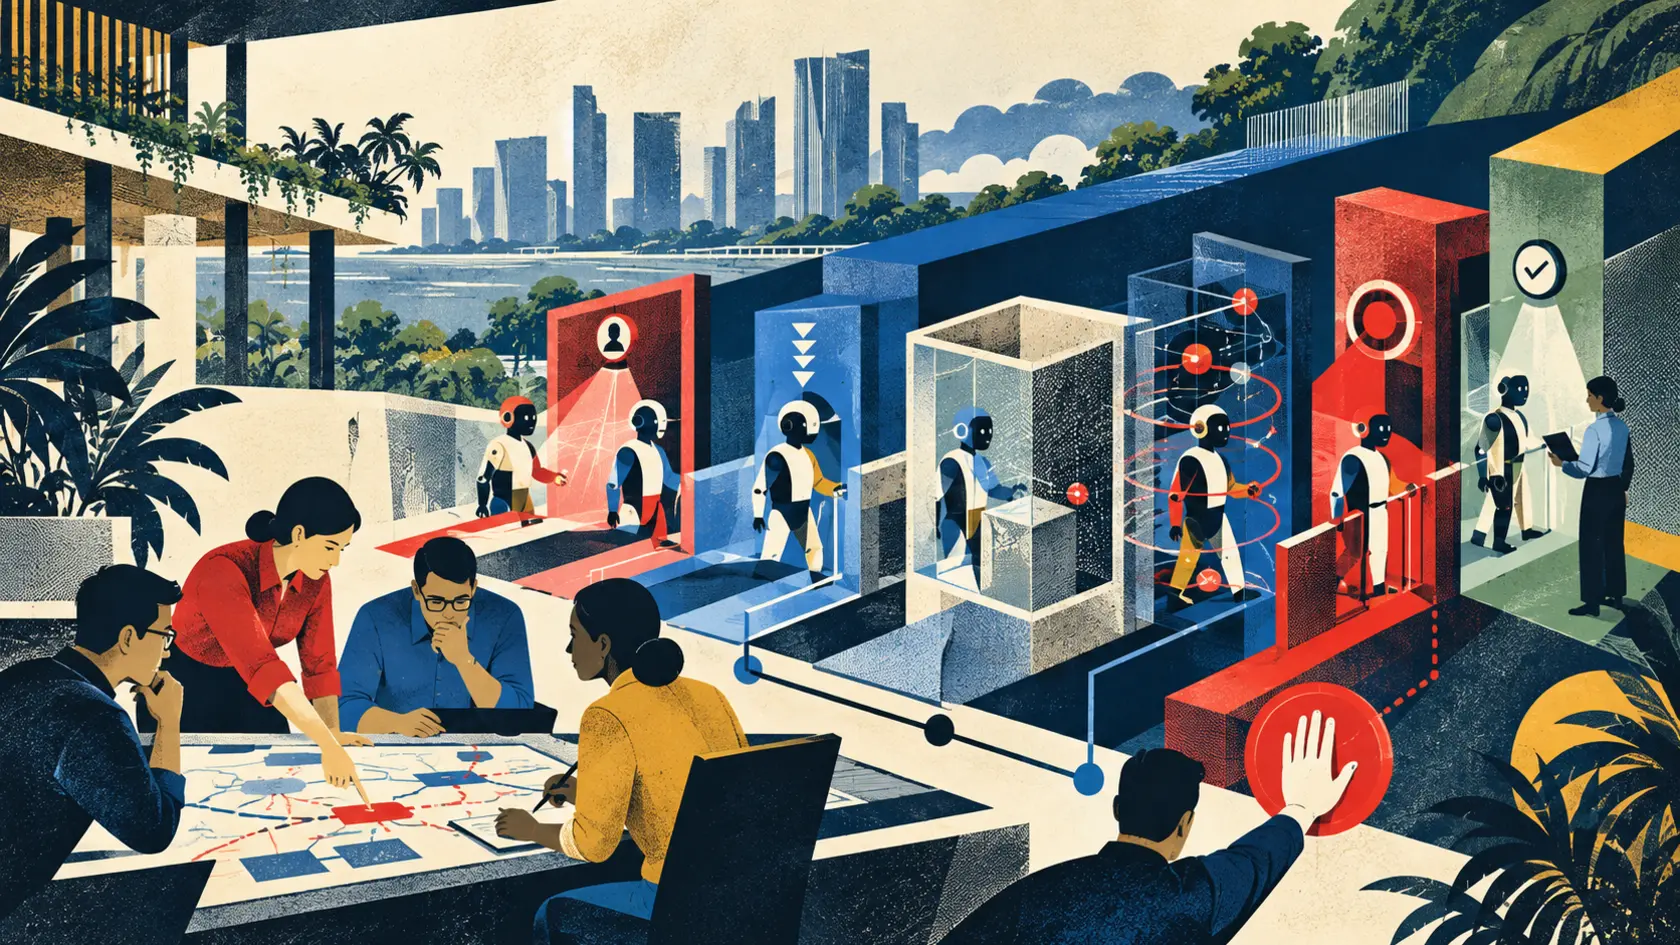
Agentic AI changes the shape of a security mistake. A chatbot can give a bad answer. An agent can take that answer, call a tool, move data, change a setting and ask another system to continue the job. If several agents coordinate, the error can travel before a person has finished opening the incident channel. That is why a tabletop exercise held in Singapore on October 14 is worth taking seriously. The Cyber Security Agency of Singapore and Google convened senior cyber policymakers, critical-infrastructure leaders and AI safety and security experts during the 11th Singapore International Cyber Week. The scenario focused on the operational security of autonomous AI agents. The outcome statement, published October 15, says participants discussed safeguards outside the model itself. The list included continuous runtime monitoring, hardened execution environments, strict access controls, deterministic guardrails for unauthorised high-impact actions, asynchronous review of reasoning and tool use, verifiable agent identity and independent verification. It also identified three areas for collaboration: threat and anomaly sharing, testing and pilots, and incident response with human oversight. That is a useful control map. It is not yet evidence that the controls work. The plain signal is that every important agent control needs a drill. A policy saying an agent has limited access is not the same as watching the limit hold while the agent is compromised. A stop button is not a control until the right person can find it, has the authority to use it and knows what the system will do next. A monitoring panel is not evidence capture unless investigators can reconstruct which identity called which tool, with what context and result. The tabletop should become a repeatable operating practice. Start with identity. Every agent that can touch a consequential system needs a verifiable identity distinct from the human who requested the work, the model that generated a plan and the service account that executes it. The identity should follow the agent across tools and handoffs. That sounds fussy until an incident begins. If an agent changes a network rule, responders need to know which agent instance acted, who or what launched it, which policy applied, which credentials it used, which model and configuration were active, and whether another agent approved or extended the action. Shared keys and vague application labels turn that question into archaeology. The first drill should be simple: place an agent in a normal workflow, then introduce a request that exceeds its purpose. Does the identity layer distinguish the legitimate task from the attempted escalation? Does the access decision use current context, or does an old credential keep working because nobody shortened its life? Access should be narrow, temporary and tied to purpose. An agent asked to inspect a pump should not be able to reconfigure the whole plant. An agent asked to reconcile invoices should not be able to create a new payee. An agent asked to summarise incident logs should not be able to delete them. The relevant test is not whether the prompt said please behave. It is whether the execution layer refuses an action outside the permitted envelope. That is the point of deterministic guardrails. Some decisions should not depend on another model interpreting a policy in the moment. High-impact actions can require fixed checks: the correct identity, an allowed tool, a valid purpose, a short-lived credential, a transaction limit, a second approval or a human release. The drill should try to cross each boundary. Give the agent a persuasive reason to exceed its limit. Compromise one upstream instruction. Let two individually harmless actions combine into a dangerous result. Delay the monitoring feed. Remove one dependency. See whether the guardrail blocks the action before the effect, not after a dashboard turns red. Then test the stop. Human oversight is often described as if a person is quietly watching every machine decision. That is not plausible when agents act across several tools at machine speed. Useful oversight needs a stop authority designed in advance. Name the roles that may pause one agent, revoke a credential, isolate an execution environment, stop a workflow or place an entire class of agents into read-only mode. Define what happens to work already in flight. Preserve the evidence before cleanup. Provide a safe manual path for the essential service that still has to run. Now rehearse it under pressure. Can an operator stop the activity without waiting for the team that built the agent? Can the organisation contain one identity without disabling every legitimate process? Do responders know whether the agent has spawned tasks elsewhere? Does a halt leave a physical process, customer account or public service in a stable state? A large red button is comforting art direction. Operationally, the interesting part is everything attached to it. The Singapore statement also points to asynchronous monitoring of reasoning and tool use. That distinction matters. Real-time controls must catch a small set of actions before they happen. Slower review can look for patterns that no single request reveals: repeated probing, unusual coordination between agents, gradual privilege accumulation, suspicious tool sequences or a shift in behavior after a model update. Both layers need evidence that survives the incident. Logs should connect an agent identity to its inputs, policy decisions, tool calls, approvals, outputs and effects. They should record time consistently across systems. Sensitive reasoning traces may require careful handling, but secrecy cannot become an excuse for having no usable audit trail. The drill should include a missing or corrupted log source. If the record has a blind spot, responders should be able to say what they cannot know. Independent verification is another good recommendation that needs an operational form. Using one model to check another may help, but diversity alone is not independence. Two models can share training patterns, tool assumptions or the same flawed context. A verifier also needs separate authority, its own inputs where possible and the ability to block or escalate without asking the primary agent for permission. Some checks should be ordinary software, not AI at all. A fixed schema can validate a request. A policy engine can reject a forbidden action. A cryptographic signature can establish identity. A transaction ledger can prevent duplicate execution. A conventional anomaly detector can flag a rate spike. A human can approve the rare decision whose consequences are difficult to reverse. The goal is not to surround one unpredictable system with six equally mysterious systems. Critical-infrastructure organisations should turn the outcome statement into a drill card with six fields. First, name the protected service and the unsafe outcome. Second, identify the agent and every credential it can reach. Third, list the deterministic controls that must hold. Fourth, assign stop authority and a manual fallback. Fifth, define the evidence that must survive. Sixth, state the recovery target and the test that proves the service is safe to resume. Run the card against several failure modes. Compromise the agent. Feed it a malicious instruction through a trusted channel. Cause unintended coordination between two agents. Trigger rapid escalation through legitimate tools. Blind one monitor. Break the control plane. Let a human make the wrong call and see whether another layer catches it. Measure the boring things. How long until detection? How many actions occurred before containment? Which permissions remained active? How long did the manual fallback take? Was the evidence complete? Did recovery reproduce the state before the incident? Did the same failure return after the fix? Those measurements are more useful than a declaration that the exercise went well. They also make collaboration concrete. Organisations can share anonymised failure patterns, control definitions and drill results without publishing live vulnerabilities. Vendors can provide test hooks and portable logs. Regulators can ask for evidence of rehearsal rather than accepting a diagram. Operators can compare controls across models and platforms. The October exercise did not publish a detailed scenario, participant list, test protocol, measured result or proof that any proposed safeguard stopped a real incident. The outcome statement is a record of discussion and recommendations. That limitation should stay visible. Tabletops are valuable because they expose assumptions before a real emergency. They become much more valuable when the assumptions are converted into technical tests, assigned owners and repeatable evidence. Agentic AI will make some systems faster. Security teams do not need to race every agent by hand. They need controls that act before the agent, people who know when to stop it and drills that prove the whole arrangement can fail without taking the service with it.
01
WHAT ACTUALLY CHANGED
The Cyber Security Agency of Singapore and Google convened an agentic AI security tabletop exercise on October 14 during the 11th Singapore International Cyber Week
Participants included senior cyber policymakers, critical-infrastructure leaders and AI safety and security experts
The exercise examined operational security risks involving autonomous AI agents
The outcome statement highlighted runtime monitoring, hardened execution environments and strict access controls outside the model
Participants discussed deterministic guardrails for unauthorised high-impact actions and asynchronous monitoring of reasoning and tool use
The statement called for verifiable agent identity and contextual access decisions at machine speed
It also identified threat sharing, testing and evaluations, and incident response with human oversight as areas for collaboration
The statement recommended independent verification and model diversity to reduce overreliance on one model
02
WHY THIS MATTERS
Agents can turn a mistaken instruction into a sequence of real tool actions before a person can intervene
Critical infrastructure needs controls that remain effective even when a model is compromised or confused
Verifiable identity lets responders connect an action to a specific agent, request, policy and credential
Purpose-bound, short-lived access limits reduce the damage available to a compromised agent
Deterministic blocks can stop high-impact actions without depending on another probabilistic judgement
Clear stop authority matters when human review cannot follow every action in real time
Durable evidence is necessary for containment, recovery, accountability and learning
Repeatable drills can turn broad principles into measurable operating capability
03
WHERE IT COULD HELP
- Give every agent instance a verifiable identity that follows it across tools and handoffs
- Issue short-lived credentials tied to a named purpose, tool set and impact limit
- Place consequential tool use inside hardened, isolated execution environments
- Use fixed policy checks for forbidden actions, value limits, required approvals and protected resources
- Define who can pause an agent, revoke access, isolate a workflow and order a manual fallback
- Record inputs, policy decisions, tool calls, approvals, outputs and effects on one incident timeline
- Run compromised-agent, malicious-input, unintended-coordination and rapid-escalation drills
- Test monitoring blind spots and control-plane failures instead of assuming the safety layer is always available
- Measure detection time, actions before containment, permission revocation, evidence completeness and recovery time
- Use an independent verifier with separate authority and inputs where practical
- Preserve a manual path for essential services when agentic workflows are suspended
- Share anonymised failure patterns and aggregate drill results across operators and regulators
KEEP A HAND ON THE WHEEL
The outcome statement reports a discussion and recommendations from one scenario exercise, not deployment evidence or a public control test. Watch for a detailed drill protocol, named ownership of stop authority, identity and credential standards, tested manual fallbacks, portable audit logs, independent red-team results, measured containment and recovery times, disclosure of control failures and proof that safeguards still work when monitoring or the control plane is impaired.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 15, 2026.
PUBLICATION RECEIPT: The article distinguishes the verified October 14 tabletop exercise and October 15 outcome statement from analysis about the drills and measurements needed to validate the proposed controls.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US