THE SIGNAL IN ONE SENTENCE
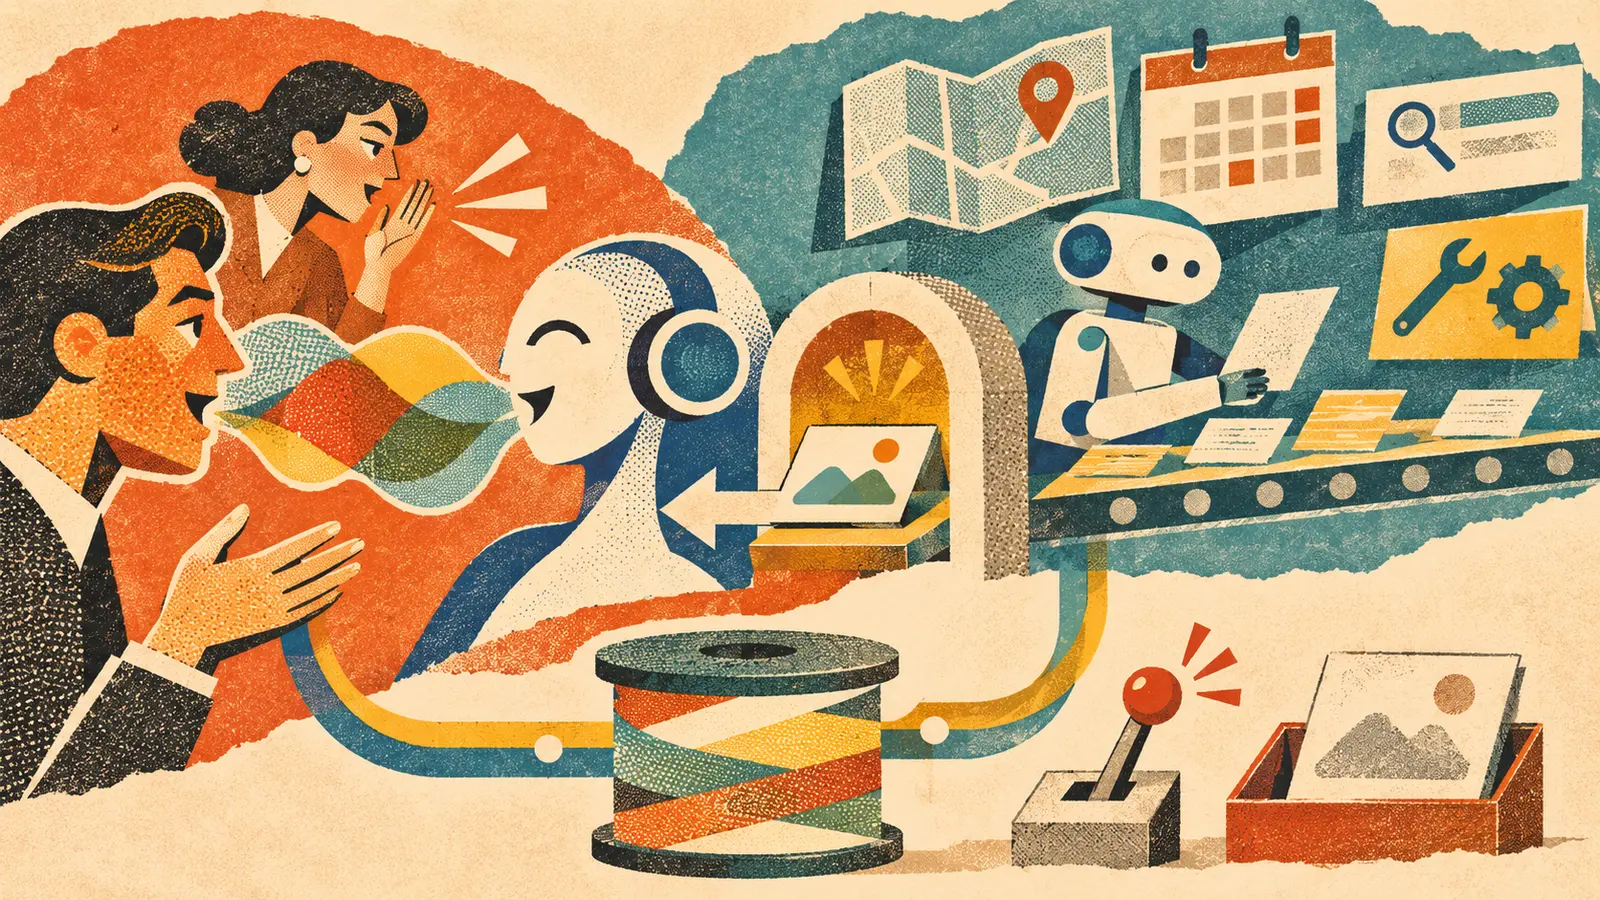
Most voice assistants still behave like someone holding a walkie-talkie. You speak. They wait. They think. Then they speak while you politely pretend not to interrupt. MOSS-Live is trying to make that rhythm feel more like a real conversation. The OpenMOSS team describes a full-duplex system that can listen and speak at the same time, respond to interruptions and backchannels, track live video, use tools in the background and return to the conversation when a task is ready. Its public demonstrations include a group meeting, a road trip around Zhoushan and a guide in Shanghai. The interesting part is not just that the assistant can talk over the sound of its own machinery. It is how the machinery is divided. MOSS-Live uses a foreground interaction model for listening, turn taking and speech. A background task model handles longer reasoning, tools and jobs that should not freeze the conversation. A coordination layer shares memory, context and task state between them. That gives the assistant two clocks. On the foreground clock, a person may interrupt, correct a name, change the destination, revoke permission or ask a new question. On the background clock, a search may still be running, a calendar request may be pending or a route may have been calculated from instructions that were true 20 seconds ago. The product challenge is no longer only whether the model can hear and answer. It is whether those two timelines can meet without smuggling stale instructions into the final reply. Imagine asking a voice assistant to find dinner near the station while you continue talking with a friend. The background model starts a search. A few seconds later you add that one person has a severe peanut allergy. The assistant acknowledges the correction and keeps the conversation moving. What happens to the search already in flight? If the allergy update changes only the conversational memory, the tool can finish with an unsafe result. If the background task sees the update but does not reveal that it restarted, the user may not know why the answer is delayed. If both timelines write to shared memory at once, an older tool result can overwrite the newer constraint. If the user says cancel, the foreground voice can sound reassuring while the background action continues. This is why every live agent needs a two-timeline handoff. The handoff should begin when a background job starts. Give the job an identity, start time, initiating user request and a versioned snapshot of the constraints it received. Show whether it can only read, whether it can change something and which tools or services it may touch. Then keep a change log while the conversation continues. A correction, interruption, new preference, consent change or cancellation should be written as an event with a timestamp and a consequence for the job. The background task should either accept the update, restart under the new constraints, pause for clarification or declare that the change arrived too late. When the tool returns, the result should carry its own timestamp and dependency list. Which location did it use? Which date? Which people? Which allergy, budget or access constraint? Which version of the conversation state? A result is not current merely because it arrived last. Before the assistant speaks the result, the coordination layer should compare the result against the newest user state. If the state changed, the assistant can say what happened in plain language: the first search finished using your old location, so I discarded it and ran a new one. That is a tiny sentence with a lot of trust inside it. Cancellation deserves the same rigor. A spoken stop should not be a decorative phrase. The foreground model needs to send a cancellation signal to the background task, receive an acknowledgement and disclose any action that could not be reversed. If a reservation was already submitted or a message already sent, the assistant must not pretend that silence erased it. The OpenMOSS article reports strong results on the team's selected evaluations. On FDB v3, the project reports a 51.00 percent tool-use success rate, tied for the best figure in its comparison. On tau-Voice, it reports 57.93 percent multi-turn task success, second highest in the presented table. In a tool-use breakdown, the team reports 95.68 percent tool-selection F1, 72.17 percent argument accuracy, 66.00 percent semantic success, 83.00 percent post-tool response quality and 2.36 seconds of latency. Those figures are useful signals, not field guarantees. They come from the project and selected benchmark settings. They do not establish how the system handles a noisy kitchen, overlapping speakers, code switching, a poor connection, a child in the room, a revoked permission or a tool that returns after the conversation has changed. A benchmark can score whether a tool was called. It rarely captures whether the human understood which version of their request the tool actually used. The public repository also deserves a sober reading. At verification time it was a very small repository with a single visible commit, documentation and media assets. No public model weights or complete implementation were visible in the reviewed listing. That makes the architecture and demonstrations inspectable as a proposal, but it does not yet give outside teams the material needed for full reproduction. There is still plenty worth learning from the design. Splitting interaction from task execution is sensible. A slow search should not make the assistant deaf. A person should be able to interrupt a long explanation without destroying a useful background job. A live camera feed can help a guide respond to what someone is seeing now. Streaming interpretation can preserve conversational rhythm instead of waiting for complete paragraphs. But shared memory is not magic glue. It is a concurrent system. Software engineers already know the failure modes: races, stale reads, partial writes, duplicate work, conflicting updates and actions that finish after cancellation. Voice makes those failures harder to inspect because the interface disappears as soon as the sentence ends. A pleasant voice can turn uncertainty into false confidence with remarkable efficiency. So publish the state. Not as a wall of developer telemetry. Give the user a compact live card or spoken summary showing what the assistant is doing, which request version it is using, whether the job is read-only or can take action, when it last incorporated a correction and how to stop it. Keep the detailed event log available for review after the conversation. For higher-stakes tasks, the handoff should require confirmation. Before sending money, booking travel, changing a record or contacting another person, read back the final action using the newest constraints. Name anything that changed while the task was running. Ask once, clearly, at the point of consequence. The privacy problem runs on two timelines too. A system that continuously listens, watches video and shares memory across models may capture bystanders, private surroundings and conversations that were never meant for the assistant. Selective attention is not consent. The product should make microphone and camera state obvious, separate wake and record behavior, minimize retention, let users inspect and delete stored memory and avoid training on ambient material without a specific choice. Group conversations need special care. One person may invite the assistant while everyone else is merely present. A backchannel such as yes or right can be conversational grease, not authorization. The system should not turn an overheard remark into a tool instruction unless the speaker, intent and permission are clear. The useful future here is not a machine that never stops talking. It is an assistant that stays present while work continues, then tells you exactly which conversation produced which action. MOSS-Live makes the two-clock architecture unusually visible. That is valuable. Now the handoff needs to be just as visible: start state, live changes, tool state, cancellation, freshness check and final claim. Conversation can feel natural. Consequences still need paperwork.
01
WHAT ACTUALLY CHANGED
OpenMOSS published MOSS-Live on November 7 as a full-duplex multimodal assistant architecture. The project says the system can listen and speak at the same time, handle interruptions and backchannels, use live vision, run tools in the background and support streaming interpretation and proactive triggers.
The architecture separates live interaction from longer work. A foreground interaction model handles listening, speech and turn taking. A background task model handles reasoning, tools and longer jobs. A coordination layer shares memory, context and task state.
The team published demonstrations across several conversational settings. The reviewed examples include a group meeting, a road trip around Zhoushan and a guide in Shanghai, with the assistant continuing the interaction while background work proceeds.
The project reports competitive results on selected evaluations. Its published tables show 51.00 percent tool-use success on FDB v3 and 57.93 percent multi-turn task success on tau-Voice, plus a detailed tool-use breakdown covering selection, arguments, semantics, response quality and latency.
The public release is currently easier to inspect as a technical proposal than reproduce as a complete system. At verification time the public repository had one visible commit and contained documentation and media assets, while no model weights or complete implementation were visible in the reviewed listing.
02
WHY THIS MATTERS
A live assistant can keep listening while a tool works. That reduces dead air and makes interruption possible, but it also allows the conversation to change before the task finishes.
Foreground acknowledgement does not prove background cancellation. The system needs a confirmed path from spoken correction or stop command to the task that can still act.
The newest result may rely on old instructions. Every tool response needs a freshness check against the latest location, people, time, preferences, permissions and safety constraints.
Shared memory creates concurrency risk. Two models can read and write state at different times, producing races, duplicated work, stale updates or an older result that overwrites a newer instruction.
Voice can hide uncertainty. A fluent spoken answer disappears quickly and may sound more settled than the underlying task state. Users need a visible or reviewable event record.
Continuous audio and video affect people beyond the account holder. Selective attention does not replace notice, consent, retention controls or a clear boundary between conversation and authorization.
03
WHERE IT COULD HELP
- Give every background task a unique identity, start time, initiating request and versioned constraint snapshot.
- Show a compact live task card with status, current request version, tools in use, last update and stop control.
- Write every correction, interruption, permission change and cancellation as a timestamped event linked to affected tasks.
- Require the background task to accept an update, restart, pause for clarification or declare that the change arrived too late.
- Attach location, date, people, preferences, safety constraints and memory version to every returned result.
- Compare tool output with the newest conversation state before presenting it, and discard or label stale results.
- Make cancellation a confirmed protocol with acknowledgement, final status and disclosure of any irreversible action.
- Require a fresh readback and confirmation before money, bookings, messages, record changes or other consequential actions.
- Separate conversational backchannels from authorization so an overheard yes does not approve a tool call.
- Expose microphone, camera, recording and memory state continuously, including when the assistant is silent but still sensing.
- Let users inspect, correct and delete shared memory, and record which task versions consumed each memory item.
- Test overlapping speakers, noisy rooms, late tool responses, network loss, duplicate callbacks, stale memory and cancel-after-submit behavior before deployment.
KEEP A HAND ON THE WHEEL
MOSS-Live was published November 7 by the OpenMOSS team. The reviewed evidence is the team's technical article and public repository. The demonstrations, architectural descriptions and benchmark results are project-authored and were not independently reproduced for this article. The reported results come from selected evaluation settings. A 51.00 percent tool-use success rate on FDB v3 and 57.93 percent multi-turn task success on tau-Voice do not predict performance for every language, accent, room, device, tool, network condition or real-world consequence. The detailed tool-use figures, including 95.68 percent tool-selection F1, 72.17 percent argument accuracy, 66.00 percent semantic success, 83.00 percent post-tool response quality and 2.36 seconds of latency, are project-reported. Different hardware, endpoints, prompts and service delays can change both accuracy and response time. At verification time the public repository had one visible commit and a small set of documentation and media files. No public weights or complete implementation were visible in the reviewed listing. A public repository name should not be mistaken for a fully reproducible release. Full-duplex conversation does not guarantee correct speaker identification, safe interruption handling or reliable cancellation. A spoken acknowledgement can arrive before a background tool has stopped, and some external actions cannot be reversed after submission. Shared memory can improve continuity while also spreading stale or sensitive information across tasks. Teams should version state, restrict write authority, log dependencies and test conflict resolution rather than treating shared context as a single reliable truth. Always-listening microphones and live cameras can capture bystanders and private surroundings. Product teams need obvious sensing indicators, consent appropriate to the setting, strict retention limits, access controls and practical deletion. Selective attention is a model behavior, not a privacy guarantee. Examples in this article such as task receipts, versioned constraints, cancellation acknowledgements, freshness checks and confirmation gates are editorial recommendations. They are not all confirmed product features of MOSS-Live. Finally, a detailed event log can itself contain audio transcripts, location, health information, private images and tool output. Protect it with least privilege, limited retention and redaction that preserves accountability without duplicating sensitive material unnecessarily.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 9, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US