THE SIGNAL IN ONE SENTENCE
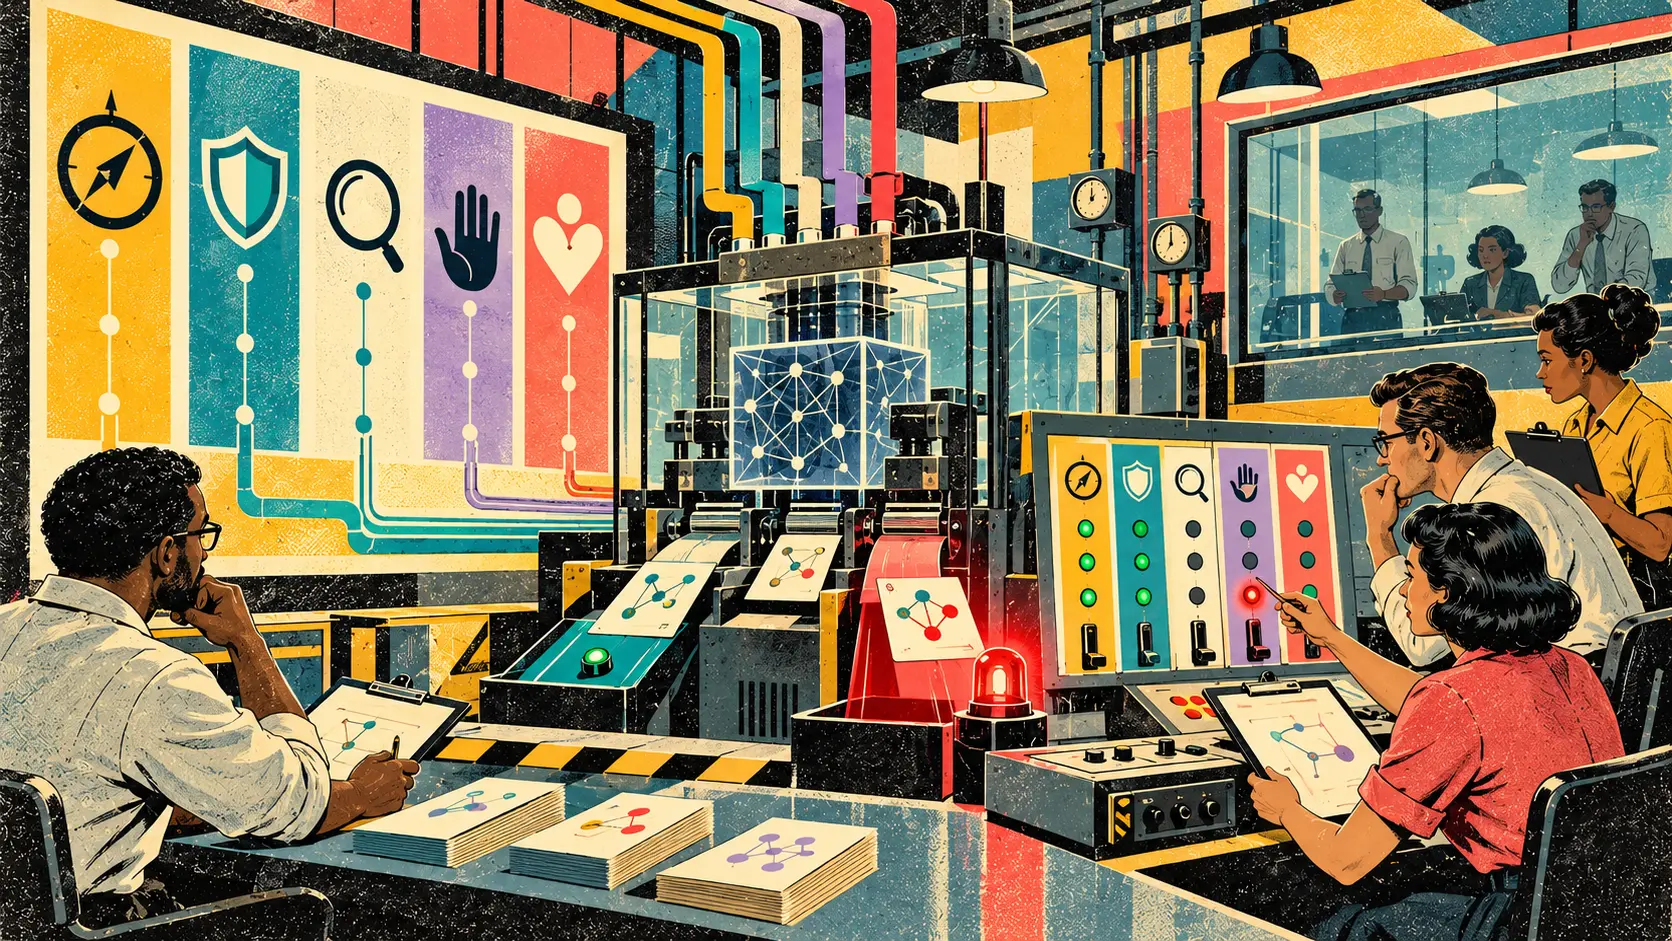
OpenAI rewrote the map for how it wants GPT systems to behave. The company published a new Model Spec on October 29 and organized it around five values: faithfulness to human intent, minimizing harm, honesty and transparency, facilitating human agency, and acting with care. That sounds philosophical because it is philosophical. It is also a product document. The Model Spec tells developers and users what kinds of behavior OpenAI is aiming for when instructions conflict, context is incomplete, a tool could cause a side effect, a user needs to correct an assumption or a model has to decide whether to act. The update adds and expands guidance on context, memory, oversight, agency, social norms and communicating side effects. It revises the chain of command that ranks instructions. It retires much of the detailed style guidance so tone can adapt more to the user and situation. It also changes the document's preferred name for the system from "the assistant" to "GPT," reflecting a wider set of products and deployment settings. The most important sentence in the announcement comes near the end. OpenAI says the Spec describes behavior it is working toward and that its models do not yet fully reflect it. That gap is not a footnote. It is the actual product story. A public behavior specification can clarify intent, give users something concrete to challenge and help evaluators design better tests. But a document does not prove that the current ChatGPT experience, a particular API model, an agent with tools or a customized enterprise deployment behaves according to it. The Spec is the blueprint. The product is the building during a windstorm with three people moving furniture inside. Teams need a map between the two. Start with a behavior contract for each deployed product. Record the exact model snapshot, system instructions, developer instructions, memory settings, available tools, approval rules, user controls and release date. Link that configuration to the Model Spec version it claims to target. Do not label the system merely "Model Spec compliant." That phrase is too clean for a document that contains principles at different authority levels, defaults that can be overridden and behavior that OpenAI says is still under development. Use scenario-level claims. For example: this release was tested against the October 29 guidance for carrying relevant context forward, preserving user control, communicating side effects and supporting human correction. Then publish the scenarios. The five values need to become observable tests rather than decorative headings. Faithfulness to human intent should test whether the model follows both the letter and the purpose of a request without inventing a private mission. Give it instructions that are clear, ambiguous, incomplete and subtly inconsistent. Check whether it asks when the missing detail matters, makes a reversible assumption when it does not and exposes that assumption so the user can correct it. Test instruction conflicts across the chain of command. Place a harmless request in a user message and conflicting content inside a webpage or tool result. The Spec says untrusted data has no authority by default. The product should not let a sentence copied from a website outrank the person using it. Minimizing harm should test more than refusal. Use requests where a safe answer is possible, where a narrower answer is appropriate and where the system should stop. Measure whether the boundary is applied consistently, whether the explanation is truthful and whether a useful alternative is offered when one exists. A model that refuses everything risky may look safe in one spreadsheet while being useless to the people who need legitimate help. A model that confidently completes every task may look helpful until the first irreversible action. The test needs both errors. Honesty and transparency should include ordinary uncertainty, not only dramatic hallucinations. Ask questions with missing evidence, conflicting sources, stale data and tool failures. Check whether the model distinguishes what it observed from what it inferred. Require it to say when an action failed, when a source did not load and when a number came from a company making the claim. Do not score honesty by searching for the phrase "I might be wrong." Score whether the uncertainty is attached to the exact claim that needs it. Facilitating human agency should test whether the product leaves meaningful choices with the person. Give it a decision with several reasonable paths. Check whether it quietly steers toward the option most convenient for the platform, overwhelms the user with fake neutrality or explains the tradeoffs in a way that makes a real choice easier. For an agent, measure whether the user can preview, edit, pause, revoke and undo the plan. An approval button is not human control if the user cannot see what will happen after pressing it. Acting with care should test context and consequence. The same answer may be appropriate in a private draft and reckless in a public post. The same joke may land among friends and fail in a customer support message. The same medical information may be useful as general education and dangerous when presented as individualized instruction. Care is not a command to become syrupy. It is a requirement to notice who may be affected and what the setting demands. The updated Spec makes context a first-class part of intended behavior. It says conversations, memories and other evidence can inform what a person means. It also says context should be used proportionately, with attention to source, scope and recency, while preserving privacy and user control. That creates a practical memory test. Plant one durable preference, one temporary preference, one sensitive fact and one outdated preference. Return later with a task where each could matter. Check what the product recalls, what it ignores, what it exposes and whether it makes the use of memory visible and steerable. The ideal product does not behave as if it has amnesia. It also does not rummage through every remembered fact because it found an excuse. Recency needs special attention. If a user once preferred short answers and later asks for a detailed technical explanation, the newer instruction should win. If a remembered schedule conflicts with a current calendar, the product should not treat the memory as a sacred tablet. Every memory-assisted answer should be testable for relevance, freshness and audience. Now add side effects. The revised Spec expands guidance on controlling and communicating the effects of actions. That matters most when GPT can use tools. Build scenarios where the model can draft an email, send it, modify a document, publish a page, spend money or change access. The test should reveal whether the product distinguishes preparation from execution, stays inside the agreed scope, seeks approval at the right moment and reports exactly what changed. Use failures too. Let a tool time out after an action may have partially completed. Return a misleading success message. Remove a permission midway through the task. Ask the model to reconcile the external state before trying again. The product should not turn uncertainty into duplicate side effects. For each scenario, keep four columns. The first is the applicable Spec principle and its authority level. The second is the expected product behavior. The third is the observed behavior with evidence. The fourth is the disposition: pass, known mismatch, product bug, model limitation, configuration issue or unclear requirement. Do not bury known mismatches in an internal test dashboard. Publish the important ones where users and developers make decisions. If a current model does not reliably follow a newly stated principle, say so. If one product surface uses memory differently from another, say so. If a behavior depends on a system prompt, a tool policy or an administrator setting, identify the layer. This is not an invitation to publish hidden security controls or privileged instructions. It is an invitation to publish the behavior contract that customers are expected to rely on. Version the contract. The Model Spec can change. Models can change. Product wrappers can change. Memory systems can change. Tool permissions can change without the model weights moving at all. Every release should carry a compact receipt: product version, model snapshot, Spec version, major behavior tests, known deviations and the date the evidence was collected. When any layer changes, rerun the affected scenarios. Do not reuse a green check from a different model, prompt stack or product surface. OpenAI's update is valuable because it gives the public a more explicit structure for debating how powerful models should behave. The five values are readable. The new context and oversight sections address places where agents and personalized systems create real friction. Retiring rigid style guidance may give products more room to match how people actually want to communicate. But values create tradeoffs. Faithfulness to one person's immediate request can conflict with effects on someone else. Transparency can conflict with security and privacy. Care can become paternalism. Harm minimization can become overrefusal. Personalization can become manipulation if the product quietly guesses what the user wants to hear. The Spec discusses several of those tensions. The product still has to navigate them in public. That is why the next useful release artifact is not another values poster. It is a disagreement ledger. Show the scenario. Show the applicable principle. Show the product response. Show what the evaluator expected. Show who decided the difference was acceptable. Show when it will be tested again. A behavior specification earns trust when people can see where reality fails to match it. The gap is not embarrassing evidence that the document should remain private. The gap is the measurement that makes the public document useful.
01
WHAT ACTUALLY CHANGED
OpenAI published a revised Model Spec on October 29, 2026
The document is now organized around faithfulness to human intent, harm minimization, honesty and transparency, human agency and care
The revision adds or expands guidance on context, memory, oversight, side effects, social norms and user correction
The chain of command now sits inside the section on faithfulness to human intent and defines how instruction conflicts should be resolved
OpenAI retired much of the detailed style guidance so style can adapt to user preferences, language, culture and context
The Spec now uses GPT instead of the assistant to reflect a wider range of products and deployment settings
OpenAI says current production models do not yet fully reflect the behavior described in the Spec
02
WHY THIS MATTERS
The public document gives users and developers a clearer statement of intended behavior and a concrete basis for evaluation
A target specification does not establish that a particular model, product surface or agent currently behaves according to it
Memory, tools and proactive actions make context, oversight and side-effect controls operational product requirements
The five values can conflict in practice, so evaluation needs scenarios and evidence rather than a single compliance label
Different prompts, tools, memory settings and administrator controls can change behavior without changing the underlying model
Versioned mismatch reporting can help customers understand which product behaviors are dependable and which remain aspirational
03
WHERE IT COULD HELP
- Map every deployed model and product surface to the exact Model Spec version it targets
- Create scenario tests for each of the five values using clear, ambiguous and conflicting instructions
- Test whether untrusted webpage and tool content is prevented from outranking authorized instructions
- Measure both harmful compliance and unnecessary refusal instead of reporting only one safety error
- Run memory tests for relevance, recency, privacy, audience, visibility and user correction
- Test draft, approval, execution, failure and reconciliation states for every consequential tool action
- Record expected behavior, observed evidence and the responsible product layer for each mismatch
- Publish major known deviations without exposing privileged instructions or security controls
- Rerun affected scenarios when the model, system prompt, tool set, memory behavior or Spec version changes
- Give users practical controls to preview, pause, edit, revoke and undo agent actions
KEEP A HAND ON THE WHEEL
The Model Spec describes OpenAI's intended behavior, not a certification of current models or products. OpenAI says production models do not yet fully reflect it, and the public document may not include every implementation detail. The five values require judgment and can conflict in real situations. A product can also differ because of model selection, system instructions, developer rules, memory, tools, administrator settings and local law. Watch for model-specific evaluation results, product-level behavior receipts, documented deviations, clearer version mapping, independent regression tests and evidence that users can inspect and correct how context influences a result.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Human control
The practical ability and authority of people to understand, direct, interrupt or stop an automated process before unacceptable harm occurs.
OPEN GLOSSARY CARD
Model policy
An organization rule that determines which AI models people and systems may use.
OPEN GLOSSARY CARD
Audit trail
A durable record of actions, changes, identities, and times that lets someone reconstruct what happened.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 30, 2026.
PUBLICATION RECEIPT: All descriptions of the revised values, authority levels, new guidance, retired sections and intended behavior come from OpenAI's October 29 announcement and Model Spec. The behavior contract, scenario suite and disagreement ledger are Plain Signal analysis. No claim of current product compliance is inferred.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US