THE SIGNAL IN ONE SENTENCE
Red Hat is adding tools that help companies see who used shared AI hardware, what it cost, whether one team crowded out another, and how a model behaved before it was released. Some features are ready for general use, while others remain previews or early access.
01
WHAT ACTUALLY CHANGED
Red Hat announced AI 3.5 on September 10 with a noticeably unglamorous mission: make shared AI infrastructure behave like infrastructure. The release report describes controls for evaluating models, observing inference, allocating graphics processors, separating tenants, tracking usage, and changing models without abruptly breaking the applications that depend on them.
EvalHub is the new evidence desk. Red Hat says it can benchmark models for safety before deployment and produce compliance-related evidence. Models in the AI Catalog can carry Garak safety scores plus information about exposure of personally identifiable information and toxicity. That gives a platform team something more concrete than a model name and a vendor promise, although a score is not a safety certificate.
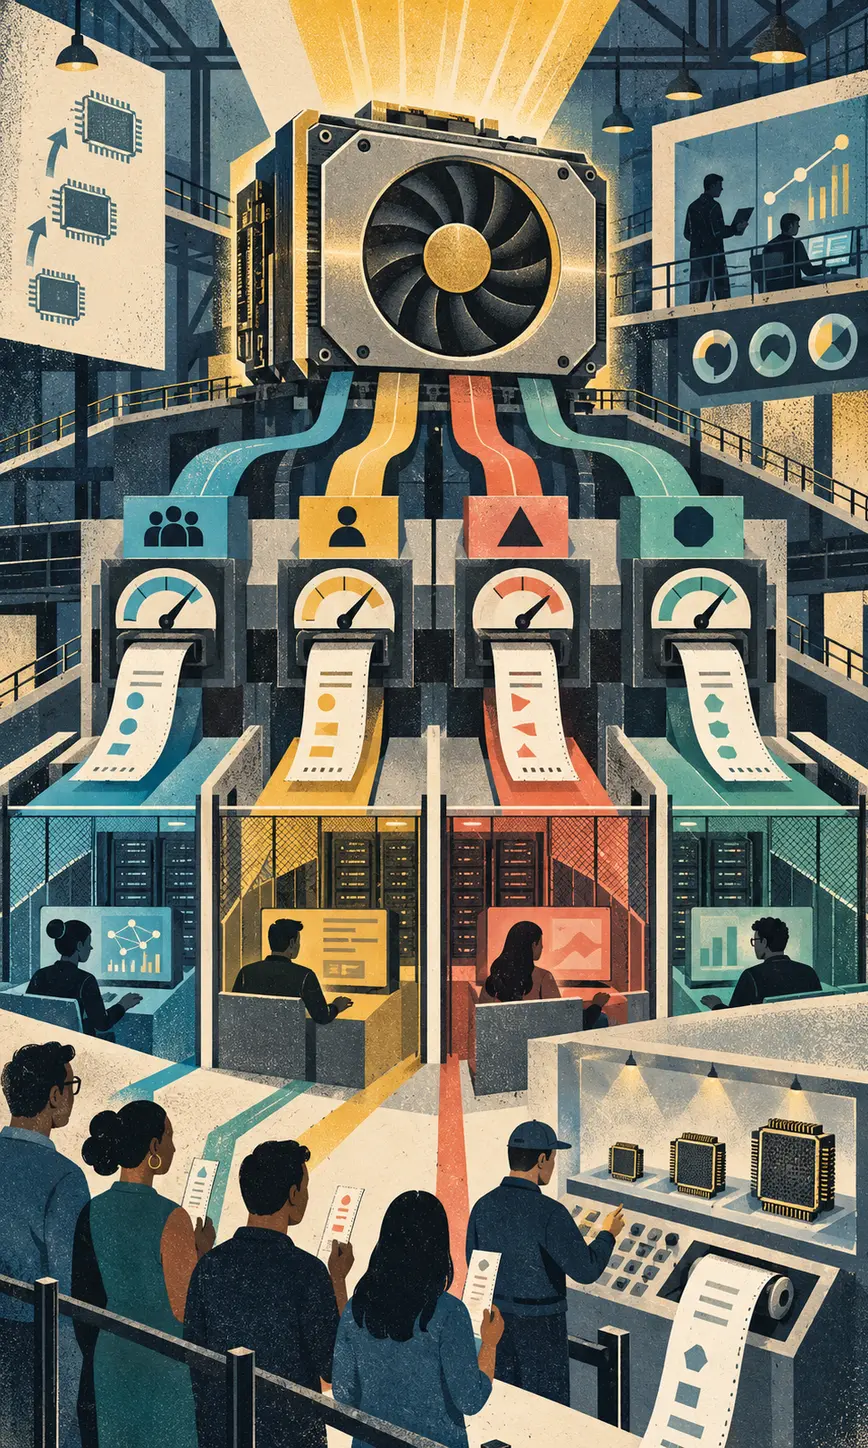
The receipts arrive through observability and usage accounting. Dashboards cover inference health, model performance, hardware inventory, and GPU utilization. Non-administrator users can see their own token consumption for monitoring and showback. Showback does not necessarily send a bill. It tells a team how much shared capacity it consumed so costs can stop hiding inside one mysterious infrastructure total.
Red Hat also describes fair-share GPU scheduling across tenants and priority-aware serving with admission control. A customer-facing inference request can move ahead of a background batch when capacity is tight. Hosted control planes on OpenShift Virtualization give tenants separate cluster control planes while hardware remains consolidated, and virtual machines provide another isolation boundary around GPU-enabled workloads.
Feature maturity matters here. The release report identifies CPU offloading as generally available and storage offloading as a developer preview. Support for the Responses API and built-in retrieval-augmented generation is generally available. Multimodal serving through vLLM Omni is early access. Distributed inference is generally available on CoreWeave CKS and Microsoft Azure, while Amazon EKS is a technology preview. The Kubeflow Spark Operator is also a developer preview.
02
WHY THIS MATTERS
A single GPU can cost more than the car in the parking lot, which makes sharing attractive. Sharing also creates a tiny office politics simulator inside the cluster. One team launches a long experiment, another needs a fast production response, and everyone insists their workload is urgent. Fair scheduling and explicit priority turn that argument into a policy the platform can enforce.
Usage records change the conversation about AI cost. Without per-user or per-team evidence, a successful pilot can become an invoice nobody can explain. Token consumption, GPU utilization, and inference health help operators distinguish a genuinely valuable service from a forgotten endpoint quietly eating capacity. They also make budgeting, internal allocation, and capacity planning less theatrical.
Evaluation evidence can make model selection more disciplined. A catalog entry that includes repeatable safety tests, privacy exposure, toxicity risk, and tool-calling suitability is more useful than a leaderboard with one heroic score. But teams still need tests built around their own data, languages, users, permissions, and failure costs. A generic evaluation is the beginning of due diligence, not the end.
Controlled rollouts matter because a model update can change behavior even when the API remains stable. Routing a small share of traffic to a new version, comparing results, and rolling back on failure is familiar software practice. Bringing that pattern into model serving lets an organization treat weights, prompts, guardrails, and inference engines as production changes rather than acts of faith.
The larger signal is that enterprise AI is becoming an operations discipline. The differentiator is moving away from merely getting a model to answer and toward proving who can access it, how resources are divided, what the system costs, what evidence was collected, and what happens when an upgrade misbehaves. Nobody makes a cinematic launch video about showback. The finance and security teams will still ask for it on Monday.
03
WHERE IT COULD HELP
- Give teams self-service visibility into token consumption and shared GPU use
- Reserve priority for latency-sensitive inference while batch work uses spare capacity
- Evaluate models for safety, privacy exposure, toxicity, and tool use before deployment
- Separate tenant control planes and workloads on consolidated GPU infrastructure
- Roll out new models gradually, compare production behavior, and reverse unsafe changes
KEEP A HAND ON THE WHEEL
The detailed feature account comes from a September 10 release report carrying Red Hat’s announcement and executive statement. Red Hat’s primary announcement and version 3.5 documentation were not publicly indexed or reachable when this article was verified. Availability labels therefore need confirmation against customer documentation before procurement or production use. Generally available, developer preview, technology preview, and early access do not carry the same support or stability expectations. Garak scores and catalog evaluations do not prove a model is safe, compliant, private, unbiased, or suitable for a specific organization. The public report does not provide complete pricing, licensing, hardware requirements, service-level guarantees, regional availability, or benchmark methods.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Showback
A usage report that shows a team what shared technology resources it consumed and what those resources cost, without necessarily charging the team directly.
OPEN GLOSSARY CARD
Multi-tenancy
An arrangement where several users, teams, or customers share underlying infrastructure while their access, workloads, and data remain logically separated.
OPEN GLOSSARY CARD
Controlled rollout
A staged release that sends limited traffic to a new version, watches the results, and allows a quick reversal before wider deployment.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on September 10, 2026.
PUBLICATION RECEIPT: Revision 1. Published September 10, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US