THE SIGNAL IN ONE SENTENCE
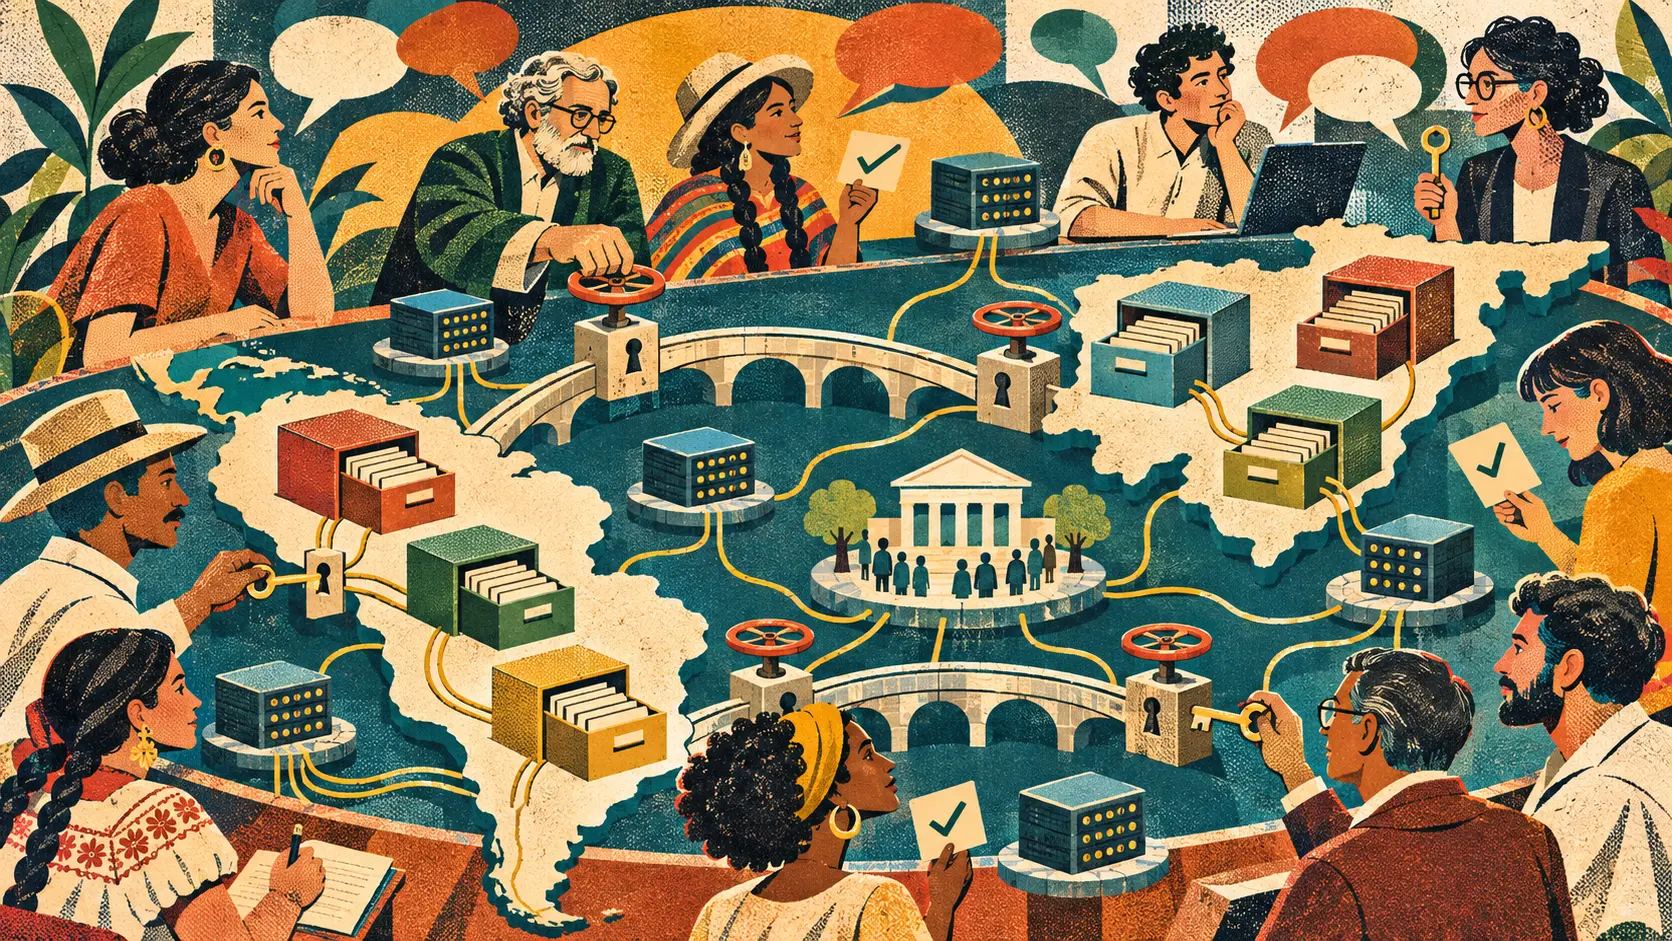
A federation is a group project where nobody hands the teacher one giant USB drive. That is the useful promise inside the new Ibero-American Artificial Intelligence Alliance agreed in Madrid on November 3. Ministers and digital authorities from across Ibero-America adopted a declaration organized around three things: access to useful data, AI models adapted to the region's languages and needs, and shared use of existing computing capacity. The first part deserves close attention. Spain's Ministry for Digital Transformation says the proposed Ibero-American Data Space will be federated. It will not be a single regional database. Each participating country will decide which information it shares and under what conditions, while keeping national rules and control in place. That distinction is not bureaucratic garnish. It is the difference between cooperation and a very large bucket. The alliance is voluntary. The ministerial agreement was scheduled to be elevated to heads of state and government at the Ibero-American Summit on November 4 and 5. When verified, the public documents did not provide final membership, budgets, dataset inventories, licenses, compute allocations, governance votes or delivery dates. So this is a political and technical direction, not a finished platform. The direction is still important. Ibero-America spans very different public institutions, legal systems, research networks, infrastructure, industries and communities. Spanish and Portuguese connect much of the region, but they do not exhaust its languages. Indigenous, regional and sign languages carry knowledge and public-service needs that large general models routinely flatten or overlook. A federated design can let a health ministry, statistical office, university, archive or local-language project keep custody of its material while making a defined portion available for an approved use. The data may remain where it is. A model, query or controlled computation can travel to it. Only permitted results should return. That is the clean diagram. Real life adds lawyers, procurement systems, missing metadata, old servers, disputed rights and the occasional spreadsheet named final_final_2. The alliance's other two pillars are meant to connect to the data layer. The declaration proposes a shared technological base from which countries or sectors could adapt models for national, linguistic and practical needs. The official materials point to existing initiatives including Spain's ALIA, Portugal's AMALIA, Chile-led LATAM GPT and the Dominican Republic's SoberanIA as foundations to coordinate rather than replace. It also proposes organizing access to computing capacity that already exists in the region. The ministry says the aim is to match supply and demand without requiring a new regional computing complex. A separate summit process has discussed stronger regional supercomputing coordination alongside the AI alliance. There are sensible public uses hiding in that structure. A small university could request a controlled run on infrastructure it cannot afford alone. A public-service team could adapt a model to a national legal vocabulary. Researchers could study climate, agriculture or disease across borders without copying every underlying record into one warehouse. A language community could help define an evaluation set and decide which cultural material should never become training data. But federation does not make the politics disappear. It moves the politics into permissions. Who has the authority to approve a dataset? Does a ministry own the right to share records collected from people for a different purpose? Can a national decision override an Indigenous community's governance? Does a public archive's digitization contract permit model training? If a country withdraws permission, can the consortium identify every derivative dataset, model adapter and cached result that used the material? Those are not edge cases. They are the operating system. The alliance needs a public permission ledger. For every participating dataset, start with authority. Name the institution, law, agreement or community process that allows access. Separate custody from rights. A ministry may host a file without owning every right inside it. Record purpose next. Training a translation model, answering an approved research query and building a commercial assistant are not the same use. Permission for one should not silently become permission for all three. Then record the people represented. A national label is too blunt. A dataset may contain children, patients, workers, migrants, farmers, artists or speakers of a language that has survived because a community guarded it carefully. The ledger should show who was consulted, who can object and who receives value when the material improves a model. Make every permission time-bound and revocable. Store the start date, review date, withdrawal method and the exact systems affected by a change. A veto that exists only in a meeting document is not much of a veto. Track movement and computation separately. If raw data stays in country but model updates leave, say so. If only aggregate results return, define the privacy test. If a model adapter can memorize protected material, treat that adapter as a governed output rather than a harmless little attachment. Add the model receipt. Name the base model, adaptation method, training records, evaluation languages, failure tests, release terms and operator. A shared technological base can still produce many local systems with very different risks. Add the compute receipt too. Show who received scarce capacity, for how long, at what public cost and under which priority rules. Shared infrastructure can widen access, or it can become a queue where the largest institutions always know the right person to call. Finally, publish outcomes. Did the project improve a public service? Did it support a language that commercial systems neglect? Did local researchers gain durable skills and infrastructure? Did the communities represented in the data receive access, compensation, governance power or useful tools in return? The official declaration places rights, sustainability, inclusion, security and privacy around the alliance. It also contemplates nonbinding standards for data protection and digital government. Those are good headings. They are not yet evidence that a specific dataset, model or compute allocation satisfies them. Voluntary cooperation also has a structural limit. A country can join a project without accepting a strong common enforcement mechanism. A nonbinding standard can help institutions align, but it cannot resolve every conflict between national law, community authority, research access and commercial pressure. That does not make the alliance empty. It makes the receipts essential. If the federation works, countries should be able to cooperate without dissolving their authority into a regional pool. Language communities should be able to participate without donating themselves to a model. Smaller institutions should gain access to compute without losing control of their research. Public money should produce public capability, not merely subsidize another private API bill. The architecture can support that. A federation can keep data near its stewards, move approved computation to the data and preserve national control. But the architecture will not enforce the promise by itself. Every bridge needs a gate. Every gate needs an owner. Every opening needs a purpose, an expiry and a record of what crossed. Keep that ledger public enough to inspect, detailed enough to audit and simple enough for an affected person to understand. Then each country's veto becomes more than a diplomatic sentence. It becomes a working control.
01
WHAT ACTUALLY CHANGED
Ibero-American ministers and digital authorities adopted the Madrid Declaration on digital transformation and artificial intelligence on November 3.
The declaration creates a voluntary Ibero-American Artificial Intelligence Alliance organized around data access, locally relevant models and shared access to existing computing capacity.
The proposed Ibero-American Data Space is federated rather than one regional database, with each country deciding what it shares and under which conditions.
The model pillar proposes a shared technological base that can be adapted for countries, languages, sectors and specific uses.
The official materials identify ALIA, AMALIA, LATAM GPT and SoberanIA as existing initiatives that can contribute to the regional effort.
The compute pillar aims to coordinate existing capacity and match supply with demand instead of requiring a new regional computing complex.
The ministerial agreement was scheduled to be elevated to the November 4 and 5 Ibero-American Summit of heads of state and government.
02
WHY THIS MATTERS
A federated design can support cross-border research and public services while leaving data under national or local custody.
The region needs models and evaluations that cover Spanish, Portuguese, Indigenous, regional and sign languages rather than treating linguistic diversity as an afterthought.
Shared access to existing compute could widen participation for universities, public agencies and smaller research teams that cannot fund major infrastructure alone.
National control does not automatically protect community rights, purpose limits or people whose records are represented in a dataset.
A visible permission ledger can make authority, approved uses, withdrawals, model derivatives and public returns inspectable across the federation.
The agreement is still voluntary and incomplete, so budgets, membership, licenses, allocations and enforcement will determine whether the promise becomes public infrastructure.
03
WHERE IT COULD HELP
- Create a public registry for every participating dataset, model adaptation and compute allocation.
- Name the legal, institutional or community authority that permits each data use, and separate physical custody from intellectual, cultural and privacy rights.
- Define the approved purpose, prohibited uses, eligible operators, start date, review date and withdrawal process for every permission.
- Record the people and language communities represented, how they were consulted and what value returns to them.
- Keep raw-data movement, remote computation, aggregate outputs, model updates and cached artifacts as separate ledger events.
- Attach a receipt to every adapted model with its base model, training sources, languages, evaluations, license, operator and known limitations.
- Publish compute-allocation criteria, queue position, public cost, energy use, duration, operator and completed work.
- Test whether permission withdrawal reaches copied data, indexes, checkpoints, adapters, evaluation sets and downstream systems.
- Require independent security, privacy and bias tests before a shared service reaches people in health, education, employment, justice or benefits.
- Report public outcomes, including service quality, language coverage, local research capacity, community benefit and unresolved harms.
KEEP A HAND ON THE WHEEL
This is a ministerial agreement and proposed alliance, not a completed data space or deployed regional model. Membership is voluntary. The reviewed official sources do not provide final participating countries, budgets, governance votes, dataset inventories, licenses, compute allocations, delivery dates or independent performance evidence. A federated architecture can reduce central collection but does not by itself settle consent, community authority, cross-border law, model memorization, cybersecurity, procurement or unequal access to compute. Watch for the final summit record, formal membership, governance documents, data and model licenses, community representation, allocation rules, withdrawal tests, public audits and evidence that benefits return to the people and institutions supplying data and knowledge.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on November 4, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US