THE SIGNAL IN ONE SENTENCE
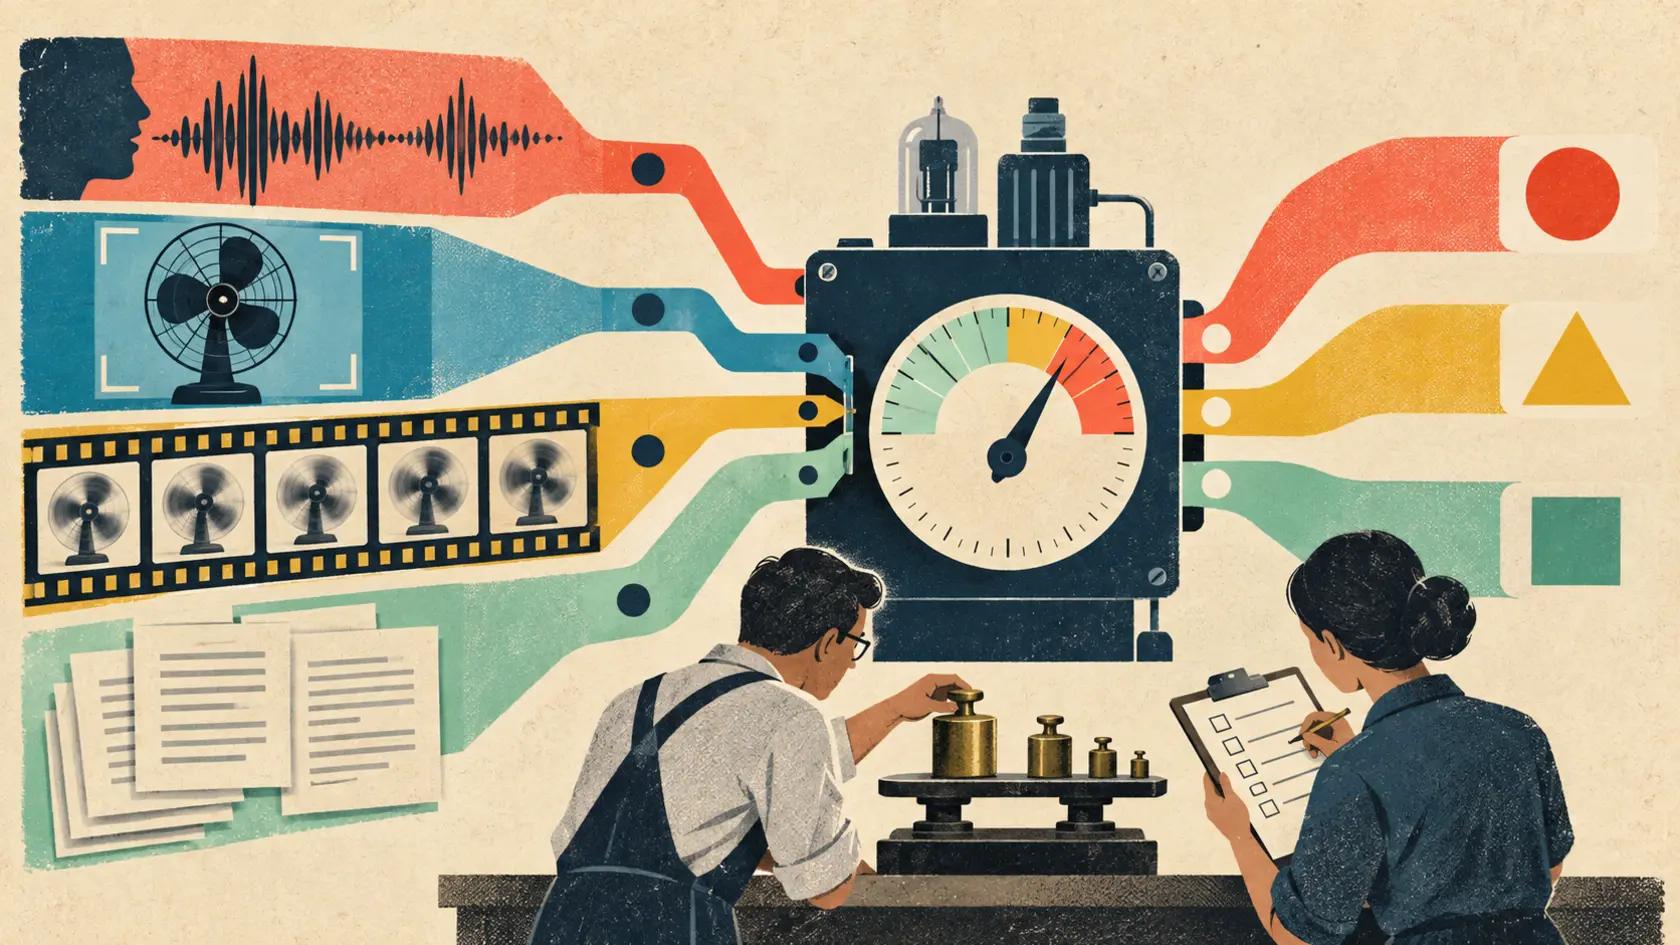
A machine does not become trustworthy merely because it answers with a decimal instead of a paragraph. Cloudflare released Clef-omni on October 9, one week after introducing its first Clef decision models. The new model can receive text, JSON, images, audio and video, then score a set of allowed answers in one forward pass. It does not draft a response or explain itself in free-form language. Give it a state, a question and a bounded menu of options, and it returns probabilities. That is a useful shape for software. A maintenance system could ask whether a photographed equipment label is visible, whether a recording contains grinding and whether a fan is moving in a video. A support workflow could combine a customer's message with a call recording and decide which approved queue receives the case. A safety tool could score a clip against a defined set of review categories without asking a general-purpose model to write a small essay and hoping another program can parse it. The release makes those decisions easier to build. It does not make the confidence scores portable by default. That is the plain signal: multimodality expands the evidence a decision model can inspect, while also expanding the number of ways its probabilities can lose contact with reality. Clef-omni is an open-weight, mixture-of-experts model built from the comprehension side of Qwen3-Omni-30B-A3B-Instruct. Cloudflare kept the vision and audio encoders, discarded the speech-output path for this use, and added a joint schema head that scores every allowed option. The model card describes a 30-billion-parameter model with about three billion active parameters per token. The repository is available under the Apache 2.0 license. Cloudflare's hosted version accepts common audio and video formats alongside text and images. The local model card says video files are sampled at two frames per second and that their soundtracks can be processed with the visual frames. It returns one logit for every allowed option, then applies a softmax within each question to produce probabilities. That last word needs care. A softmax turns relative scores into numbers that add to one. It does not prove that an answer labeled 90 percent will be correct nine times out of ten in a particular warehouse, language, call center or weather condition. Calibration is an observed relationship between stated confidence and outcomes. It has to be measured on the work that actually matters. Cloudflare publishes a broad evaluation table, and the results are not a simple victory lap. The company reports Clef-omni at 98.2 percent on the BFCL case-exact benchmark, 92.7 percent accuracy on API-Bank and 66.6 on ToolRet's ranking metric. Those are company-run results using the Decision Index 0.2.1 suite. The end-to-end workflow scores are a sharper warning against reading too much into the polished probability output. Cloudflare reports 60.2 percent exact actions for invoice processing, 71.6 percent for customer service and 61.7 percent for security incidents. On agent-trace observability, Clef-omni scored 65.8 percent for the primary action, below the other published models in the table. The original Clef or smaller Clef-flash also beat Clef-omni on several listed tasks. That is not a failure of the release. It is evidence that adding ears and a camera does not automatically improve a job that mainly depends on text, labels or a particular decision boundary. The new model is most interesting when information genuinely crosses media. Consider an equipment inspection. A photo may show the correct model and serial label. Audio may reveal a rattle that the image cannot. Video may show the fan turning but miss an intermittent wobble between sampled frames. A written work order may say the unit was serviced yesterday. Clef-omni can consider these channels together and return a bounded decision. Now change the room. Move the same unit beside another machine. Record it with a cheaper phone. Compress the video. Add an accent to the spoken note. Shoot the label through glare. Drop several frames. Place the microphone inside a protective case. The equipment did not change, but the evidence reaching the model did. That is distribution shift in work clothes. Multimodal systems also create disagreement problems. The note says the repair is complete, while the video shows a panel still open. The camera timestamp and audio recording do not align. One channel is missing. A file has sound but no usable picture. A transcript loses the warning hidden in tone. The system needs an explicit policy for conflict, absence and uncertainty. Otherwise, one vivid channel may quietly dominate the decision. Cloudflare's architecture removes text generation and output parsing from the hot path. That can reduce latency and prevent the model from inventing an answer outside the approved schema. It does not remove the need for abstention. If the evidence is poor or the channels disagree, the allowed answers should include send to review, request another recording or insufficient evidence. The cost and speed changes elsewhere in the Clef family reinforce the attraction of putting these models into busy workflows. Cloudflare cut hosted Clef-flash input pricing from $0.09 to $0.038 per million input tokens. Clef remains $0.24, while Clef-omni launched at $0.15 per million input tokens. The cheaper hosted Clef-flash now has a 24,000-token context window instead of the previously advertised 64,000. Cloudflare says only 0.24 percent of observed requests exceeded 24,000 tokens. Its downloadable weights remain untouched and were trained for a 256,000-token context, according to the company. Cloudflare also reports that serving changes made hosted Clef between 1.7 and 2 times faster at the tested input sizes. The company says the improvement came mostly from infrastructure work, including a move to SGLang, rather than new weights. Cheaper and faster can make decision models practical at larger volume. It can also make an untested threshold fail at larger volume. The safe rollout begins in shadow mode. Let Clef-omni score real cases without controlling them. Preserve the input conditions and eventual outcomes. Then ask whether cases assigned 80 percent actually resolve that way at roughly the expected rate. Break the answer down by modality, language, device, location, lighting, noise, file length and consequence. Do not calibrate only the top choice. A model may select the correct queue often while overstating its certainty. That difference matters when software uses confidence to decide whether to act automatically or involve a person. Thresholds should follow the cost of error. A low-confidence product tag can be corrected later. A security block, medical escalation, insurance decision or workplace-safety instruction carries a different burden. The same model score should not trigger the same action everywhere. Teams should also compare the multimodal model with simpler baselines. If text alone performs as well for ticket routing, feeding every call recording into a larger model adds privacy, storage, latency and governance cost without adding useful evidence. If audio makes the difference for mechanical inspection, measure exactly which audio conditions preserve that benefit. Open weights help. A team can run Clef-omni on infrastructure it controls, inspect the serving code and build tests without sending every recording to a hosted service. The model card says the documented bfloat16 setup needs about 64 GB of GPU memory on a single Nvidia H200. Open licensing therefore makes the model portable in principle, not necessarily lightweight on ordinary hardware. Local deployment does not erase the data problem. Audio and video can contain faces, voices, bystanders, conversations, locations and other information that the person operating the workflow did not intend to collect. A useful decision system needs rules for consent, minimization, access, retention and deletion before the first production upload. It also needs a record of model and media versions. A new phone camera, codec, microphone, frame sampler or compression setting can change performance without a model update. Monitoring should treat those input-pipeline changes as releases, not invisible plumbing. The most practical design is a ladder. Start with the smallest evidence set that solves the job. Add a modality only when it improves a defined outcome. Test calibration on local cases. Route uncertainty to a person. Record what happened. Recheck the relationship between confidence and reality after devices, users, policies or environments change. Clef-omni makes the machine able to hear and watch. The harder work is teaching the organization when not to believe what it thinks it saw.
01
WHAT ACTUALLY CHANGED
Cloudflare released Clef-omni on October 9 as an open-weight multimodal decision model
The model accepts text, JSON, images, audio and video and returns probabilities across allowed answers without free-form text generation
Clef-omni is post-trained from Qwen3-Omni-30B-A3B-Instruct and published under the Apache 2.0 license
Cloudflare launched hosted Clef-omni at $0.15 per million input tokens
Hosted Clef-flash pricing fell from $0.09 to $0.038 per million input tokens while its hosted context window fell from 64,000 to 24,000 tokens
Cloudflare reports hosted Clef serving improvements of 1.7 to 2 times at its tested input sizes
02
WHY THIS MATTERS
A bounded probability output is easier for software to consume than prose, but the number still needs calibration against real outcomes
Audio and video enable useful cross-media decisions while introducing noise, device, codec, timing and privacy failure modes
Published workflow scores show that multimodal support does not make Clef-omni the best Clef variant for every task
Lower cost and latency can move decision models into high-volume operational paths where a bad threshold scales quickly
Open weights improve portability, but the documented local setup still requires substantial GPU memory
Input-pipeline changes can alter performance even when the model version stays the same
An abstention and human-review path remains necessary when channels conflict or evidence is incomplete
03
WHERE IT COULD HELP
- Combine equipment photos, operating sounds, video and work orders for bounded maintenance triage
- Route customer cases using a message and call recording while preserving a human-review option
- Score approved safety or moderation categories without parsing free-form model prose
- Run shadow evaluations before allowing a score to control a production action
- Measure calibration separately by device, language, media quality, environment and consequence
- Include insufficient evidence and request another sample among the allowed outcomes
- Compare multimodal performance with text-only and single-modality baselines before collecting more data
- Version cameras, microphones, codecs, frame samplers and preprocessing alongside the model
- Set retention and consent rules for audio and video before production use
KEEP A HAND ON THE WHEEL
Cloudflare produced the release, pricing, latency measurements and benchmark results cited here. The model card describes internal evaluation runs rather than independent replication, and the published workflow scores vary considerably by task. A softmax probability is not evidence that confidence is calibrated for a particular deployment. Local teams still need outcome data, subgroup checks, threshold testing, drift monitoring and a human-review lane. The documented self-hosted setup uses a single Nvidia H200 with about 64 GB of GPU memory in bfloat16. Audio and video can capture personal information and bystanders, so the decision architecture must include consent, minimization, retention and deletion controls.
04
TERMS WORTH KEEPING
OPEN GLOSSARY CARD
Decision model
A model that scores a defined set of allowed answers so software can make a bounded choice without parsing free-form prose.
OPEN GLOSSARY CARD
Distribution shift
A change in the people, data, devices or environment that makes production inputs differ from the conditions used to test a model.
OPEN GLOSSARY CARD
Calibration
Measuring and adjusting a system so its controls and readouts match how the hardware actually behaves.
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 10, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US