THE SIGNAL IN ONE SENTENCE
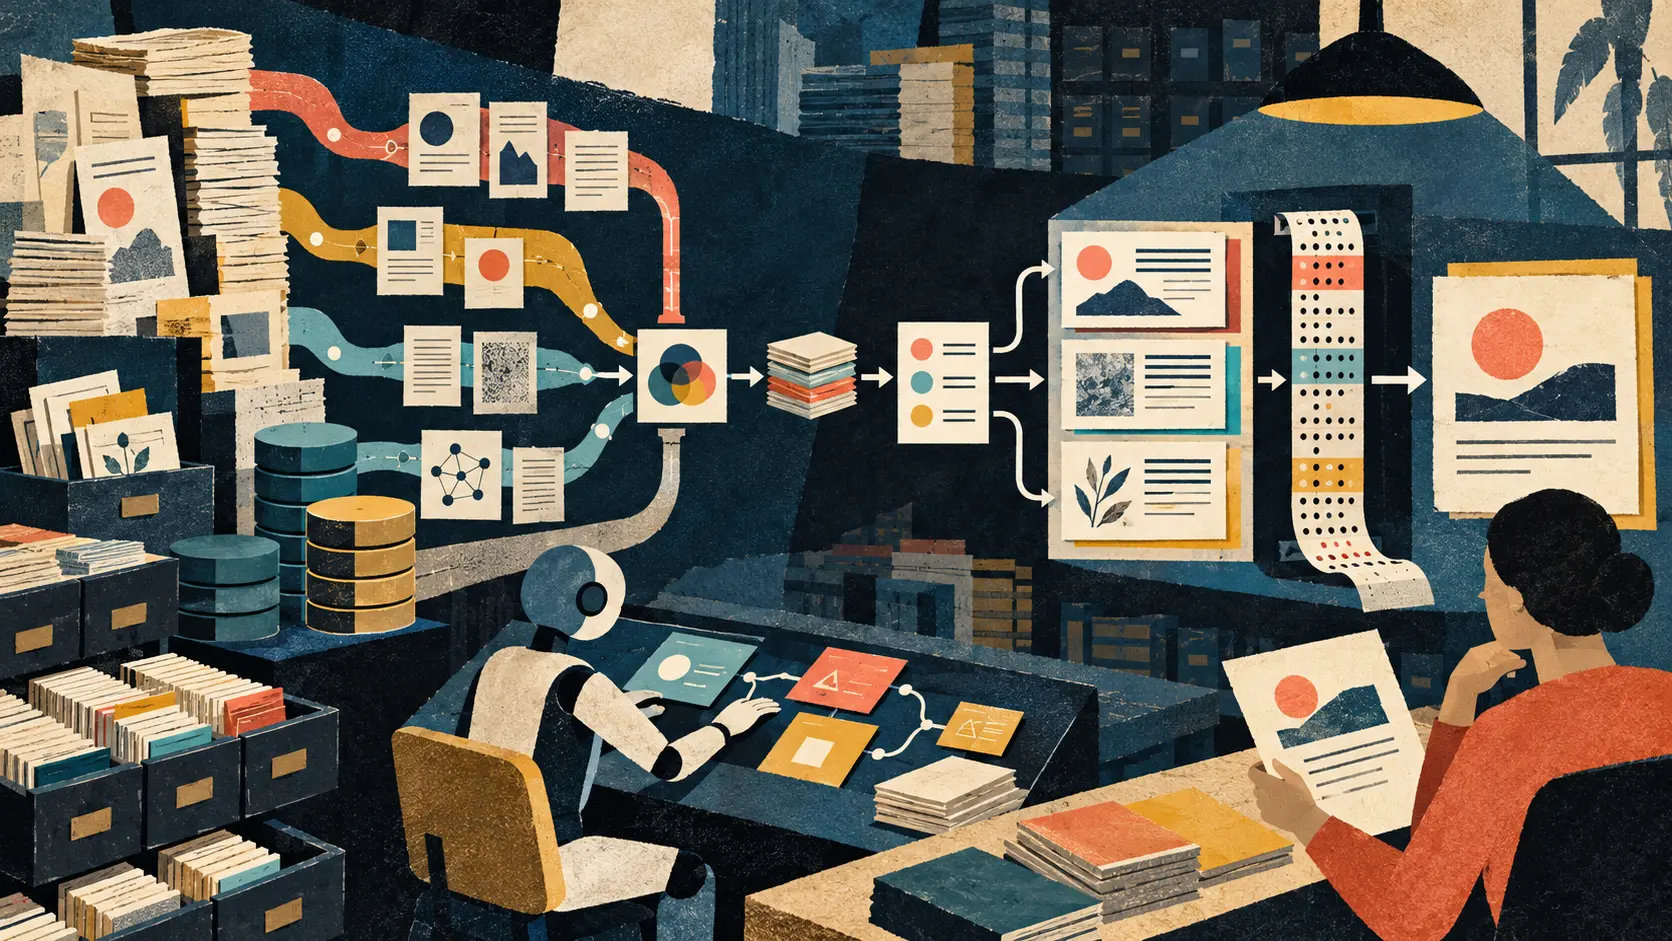
A search agent usually shows you the answer and, if you are lucky, a few citations. It rarely shows you the little retrieval machine it built to find them. Meta researchers published a paper on October 20 about Retrieval Program Learning, or RPL. Instead of asking a language model to call one fixed search tool at a time, RPL lets the model write a short executable program from a set of retrieval primitives. Those primitives include dense retrieval for semantic similarity, sparse retrieval for lexical matching, reciprocal-rank fusion, deduplication and reranking. The program can run several searches with different queries, keep intermediate results in local state, combine candidate lists and choose which documents enter the model context. That is a meaningful shift. The model is no longer only deciding what to search for. It is deciding how search itself should work for this question. The plain signal is this: save the retrieval program with the answer. If an agent writes code that determines which sources are found, discarded, combined and shown to the answering model, that code is part of the answer's provenance. The final citations tell you what survived. The program tells you how the evidence was selected. The researchers tested RPL with Qwen3 models at 4 billion and 8 billion parameters. For open-domain question answering, they trained on Natural Questions and HotpotQA, then evaluated on seven single-hop and multi-hop benchmarks using a 2018 Wikipedia snapshot. The author-reported results were strong. The 4B RPL model reached an average exact-match score of 0.515 across the seven benchmarks. That exceeded every tested 8B baseline, including Search-R1 at 0.494 and AutoRefine at 0.487. The 8B RPL model reached 0.531. The biggest gains appeared on multi-hop questions, where useful evidence may be split across documents and one search result can change the next query. RPL also performed best in the paper's GlobalQA experiments, which ask models to count, sort, select top results and find extrema across a corpus. The researchers report the highest average answer F1 and document-coverage F1 for both model sizes. The efficiency story may be more interesting than the leaderboard. A normal retrieval loop often pours raw documents into the model context. Search more broadly and the prompt gets longer. RPL can search a large candidate set inside the program, process those results and print only selected evidence or an aggregate result for the model. In the paper's GlobalQA comparison, RPL used between 1.00 and 1.27 retrieval turns at convergence. MARAG-R1 used 2.00 to 4.61 and Search-R1 used 2.18 to 2.24. The authors report training up to about 5.8 times faster than Search-R1 and 2.2 times faster than MARAG-R1 in that setup. Those numbers are benchmark results, not a production service-level agreement. Still, the design principle is practical: retrieval breadth and context consumption do not have to be the same knob. An agent can inspect one hundred candidates without making the answer model read one hundred documents. That efficiency creates a new blind spot. Suppose the model searches for a company announcement with dense retrieval, searches for a regulatory filing with lexical retrieval, fuses both lists, removes duplicates, reranks the survivors and exposes three documents. The final answer may cite those three documents correctly. But why those three? Which queries were used? How many candidates were fetched? Which retriever produced each item? What was removed as a duplicate? Which reranker and version set the final order? Did a filter silently exclude a date range, language or jurisdiction? Did the program print a summary instead of the source text? The citations cannot answer those questions by themselves. The executed program can. A useful answer receipt should preserve at least six layers. First, save the exact program that ran. Do not keep only a pretty diagram or reconstructed explanation. Preserve the executable artifact, its hash and the sandbox policy that constrained it. Second, record every search call. Store the query, retriever, index or corpus version, parameters and timestamp. Dense and sparse retrieval can fail differently, so the record should not flatten them into one generic search event. Third, keep stable identifiers for the candidate documents. A complete copy may be inappropriate or legally restricted, but a reviewable system still needs document IDs, source locations, versions and content hashes where permitted. Fourth, record the transformations. Fusion, deduplication, filtering, sorting and reranking should leave a compact trace. A reviewer should be able to see why a document entered or left the candidate set. Fifth, distinguish retrieved material from admitted context. RPL's main structural advantage is that it can process more than it exposes. The receipt should therefore show both the broad candidate set and the smaller context set, with the rule that connected them. Sixth, bind the final answer and citations to that execution. Record the answering model, model version, prompt or workflow version, retrieved context and completion identifier. If the answer changes while the retrieval program stays fixed, that should be visible. If the retrieval changes while the answer stays nearly identical, that should be visible too. This is not a demand to dump every internal token onto a user. There are good reasons not to expose raw chain-of-thought. It may contain sensitive data, misleading intermediate speculation or material that was never intended as a factual explanation. A retrieval receipt is different. It records external actions and evidence selection, not a private stream of model cognition. The public view can stay simple: citations, source dates and a short explanation of how evidence was selected. The audit view can be richer: executed program, queries, document identifiers, transformations, context admissions, model versions, timing and errors. The research itself uses verification during training. RPL's program mutation procedure takes suboptimal programs sampled during reinforcement learning and makes grammar-constrained local changes, such as replacing a retriever, increasing candidate breadth or adding reranking. It executes the variants and keeps those that surface sufficient evidence. For each retrieval-verified mutation, the system splices the real execution output into the trajectory and asks the policy to continue toward an answer. If the new answer is wrong, the answer span can be masked while the verified retrieval program still teaches the model. That separation is worth noticing. A program can find useful evidence and still support a bad final answer. Conversely, a correct answer can be produced from a brittle or incomplete search path. Product evaluation should score both layers. Measure answer correctness, but also document coverage, source quality, query stability, context selection, citation support and sensitivity to index updates. Replay saved programs against a frozen corpus to test reproducibility. Replay them against a current corpus to reveal source drift. Do not confuse reproducibility with timelessness. A search program run today may produce different results tomorrow because the corpus, embeddings, lexical index, reranker or access permissions changed. The receipt must pin versions or preserve enough metadata to explain the difference. Programmable retrieval also expands the attack surface. A model that can write loops, conditions and set operations can create expensive queries, over-broad scans or pathological reranking workloads. The sandbox needs limits on execution time, retrieval calls, candidate counts, memory, output size and allowed operations. Source poisoning remains a problem. A clever program cannot turn a malicious or corrupted corpus into trustworthy evidence. It may simply retrieve the poisoned material more efficiently. Access control matters too. Local program state can contain documents that never appear in the final context. A system must still enforce permissions at retrieval time, isolate tenants and prevent the program from inferring protected records through counts, ordering or aggregate outputs. The paper does not claim to solve those production problems. Its experiments use two Qwen3 model sizes, a 2018 Wikipedia snapshot for open-domain QA and the GlobalQA corpus for corpus reasoning. Exact match and set-based F1 are useful research measures. They do not establish factual reliability on a live web index, resistance to adversarial sources, secure code execution or safe behavior in medicine, law, finance or other consequential settings. The results are also author-reported in an arXiv preprint. The Meta publication page links the paper and summarizes the findings, but this is not an independent replication. There is still a lot here for builders. Fixed retrieval pipelines are easy to inspect because somebody designed them in advance. Learned retrieval programs are adaptive, which is the point. One question may need dense search and reranking. Another may need lexical search, aggressive deduplication and a count computed over identifiers. A third may need two complementary subqueries and only three passages admitted to context. That flexibility can save tokens and find better evidence. It also means the search policy has become a decision-maker. Treat its program as a first-class artifact. Give it an execution ID. Make it replayable. Show the candidate-to-context funnel. Preserve the exact source versions. Attach the receipt to the answer before any downstream system turns that answer into a recommendation, ticket, report or decision. The future of retrieval may look less like calling search and more like writing a tiny search engine for every question. Fine. Just keep the tiny search engine with the answer it produced.
01
WHAT ACTUALLY CHANGED
Meta researchers introduced Retrieval Program Learning for executable, model-written search procedures
The retrieval SDK includes dense search, sparse search, reciprocal-rank fusion, deduplication and reranking
Programs can use ordinary control flow and local state to process intermediate results
Only content explicitly printed by the program enters the language model context
The design separates candidate retrieval breadth from final context size
Program mutation creates grammar-constrained local variants of suboptimal retrieval programs
Mutated programs are executed and checked for evidence coverage before distillation
The authors tested Qwen3 models at 4B and 8B parameters on seven open-domain QA benchmarks
The 4B RPL model exceeded all tested 8B baselines on average exact match
RPL also led the tested GlobalQA methods on answer and document-coverage F1
The paper reports fewer retrieval turns and lower training time than the tested search-agent baselines
The work is an arXiv preprint with author-reported benchmark results, not a production safety evaluation
02
WHY THIS MATTERS
The retrieval program determines which evidence the answering model is allowed to see
Final citations reveal surviving sources but not the full evidence-selection process
Dense and lexical retrieval can surface different errors and omissions
Fusion, deduplication and reranking can remove decisive documents without leaving a user-visible trace
Broad retrieval can be useful without flooding the model context
A verified retrieval path can still lead to an incorrect answer
A correct answer can still rest on a brittle or incomplete search path
Versioned execution records make source drift and index changes easier to diagnose
Programmable search increases the need for sandbox limits and access controls
A retrieval receipt supports review before an answer becomes an operational decision
03
WHERE IT COULD HELP
- Store the exact executed retrieval program and a content hash
- Record queries, retrievers, parameters, corpus versions and timestamps
- Preserve stable identifiers and versions for retrieved candidates
- Log fusion, deduplication, filtering, sorting and reranking decisions
- Show the difference between retrieved candidates and admitted context
- Bind the final answer and citations to a specific retrieval execution
- Offer a simple public receipt and a richer authorized audit view
- Replay programs against frozen corpora for reproducibility checks
- Replay against current corpora to detect source and index drift
- Set limits on calls, candidate counts, runtime, memory and output size
- Evaluate answer quality and retrieval quality as separate layers
- Require human review before retrieved answers trigger consequential actions
KEEP A HAND ON THE WHEEL
Watch for released code or trained checkpoints; independent replication; live-index and multilingual evaluations; source-poisoning tests; sandbox and permission models; replay tooling; measurements of citation support rather than answer match alone; behavior when corpora change; comparisons that equalize compute and context budgets; and product interfaces that expose the candidate-to-context funnel without leaking protected data.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 21, 2026.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US