THE SIGNAL IN ONE SENTENCE
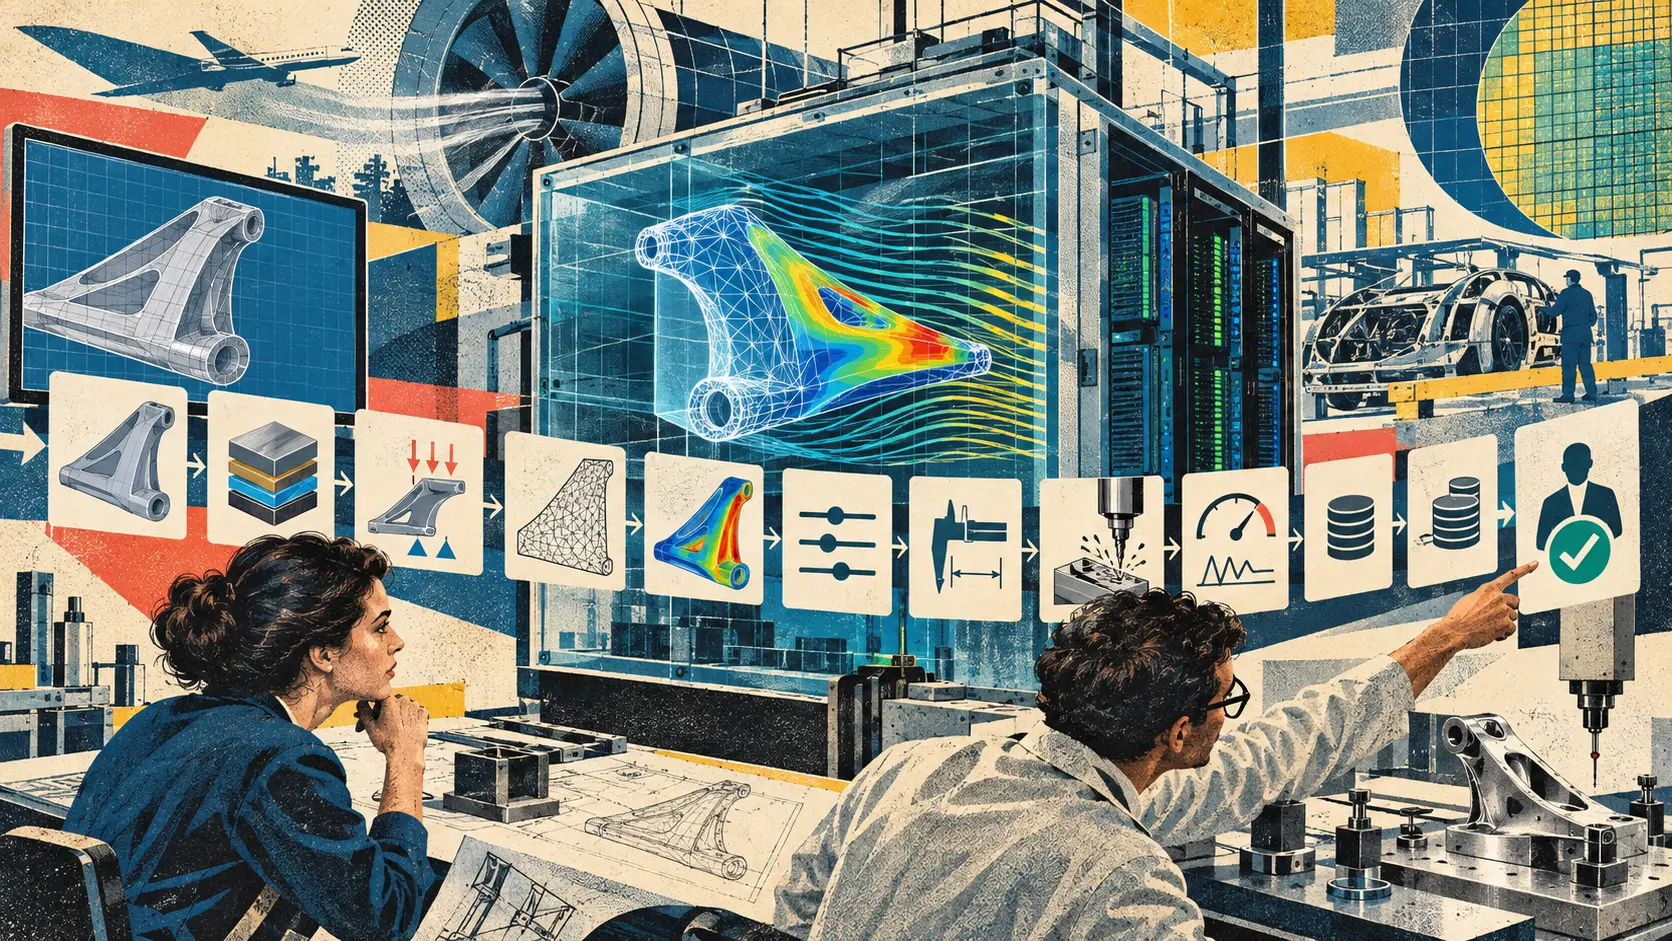
An AI agent can draw a bracket, launch a simulation and return a polished chart before lunch. That does not mean anyone should bolt the bracket to an airplane. Mistral and NVIDIA announced a collaboration on October 21 to build what they call AI-native engineering workflows. The plan connects Mistral models and data-generation pipelines with NVIDIA CUDA-X libraries, the Warp framework for GPU-accelerated physics and Omniverse libraries for 3D scenes and simulation-ready assets. The companies describe a closed loop joining simulation, AI model development and engineering design. An agent could help prepare geometry, invoke tools, inspect results, revise a design and run another test without a person manually carrying every file between systems. That is a serious idea. Engineering already contains long chains of repetitive setup, translation, meshing, solver execution and result review. Shortening those chains could let teams explore more options before metal, silicon or composite material enters production. The announcement also contains the part worth circling in red pencil. Mistral and NVIDIA say they will develop public benchmarks and open datasets for physics models, automated CAD-to-simulation workflows and engineering agents in computer-aided engineering and electronic design automation. Those benchmarks do not exist yet. The collaboration is a plan, not a published production system. The companies report no validated reduction in design time, no fielded aerospace or automotive component, no semiconductor tape-out result and no independent comparison showing that an agent produced a technically correct design more reliably than an established workflow. The plain signal is that engineering agents will not be judged by whether they can operate a tool. They will be judged by whether the complete handoff preserves the problem an engineer actually meant to solve. That handoff begins before the solver runs. A simulation needs geometry, materials, loads, constraints, contacts, initial conditions, boundary conditions, mesh choices, solver settings, convergence criteria and units. The output depends on every one of them. A beautiful stress plot can be numerically correct for the wrong material, the wrong bolt condition or the wrong direction of force. Language models are unusually good at producing plausible connective tissue. That makes them useful for assembling workflows and dangerous when missing assumptions can hide inside fluent explanations. An agent might infer that a surface is fixed because a nearby example used the same convention. It might choose an aluminum alloy when the bill of materials only says aluminum. It might repair a failed mesh by simplifying a feature that carries the load. It might change a tolerance until the solver converges, then present the cleaner result as if the design had never changed. None of those mistakes requires a spectacular hallucination. Ordinary convenience is enough. The benchmark therefore needs to evaluate more than the final answer. Mistral says the planned evaluations will assess an agent's ability to use engineering tools, complete multistep workflows and produce technically correct results while measuring execution time and computational cost. That is a solid starting frame. The useful version should preserve a receipt for every step. Start with the task contract. The benchmark should state what is known, what is unknown and which decisions the agent may make. If a material is missing, should the agent stop, ask a question or select from a documented approved set? If a CAD body is not watertight, may it repair the geometry? If a solver fails to converge, may it change the mesh, time step or physical model? Without that contract, success can mean that the agent quietly rewrote the assignment. Next, preserve the input bundle. Save the exact CAD or EDA files, units, coordinate systems, material records, loads, constraints, process rules, software versions and reference documentation. Attach stable identifiers instead of relying on a screenshot or a natural-language summary. Then record every tool action. Which file did the agent open? Which geometry did it alter? Which mesher and solver did it call? What parameters changed between runs? What warnings appeared? Which result did the agent reject, and why? How much wall time and compute did each attempt consume? The action trace is not administrative confetti. It is the only way to distinguish a good result from a lucky result. NVIDIA Warp shows why this matters. Warp is an open-source Python framework that compiles functions for GPU-accelerated simulation and supports differentiable workflows, geometry operations, sparse linear algebra and finite-element methods. That range is useful, but it also means an agent may operate close to kernels, meshes and numerical methods where a small choice can change both speed and physics. Omniverse introduces a different handoff. NVIDIA describes its libraries as tools for structuring 3D data, preparing simulation-ready worlds and validating assets. Its SimReady checks can identify whether an asset has the properties required downstream. A scene that looks complete can still lack physical properties, semantic labels or collision behavior. Visual correctness is not simulation readiness. The benchmark should exploit that difference. Give the agent assets that look convincing but contain missing units, flipped normals, incomplete materials, invalid contacts, ambiguous coordinate frames or hidden geometry defects. Reward it for stopping and naming the problem. Do not reward it for producing a more cinematic failure. Engineering agents also need adversarial tests that remain boring. Swap millimeters and meters. Omit a decimal in a material property. Use a reference document from an older solver version. Supply two surfaces with nearly identical names. Include an attractive chart from a failed run. Set a convergence tolerance that allows a quick answer but not a trustworthy one. These are not puzzle-box tricks. They resemble the clerical and configuration errors that already break real engineering work. The final result should be evaluated on several layers. First is execution. Did the files open, tools run and workflow finish without corrupting the project? Second is numerical correctness. Did the solver converge under an appropriate method, and can the result be reproduced from the saved inputs and settings? Third is physical validity. Does the result obey conservation laws, material limits, known symmetries and expected behavior on simpler cases with analytical answers? Fourth is design validity. Does the proposed component meet the actual requirement, tolerance, manufacturing process, safety factor and regulatory constraint? Fifth is decision quality. Did the agent identify uncertainty, ask for missing information and route consequential choices to the right human? A single pass or fail score will mash those questions together. The benchmark should publish a failure taxonomy. An agent can misunderstand the requirement, alter geometry, misassign material, choose the wrong model, mishandle units, fail to converge, read the wrong result, overstate certainty or lose the provenance of a human change. Those failures demand different fixes. This is especially important for closed-loop optimization. Once an agent can revise a design after each simulation, it can search a large design space quickly. It can also learn to exploit the evaluator. If the objective rewards low mass and acceptable peak stress, the agent may find a geometry that passes under a coarse mesh and fails when the mesh is refined. If the benchmark rewards speed, it may skip checks that an engineer considers mandatory. The evaluation has to hold out stricter tests than the agent sees during optimization. Re-mesh the final design. Change the solver. Run an independent high-fidelity check. Compare against a physical test where practical. Measure whether performance survives small changes in load, temperature, manufacturing variation and material properties. Robustness belongs in the score. So does abstention. An agent that stops after detecting an ambiguous load case may be more valuable than one that completes every task. The benchmark should include cases where the correct action is to request a missing specification, reject a corrupted input or escalate a safety-critical decision. Completion rate alone will punish good judgment. The companies also mention open datasets. Those datasets should include successful runs, failed runs, incomplete tasks and human corrections. A clean collection of finished examples will teach models what polished outputs look like. It will not teach them when engineering work becomes unsafe or irreproducible. Licensing and confidentiality need care too. Aerospace, automotive and semiconductor workflows often contain proprietary geometry, process rules and simulation data. An open benchmark cannot simply republish customer files. It can use purpose-built tasks, permissively licensed examples and synthetic variants, but it should explain which parts resemble real industrial distributions and which parts are convenient stand-ins. Open does not automatically mean representative. There is also a platform question. Mistral and NVIDIA are defining evaluations around Mistral models and NVIDIA's accelerated stack. Their contribution can still be useful, but a public benchmark should not quietly become a product compatibility test. The task format, scoring code, reference outputs and error categories should allow other models, hardware and engineering tools to participate. Results should separate model capability from tool integration, hardware speed and proprietary solver performance. A team should be able to reproduce the benchmark without buying the exact stack that helped write it. That is how an industry benchmark earns the word public. For engineering teams, the practical starting point is not a fully autonomous design loop. It is a narrow, observable assistant. Let the agent prepare a simulation deck, but require a human to approve the geometry, materials and boundary conditions. Let it launch a batch of runs, but save the command, environment and logs. Let it summarize results, but link every claim to the exact field and run that produced it. Let it propose a revision, but show the changed parameters before another solve begins. These controls do not defeat the point of automation. They put the expensive human attention at the handoffs where meaning can change. Mistral and NVIDIA are right that shared evaluations could build confidence. Engineering agents need a common proving ground before tool fluency gets mistaken for professional judgment. The benchmark should make the invisible work visible: the assumptions, conversions, solver warnings, rejected runs, computational budget and human decisions that sit between a prompt and a part. If the final chart is the only artifact left behind, the workflow has not closed the loop. It has closed the evidence drawer.
01
WHAT ACTUALLY CHANGED
Mistral and NVIDIA announced an engineering collaboration on October 21, 2026
The companies plan to connect Mistral models and data-generation pipelines with NVIDIA CUDA-X libraries and the Warp framework for accelerated physics workflows
They plan to integrate Mistral models with NVIDIA Omniverse libraries for GPU-accelerated 3D scene generation and simulation-ready asset creation
The proposed workflow links simulation, AI model development and engineering design in a closed loop
Mistral and NVIDIA say they will develop public benchmarks and open datasets for evaluating physics models
The collaboration also targets dedicated evaluations for agents working in computer-aided engineering and electronic design automation
The planned evaluations are intended to measure tool use, multistep completion, technical correctness, execution time and computational cost
No benchmark, open dataset or validated production result was released with the announcement
02
WHY THIS MATTERS
Engineering simulations depend on geometry, materials, units, boundary conditions, solver settings and tolerances that a fluent agent can silently misread or alter
A technically correct solver run can still answer the wrong engineering question
Closed-loop optimization can explore more designs while also exploiting weak objectives or coarse evaluation methods
Tool-action traces make it possible to reproduce a result and identify where the meaning changed
Benchmarks can reward useful abstention when inputs are incomplete or a decision exceeds the agent's authority
Open failure cases and human corrections are as important as polished successful examples
Cross-platform task formats can separate general engineering capability from one vendor stack
Human review is most valuable at handoffs where assumptions, geometry, physics or acceptance criteria can change
03
WHERE IT COULD HELP
- Prepare a simulation input deck while requiring human approval of materials, loads and boundary conditions
- Generate meshes and flag geometry defects without silently repairing safety-relevant features
- Launch reproducible batches with saved commands, environments, solver versions and logs
- Summarize results with links to the exact run, field and output file supporting each claim
- Compare design variants while holding out stricter meshes, solvers and physical checks for final validation
- Test agents on unit errors, missing properties, stale documentation and visually convincing failed runs
- Score execution, numerical correctness, physical validity, design validity and decision quality separately
- Measure wall time, compute cost, retries, rejected runs and human correction effort
- Include tasks where asking a question or stopping is the correct result
- Publish benchmark schemas, scoring code, reference evidence and failure categories for competing tools and models
KEEP A HAND ON THE WHEEL
The October 21 announcement is a collaboration plan. Mistral and NVIDIA have not released the promised public benchmarks or open datasets, and they report no validated production outcome for aerospace, automotive or semiconductor design. Faster simulation does not establish correct requirements, trustworthy boundary conditions, manufacturability or safety. A public benchmark built around the companies' own models and software could also favor their stack unless tasks, scoring and reference evidence remain portable. Watch for released datasets and licenses; representative failure cases; full tool traces; unit and provenance checks; held-out physics and robustness tests; independent solvers and physical validation; explicit abstention scores; computational budgets; cross-platform participation; and evidence that engineers can inspect, reproduce and reject an agent's work before it reaches production.
04
TERMS WORTH KEEPING
SOURCES AND VERIFICATION STATUS
This article was written from the materials below. Product claims and dates were checked against those sources on October 22, 2026.
PUBLICATION RECEIPT: Reporting verified immediately before publication against Mistral and NVIDIA primary sources. Planned collaborations, benchmarks and datasets are distinguished from released tools, independent evaluations and production engineering results.
THE PUBLICATION ENGINE
WANT A SIGNAL OF YOUR OWN?
We build source-grounded publications, private briefings, and editorial systems for organizations with something useful to say.
WORK WITH US